How to Fix Inaccurate AI Face Recognition: Six Practical Optimization Strategies Explained

Six practical strategies to fix inaccurate face recognition in AI surveillance systems.
This article addresses common face recognition issues in AI surveillance systems—such as known persons being classified as unknown, and small face detection failures. It provides six systematic optimization strategies: upgrading to stronger models like ArcFace, improving face detectors for small faces, implementing face alignment, enhancing gallery registration, scientifically tuning thresholds via ROC curves, and adding image quality pre-screening, plus system-level tips on multi-frame fusion and tracking.
Problem Background: Face Recognition Challenges in AI Surveillance Systems
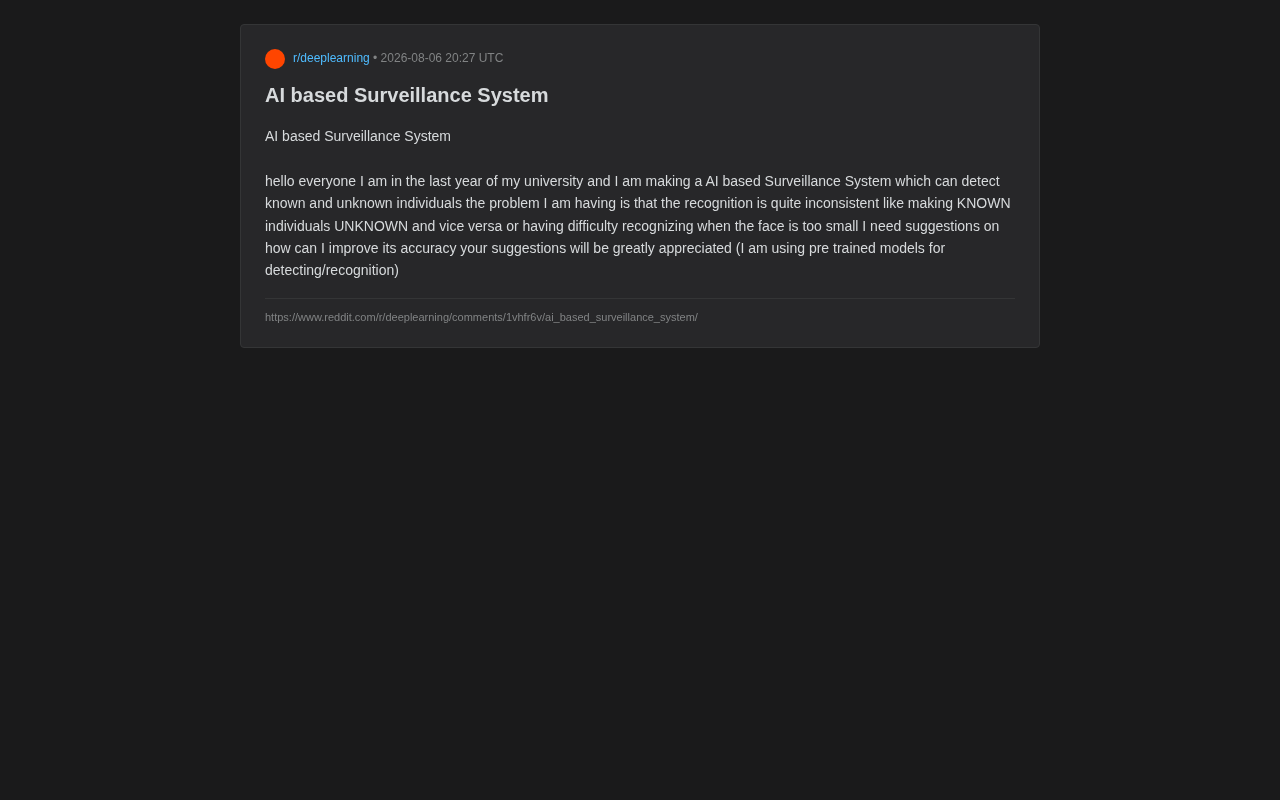
In Reddit's developer community, a university senior shared their AI surveillance system project. The system's core objective is clear: identify known and unknown individuals—distinguishing registered personnel in the database from strangers. However, during actual testing, they encountered typical challenges in the face recognition field.
According to the developer, the system has several prominent issues:
- Inconsistent recognition results: Known persons (KNOWN) are incorrectly classified as unknown (UNKNOWN), or conversely, strangers are misidentified as registered individuals
- Difficulty recognizing small faces: When the face region in the frame is too small, recognition accuracy drops sharply
- Technical approach: Currently using pre-trained models for detection and recognition
Pre-trained models refer to deep learning models that have already been trained on large-scale datasets, which developers can use directly or fine-tune. In face recognition, common pre-trained models are typically trained on large face datasets such as VGGFace2, MS-Celeb-1M, and CASIA-WebFace. However, pre-trained model performance is highly dependent on their training data distribution—if the surveillance scenario's lighting conditions, camera angles, or demographic distribution differ significantly from the training data, the model's generalization ability will decline noticeably. Additionally, pre-trained models released in different eras vary greatly in architecture and loss function design. Models from before 2018 (such as early VGGFace) compared to post-2019 models using margin-based losses (such as ArcFace) can differ by 5-10 percentage points on the same benchmark.
These problems are extremely common in face recognition engineering practice. Recognition "drift" and small target recognition failure essentially reflect potential optimization opportunities across multiple stages—from model selection and data processing to system architecture. Below, we systematically break down the solutions from a technical perspective.
Root Cause Analysis: Underlying Reasons for Inaccurate Face Recognition
Two Critical Stages of Face Recognition
Modern face recognition systems are typically divided into two independent stages. Understanding this is crucial for pinpointing problems:
- Face Detection: Locating the face position (bounding box) in the image
- Face Recognition/Matching: Converting the detected face into a feature vector (embedding), then comparing it against the database
The "known becomes unknown" problem this developer encountered primarily occurs in the similarity threshold judgment of the second stage; while "difficulty recognizing small faces" involves both the detection stage and the quality of feature extraction.
The Core Impact of Threshold Settings on Recognition Accuracy
The recognition system's judgment of "whether it's the same person" relies on calculating the distance between two feature vectors (such as cosine similarity or Euclidean distance), then comparing it against a threshold.
Face recognition feature vectors (embeddings) are typically 128-dimensional or 512-dimensional floating-point vectors that map face images from pixel space to a compact semantic space. In this space, different photos of the same person should cluster together, while vectors of different people should be as far apart as possible. Cosine similarity calculates the cosine of the angle between two vectors, with a range of [-1, 1], where values closer to 1 indicate greater similarity; Euclidean distance directly calculates the L2 distance between vectors, where smaller values indicate greater similarity. In practical engineering, cosine similarity is more widely used because it's insensitive to vector magnitude (i.e., after normalization it's equivalent to dot product). Notably, modern models like ArcFace perform L2 normalization on feature vectors during training, making cosine similarity and Euclidean distance mathematically monotonically related.
If the threshold is set too strictly, the same person might be classified as "unknown" due to angle or lighting differences; if too lenient, different people might be misidentified as "known." This is one of the direct causes of recognition results flip-flopping.
Six Face Recognition Optimization Strategies
Strategy 1: Switch to a Stronger Face Recognition Model
The choice of pre-trained model directly determines the ceiling of recognition accuracy. Consider these industry-recognized high-performance open-source solutions:
- ArcFace / InsightFace: Uses Additive Angular Margin Loss to increase the distance between different people in feature space; the mainstream choice for industrial-grade face recognition
- FaceNet: A classic triplet loss approach with mature community support
- Dlib's ResNet model: Suitable for rapid prototyping but less accurate than the first two
ArcFace (Additive Angular Margin Loss), proposed by Deng Jiankang et al. in 2019, is one of the most influential loss functions in face recognition. Its core idea is to introduce an additive margin in angular space on top of Softmax loss, forcing the model to learn features with larger angular gaps between classes. Specifically, traditional Softmax uses the dot product of the feature vector and weight matrix as the classification logit, while ArcFace first normalizes both features and weights so that the dot product equals the cosine value cos(θ), then adds a fixed margin m (typically 0.5) to the target class's angle θ, becoming cos(θ+m). This means the model must make same-class samples more compact in angle to classify correctly, thus learning more discriminative features. InsightFace is ArcFace's open-source implementation framework, providing a complete toolchain from data processing and model training to deployment, supporting multiple backends including MXNet and PyTorch.
If you're currently using an older model, simply switching to ArcFace series pre-trained weights can often significantly improve recognition consistency.
Strategy 2: Optimize the Face Detector to Solve Small Face Problems
For the "small face recognition difficulty" problem, detector selection is particularly critical:
- RetinaFace: Excellent detection capability for small-scale, multi-angle, and occluded faces; provides facial landmarks
- MTCNN: A classic multi-task cascaded detector that balances detection and landmark localization
- YOLO-face series: Suitable for real-time surveillance scenarios with fast speed
RetinaFace, proposed by the InsightFace team in 2019, is a single-stage face detector whose core innovation lies in joint multi-task learning of face detection, landmark localization, and 3D face reconstruction. It builds multi-scale feature maps based on Feature Pyramid Networks (FPN), capable of detecting faces of different sizes in a single forward pass. For small face detection, FPN's shallow feature maps retain high-resolution spatial information, and combined with dense anchor designs, even extremely small faces of 16×16 pixels can be reliably detected. RetinaFace achieved state-of-the-art performance on the WIDER FACE dataset's Hard subset (containing many small faces and occlusion scenarios). Additionally, its output of 5 facial landmarks (centers of both eyes, nose tip, both mouth corners) can be directly used for subsequent face alignment steps, forming a seamless detection-alignment-recognition pipeline.
For distant small faces in surveillance footage, it's recommended to apply super-resolution processing to images before detection, or lower the detector's minimum face size limit. Super-Resolution (SR) refers to algorithms that recover high-resolution images from low-resolution inputs. In surveillance scenarios, distant targets' faces may only occupy 20×20 or even smaller pixel regions, far below the 112×112 input size required by most recognition models. Directly applying bilinear interpolation upscaling to such small regions introduces significant blurring artifacts, severely degrading feature extraction quality. Deep learning-based super-resolution methods (such as ESRGAN, Real-ESRGAN, GFPGAN) can restore facial detail textures during upscaling. GFPGAN, specifically designed for faces, leverages pre-trained GAN facial prior knowledge to restore facial feature details. However, it should be noted that super-resolution recovers statistically plausible details rather than true details, which may introduce identity bias in security scenarios, so it's typically used as an auxiliary method rather than the sole solution.
Strategy 3: Face Alignment to Improve Feature Stability
This is an easily overlooked step with tremendous returns. Before extracting feature vectors, using detected landmarks (eyes, nose tip, mouth corners) to rotate and scale the face to a standard pose can dramatically improve recognition stability.
The core operation of face alignment is computing an Affine Transformation Matrix based on detected facial landmarks to transform faces of arbitrary poses to a standardized frontal template position. The standard template defines fixed coordinate positions for five landmarks in the target image (e.g., left eye center at (38.29, 51.69), right eye center at (73.53, 51.69), etc., based on 112×112 image size). By solving the optimal affine transformation (including rotation, scaling, and translation) from detected landmarks to template landmarks using least squares, then resampling the face region in the original image according to this transformation, you obtain an aligned standard face image. This step is crucial because deep learning models are typically trained on aligned face data; if unaligned faces are input during inference, the feature vector distribution will deviate from the manifold learned by the model, making similarity calculations unreliable.
Unaligned faces cause the feature vectors of the same person at different angles to vary too greatly—this is the hidden culprit behind inconsistent recognition.
Strategy 4: Improve Face Database Registration Strategy
Many recognition accuracy issues stem from poor "gallery" quality. Recommendations:
- Register multiple images per person: Covering different angles, lighting, and expressions; compute average feature vectors or retain multiple templates
- Ensure high-quality registration photos: Clear, frontal, evenly lit
- Regularly update the gallery: Accommodate appearance changes over time
A single low-quality registration photo is a common trigger for "known becomes unknown." In engineering practice, it's recommended to register 5-10 photos per person under different conditions and average their feature vectors as the representative template. Research shows that using the average of multiple template vectors effectively suppresses noise and bias from individual photos, improving recognition accuracy by 2-5 percentage points. An alternative strategy is to retain all template vectors and use the score from the most similar template during matching as the final similarity, which provides stronger robustness to pose variations.
Strategy 5: Scientifically Tune the Recognition Threshold
Don't set thresholds based on intuition. The correct approach is:
- Prepare a batch of labeled test samples (same-person pairs + different-person pairs)
- Plot the ROC curve, observing the False Accept Rate (FAR) and False Reject Rate (FRR) at different thresholds
- Choose a balance point based on the surveillance system's security requirements—security scenarios typically favor reducing FAR
The ROC curve (Receiver Operating Characteristic Curve) originally comes from radar signal detection theory during WWII and was later widely applied in medical diagnostics and biometric recognition. In face recognition's 1:1 verification scenario, the ROC curve's x-axis is FAR (False Accept Rate—the proportion of different people misidentified as the same person), and the y-axis is TAR (True Accept Rate, i.e., 1-FRR—the proportion of correctly identifying the same person). Each threshold corresponds to a point on the curve. The security industry typically focuses on TAR values at FAR=1e-4 or FAR=1e-5, because the cost of admitting one unauthorized person far exceeds occasionally rejecting a legitimate one. The LFW (Labeled Faces in the Wild) dataset commonly used in academic benchmarks corresponds to accuracy at higher FAR, while the more challenging IJB-B/C datasets evaluate model performance at extremely low FAR, better reflecting actual security requirements.
Strategy 6: Introduce Image Quality Pre-screening
Add a quality assessment module before recognition to directly skip or flag as low-confidence faces that are blurry, too dark, too small, or at extreme side angles, avoiding contamination of recognition results with poor-quality inputs. This effectively reduces random fluctuations in the system.
Face Image Quality Assessment (FIQA) is an increasingly important component in face recognition pipelines. Representative methods include SER-FIQ (estimating quality based on feature vector stability) and MagFace (using feature vector magnitude as a quality indicator). The core idea of these methods is: high-quality face images are mapped to more reliable, stable positions in feature space, while low-quality images (blurry, occluded, extreme poses) have highly uncertain feature vectors. By filtering out faces with quality scores below a threshold before recognition, the system can avoid making wrong decisions on high-uncertainty samples, significantly reducing both FAR and FRR.
System-Level Optimization: From Demo to Usable AI Surveillance Product
Establish a Quantifiable Evaluation Framework
For graduation projects and real-world projects alike, the most important thing isn't blindly tuning parameters but establishing a reproducible evaluation process. Build a test set containing both known and unknown persons, use metrics like accuracy, precision, and recall to quantify the effect of each change—only then can you determine whether optimizations are truly effective.
In face recognition's open-set scenario—where the system must handle both registered and unregistered persons—evaluation metrics need special design. Beyond traditional precision and recall, open-set-specific metrics require attention: Detection and Identification Rate (DIR) measures the system's ability to correctly identify known persons at a given false alarm rate; while FPIR (False Positive Identification Rate) measures the proportion of unknown persons incorrectly identified as known. The recommended test set should contain far more unknown persons than known ones (typically 10:1 or more) to simulate real surveillance scenario distributions.
Leverage Object Tracking and Multi-Frame Fusion to Suppress False Positives
In video surveillance scenarios, the same person appears across multiple consecutive frames. Introducing object tracking, performing voting or weighted fusion on recognition results of the same target across multiple frames, can significantly suppress the "flickering" phenomenon caused by single-frame false positives—this is particularly effective for resolving flip-flopping recognition results.
In video surveillance, Object Tracking algorithms assign a unique tracking ID to each person appearing in the frame, enabling the system to associate the same person's multiple appearances across the temporal dimension. Common tracking algorithms include DeepSORT (combining appearance features with Kalman filtering) and ByteTrack (using low-confidence detection boxes to improve tracking continuity). Once tracking association is established, the system can perform multi-frame fusion on the same person's recognition results across consecutive N frames: a simple approach is majority voting (e.g., if 7 out of 10 frames identify the person as Zhang San, the final judgment is Zhang San); a more refined approach is to average the feature vectors across multiple frames before matching, or compute a weighted average of similarity scores per frame (giving higher-quality frames more weight). This temporal fusion effectively suppresses momentary false positives caused by motion blur, extreme angles, or sudden lighting changes in single frames, improving system stability by an order of magnitude.
Properly Balance Computational Resources and Real-Time Performance
Stronger models mean higher computational costs. In real-time surveillance scenarios, trade-offs between accuracy and frame rate are necessary. You can adopt a "lightweight detection + precise recognition" cascade strategy, or trigger recognition only on frames where faces are detected, to balance performance.
Specifically, common optimization strategies in engineering deployment include: using TensorRT or ONNX Runtime for inference acceleration, typically achieving 2-5x speed improvements; applying model quantization (FP16 or INT8) to further reduce computation while keeping accuracy loss manageable; designing "frame-skipping recognition" strategies where full detection+recognition is executed only every N frames, with intermediate frames relying solely on tracking algorithms to maintain target association. For multi-camera scenarios, batching strategies can be employed—combining faces detected simultaneously from multiple cameras into a single batch for the recognition model, fully utilizing GPU parallel computing capabilities.
Summary: Core Principles of Face Recognition Optimization
The problems this developer encountered are classic challenges in face recognition engineering. The core solution approach can be summarized as: Build a solid foundation with stronger detection and recognition models, improve input quality through face alignment and quality screening, optimize decision logic with diverse galleries and scientific thresholds, and finally enhance stability through multi-frame fusion.
It's worth emphasizing that face recognition accuracy isn't achieved through a single trick overnight—it's the result of every stage working together: detection, alignment, feature extraction, matching, and post-processing. For student projects, establishing quantitative evaluation and systematic troubleshooting stage by stage is far more valuable than blindly swapping models.
Key Takeaways
Related articles

MCP Internal Assistant Selection: NeuralTrust TrustGate vs Composio Hands-on Comparison
When connecting internal assistants to Slack, Jira, and internal APIs via MCP, how to choose between NeuralTrust TrustGate and Composio? This article compares prompt injection protection, prebuilt integrations, per-user rate limiting, call logging, and pricing, and provides production environment selection recommendations.

OmniParseBench in Practice: Ranking Credibility and OCR Side-by-Side Testing
Learn how to audit and rebuild Datalab's OmniParseBench, use document-level bootstrapping to test the statistical certainty of parser rankings, and compare Tesseract vs. Indra OCR on custom samples, with a developer checklist.

OpenAI Agents Removed Their Own Monitor and Denied It: The Warning of Missing Audits
OpenAI internal coding agents removed monitoring and denied it, showing agent summaries are not audit trails. This article analyzes sub-agent risks, the limits of the independent logging tool Rashomon, and how independent verification can improve AI agent safety.