IMGNet: A New Face Verification Approach Where Sign Pattern Matching Challenges Cosine Similarity

IMGNet replaces cosine similarity with sign pattern matching for face verification, outperforming cosine on all benchmarks at just 10MB.
IMGNet is a 10.58MB face verification model that replaces cosine similarity with sliding window sign pattern matching, inspired by structural linguistics. Trained on CASIA-WebFace, its sign metric outperforms cosine on LFW, AgeDB-30, CALFW, and CPLFW. A cross-model experiment on pretrained ArcFace embeddings (99.58% on LFW with no retraining) suggests sign consistency may be an intrinsic property of well-trained face embeddings, independent of training objective.
From Javanese to Face Recognition: An Unconventional Inspiration
An independent researcher from Indonesia recently shared his open-source project IMGNet on Reddit's r/deeplearning community — a face verification model with one standout feature: it completely abandons the industry-standard cosine similarity in favor of a novel metric called "sliding window sign pattern matching."
Cosine similarity has been the de facto standard for high-dimensional vector comparison since its rise in information retrieval in the 1990s. Mathematically, it computes the cosine of the angle between two vectors, making it entirely insensitive to vector magnitude and focused purely on direction. In face recognition, cosine similarity became widely adopted around 2015 alongside deep learning models like DeepFace and FaceNet, prized for its simplicity and scale-invariance. FaceNet further streamlined this by projecting embeddings onto a unit hypersphere via L2 normalization, making cosine similarity equivalent to Euclidean distance. Yet its fundamental limitation remains: it measures angular difference on a high-dimensional sphere, relying entirely on global directional information while ignoring local relational structure among embedding dimensions — and that is precisely what IMGNet aims to overcome.
The author's inspiration is remarkably unique. He noted that in Javanese, "thank you" is "matur suwun," while in Sundanese the same sentiment is expressed as "hatur nuhun" — completely different surface forms, identical meaning. Identity is preserved through relational structure, not absolute values. This is the core idea behind IMGNet: rather than comparing the global angular direction of embedding vectors (which is what cosine similarity does), find locally consistent sign patterns within overlapping windows of the embedding vector.
This analogy has deep theoretical roots in linguistics. Structuralist linguistics founder Ferdinand de Saussure argued in the early 20th century that the meaning of a linguistic sign comes from its differential relationships within a system, not from its absolute properties. Different languages can express the same concept with entirely different sound forms because meaning lives in relational networks. Translating this insight to face embeddings suggests that identity information may similarly be encoded in relative relationships between dimensions (sign patterns), rather than the absolute direction of the embedding vector.
This linguistics-inspired perspective offers an intriguing new angle for a field long dominated by cosine similarity.
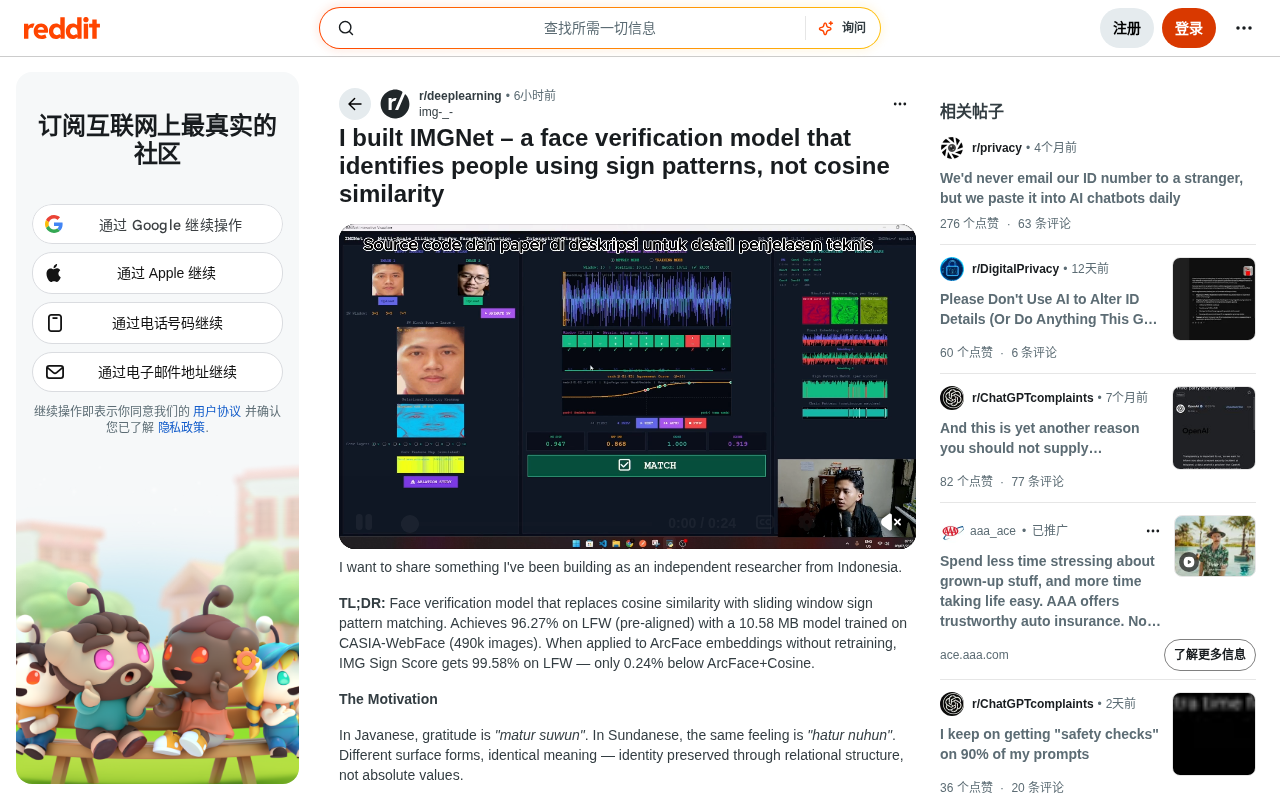
Technical Core: Three Key Innovations
SW Block: Multi-Scale Relational Operations
IMGNet's first layer replaces standard convolution with a "multi-scale relational operation." For each pixel, it computes differences between that pixel and all its neighbors across prime window sizes {3, 5, 7}. This yields 240 difference values per pixel, which a small MLP then maps to output channels.
Using prime window sizes is a deliberate design choice to avoid redundant sampling overlap between scales, making multi-scale information more complementary. Standard CNNs typically use fixed 3×3 or 5×5 kernels, where systematic pixel overlap between scales leads to redundant information as the receptive field expands. The prime combination {3, 5, 7} ensures larger least common multiples between windows, making the spatial patterns captured at each scale statistically more independent. This echoes the signal processing concept of "orthogonal basis decomposition" — constructing maximally orthogonal (non-redundant) basis functions to maximize the independent information carried by each, making more efficient use of limited compute.
It's worth noting that the "sliding window" concept itself has deep technical roots. Originating in digital signal processing, sliding windows are a foundational operation in time-series analysis and image processing. IMGNet migrates this idea from the spatial domain to the dimension domain of feature vectors, transforming inter-embedding comparison from a global angular computation into an aggregated judgment of sign consistency across multiple local windows — a conceptual cross-domain transfer, not simple engineering reuse.
IMG Sign MSE Loss: A Pure Sign Pattern Loss Function
According to the author, this is the first face verification loss function based entirely on sign pattern consistency, with no dependence on any magnitude information. The core computation:
score = mean(gate(tanh(β · E1 · E2)))  # sliding window, β=10
loss_same = ((1 - score) ** 2).mean()   # push toward 1.0
loss_diff = (score ** 2).mean()          # push toward 0.0
The tanh(β · E1 · E2) term is the key. When β is large enough (10 here), the tanh function sharpens the sign information of the product toward ±1, "compressing" the continuous magnitude information of the embedding vectors into a pure sign consistency signal. This resembles "sign encoding" in information theory: sacrificing amplitude precision in exchange for structural stability. More broadly, this design resonates conceptually with Spiking Neural Networks in neuroscience — biological neurons transmit information through binary fire/no-fire patterns rather than continuous activation amplitudes, a mechanism considered more robust under noisy conditions. This explains the training stability data: during epochs 29–50, the sign pattern loss variance was only ±0.40%, versus ±2.25% for magnitude-based variants, indicating significantly more stable training.
Unified Threshold and Voting Mechanism
IMGNet defines three metrics — IMG Sign Score, AMP IMG Score, and Chain Score — all operating in the [0,1] range, sharing a single threshold derived from scanning IMG Sign.
Final decisions use a voting system: 2/3 or 3/3 agreement means MATCH, 1/3 means UNCERTAIN, 0/3 means DIFFERENT. This multi-metric voting mirrors ensemble learning's majority vote mechanism — combining complementary perspectives to reduce the risk of any single metric's misclassification. The UNCERTAIN category is particularly noteworthy for production deployment: it lets the system proactively identify low-confidence samples and route them to human review rather than forcing a potentially wrong binary decision. This "reject option" is well established in high-stakes domains like medical imaging and financial risk control; IMGNet's adoption of it reflects careful thought about real-world deployment.
Experimental Results: Small Model, Solid Performance
IMGNet weighs only 10.58 MB (FP32) and was trained on the CASIA-WebFace dataset (490K images). CASIA-WebFace, released by the Chinese Academy of Sciences in 2014, contains 494,414 images of ~10,575 identities and has long served as a standard training set for lightweight face recognition research. It's worth noting that current SOTA models (e.g., AdaFace, CosFace) typically train on datasets tens to hundreds of times larger — MS-Celeb-1M (~5.8M images) or WebFace260M (~260M images) — so results on CASIA-WebFace reflect methodological relative advantage rather than absolute performance ceiling.
Across multiple standard face verification benchmarks, the sign pattern metric (IMG Sign) consistently outperforms cosine similarity:
| Dataset | IMG Sign | Cosine |
|---|---|---|
| LFW | 96.27% | 95.53% |
| AgeDB-30 | 78.80% | 77.22% |
| CALFW | 78.73% | 78.32% |
| CPLFW | 76.85% | 74.62% |
| Overall | 81.02% | 79.49% |
LFW, AgeDB-30, CALFW, and CPLFW are industry-recognized benchmarks testing generalization across different challenges: varying lighting, age, and pose. AgeDB-30 focuses on cross-age verification spanning 30+ years; CPLFW deliberately introduces large pose variations and is considered one of the most challenging pose robustness tests. IMGNet shows more pronounced advantages on these two harder benchmarks, suggesting sign patterns are more robust to extreme variations.
While absolute accuracy still lags behind SOTA models, the sign metric's consistent outperformance of cosine across all benchmarks — at this compact model size and under identical embedding conditions — is a signal worth paying attention to.
The Key Finding: Is Sign Consistency an Intrinsic Property of Embeddings?
What gives this project genuine theoretical depth is a cross-model experiment. The author applied IMG Sign Score to pretrained ArcFace (buffalo_l) embeddings without any retraining.
ArcFace (2018, Deng et al.) is one of the most influential loss functions in face recognition, using additive angular margin in angle space to force embedding vectors into compact intra-class clusters and inter-class separation on the hypersphere. It adds a fixed margin m (0.5 radians in the paper) to the target class angle in the softmax loss, compelling the model to learn more discriminative features. This produces highly structured embedding distributions on the high-dimensional hypersphere — a prerequisite that makes IMGNet's cross-model experiment viable: highly structured embedding spaces naturally contain rich local pattern information. buffalo_l is a high-performance pretrained model in the InsightFace framework trained with ArcFace, designed entirely around cosine similarity. Applying a metric trained for a different objective directly to its embeddings is essentially a zero-shot probing experiment decoupling metric from training objective.
The result: on LFW, IMG Sign achieves 99.58%, only 0.24% below ArcFace+Cosine's 99.82%.
The implication is significant. It suggests that sign pattern consistency may be a fundamental property of well-trained face embeddings, independent of the training objective itself. In other words, even if an embedding was trained for cosine similarity, its internal sign structure still carries sufficient identity information.
This aligns with recent research on the intrinsic geometric structure of embedding spaces. Around 2021, multiple studies found that vision models thoroughly pretrained on large-scale datasets like ImageNet showed far smaller-than-expected retrieval performance differences across cosine, Euclidean, Manhattan, and other distance metrics, suggesting that strong supervised training produces a kind of metric-robust feature structure — the information redundancy and structural integrity of the feature space far exceeds what any single metric can fully exploit. The emerging "Universal Metric Learning" research around 2023 further found that embedding models trained on large-scale data spontaneously develop a "metric-agnostic" internal order, maintaining high discriminability regardless of whether cosine distance, Manhattan distance, or other metrics are used. IMGNet's cross-model experiment provides new evidence from the sign domain for this theory, while also offering preliminary support for the hypothesis that "similarity metrics should be co-designed with training objectives rather than defaulting to cosine."
An Unverified Incidental Finding
While building an interactive ablation visualization tool (with custom polygon masks), the author discovered an interesting phenomenon: occluding the same facial region in photos of the same person produces delta spikes at similar embedding dimensions, while photos of different people show significantly different spike locations.
This suggests the overlapping sliding window loss may induce implicit spatial organization in the embedding space. If formally verified, the implications would extend into Explainable AI (XAI) — meaning the model's embedding dimensions may have traceable correspondences to specific facial regions, providing a new analytical entry point for transparency in "black box" face recognition. This direction aligns closely with Concept Bottleneck Models and TCAV (Testing with Concept Activation Vectors), both of which seek traceable mappings between continuous embedding spaces and human-interpretable concepts (facial features, expressions). If IMGNet's embedding dimensions do encode spatial correspondence, it would mean the loss function accidentally guided the model toward learning a more interpretable feature decomposition. The author honestly emphasizes this finding is "not yet formally validated" — a commendably cautious stance for independent research.
Significance and Reflection
IMGNet's value may lie less in topping a leaderboard and more in the core proposition it raises: metric and loss should be co-designed (metric-loss alignment), rather than habitually defaulting to cosine similarity.
For a long time, face recognition and representation learning more broadly have treated cosine similarity as an unquestioned default. This has historical justification — the combination of spherically normalized embeddings and cosine metrics was repeatedly validated as efficient and reliable in early work like FaceNet, creating a path dependency. Such dependencies are common in technology history: the QWERTY keyboard layout, the TCP/IP stack, and even ReLU's dominance in deep learning are all examples of early efficient solutions solidifying into industry defaults through positive feedback loops. Once a solution becomes the default, the surrounding toolchain, benchmarks, and pretrained models further entrench it, making alternatives face high switching costs even when they're superior in certain dimensions. Yet IMGNet, with a 10 MB model and a series of reproducible experiments, reminds us that this default choice isn't necessarily the only or optimal answer. The metric itself, as a designable variable, may hold untapped potential in lightweight, edge deployment, and specialized application scenarios.
The author has open-sourced the paper, code (GitHub), and model (Hugging Face), and welcomes community discussion on the "metric-loss alignment" hypothesis. For researchers interested in the fundamentals of representation learning, this is a direction worth exploring further.
Project links: Paper (Zenodo DOI: 10.5281/zenodo.21232755), Code (github.com/imamgh11/imgnet), Model (huggingface.co/imghost11/imgnetV1)
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.