Is AI Agent Development Forgetting Software Engineering Fundamentals?

AI Agent development is forgetting software engineering fundamentals like input validation, data modeling, and access control.
Starting from a viral Reddit post, the article argues that AI Agent development widely neglects traditional software engineering practices: input validation, data modeling, access control, and injection defense. It analyzes the design gap in Agent memory systems, the dual nature of vibe coding, and concludes that software engineering skills aren't replaced by AI — they're the prerequisite for using AI coding tools effectively and designing systems well.
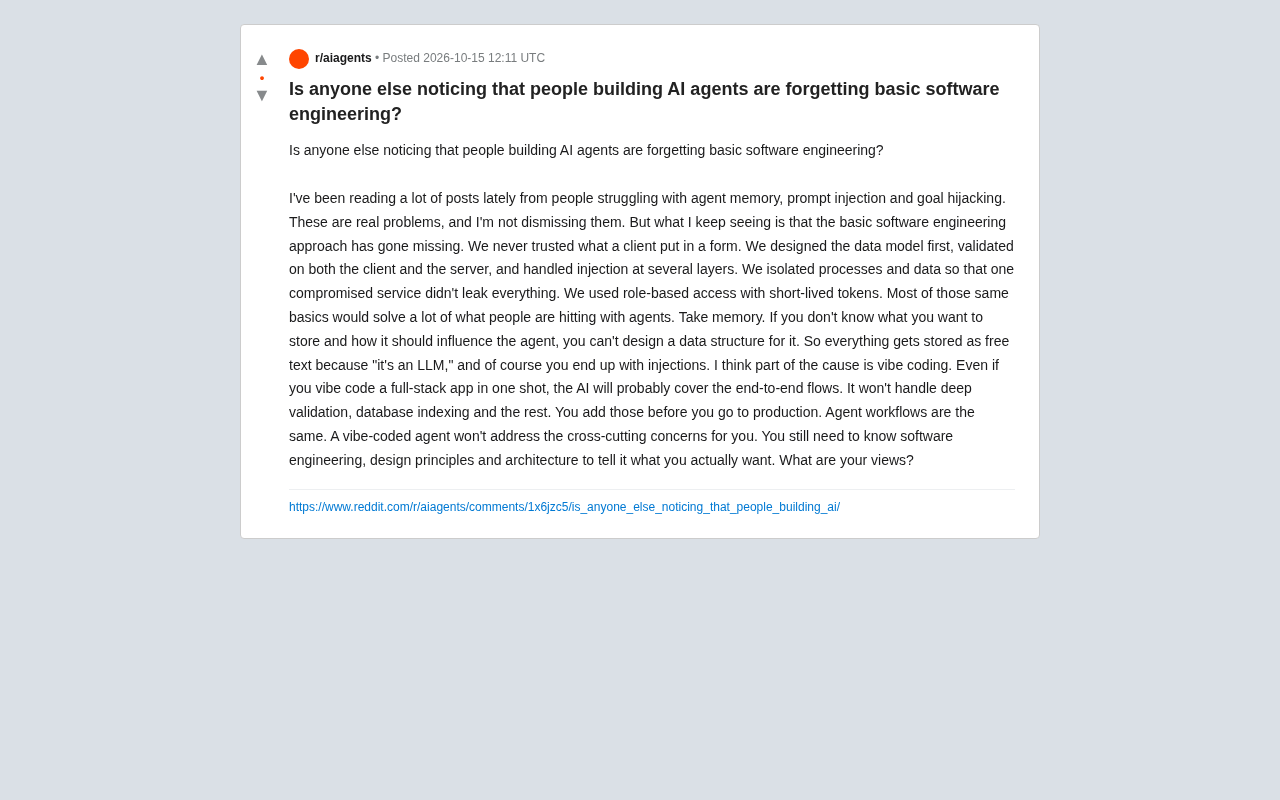
A post on Reddit struck a chord with many: more and more people building AI Agents are forgetting basic software engineering principles. The author lists high-frequency problems like Agent memory management, prompt injection, and goal hijacking, then cuts to the heart of the matter — the root cause of these issues is that developers are skipping the fundamentals that decades of software engineering have accumulated.
The Software Engineering Common Sense That's Been Forgotten
The original poster revisits a set of classic practices: treating form input as untrusted, designing the data model first, dual validation on client and server, multi-layered injection defenses, process and data isolation, role-based access control with short-lived tokens. In traditional web development these are muscle memory, but in the Agent development context, they seem to have been collectively forgotten.
This observation deserves attention. An Agent is essentially a system that accepts natural language input, calls external tools, maintains state, and produces output. Its attack surface is no smaller than a web application's — arguably larger — because LLM output is inherently unpredictable, and the side effects of tool calls can act directly on the real world. Yet many people approach Agent security as if we'd gone back to the Web 1.0 era.
Prompt injection refers to an attacker embedding disguised instructions into inputs the Agent can read (user messages, web content, tool return values, memory entries, etc.), inducing the LLM to deviate from its original task and perform operations the attacker intends. The difference from traditional SQL injection is that SQL injection attacks a parser with clear syntactic boundaries that can be defended; prompt injection attacks the model's understanding of natural language itself, where instructions and data coexist in the same token sequence, and there is currently no reliable general solution. Goal hijacking is a specific form of prompt injection, where an attacker overrides the Agent's original objective via injected content, causing it to perform other tasks — for example, turning "help me summarize this email" into "forward this email to a certain address." Defensive approaches typically include explicitly marking and isolating content from untrusted sources, limiting the permission scope of tool calls, and introducing human confirmation or an independent validation layer before critical actions.
The Design Gap in Memory Systems
The author's analysis of Agent memory issues is particularly sharp. He points out: if you don't know what to store and how that information should influence Agent behavior, you can't design a data structure for it. The result is that everything gets shoved in as free text, on the grounds that "it's an LLM anyway."
This chain of logic points to a key issue: an Agent's memory system is fundamentally a data modeling problem, not a prompt engineering problem. In traditional applications, we design table structures, build indexes, and define relationships based on query patterns. But Agent "memory" is often reduced to a vector database plus a concatenated context window. The lack of structure means you can't validate effectively, can't retrieve precisely, and can't control how information flows back into the reasoning process. The reason injection attacks are especially rampant in Agent scenarios is largely that the memory layer hasn't done input sanitization or source tagging.
Vector databases map text into high-dimensional vectors via embedding models, then perform approximate nearest neighbor retrieval based on metrics like cosine similarity — well suited for queries that are semantically similar but lexically different. But their limitations are obvious: they can't express structured relationships (such as "which user, in which session, at what time produced this memory"), can't do precise filtering or transactional updates, and similarity thresholds lack interpretability. In contrast, traditional relational databases support foreign keys, unique constraints, indexes, and transactions, allowing precise control over writes and reads. A more reasonable approach for Agent memory systems is often a hybrid architecture: structured metadata (source, time, permissions, type) in a relational database, semantic content indexed by vectors to assist retrieval and recall, and rule-based filtering to decide what information can flow back into the reasoning context. This preserves the flexibility of semantic retrieval while enabling verifiable control over source and permissions.
The Other Side of Vibe Coding
The original poster attributes part of the cause to the popularity of vibe coding. His judgment: even if you use AI to generate a full-stack application in one go, the AI will likely cover the end-to-end flow, but it won't handle deep validation, database indexing, and other "inconspicuous but critical" parts. You need to fill those in yourself before going live. The same applies to Agent workflows — a vibe-coded Agent won't handle cross-cutting concerns for you.
This view isn't a rejection of vibe coding's value. Rapid prototyping to validate ideas does need that kind of efficiency. The problem is that many people treat the prototype as the product. The gap between prototype and production system is precisely what software engineering exists to solve: error handling, edge cases, security, observability, performance degradation.
Cross-cutting concerns refer to requirements that can't be cleanly assigned to a single module but permeate the entire system — typical examples include logging, authentication, error handling, transaction management, rate limiting, and observability. Their difficulty lies in the fact that it's not enough to get one place right; you need consistency across all relevant paths. These are precisely the parts AI code generation most easily overlooks — generative models tend to focus on the main flow and get the demo running, while cross-cutting logic is scattered across edge cases, exception branches, and concurrency scenarios, and isn't easily covered in a single generation. This is also why a working prototype doesn't mean a usable system: a prototype only validates the main path, while a production system must handle all the side paths.
You Need to Know What You Want
The last line of the original post deserves to be pulled out on its own: you still need to understand software engineering, design principles, and architecture to tell AI what you actually want.
This line touches the core paradox of AI-assisted development. AI can help you write code, but it can't define the problem for you. If you don't know what kind of validation logic, what isolation level, what data model you need, you can't even write an effective prompt to get AI to generate the right implementation. Software engineering knowledge isn't replaced here — it becomes a prerequisite for collaborating with AI.
From another angle, AI programming tools lower the barrier to implementation, not the barrier to design. More people can translate ideas into code, but the number who can think clearly about how a system should be organized hasn't grown proportionally. That gap is the breeding ground for all the problems in current Agent development.
One-line Summary
AI Agent development is forgetting software engineering fundamentals like input validation, data modeling, and access control.
Paragraph Summary
Starting from a resonant Reddit post, the article points out that traditional software engineering practices are widely missing from AI Agent development: fundamentals like input validation, data modeling, access control, and injection defense have been collectively forgotten, even though an Agent's attack surface is actually larger than a web application's. The author specifically analyzes the design gap in memory systems — memory is essentially a data modeling problem, yet it's reduced to a vector store plus context concatenation, resulting in an inability to validate, an inability to retrieve precisely, and a breeding ground for injection attacks. The article also discusses the dual nature of vibe coding: it can efficiently cover the end-to-end main flow, but cannot automatically handle deep validation, indexing, security, and other cross-cutting concerns. The ultimate conclusion is that software engineering knowledge hasn't been replaced by AI — it has instead become a prerequisite for effectively using AI programming tools, defining problems, and designing systems.
Related articles

Random Pruning of the DPO Computation Graph: 1.4x Training Speedup and Lower Peak Memory
DPO training too slow and memory-hungry? This paper proposes a random pruning framework for the DPO computation graph, sampling independently across position, sequence, and branch dimensions; branch pruning achieves a 1.426x step-time speedup and cuts training time by about 30%, with in-depth attribution of memory and time gains.

Why Does JEPA Underperform MLM in Longitudinal EHR Representation Learning?
New study compares JEPA and MLM for longitudinal EHR representation learning on MIMIC-IV: three JEPA variants train stably without collapse but underperform MLM; target size, not heterogeneity, drives prediction error.

Transfer Learning + Visible Light Communication: A New Approach to Energy-Efficient Indoor Positioning
A study proposes a transfer learning-based visible light communication indoor positioning method, achieving 47% accuracy improvement on the BOSCH factory dataset, 67.5% model efficiency under high noise, and introducing the ME composite metric for energy-efficient positioning in energy-constrained industrial IoT scenarios.