Jensen Huang Mobbed by Engineers in Taiwan: AI Frenzy Through Lex Fridman's Lens

Jensen Huang's Taiwan trip reflects the AI hardware race: liquid cooling, token economics, and the HBM bottleneck
Through Lex Fridman's lens, Jensen Huang's Taiwan trip appears as an engineer fan event but actually captures key signals of the AI infrastructure race. The new generation system achieves 100% liquid cooling, with assembly time compressed from two hours to five minutes and now in full production; Jensen Huang proposes a fundamental shift in CPU design logic—in the AI era, don't rent cores but generate tokens, with pricing units shifting from core count to throughput; HBM memory supply remains tight, making SK Hynix a key bottleneck in the computing chain. He also predicts a future dominated by voice control, while Lex Fridman believes typing is better for deep thinking. This informal exchange reveals that attention in the AI era is flowing toward those who control computing infrastructure.
When Jensen Huang Walks Into Taiwan: An Engineer's Star-Studded Encounter
Lex Fridman's camera captured a fascinating scene: Jensen Huang surrounded by a crowd of engineers in Taiwan, with people shouting "I love you," the atmosphere resembling a rock star's tour. Someone joked that Jensen Huang in Taiwan is like The Beatles in the '60s—except The Beatles could actually sing.
The value of this video isn't in the celebrity effect, but in how it captures the real atmosphere at the front lines of the AI hardware race. When the central figure of the world's most critical AI chip supply chain walks through Taiwan's streets and venues, the engineers' reactions reflect a fact: competition in AI infrastructure has penetrated into the capillaries of the industry.
100% Liquid Cooling: Reading the Pace of AI Hardware Evolution Through Engineering Details
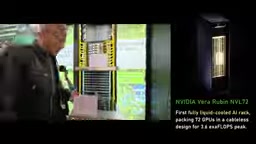
In the video, Jensen Huang showcased a key iteration: the new generation system achieves 100% liquid cooling, whereas the previous Grace Blackwell generation only had 80% liquid cooling. Behind this numerical change is an engineering philosophy that has been repeatedly validated—"things that are easy to build are also reliable."
Assembly time has been compressed from two hours to five minutes. The significance of this change goes far beyond efficiency gains alone. Against the backdrop of explosive growth in AI computing demand, delivery speed directly determines the pace at which data centers come online. When chip supply itself has already become a bottleneck, the speed of system integration becomes another critical variable.
Jensen Huang confirmed the system is "officially in full production." This means the closed loop from design to mass production has been completed, and what's tested next is the supply chain's throughput capacity.
The proliferation of liquid cooling in AI server domains stems from the widening gap between air cooling's heat dissipation capacity and GPU power consumption growth. Traditional data centers primarily rely on cold air passing through servers to carry away heat, but when a single AI accelerator card's power consumption breaks through 700 watts and a single rack's power consumption approaches 100 kilowatts, air's specific heat capacity and airflow efficiency are no longer sufficient to complete heat dissipation at reasonable energy costs. Liquid cooling works by directly attaching cold plates to heat-generating components and circulating coolant to carry away heat; its thermal conductivity is typically dozens of times that of air, allowing it to handle higher heat density in a smaller volume.
Going from 80% to 100% liquid cooling may seem like just a percentage change, but it actually involves a complete redesign of the system architecture: the remaining air-cooled portions are typically peripheral components like memory, power supplies, and network chips. Achieving full coverage requires rethinking the cold plate layout, tubing routing, leak detection, and quick-connector reliability for every heat-generating component. This is also one reason assembly time could be compressed from two hours to five minutes—modular liquid cooling tubing makes system assembly closer to plug-and-play, rather than connecting tubes one by one.
AI Doesn't Rent Cores, AI Generates Tokens
The most thought-provoking exchange in the video is Jensen Huang's explanation of the restructuring of CPU economics.
He pointed out a fundamental paradigm shift: the design logic of hyperscale CPUs in the x86 era was "being rented," and more cores were always better because the unit of pricing was "dollars per core." But in the AI era, this logic fails—"AI doesn't rent cores, AI generates tokens, then sells tokens."
This means the CPU's design goal shifts from "stacking core counts" to "completing the token generation loop as fast as possible." Jensen Huang summarized this business model with an extremely blunt statement: "The more you buy, the more you make."
Lex Fridman called him "the best salesperson in the world," and Jensen Huang didn't deny it, only saying "the technology is complex, but the business model isn't." This may be a key to understanding NVIDIA's strategy.
To understand the paradigm shift Jensen Huang described, one must first clarify the CPU pricing logic of the cloud computing era. In traditional virtualized data centers, a physical CPU is split into multiple virtual cores rented out to different tenants, and cloud providers charge by vCPU count and usage duration. Therefore, the CPU design goal is to pack in more cores and support more concurrent threads, enhancing a single chip's "rentability" value.
AI inference is an entirely different workload form: users request a prompt, and the system outputs results billed per token. In this process, the CPU mainly handles auxiliary tasks like data preprocessing, scheduling, and sampling, while the actual matrix operations are completed by GPUs or specialized accelerators. Therefore, the CPU's value is no longer "how many tenants can it accommodate simultaneously," but "how quickly can it feed data to accelerators and complete a generation cycle." When inference pricing is measured per million tokens, throughput—not core count—directly corresponds to revenue. This is the technical foundation of Jensen Huang's "the more you buy, the more you make" business logic.
The Five-Layer Cake and HBM: Making the AI Industry Chain Tangible
During the conversation, Jensen Huang mentioned the analogy that "AI is a five-layer cake." Although the original material didn't elaborate on the details of each layer, the intent is clear: AI is not a single technology, but a stacked structure from underlying hardware to upper-layer applications.
The SK Hynix segment in the video further confirms this. Jensen Huang paused at SK Hynix's booth, calling it "the legendary high-bandwidth memory company," and mentioned the technical path of LPDDR memory entering data centers—"twice the bandwidth, half the power." He repeatedly said "please produce more," with a half-joking tone, but the supply-demand tension behind it is real.
"Supply is too tight, memory is too big"—this phrase appeared multiple times in the video, both a joke and a statement of fact.
High Bandwidth Memory (HBM) is one of the most expensive single components on AI accelerator cards. Its principle is to vertically stack multiple layers of DRAM chips through through-silicon vias, then package them with the GPU via a silicon interposer, achieving TB/s-level bandwidth over extremely short distances. Compared to traditional DDR memory connected externally through memory buses, HBM has lower power consumption and several times higher bandwidth, at the cost of complex manufacturing processes, low yields, and slow capacity expansion.
This explains why HBM has become the tightest bottleneck in the AI computing chain. A high-end AI accelerator card needs to carry multiple HBM stacks, and only a handful of manufacturers worldwide can stably mass-produce HBM, with SK Hynix holding the largest share thanks to its first-mover advantage. Jensen Huang repeatedly saying "please produce more" at SK Hynix's booth is not mere courtesy—even if GPU production capacity is sufficient, insufficient HBM supply would equally block complete system shipments. This also explains the LPDDR path into data centers that he mentioned: using mature low-power memory solutions from the mobile phone sector, with the compromise of "twice the bandwidth, half the power," to provide a second memory supply curve beyond HBM for inference scenarios.
Lex Fridman's Podcast and Jensen Huang's "Persona"
In the video, Jensen Huang proactively mentioned Lex Fridman's podcast—"a great podcast, very very long." This detail may seem like small talk, but it actually reflects a characteristic of information dissemination in the AI field: ultra-long conversations are becoming the primary vehicle for the spread of technical ideas.
Lex Fridman flew to Taiwan specifically to meet Jensen Huang, not just "happening to pass by." The two planned to spend several days together, with Jensen Huang saying he would show him around Taiwan. Such informal exchange scenarios often reveal industry leaders' true thinking better than formal launch events.
The Future of Voice Control and the Paradox of Thinking Speed
At the end of the video, there's a rather philosophical exchange. Jensen Huang predicted that "the future will be primarily voice-controlled," but Lex Fridman offered a counterintuitive view: typing sometimes helps thinking more than speaking.
"Speed isn't everything. Sometimes you need to pause and think."
This exchange may seem unrelated to AI, but it touches on a core question: as AI systems' interaction speeds accelerate, can human thinking rhythms keep up? In an era where token generation speed is measured in milliseconds, human cognitive bandwidth has instead become the bottleneck.
What This "Mobbing" Reveals
Stripping away the entertainment surface, this video records several industry signals worth noting:
The full production of the 100% liquid cooling system marks that thermal management solutions for high-density AI computing have entered a mature stage. The significant compression of assembly time means deployment efficiency is becoming part of competitiveness. The shift in CPU design logic from "core count" to "token generation speed" is reshaping chip architecture priorities. And the persistent tightness of HBM supply shows that memory bandwidth remains one of the tightest links in the entire AI computing chain.
The scene of Jensen Huang being mobbed in Taiwan is essentially a microcosm of where attention flows in the AI era—the scarcest attention is concentrating on those who control computing infrastructure.
One-line Summary
Jensen Huang's Taiwan trip reflects the AI hardware race: liquid cooling, token economics, and the HBM bottleneck
Paragraph Summary
Through Lex Fridman's lens, Jensen Huang's Taiwan trip appears as an engineer fan event but actually captures key signals of the AI infrastructure race. The new generation system achieves 100% liquid cooling, with assembly time compressed from two hours to five minutes and now in full production; Jensen Huang proposes a fundamental shift in CPU design logic—in the AI era, don't rent cores but generate tokens, with pricing units shifting from core count to throughput; HBM memory supply remains tight, making SK Hynix a key bottleneck in the computing chain. He also predicts a future dominated by voice control, while Lex Fridman believes typing is better for deep thinking. This informal exchange reveals that attention in the AI era is flowing toward those who control computing infrastructure.
Related articles

Beyond the Mainstream World: Security and Privacy Struggles in Overlooked Regions
Human-centered security research has long focused on the West, causing security solutions to fail in the mainstream world. Researcher Collins Minando draws on Kenyan mobile loan apps, internet café authentication dilemmas, and local expert studies across nine countries to reveal how socioeconomic constraints reshape privacy practices, and proposes mobile money privacy redesign and PETs deployment pathways.

Claude Reportedly Able to Hide Secret Messages in Benign Images
A Reddit post claims Claude Fable 5.1 can hide secret messages in benign images. This article reviews the background, image steganography principles, and potential security risks, and suggests a testing path from rumor to verification.

Federal Government Awards $85 Million; CFS to Develop Fusion-Specific Semiconductors
The federal government awards $85 million to Commonwealth Fusion Systems to develop conductors and power semiconductors for fusion plants. This article analyzes the significance of this funding for the fusion supply chain and commercialization path.