Jev Model Goes Viral: The Ultra-Fast Judgment Engine Built for Agents

Jev is a high-speed judgment model for Agents that replaces costly LLM if-decisions at a fraction of the price.
Jev is a dedicated small model that only makes judgments — never generates text — handling pick-one, scoring, and yes/no decisions in 70ms at hundreds of times lower cost, with reliable confidence scores. Unlike GPT-style or reasoning models, Jev's key advantage is calibrated confidence you can trust, enabling tiered logic where high-confidence results auto-execute and low-confidence ones escalate. For developers building Agents, especially in high-frequency scenarios like web automation testing, Jev decouples decision-making from generation so large models only intervene when truly needed.
Why Jev Is Suddenly Everywhere in China's AI Community
The Jev model has sparked widespread discussion in China's AI community, topping global search trends — ranking first in China, second in South Korea, seventh in Japan, while sitting at just 29th in its home country, the United States. This curious contrast reflects the reality that a massive number of Chinese developers are grinding away at Agent deployment, and Jev hits them right where it hurts most: cost and efficiency.
For anyone building Agents, Jev's value is immediate and concrete: it can dramatically reduce both execution time and cost. When your agent workflow is packed with "judgment" steps, calling a large model at every decision point means high latency and high fees. Jev offers a different path.
What Jev Actually Is
Jev doesn't generate text. It does exactly three things: pick one option from a list, assign a score, or output a yes/no. And every judgment comes with a confidence score.
In plain terms, it replaces the if decisions in your Agent — the ones that would normally require a full LLM call — with a dedicated small model. The official numbers are striking: results in 70 milliseconds, costs hundreds of times cheaper, and output tokens are free.
Plug it into a typical Agent workflow and you've decoupled decision-making from generation — letting a dedicated "referee" handle judgments instead of making your "writer" moonlight as a judge.
The technical category Jev belongs to is commonly known as a discriminative small model or router model, which is fundamentally different from generative large models. Generative models (like the GPT series) are trained to predict the next token, so they naturally excel at "writing." Discriminative models, on the other hand, are trained to make the best classification among a finite set of options. Their parameter counts can be extremely small (typically in the hundreds of millions to a few billion range), and inference requires far less compute than generative models. This is the structural reason Jev can push latency down to 70ms — it doesn't need to generate text token by token; it simply outputs a probability distribution at the output layer and picks the highest-confidence category. This architecture was already widely used in the classic NLP era (think BERT, RoBERTa). Jev's innovation is repackaging it as a "judgment-as-a-service" interface designed for Agent workflows, with a particular focus on confidence calibration.
Why It's So Fast: Three Different Training Philosophies
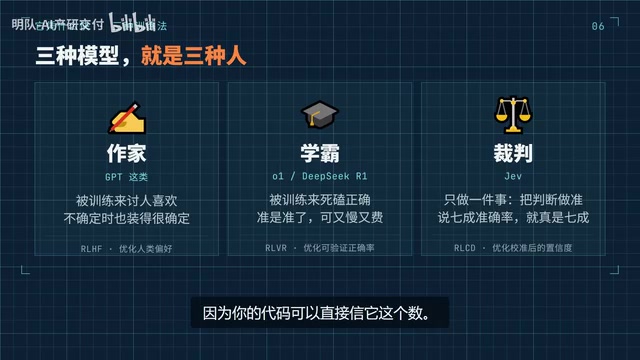
According to a Bilibili creator's analysis, the root of Jev's speed lies in how it was trained. He uses a vivid analogy, comparing the three types of models to three types of people:
Type 1: GPT-style Models — Trained to "Please People"
These general-purpose large models can chat and write, but their weakness is that they fake certainty even when uncertain — telling you they're 90% confident when the actual accuracy might be closer to 70%. Their confidence scores aren't reliable, so you can't take them at face value.
Type 2: DeepSeek-R1-style Reasoning Models — Trained to "Get It Right No Matter What"
These models grind through a problem repeatedly until they nail it. They're accurate, but slow and compute-heavy. Great for high-value, low-frequency complex tasks — not suitable for high-frequency judgments.
Type 3: Jev — Trained to Do One Thing: Judge Accurately
Jev's most critical trait is that "when it says it's right, it really is." If it says 70% accuracy, it's genuinely close to 70%. This reliability in confidence calibration means your code can directly trust its output.
One-sentence summary: large models are writers, reasoning models are overachievers, and Jev is the referee who just blows the whistle — no essays, just fast and accurate calls.
Confidence calibration is an important concept in statistics and machine learning. It measures how well a model's output probabilities align with its actual accuracy. A "well-calibrated" model should be correct roughly 80% of the time across all predictions where it says "I'm 80% confident." General-purpose large models are widely known to suffer from overconfidence — they tend to output confidence scores close to 100% even when actual accuracy is much lower. This happens because the RLHF (Reinforcement Learning from Human Feedback) training process rewards models for giving answers that sound definitive. Jev addresses this through targeted training techniques (potentially including temperature scaling, Platt scaling, or specialized calibration loss functions) to correct this bias, making confidence numbers statistically meaningful and directly usable as decision thresholds in engineering code.
Confidence Tiering: Making Judgments Actually Usable
Jev's real engineering value lies in the fact that its confidence scores can directly drive a tiered decision logic:
- Above 90%: Execute automatically
- 60% to 90%: Route to a human for review
- Below 60%: Don't act at all
This tiered strategy only works because the confidence scores are trustworthy. The creator cited a real-world example of booking international flights: the entire flow took just 7 seconds end to end, with browser-level calls dropping from over a thousand down to about a hundred. The speed comes from the fact that every step — which button to click, what to fill in — no longer waits for a large model to respond. Jev makes the call instantly.
For Agent developers, this kind of speed and cost control is a genuine game-changer.
Four Areas Most Worth Retrofitting with Jev
Drawing on his previously open-sourced QA Agent, the creator distilled several specific scenarios where Jev delivers the most value. In his Agent, the web automation component consumes the most tokens — opening pages, logging in, clicking elements, taking page snapshots — every step requires feeding the entire page to a large model before it can decide what to do next, adding up to dozens of round trips per test case.
1. Element Selection in E2E Testing
A button is clicked and a modal pops up — should it be dismissed? Which element should be clicked next? These "pick one of three" decisions are perfect for Jev, which returns a confidence-scored choice in 70ms.
2. Failure Classification
A test case fails — is it a script error, a product bug, or an environment issue? Feed these options into a "pick one of five" judgment and Jev can categorize the failure quickly.
3. Pass/Fail Gate Decisions
Did this test case pass or not? Let Jev give an initial yes/no with a confidence score, and only escalate uncertain cases to a large model for review.
4. Regression Re-runs — The Biggest Win
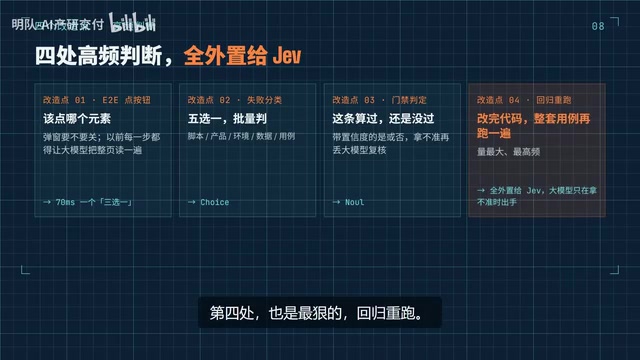
Running the same scripts repeatedly at high volume and frequency is a classic "cost black hole." Offloading all these judgments to Jev — with the large model only stepping in when Jev is uncertain — is where the biggest savings are. This is the highest-ROI retrofit.
The QA Agent described here belongs to the web E2E testing space, where the core workflow involves an agent operating a browser like a real user: opening pages, locating elements, triggering interactions, and comparing screenshots. These agents make extremely dense calls to large models because every step of "where to look, what to click" requires understanding the page's DOM structure or screenshot content. In traditional approaches (like Playwright + LLM), a single complete test case can easily require dozens of LLM calls, with token consumption and latency as the primary bottlenecks. Replacing purely judgment-based steps (like "does this modal need to be closed?") with Jev is equivalent to inserting a high-speed caching layer into the agent's decision chain — only complex reasoning that Jev can't handle escalates to the large model. This is the logic behind the "from over a thousand calls down to a hundred" figure mentioned earlier.
Jev Isn't a Replacement — It's a Division of Labor
Jev's role isn't to replace large models; it's to work alongside them with a clear division of responsibilities: the large model handles "writing" and "responding," Jev handles "judging," and the code handles "taking action." Each does what it does best, which is how you drive down both cost and latency at the same time.
Of course, Jev has clear limitations: it gives you a judgment but can't explain why it made that call. It also doesn't support image input yet. This means that for scenarios requiring explainability or visual understanding, large models still need to serve as the fallback.
Final Thoughts
If you're building Agents and you're being strangled by the cost of high-frequency judgments, this direction is worth experimenting with yourself. The creator plans to iterate Jev into his QA Agent and will continue open-sourcing the results. For developers struggling with Agent execution efficiency and token costs, the "dedicated judgment layer" architecture that Jev represents may be a seriously worth evaluating design choice.
Related articles

JobRunner MCP Server: AI Agents Can Now Fix Failed Java Jobs
JobRunner launches an open-source MCP server enabling AI agents to view cluster status, diagnose failures, and recover Java jobs—incident response from any cloud coding environment or existing agent.

MLAI Digital Launches 9 Security Agents: MCP Server Safeguards the Full Lifecycle of Agentic AI
MLAI Digital launches Security MCP Server with nine built-in specialized security agents covering vulnerability discovery, attack simulation, prompt injection detection, API and infrastructure assessment, and accelerated remediation—embedding security validation across the full Agentic AI lifecycle from development to production.

Running Isaac Lab on H100 GPUs: Exploring Better Approaches
Exploring optimization methods for running Isaac Lab on NVIDIA H100 GPUs, including MIG configuration, mixed precision, TensorRT acceleration, and community experience to improve robotics simulation and reinforcement learning efficiency.