Jev: The Ultra-Fast AI Decision Engine That Challenges the ChatGPT Architecture

ChatGPT co-inventor launches Jev, a decision model claiming 200× speed and 1/400th the cost of traditional LLMs.
Jev is a new AI product built over two years by a ChatGPT co-inventor, architecturally distinct from mainstream chat models. Using a custom RLCD training approach instead of RLHF, it's positioned as a general-purpose decision model rather than a conversational generator. Its standout advantages are extreme speed and cost — up to 200× faster than traditional LLMs at 1/400th the cost, with output tokens completely free. It excels in scenarios requiring massive parallel decisions, like customer service routing, real-time game control, NPC decision-making, and rebuilding Tesla FSD logic. Its claimed zero-hallucination property stems from outputs being constrained to structured option sets. Clear limitations include inability to write code from scratch, handle deep reasoning, or support interactive dialogue — but its speed alone proved decisive even in chess, where it won on time despite weaker play.
A New Bet from a ChatGPT Co-Inventor
The internet is buzzing about a new AI called Jev, and its most striking feature comes down to a single word: speed. Related posts have racked up nearly 30 million views. The person behind it is no small name — he was one of the co-inventors of ChatGPT, yet he's now brought something architecturally unlike ChatGPT in almost every way.
According to the founder, he spent two years in "stealth mode" building an entirely new training approach called RLCD (Reinforcement Learning for Calibrated Decisions) — a deliberate departure from the RLHF (Reinforcement Learning from Human Feedback) that powers ChatGPT. His core challenge: why hasn't a chat model that surpasses human ability brought us any closer to AGI?
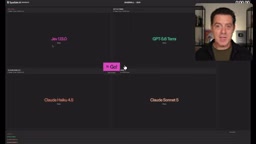
His answer is to take a different road entirely. Jev isn't a chat model — it's a general-purpose decision model. Feed it any decision that needs to be made, and it handles it, processing thousands of decisions in parallel within seconds. The team claims it can run up to 200× faster than traditional large models at as little as 1/400th of the cost. Because output token costs are pushed so low, they've made output tokens completely free and unlimited, with input tokens priced at just a fraction of a cent.
The Difference Between RLHF and RLCD
RLHF (Reinforcement Learning from Human Feedback) is the core alignment technique behind mainstream large models like ChatGPT: the model generates multiple candidate responses, human annotators score them based on subjective preference, those scores train a "reward model," and reinforcement learning is used to push the AI toward outputs humans find satisfying. This approach makes models seem "smart, fluent, and likable" — but critics point out that it's fundamentally optimizing for "what humans think is good" rather than "what is objectively correct." When human raters make mistakes or carry biases, the model can learn flawed judgment patterns, which is one source of hallucinations.
RLCD (Reinforcement Learning for Calibrated Decisions) shifts the optimization target from "human satisfaction" to "decision calibration" — meaning the model's confidence levels should closely match its actual accuracy rates, avoiding both overconfidence and excessive hedging. This approach has a research foundation in fields like financial risk management and medical diagnostics. The core goal is for the model to "know what it knows and what it doesn't," so it can deliver trustworthy, structured judgments in critical scenarios rather than fluent-but-potentially-wrong prose.
Decision Engine: What It's Good At, and What It Isn't
Jev is best understood as a "decision engine": give it a state or a batch of information, and it makes judgments — not one at a time sequentially, but hundreds or thousands of decisions in parallel.
A typical example is customer service ticket routing. When a user complains "I was charged twice and this needs to be resolved today" along with account details (Pro plan, account age 420 days), Jev can determine in milliseconds: what type of request is this? Does it need urgent handling? What's the priority? It outputs conclusions directly from a given set of options.
In benchmarks, the team shows Jev matching Luna, Tara, and Sonnet 5 on metrics like type safety — and even outperforming Opus 5 — at a fraction of the price.
That said, the founder is candid about the trade-offs. Jev is not suited for writing code from scratch or for interactive conversational dialogue. Its use case is more like: "I have a question — or a thousand questions — answer them as fast as possible." The team even calls out directly that Jev will clearly underperform ChatGPT or Claude on tasks requiring deep reasoning, like playing chess.
Their tagline is pointed: "We're building prod, not God" — widely read as a direct jab at Anthropic.
The Fundamental Difference Between a "Decision Model" and a "Generative Model"
Mainstream large language models (LLMs) are autoregressive generative models at their core: they predict one token at a time, outputting word by word — inherently serial. This architecture makes them excellent at coherent reasoning, open-ended writing, and multi-turn conversation, but single-inference latency is relatively high, and the cost of processing large numbers of independent problems scales linearly.
Decision models are designed differently: given a state space and a finite set of action options, the model's task is to select the optimal action from a discrete set rather than generate arbitrary free-form text of any length. This kind of task is naturally parallelizable — 1,000 independent routing decisions can be reasoned about simultaneously without waiting on each other's results. This also explains why Jev's output token costs are so low: its outputs are typically short, structured labels or action commands (e.g., "high priority / refund / escalate to human") rather than multi-paragraph explanatory responses. This design trade-off delivers order-of-magnitude advantages in throughput and latency, while giving up the ability to handle open-ended tasks that require extended reasoning.
Zero Hallucination: Reliability for Mission-Critical Tasks
Another heavily emphasized selling point is Jev's claimed zero hallucination. The founder's logic: RLHF optimizes models to please humans, and humans make mistakes — that's one of the root causes of hallucinations in traditional large models. While hallucination rates have dropped significantly over the past few years, in certain scenarios even a single hallucination is catastrophic — medical diagnosis, military target identification, traffic control, and other life-or-death decision contexts have virtually no tolerance for error.
For enterprises that need to make thousands of decisions per second, this combination of speed, cost, and reliability is extremely compelling. The video mentions connecting batch data from emails or customer service requests into Jev via automation platforms like Zapier, completing decisions in workflows at a fraction of the cost and hundreds of times faster. (This is sponsored content in the video, presented here purely as a use-case illustration.)
Context and Limitations of the "Zero Hallucination" Claim
"Hallucination" refers to a large model confidently outputting content that doesn't match reality — one of the core challenges facing all generative AI today. Mainstream evaluations (such as TruthfulQA and HaluEval) show that even the most advanced models still have error rates of several percentage points on factual Q&A.
It's important to note that "zero hallucination" claims are typically made in the context of specific task formats. When a model's output space is strictly constrained to a predefined set of options (e.g., route to Department A / B / C — pick one), it is physically incapable of "inventing" a non-existent option, structurally sidestepping the hallucination problem. This is an entirely different context from hallucinations in open-ended text generation. Jev's "zero hallucination" is more accurately understood as: within the domain of structured decision tasks, outputs are constrained to the legal action space, avoiding the factual fabrication issues of traditional models — it does not mean the system is incapable of any error whatsoever across all tasks.
Jaw-Dropping Real-Time Demos
What really made Jev go viral was a series of live demos that were nearly impossible to follow with the naked eye.
Playing Doom in real time: Jev is embedded directly into the game loop, observing the screen and making action decisions in real time — so fast it appears to have zero latency.
Wiki Race: The model navigates from one Wikipedia page to a target page by clicking links. The video compares Jev, Tara 5.6, Haiku 4.5, and Sonnet 5 side by side — Jev completes a 3-hop path so fast the eye can barely catch it, and finishes a 5-hop path in just half a second, while the other models each take around 4, 5, and 5 seconds respectively.
Small-town NPC decisions: The author built a small-town scene using other tools, with 50 characters all driven by Jev. After broadcasting "big sale at the bakery," 50 independent decisions are produced within 0.6 seconds: 39 characters continue what they were doing, 6 go check it out, 4 participate, and 1 goes to tell others. With a more "urgent" prompt (go to the fountain or be bitten by a snake), the vast majority of characters immediately rush toward the fountain.
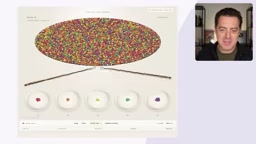
Sorting 150,000 Skittles: Using chopsticks to pick up and sort candies one by one into five color-coded bins. Even at maximum speed, the model makes decisions in parallel — directing the chopsticks one piece at a time, telling it which candy to grab and which bin to drop it into.
Community-Built Applications and a Chess Match
After Jev launched, the community quickly produced a wave of creative applications that showcase its unique value as a "decision layer":
- Model Router: Riley Brown built a model router where Jev itself doesn't answer questions — it decides which model is the most appropriate and most cost-effective to route a given prompt to.
-
Unclutter Ad Blocker: Built by Kitsi, this uses Jev to automatically remove web ads and junk content in fractions of a second. It's open source, requires your own API key, and costs just a few cents per month.
-
Rebuilding Tesla FSD: Justin Schroeder rebuilt Tesla's Full Self-Driving logic using Jev in under an hour — decisions about accelerating, steering, and stopping at stop signs are all made by Jev in real time.
-
Real-time control in Super Smash Bros. Melee: Team member Alex uses Jev to control characters in the game in real time.
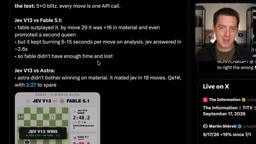
The chess weakness also had a direct head-to-head test: against Fable, Jev was outclassed in pure chess strength — by move 29 it was down 16 pieces with a second queen promoted. But while Fable spent 6 to 15 seconds analyzing each move, Jev only needed 2.6 seconds. The result: Fable lost on time — meaning in bullet chess, Jev could win almost every game just by running out the clock. This detail neatly captures Jev's essence: it trades single-point decision depth for extreme speed.
Speed as Value
Jev represents a way of thinking fundamentally different from mainstream chat models — structured, decision-oriented, ultra-fast, and ultra-cheap. It isn't a do-everything solution; writing code from scratch, deep conversational dialogue, and complex multi-step reasoning are not its strengths. But for scenarios requiring massive, parallel, low-latency decisions, the triple advantage of speed, cost, and reliability could open up entirely new application spaces.
As the video concludes: we're only just beginning to understand how to use it. As more developers get their hands on it, how much value raw speed can actually deliver will become clearer.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.