Jev: TypeSafe AI's First System 1 Model, Built Exclusively for Data Classification

Jev is a System 1 classification model: 40–200x faster than LLMs, near-zero cost, and format-perfect every time.
TypeSafe AI's Jev challenges conventional AI model expectations: it doesn't generate text or write code — it only classifies data, but does so at remarkable speed (70–500ms) and minimal cost ($0.04/million input tokens, free output). Inspired by Kahneman's System 1/System 2 framework, Jev handles fast intuitive judgment tasks rather than slow reasoning. Its core value is absolute output format reliability: define a TypeSafe JSON schema, and it returns exactly that structure, with confidence scores for accuracy calibration. Ideal for email classification, content moderation, and jailbreak detection — any task you could judge intuitively in under 10 seconds. Think of it as a callable function or an if statement, not a replacement for general-purpose LLMs.
Another new model has dropped — but this one is nothing like the LLMs we're used to. It won't write code, doesn't excel at generating long-form text, and won't show up on any "most powerful new model" leaderboards — because it was never designed for those use cases. Jev, released by TypeSafe AI, does exactly one thing: data classification — and it does it exceptionally well.
A Counterintuitive Model Positioning
Jev's core function isn't text generation. It takes in data, organizes and classifies it, then returns results in perfectly TypeSafe JSON format. You give it a format specification, and it outputs strictly according to that format — almost without fail. This means it's not meant to replace general-purpose models like Fable or Astra. If you're currently using those expensive large models for tasks that Jev could handle, it's worth rethinking your cost structure.
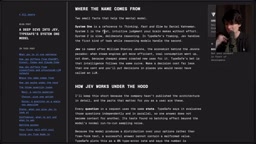
The core concept behind Jev is the "System 1 model," inspired by Daniel Kahneman's Thinking, Fast and Slow. System 1 is the brain's fast, intuitive judgment — glancing at something and immediately knowing "that shirt is blue." System 2 is slow, deliberate reasoning. In TypeSafe AI's framework, Jev handles the first type of task, while reasoning models continue to handle the second. The model's name is a reference to Jevons Paradox: when steam engines became more efficient, coal consumption actually increased, because cheaper power got applied to more places. This is exactly the right lens for understanding Jev — it doesn't unlock entirely new capabilities, but makes existing capabilities fast enough and cheap enough to deploy at scale.
Jevons Paradox was proposed by 19th-century British economist William Stanley Jevons. In 1865, he observed that improvements in steam engine efficiency didn't reduce Britain's total coal consumption — it dramatically increased it, because lower unit costs triggered broader adoption. The same analogy holds in AI: when the cost of inference or classification drops 100x, companies don't just do the same things for less money. Instead, they embed AI decision-making into hundreds of processes that were previously too expensive to automate. Jev's name thus implies a prediction about scale effects: ultra-low classification costs will generate entirely new use cases, not just optimize existing ones.
Who Built It and Why It's Fast
According to the video author, Jev was built by Diogo, a former OpenAI employee who worked on ChatGPT and RLHF. While RLHF is excellent at shaping model behavior, it offers limited benefit for classification tasks. Diogo's insight was that by focusing specifically on classification rather than general text generation, he could achieve extreme speed and cost advantages.
The result is a set of figures that seem almost absurd: input tokens at roughly $0.04 per million, compared to ~$10/million for models like Fable; and output tokens are completely free — described as "too cheap to meter." On speed, tasks that take traditional LLMs 3 to 300+ seconds take Jev just 70 to 500 milliseconds — that's 40 to 200 times faster.
To achieve this, the team built an automation-focused stack from scratch: a new model architecture, a parallelized sampler optimized for extreme efficiency, and a training method they call "calibrated decision reinforcement learning." The first public version is currently in invite-only early access, accessible via OpenRouter, Vercel AI Gateway, and similar channels.
RLHF (Reinforcement Learning from Human Feedback) is the core training method for aligning large language models with human preferences: human annotators compare and score model outputs, a reward model is trained on those signals, and reinforcement learning pushes the generative model toward higher-scored outputs. RLHF is excellent at shaping tone, safety boundaries, and instruction-following style — but for tasks like "output a structured JSON classification label," its training signal is too vague. The reward function can't precisely measure classification speed or format compliance. Diogo's decision to abandon RLHF in favor of a classification-specific "calibrated decision reinforcement learning" approach trades away general text generation entirely in exchange for extreme speed and structural compliance.
Calling Intelligence Like a Function
The key to understanding Jev is to think of it as a "function call to frontier intelligence": unstructured state goes in, typed probabilistic decisions come out. You feed it a pile of messy text data, and you get back a type-safe structure.
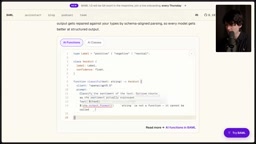
This kind of need has been addressed before — notably by BAML, which the author speaks highly of. BAML is essentially a "glue language" that sits between agents and real code, using TypeScript-like syntax to define output formats and fixing JSON formatting errors from model outputs at runtime. The author had used GPT-OSS-120b with BAML to filter comments mentioning sponsors and had a great experience — but once he stepped outside of BAML, he found that GPT-OSS-120b had nearly a 50% chance of outputting malformed JSON.
What makes Jev different: it simply cannot output the wrong format. You give it a JSON schema, it returns that schema. One clarification worth making is around "determinism" — the output shape is deterministic, always conforming to your defined format; but the content is not deterministic, just highly reliable. This is the real value of structured output: LLMs by nature aren't deterministic, but Jev lets you call it as reliably as you'd call a piece of code.
Notably, Jev provides confidence scores and uncertainty estimates with every output, letting you calibrate around accuracy — which solves the classic automation problem of traditional models that are "right 95% of the time, but never tell you when you're in that 5%."
BAML (Boundary Markup Language) is an open-source framework specifically designed to solve the engineering problem of getting LLMs to reliably output structured data. It lets developers declare expected output structures using TypeScript-like syntax, automatically injects those structure definitions into prompts at call time, and applies fault-tolerant JSON repair at runtime — handling common issues like truncated quotes or trailing commas. BAML's very existence illustrates how widespread the problem is: even GPT-4-class models have a significant probability of outputting non-compliant JSON without explicit constraints. Jev's architectural choice eliminates this problem at the root — structured output isn't the result of post-hoc repair, it's the direct output form of the model's inference, making format errors theoretically impossible.
What It Can and Can't Do
Any scenario requiring classification is a candidate for Jev: organizing YouTube videos by topic, determining whether emails are important and categorizing them, content safety and moderation, detecting jailbreak attempts, and more. The author demonstrated a number of these.
The most vivid example was a checkers game he built: Jev receives the board state (as data, not an image — it has no vision capability), and returns a move decision almost instantly. The speed is genuinely impressive — but it's not particularly smart. The author said he "beat it without really trying." This illustrates the point perfectly: it's not using the reasoning part of its brain, it's just processing data.
Other demos are equally striking: classifying 1,500 emails at an average of 200ms per email, processing 38 per second; classifying 1,118 code conversation threads and 32,311 messages at a total cost of just 37 cents; booking a flight in 7.1 seconds by reading HTML and making navigation decisions directly. It can even drive Doom in real time — running 10 times per second at under $7 per hour.
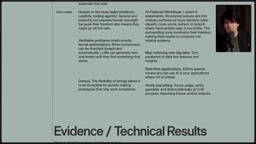
But the author repeatedly emphasizes the boundaries. When someone asked whether it could serve as a judge, evaluating the outputs of four different LLMs, the author was flat-out against it — it's both expensive and absurd. Jev only uses "half a brain"; it doesn't have the reasoning capacity needed to distinguish between the quality of different LLM outputs. Its context window is only 32K tokens, and it's essentially "as smart as a switch statement."
The Overhyped Use Cases
The author is direct about several use cases that have been oversold. Braintrust suggested using Jev to replace LLM judges for scoring agent outputs — the author thinks this is a bad idea. Writing a good judge prompt doesn't take that long, and using a non-reasoning model for evaluation only reduces trustworthiness.
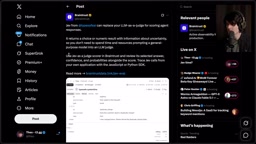
More controversial is the suggestion of using Jev for context compaction. The author explains in detail why this doesn't work: compaction isn't filtering, it's synthesizing a summary based on the full history. Jev has neither tool call output results nor model reasoning data (labs stopped returning reasoning tokens long ago), and its 32K context is nowhere near sufficient. Modern models have also been fine-tuned with compaction in mind during training, so altering the history they see tends to backfire. Cache invalidation issues would also cause costs to rise rather than fall. People have already tested this approach in practice and found it performs poorly. "Its only advantage is that it's fast enough to fit into the average Twitter user's attention span, which is exactly why the video will go viral."
How to Think About Jev
The author offers a simple heuristic: after taking in all the information, how long would it take you to answer this question? If under 10 seconds (like judging the color of a shirt), Jev is probably a good fit. If it takes more than 10 seconds of deliberate thought, it's not.
Jev is a System 1 model — System 2 is you thinking through a problem, while System 1 is your brain reacting for you, like the reflex when someone taps your knee. Its value isn't in replacing Codex, Claude, or the tools in your terminal. It's in making a wide range of classification, sorting, and rapid decision-making scenarios that were previously impractical become fast and cheap.
In other words, don't treat it as a "reasoning farm" for generating code or text. Think of it as a newly installed library or a callable function — use it like an if statement. With the right mental model, this is a genuinely exciting tool.
Kahneman's Dual Process Theory divides human thinking into two modes: System 1 is fast, automatic, and unconscious — relying on pattern matching and intuition with almost no cognitive cost. System 2 is slow, deliberate, and conscious — responsible for logical reasoning, planning, and complex judgment, consuming significant attention. In AI engineering practice, this framework provides a mental model for task routing: hand System 1-type tasks (classification, filtering, rapid labeling) to specialized lightweight models, and System 2-type tasks (code generation, multi-step reasoning, complex decision-making) to reasoning models, rather than routing everything through a single high-cost model. Jev's arrival makes this kind of architectural layering practically viable for the first time in terms of both cost and latency.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.