JevForest: A Deep Dive into Path Voting for Budgeted Feature Acquisition

JevForest uses path voting for budgeted feature acquisition, but experiments show its advantage is highly task-dependent.
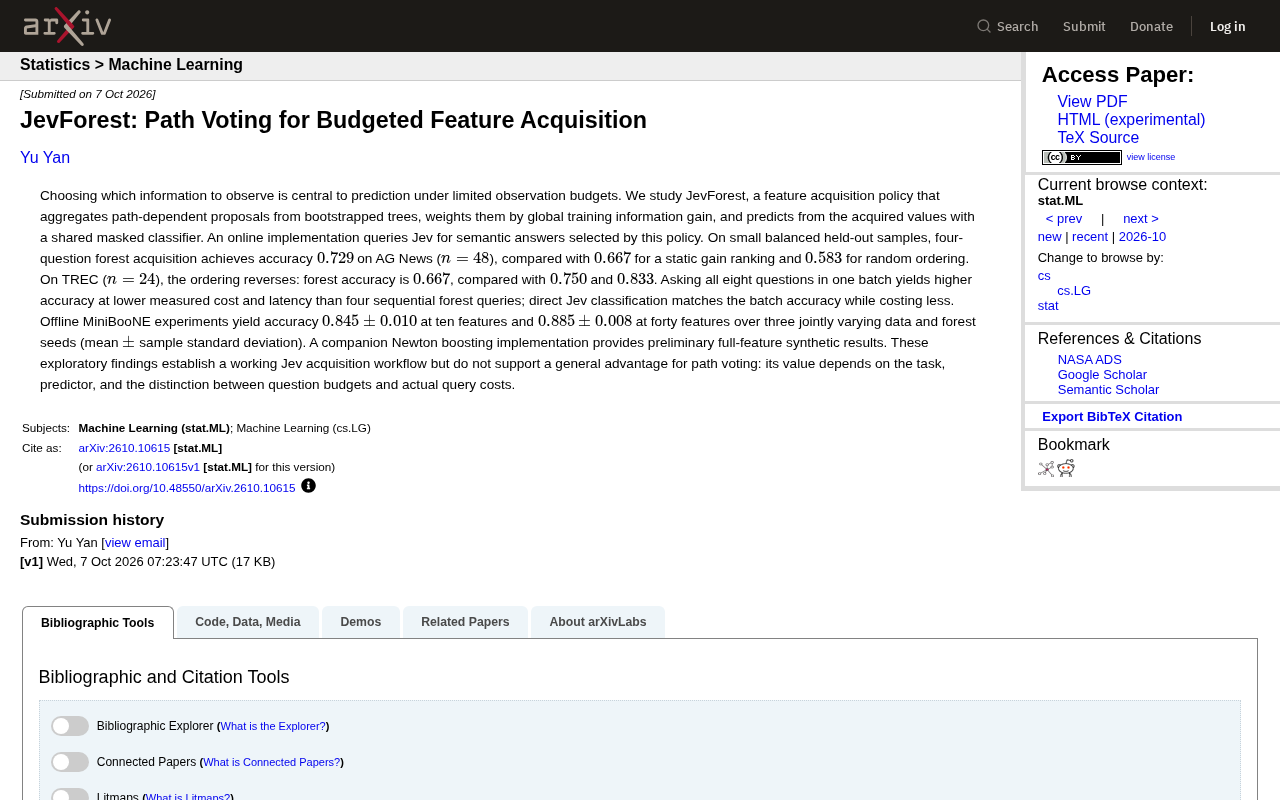
JevForest is an ensemble learning approach for budgeted feature acquisition that uses path-dependent proposals from bootstrapped decision trees, weighted by global training information gain, with a shared masked classifier for prediction. Experimental results are presented as exploratory: path voting outperforms static and random ranking on AG News, but the results completely reverse on TREC, where random ordering wins. More notably, batch querying outperforms sequential forest queries on accuracy, cost, and latency alike — exposing the fundamental gap between "question budget" and "actual query cost." The authors explicitly state that evidence does not support path voting having universal advantages, urging task-specific validation before assuming dynamic strategies beat simple baselines.
Background: When Observation Budgets Are Limited, What Should You Look At First?
In many prediction tasks, acquiring each feature comes at a cost — whether in time, money, or compute. Every diagnostic test in clinical settings has a price tag; every additional question in an interactive QA system adds latency. The core challenge becomes: under a limited observation budget, which information should you prioritize to maximize predictive accuracy?
JevForest, presented in an arXiv paper (arXiv:2610.10615v1), addresses exactly this problem, proposing a feature acquisition strategy that tackles a classic but still difficult question: how to make reliable predictions under incomplete observations.
The Core Mechanism: Path Voting
JevForest's design can be broken down into three key components:
1. Aggregating Path-Dependent Proposals from Bootstrapped Trees
The method builds on bootstrapped decision trees. Each tree proposes which feature to observe next along its decision path — a path-dependent approach, meaning feature acquisition recommendations update dynamically as new information is observed.
Bootstrap Sampling is a random sampling technique with replacement, widely used in ensemble methods like random forests. Each decision tree is trained on a random subset of the original dataset, creating structural diversity across trees. Path-dependence in the decision tree context means that as you traverse from root to leaf, each split decision is conditioned on the previous one. When a feature has already been observed, the recommendation for "what to ask next" updates dynamically along the corresponding subtree branch — rather than remaining fixed. This contrasts sharply with static feature ranking methods, which pre-determine acquisition order without reference to any observed values. The key advantage of path-dependence is the ability to prune based on actual feedback, avoiding the acquisition of features that offer no discriminative value for the current sample. The trade-off is higher computational complexity and less predictable model behavior.
2. Weighting by Global Training Information Gain
Proposals from different trees are not treated equally — they are weighted by global training information gain. Features with higher information gain carry more weight in the vote. This grounds the acquisition process in classical decision tree theory and provides a quantitative basis for prioritization.
Information Gain is a core metric in decision tree splitting criteria, measuring the reduction in class uncertainty (typically quantified via Shannon entropy) achieved by splitting on a given feature. Formally: Information Gain = parent node entropy − weighted sum of child node entropies. Higher information gain indicates greater discriminative power. In JevForest, "global training information gain" refers to information gain computed over the entire training set, not just the current sample's path. This provides a consistent reference for cross-tree voting: even when different trees produce different local splits on the same feature, the global gain serves as a common yardstick, naturally giving higher-discriminability features more weight in the aggregated vote. This design essentially strikes a balance between dynamic path-dependence (local) and global feature importance (global).
3. Prediction via a Shared Masked Classifier
After acquiring feature values, JevForest uses a shared masked classifier to make predictions based on the observed values. The masking mechanism allows the model to handle partially missing inputs — an essential capability in budget-constrained settings.
The paper also provides an online implementation: by querying Jev for semantic answers, the strategy selects which questions to ask, forming a complete interactive feature acquisition workflow.
Experimental Results: The Advantage Is Not Universal
One of the most honest — and important — aspects of the paper is its refusal to claim universal superiority for path voting. The experimental results show clear task dependency.
Diverging Results on Text Classification
On the AG News dataset (n=48), the forest acquisition approach using four questions achieved an accuracy of 0.729, outperforming static gain ranking at 0.667 and random ordering at 0.583. This suggests that dynamic path voting does provide measurable benefit on this task.
But on the TREC dataset (n=24), the ranking completely reverses: the forest method achieves only 0.667 accuracy, while static gain ranking reaches 0.750 — and random ordering is best at 0.833. The same method performing in opposite directions on two similar text classification tasks is a clear warning sign.
Batch Querying vs. Sequential Querying
A practically important finding is that asking all eight questions at once in a batch not only yields higher accuracy but also shows lower measured cost and latency compared to four sequential forest queries. Going further, directly classifying with Jev achieves accuracy comparable to the batch approach at even lower cost.
This finding is a reminder that question budget and actual query cost are not the same thing. Sequential decision-making may save on the number of questions asked, but it doesn't necessarily save on real-world cost and latency.
This finding touches on a fundamental tension in Budgeted Learning: the theoretical "question budget" and the engineering reality of "actual query cost" are often different things entirely. Sequential decision frameworks assume you must wait for results after each query before deciding what to ask next — introducing multiple round-trip latencies. Batch queries, by contrast, can be issued in parallel, with total latency determined only by the slowest request. This gap is especially significant in LLM or external API call scenarios, where four serial calls may take several times longer than a single batch call. Evaluating feature acquisition strategies therefore requires examining question/feature count, actual monetary cost, end-to-end latency, and accuracy degradation — not just the single dimension of "how many features were used."
Offline Experiments: MiniBooNE and Newton Boosting
In offline MiniBooNE experiments, JevForest achieves 0.845±0.010 accuracy with ten features, improving to 0.885±0.008 with forty features (reported as mean ± sample standard deviation across three sets of jointly varied data and forest random seeds). The paper also provides a companion Newton boosting implementation with preliminary full-feature results on synthetic data.
Interpreting These Exploratory Findings
The authors frame these results as exploratory — a notably restrained and professional stance. The work establishes a functional Jev feature acquisition workflow, but explicitly states that the evidence does not support path voting having a universal advantage.
Its value is highly dependent on three factors:
- The task itself: The opposite results on AG News vs. TREC are the clearest illustration;
- The predictor used: The masked classifier, direct classification, and Newton boosting all behave differently;
- The distinction between question budget and actual query cost: Saving questions sequentially does not mean saving real-world cost.
For researchers and practitioners, this means that before adopting any "intelligent feature acquisition" strategy, you should validate it thoroughly on your specific task — rather than assuming dynamic path voting will naturally outperform simple static ranking or batch querying.
Implications for Feature Acquisition Research
JevForest's contribution may lie less in providing an optimal solution and more in using rigorous controlled experiments to reveal the complexity of the feature acquisition landscape. Random ordering beating a carefully designed forest method on TREC, and batch querying outperforming sequential decision-making — these counterintuitive results are precisely the most valuable reminders in the field.
In practical system design, evaluation metrics should expand beyond pure "number of questions" to encompass the joint trade-off between real-world cost, latency, and accuracy. Sometimes the simplest strategy — batch acquisition or direct classification — turns out to be the best one.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.