Jointly Modeling Multivariate Ordinal Preferences: A New Framework Beyond Pairwise Comparisons

New paper proposes a joint MRF model for ordinal preferences, avoiding lossy coarsening into pairwise comparisons for better LLM alignment.
Existing preference modeling methods like Bradley–Terry and Plackett–Luce suffer from two flaws: treating multi-dimensional rating attributes in isolation and converting ordinal scores into coarsened win-loss comparisons, causing information loss. This arXiv paper proposes a covariate-dependent consecutive ratio Markov random field model that jointly models multiple ordinal attributes while incorporating covariates such as user features, fully preserving ordinal structure and inter-attribute correlations. Theoretically, the authors prove that classic models like Bradley–Terry are special cases of this joint model; practically, they develop a dedicated maximum likelihood inference procedure to handle MRF's intractable normalizing constant. The work has direct implications for RLHF alignment pipelines and recommendation systems: how preference data is modeled is itself a key variable in alignment quality.
Starting from Human Preference Data
Whether the goal is aligning large language models with human preferences or building recommendation systems, researchers inevitably work with a special type of data — multivariate ordinal data with covariates. This kind of data is extremely common in practice.
Take the classic MovieLens dataset: users rate multiple movies on a 1-to-5 scale, and the dataset also includes demographic information such as user age and gender. Similarly, the HelpSteer dataset used for LLM alignment collects human feedback on multiple dimensions of model responses — such as "helpfulness" or "verbosity" — each rated on an ordinal scale, with those ratings depending on the specific prompt-response pair.
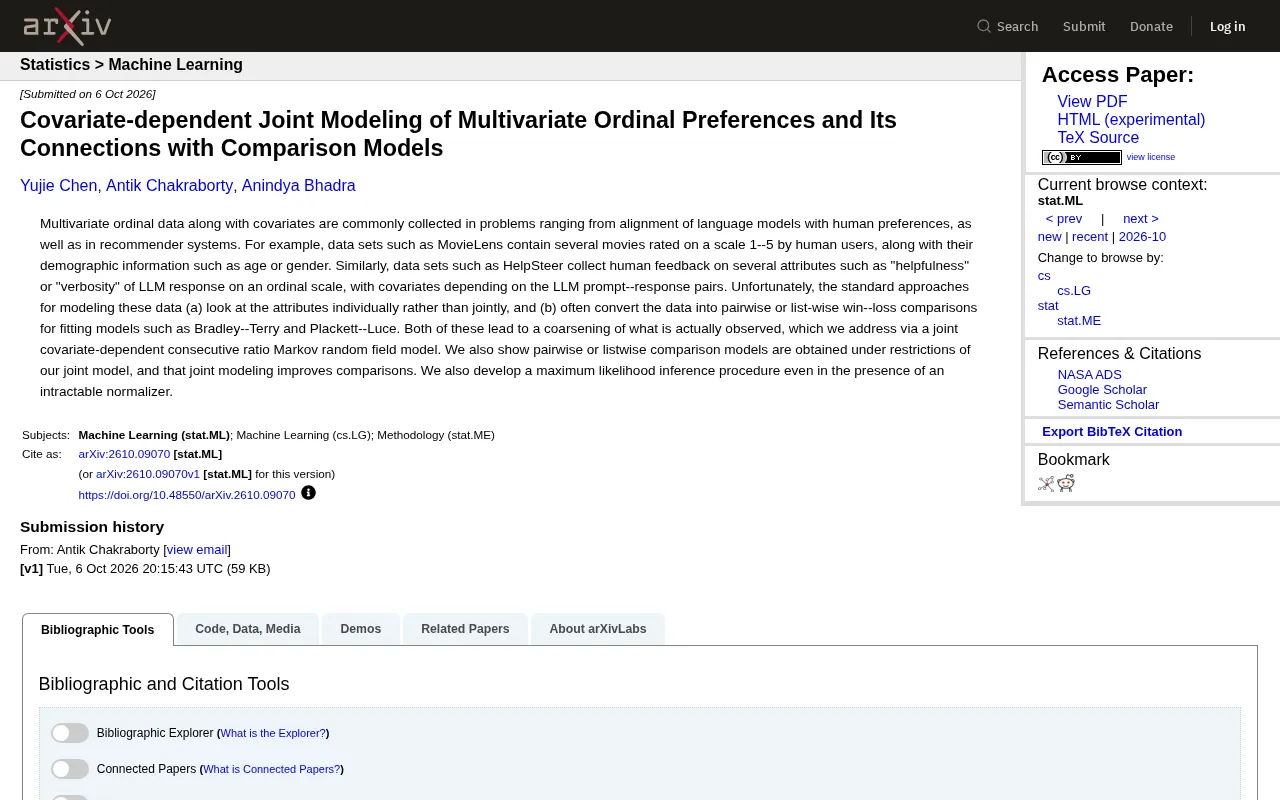
The core characteristics of this type of data are: ratings are ordinal (1 is clearly lower than 5, but the differences are not necessarily equidistant), often multidimensional (an object is evaluated on multiple attributes simultaneously), and influenced by external covariates. How to properly model this structure directly affects the quality of preference learning and model alignment.
Two Key Limitations of Existing Methods
This new arXiv paper identifies two notable flaws in standard modeling approaches.
The first problem is treating each attribute in isolation. Traditional methods tend to analyze each dimension independently, ignoring joint dependencies between attributes. In reality, "helpfulness" and "verbosity" are often correlated — an overly brief response may sacrifice helpfulness, while a verbose response isn't necessarily more helpful. Modeling dimensions in isolation loses these important correlation signals.
The second problem is converting data into pairwise or listwise win-loss comparisons. Many mainstream models, such as the Bradley–Terry model and the Plackett–Luce model, require first converting ordinal ratings into "who beats whom" comparison format before fitting. The paper's authors argue that this conversion is essentially a form of "coarsening" of the true observed data — fine-grained ordinal ratings are compressed into binary or ranking outcomes, and information is lost in the process.
These two limitations together mean that comparison-based preference models may fail to fully exploit all the signal embedded in the data.
The Bradley–Terry model is the most classic framework for comparative preference modeling, dating back to 1952. It assumes each candidate has a latent "strength" score, and the probability of one object defeating another is determined by the logistic transformation of their respective strength scores. The Plackett–Luce model is its generalization to ranking scenarios: given a set of objects, the model assumes that the top-ranked object is drawn probabilistically in proportion to strength from the remaining objects, generating a full ranking sequentially. Both models are widely used in RLHF pipelines — the reward model training paradigm used by OpenAI to train InstructGPT is essentially an instantiation of the Bradley–Terry framework. The core operation is converting annotator ratings or rankings into pairwise comparison labels (A is better than B), then fitting a reward model on these binary labels. This approach's simplicity has made it the industry default, but it also means the intensity information embedded in raw ratings — such as the qualitative difference between "5 vs. 1" and "3 vs. 2" — is completely discarded.
A Joint Covariate-Dependent Modeling Approach
To address these issues, the paper proposes a core method: a covariate-dependent consecutive ratio Markov random field model.
The design logic of this model can be broken down into several key points. It directly performs joint modeling of multiple ordinal attributes rather than handling them one by one, thereby capturing the dependency structure between attributes. The model incorporates covariates, allowing the distribution of preferences to vary with user characteristics or prompt-response context. The "consecutive ratio" approach to handling ordinality is a natural choice in statistics for ordinal responses, respecting the ordering relationships between rating levels. The Markov random field (MRF) framework provides a flexible tool for characterizing joint distributions over multiple variables.
The goal of this combination is clear: to model preference data completely without losing ordinal information, severing attribute correlations, or discarding covariate effects.
The consecutive ratio model is a parameterization method in ordinal regression, also known as a variant of the "adjacent category logit model." For an ordinal response variable (such as scores from 1 to 5), it models the transition probabilities between adjacent categories — that is, the probability of advancing one level higher given that a certain score has already been reached. This contrasts with two other common ordinal models: the cumulative logit model (such as the proportional odds model) models cumulative probabilities of "scoring no more than k"; the adjacent category logit model directly compares the probability ratios of neighboring categories. The consecutive ratio model is more interpretable in terms of a "step-by-step progression" psychological process — for example, a user deciding "whether to go from 3 to 4 stars" — making it a natural semantic fit for behavioral and psychometric data. Embedding this ordinal treatment into the MRF framework is the key design choice the paper makes for multivariate ordinal modeling.
Theoretical Connections to Comparison Models
One of the paper's particularly valuable theoretical contributions is revealing the intrinsic relationship between the new model and classic comparison models.
The authors prove that pairwise comparison models and listwise comparison models are actually special cases of their joint model under specific constraints. In other words, widely used models like Bradley–Terry and Plackett–Luce do not exist independently of the joint modeling framework — they can be derived from it as restricted versions.
The significance of this result is that it unifies seemingly disparate modeling approaches under a more general framework. More importantly, the paper further argues that joint modeling can improve the quality of comparisons themselves — by retaining richer information, the joint model theoretically outperforms methods that coarsen data upfront on preference comparison tasks. This provides theoretical justification for "whether it's worth adopting the more complex joint model."
Tackling the Intractable Normalization Problem
Markov random field models have a well-known practical obstacle: the intractable normalizing constant. The joint probability distribution of an MRF requires a partition function for normalization, and this partition function typically involves summing or integrating over all possible states — a computation that is nearly impossible to perform exactly in high dimensions.
To address this challenge, the paper specifically develops a maximum likelihood inference procedure that remains applicable even when the normalizing constant is intractable. This means the model is not only theoretically coherent but also operationally feasible for actual parameter estimation — which is often the dividing line between whether a complex statistical model can be genuinely applied.
A Markov random field (MRF) is a probabilistic graphical model that represents dependencies between variables using an undirected graph, where nodes correspond to random variables and edges represent direct correlations between variables. Its joint distribution is defined by a product of potential functions, divided by a partition function Z for normalization. The partition function requires summing over all possible combinations of values for all variables — an exponential computational problem when the number of variables or their value space is large. Common strategies for addressing this challenge include variational inference (approximating the true posterior with a simpler distribution), MCMC sampling, Contrastive Divergence, and pseudo-likelihood methods. Pseudo-likelihood, proposed by Besag in 1975, replaces the joint likelihood with the product of each variable's conditional probability given its neighbors, completely circumventing the partition function computation — making it the most commonly used practical alternative for MRF parameter estimation. The maximum likelihood inference method developed in this paper specifically for the ordinal data setting is a targeted design within this technical tradition.
Implications for AI Alignment and Recommendation Systems
From an applied perspective, this work touches on a hot area of current AI research. As RLHF (Reinforcement Learning from Human Feedback) and various alignment techniques become widespread, accurately extracting signals from human preference data has become increasingly critical.
If preference data is coarsened into simple win-loss comparisons before entering the model, downstream alignment quality may be invisibly constrained. This paper reminds us that the way preference data is modeled is itself an important variable in alignment quality. For recommendation systems, jointly considering multi-attribute ordinal ratings with user covariates similarly holds promise for more fine-grained personalization.
Of course, as a newly published, theoretically oriented paper, the method's performance on large-scale real-world datasets, computational cost, and scalability still require subsequent empirical validation. But the core principle it advocates — "don't coarsen your data prematurely" — has universal reference value for practitioners in the preference learning field.
Related articles

macOS Is No Longer UNIX: Apple Didn't Renew Certification, But the Technology Is Unchanged
Apple did not renew macOS's UNIX certification, and the Open Group has removed Apple's entry. This article analyzes the technical reality behind the expiration, Apple's possible intentions, and the practical impact on developers.

Building Stateful Multi-Agent Systems with Azure Cosmos DB
Based on the official Azure Cosmos DB tutorial, this article explains how to use the Agent Memory Toolkit to add shared persistent memory to a multi-agent travel planner, covering short-term, long-term, episodic, and semantic memory plus cross-session state continuity.

Production AI Agent Operations: A Three-Step Framework for Observing, Evaluating, and Optimizing
Azure Cosmos DB team proposes a three-step framework for production AI Agent operations: observe trace tracking, evaluate with LLM as a judge and regression testing, optimize cost across RU, retrieval, memory, and LLM layers.