Layer-by-Layer Breakdown of Q4 Quantized Models: Where Do BF16 and Q4_K_M Differences Come From

heterodyne compares quantized and full-precision models token-by-token and layer-by-layer inside llama.cpp to pinpoint drift sources.
heterodyne is a quantization drift attribution tool running inside llama.cpp. It compares two configurations (called "arms") token-by-token and layer-by-layer, recording exact full-vocabulary KL, top-1 changes, and per-layer residual streams, using activation grafting and attention/MLP contribution splitting to locate differences. Experiments show Q4_K_M vs. BF16 differences are spread evenly across layers, but for specific tokens the decisive difference forms between layers 6 and 12; when restoring BF16, attention and MLP contributions are indistinguishable, while injecting Q4_K_M shows larger MLP contribution. Also, q8_0 KV cache quantization can exceed the impact of weight quantization from BF16 to Q8_0, and the CPU path has batch-invariance issues at non-multiple-of-4 batch sizes.
When a quantized model's outputs diverge from the full-precision model, you usually only see a single aggregate number. Developer zaydmulani09 built heterodyne, which compares two configurations token-by-token and layer-by-layer inside llama.cpp to pinpoint where the differences originate. This article, based on the open-source project and its experimental data, lays out a method for attributing quantization drift.
Quantization Drift: What an Aggregated Number Hides
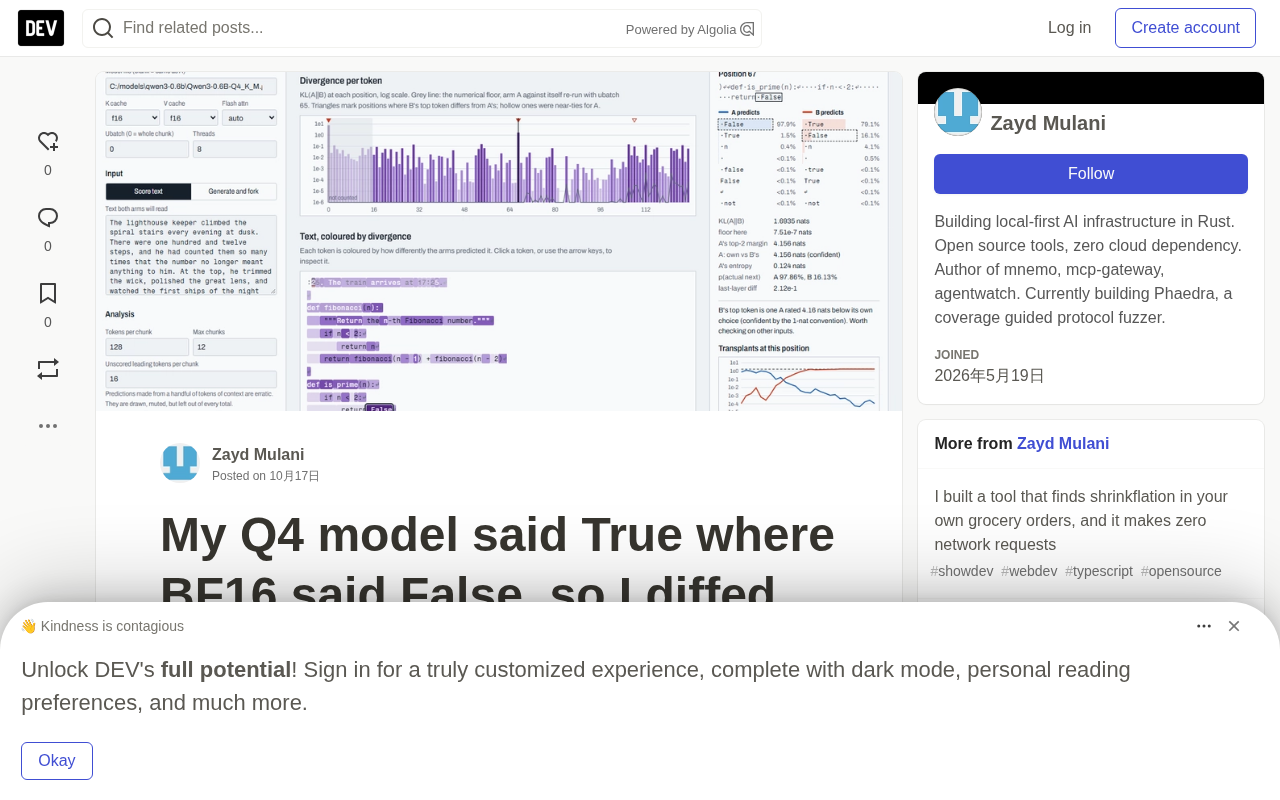
Running the same code through Qwen3-0.6B's BF16 version and its Q4_K_M quantized version, at the is_prime function definition, BF16 outputs False with 97.9% probability while Q4_K_M outputs True with 79.1% probability. This is just one token out of 1282 scored positions.
Overall, Q4_K_M changes the top-1 token at 11.6% of positions, with an average KL divergence of 0.067 from BF16, and perplexity rising from 7.83 to 8.53. These numbers show that quantization does introduce drift, but they can't answer the more critical questions: at which tokens the drift occurs, in which layers, which modules within a layer, and whether weights have a larger impact than the KV cache or batch size.
KL divergence (Kullback-Leibler divergence) measures the difference between two probability distributions: if P is the reference distribution and Q is the approximate distribution, KL(P‖Q) represents the average extra information required to encode P using Q, typically in nats. It is non-negative and asymmetric — the larger the value, the more dissimilar the two distributions. In quantization analysis, KL is often used to quantify the output distribution shift between the full-precision model and the quantized model at each token position, then summed or averaged over the full vocabulary to obtain the average KL. Note that average KL masks dramatic changes in the distribution tails: a few tokens may have extremely high KL but get averaged out by the many near-zero positions. So average KL alone can't tell you where the drift is concentrated — which is precisely why heterodyne records precise per-token, per-layer KL.
How heterodyne Works
Why Not Just Use TransformerLens
Mainstream interpretability tools like TransformerLens and nnsight all run on PyTorch. But on CPU, llama.cpp quantizes activations to 8 bits before every quantized matrix multiplication. A PyTorch model using dequantized weights is not the same model as the GGUF file you actually run. llama.cpp's built-in llama-perplexity --kl-divergence only reports aggregate values too.
heterodyne chooses to work inside llama.cpp, using the same compute kernels as the actual deployment.
GGUF is the model file format used by llama.cpp. It packages model weights, tokenizer configuration, and metadata together, and supports multiple quantization types (such as Q4_K_M, Q8_0). Quantized weights typically need to be dequantized back to floating point before participating in computation during inference, but llama.cpp uses a hybrid strategy on CPU: weights remain stored in quantized form, while activations are dynamically quantized to 8-bit integers before each matrix multiplication, and integer instructions perform the multiply-accumulate. This means the actual numerical path executed is not equivalent to "dequantize weights and run PyTorch" — the latter lacks the activation quantization step and its corresponding rounding errors. So analyzing a GGUF file with PyTorch tools may yield drift sources that differ from what you see in deployment. heterodyne embeds directly into llama.cpp precisely to avoid this discrepancy.
Dual "Arm" Comparison and the Numerical Floor
heterodyne treats each configuration as an "arm" — a GGUF file plus runtime settings that may alter its numerics (K/V cache type, flash attention, ubatch size). It runs both arms chunk by chunk on the same tokens and records:
- Exact full-vocabulary KL(A‖B) at each position, accumulated from raw logits in f64, along with each top-1 change and its confidence;
- A numerical floor: re-running arm A with an odd batch split, as a baseline for harmless variation on that machine;
- The residual stream after each layer for both arms;
- Activation grafting results (see below);
- Optionally, sweeping all combinations of different settings to attribute changes to a specific factor.
All results are saved as experiment files with provenance information (GGUF hash, llama.cpp commit, build flags) and integrity hashes. heterodyne verify can rerun and precisely compare every stored numerical value.
Numerical floor is a control baseline in experimental design: on the same machine and the same model, change the computation order in a way that doesn't alter the mathematical meaning (e.g., splitting the batch into odd sizes) and observe how much the output differs as a result. This difference comes from floating-point accumulation order, thread scheduling, and other non-essential factors — "harmless noise." Any KL measured in an attribution experiment must be significantly above this floor to be considered a genuine effect of quantization or configuration. heterodyne estimates the floor by re-running arm A with odd batch splits, which also explains why its batch-invariance test focuses on whether the ubatch size is a multiple of 4 — non-multiples of 4 trigger a different quantized activation path, which itself constitutes a numerical perturbation.
Activation Grafting: Locating Critical Layers
heterodyne uses llama.cpp's scheduler cb_eval callback to copy or overwrite tensors when computation reaches a specified graph node. Since all downstream nodes come after it in topological order, overwriting affects subsequent computation. Tensors are addressed by graph name: l_out-N is the residual stream after layer N, and ffn_inp-N is the residual between layer N's attention and MLP.
Denoising experiment: run arm B but write arm A's l_out-N, and measure KL(A‖patched B). The noising experiment is the reverse. Doing this for each layer yields a curve. Results for Q4_K_M vs. BF16 show KL smoothly decreasing from 0.062 at layer 0 to 0.0013 at layer 27, with no single layer carrying all the difference. At the is_prime token, writing BF16's residual into Q4_K_M reduces that token's KL from 0.48 after layer 6 to 0.04 after layer 9; the reverse writing reproduces the flip from about layer 12. The decisive difference for this token forms between layers 6 and 12.
Residual stream is the main trunk vector passed between layers in a Transformer: each layer's attention output and MLP output are added back to this stream, so it accumulates all information from the embedding layer up to the current layer. In llama.cpp's computation graph, l_out-N denotes the residual stream after layer N completes, and ffn_inp-N denotes the residual after layer N's attention but before its MLP. Since the computation graph executes in topological order, overwriting a node's tensor changes the inputs to all downstream nodes, making it possible to "write A's layer residual into B." Activation grafting exploits exactly this: replacing the residual stream layer by layer and observing how KL changes, to determine at which layer the difference is introduced and at which layer it is amplified or canceled.
Splitting Attention and MLP Contributions
Directly writing the MLP output would erase the MLP's response to upstream differences, causing modules with identical weights to appear "responsible." heterodyne instead restores arm A's full residual at two recovery points per layer (after attention ffn_inp-N and after MLP l_out-N), and takes the difference between adjacent points. Attention's share at layer N equals the KL when restoring A at that layer's input minus the KL when restoring A after attention; the MLP share is the next step. These steps telescope-sum without double counting.
This method has a known-answer validation: if the two arms differ only in K cache type, then only attention reads the K cache, and every MLP step must be exactly zero. The test checks bitwise, and it holds on Qwen3 as well.
Across 12 chunks and 1282 scored positions, the 95% interval shows: when restoring BF16 in Q4_K_M, attention removes 0.030 (0.019–0.041) and MLP removes 0.036 (0.024–0.048), with a paired difference of 0.006 (−0.011 to 0.022) crossing zero — the two are indistinguishable. When injecting Q4_K_M into BF16, MLP adds more (0.014, 0.005 to 0.023). The largest single step is layer 0 attention, but llama.cpp doesn't name layer 0's input, so that bar also includes token embedding differences. A few steps are negative (layer 2 attention −0.0014), meaning restoring that module alone actually moves Q4_K_M further from BF16.
This analysis requires two extra compute passes per layer per chunk; 12 chunks took 29 minutes on an i7-1355U laptop.
Other Findings
Testing different quantization levels on the same text and same laptop:
| Configuration | Average KL | top-1 change | Perplexity (BF16: 7.83) |
|---|---|---|---|
| Q8_0 | 0.0022 | 2.2% | 7.83 |
| UD-Q4_K_XL | 0.058 | 11.3% | 8.33 |
| Q4_K_M | 0.067 | 11.6% | 8.53 |
| Q3_K_M | 0.214 | 20.8% | 9.47 |
| Q2_K | 0.780 | 36.3% | 16.75 |
Two notable conclusions:
The impact of the KV cache is underestimated. Running the same Q8_0 file twice, with q8_0 K/V cache the second time, gives a KL of 0.0038 — larger than the impact of quantizing weights from BF16 to Q8_0 (0.0022).
llama.cpp's CPU path is not batch-invariant across all batch sizes. With flash attention disabled, Q4_K_M produces bit-identical output at ubatch sizes that are multiples of 4, but differs at other sizes (4.7% of top tokens change at ubatch 63). The reason is that the rearranged K-quant matrix multiplication quantizes activations in groups of 4 rows, with remainders taking a different path. This is also why heterodyne's numerical floor uses odd splits.
Limitations and Trying It Out
The author explicitly notes: only one small model, one text, one machine; grafting is an intervention on your input, indicating where restoring a model's activations eliminates differences on that text, not in a general sense which module's weight quantization is worse; CPU only — GPU kernels compute differently, and current results don't apply to GPUs.
Linux, Windows, and macOS arm64 binaries are available from GitHub releases. Run heterodyne serve --models ~/models or use the command line to compare two GGUF files. The experiment files corresponding to all numbers are in the examples/ directory.
For developers who need to troubleshoot behavioral differences in quantized models, this layer-by-layer attribution method within the deployment kernel offers a reproducible path — rather than just looking at a single KL number.
One-line Summary
heterodyne compares quantized and full-precision models token-by-token and layer-by-layer inside llama.cpp to pinpoint drift sources.
Paragraph Summary
heterodyne is a quantization drift attribution tool that runs inside llama.cpp. It compares two configurations (called "arms") token-by-token and layer-by-layer, recording exact full-vocabulary KL, top-1 changes, per-layer residual streams, and uses activation grafting plus attention/MLP contribution splitting to locate the source of differences. Experiments show that Q4_K_M vs. BF16 differences are spread evenly across all layers, but for specific tokens the decisive difference forms between layers 6 and 12; when restoring BF16, attention and MLP contributions are indistinguishable, while when injecting Q4_K_M, MLP contributes more. Additionally, q8_0 KV cache quantization can have a larger impact than quantizing weights from BF16 to Q8_0, and the CPU path has batch-invariance issues at non-multiple-of-4 batch sizes.
Related articles

FastAPI: A High-Performance Python Framework and a Production-Ready API Development Powerhouse
FastAPI is a high-performance web framework based on Python type hints, supporting async and automatic OpenAPI docs. With over 100k GitHub stars, this article analyzes its core strengths, production readiness, and selection advice.

Tesla Optimus Begins Mass Production: Can the Goal of 20,000 Units Per Week Be Achieved?
Tesla Optimus officially begins mass production as Musk sets a target of 20,000 units per week. This article analyzes the supply chain challenges behind mass production, the real gap in capacity ramp-up, and the competitive landscape for humanoid robots.

PCL: A Minecraft Launcher with 8.5k Stars — Why Was It Written in VB.NET?
An in-depth analysis of PCL, the GitHub Minecraft launcher with 8,500+ stars: why it chose VB.NET, its features and China network advantages, and the limits of Windows-only.