LLM-as-a-Judge Calibration Guide: Practical Approaches to Validating Judge Model Reliability

A practical guide to validating and calibrating LLM judge models against human review standards.
This article examines the critical but often overlooked challenge of calibrating LLM-as-a-Judge evaluation systems. It covers establishing human review as ground truth, continuously monitoring agreement rates, implementing trigger-based recalibration for model upgrades and input distribution drift, and using anchor examples to correct systematic biases — moving teams from 'ship and pray' to rigorous, trustworthy AI evaluation.
A Problem That's Been Overlooked
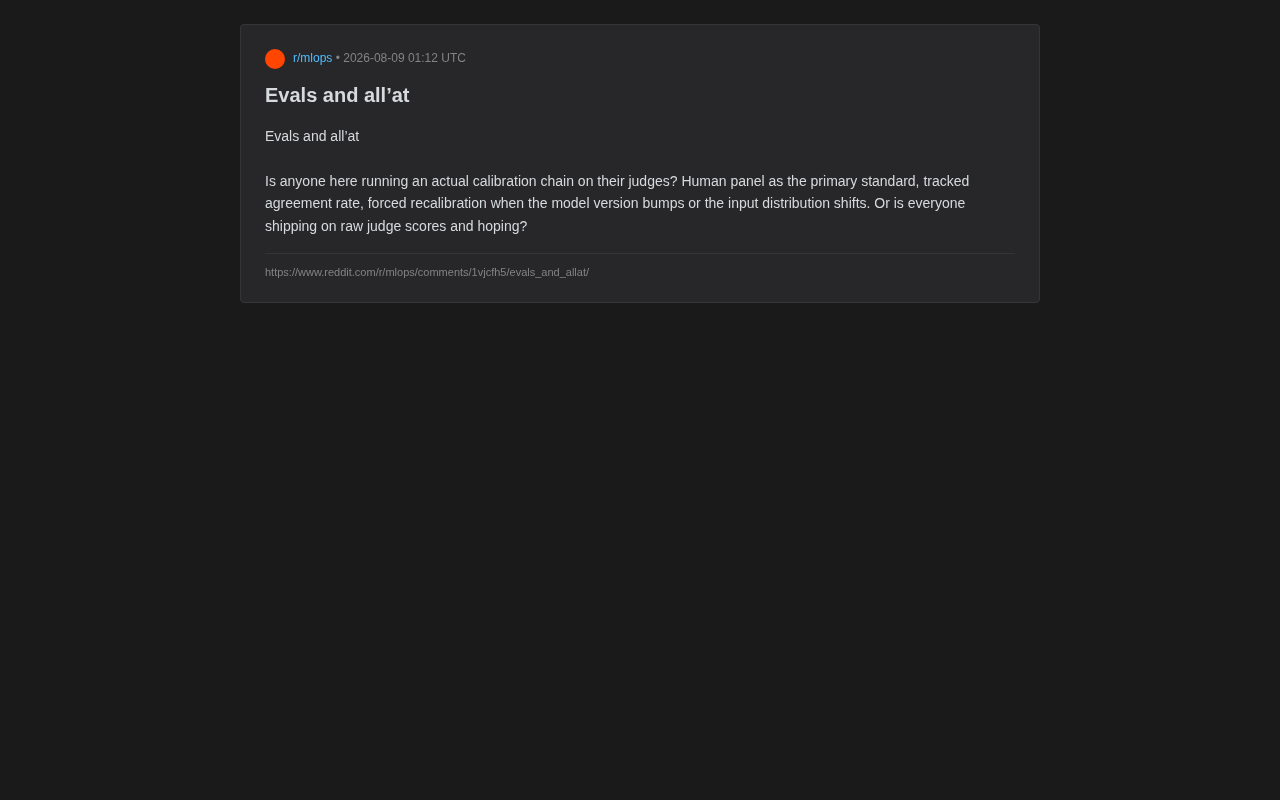
In a technical discussion on Reddit, a practitioner posed a question that hits right at a critical pain point:
"Is anyone actually running a full calibration chain for their judge models? Using a human review panel as the primary standard, tracking agreement rates, forcing recalibration when model versions upgrade or input distributions drift. Or is everyone just shipping on raw judge scores and hoping for the best?"
This seemingly simple question reveals a pervasive yet rarely addressed risk in current LLM evaluation systems: the "judge" we use to assess AI output quality may itself have never been validated for reliability.
As "LLM-as-a-Judge" — using large language models as evaluation judges — has become the industry's mainstream automated evaluation approach, more and more teams are relying on models like GPT-4 and Claude to score system outputs. However, the foundation of this practice — whether the judge model's assessments align with human experts — often lacks systematic verification.
Why LLM-as-a-Judge Became the Dominant Evaluation Approach
Human evaluation is accurate but expensive, slow, and difficult to scale. When you need to assess the quality of thousands or even tens of thousands of model outputs, hiring human reviewers is nearly impractical. So using a powerful LLM as a judge to automatically score outputs became an extremely attractive alternative.
The LLM-as-a-Judge paradigm was first systematically proposed in 2023 by a UC Berkeley research team through the MT-Bench and Chatbot Arena projects. The core idea is to leverage highly capable models like GPT-4, using carefully designed evaluation prompts, to score other models' outputs across multiple dimensions. Common evaluation modes include: pointwise scoring (directly scoring a single output), pairwise comparison (comparing which of two outputs is better), and reference-guided grading. This method gained rapid adoption because multiple studies demonstrated over 80% agreement with human reviewers, at a fraction of the cost of human evaluation.
The advantages of this approach are obvious:
- Speed: Complete large-batch evaluations in seconds
- Low cost: Orders of magnitude cheaper than human review
- Reproducibility: The same input (theoretically) produces consistent scores
But the problem lies precisely in that word "theoretically." Judge models are also probabilistic models — they have their own biases, blind spots, and instabilities. Large language models are fundamentally autoregressive probabilistic models. Even with temperature set to 0, due to floating-point arithmetic precision, batching strategies, and hardware differences, the same input called at different times may produce subtly different outputs. This phenomenon is called "non-determinism." In evaluation scenarios, this means the same piece of content being scored repeatedly by a judge model may receive different scores. Research shows that GPT-4's scores can fluctuate by ±1 point (on a 10-point scale) when repeatedly evaluating the same output — this inherent instability is the first layer of risk to judge model reliability.
Beyond instability, academic research has identified multiple systematic biases in LLM judges: position bias (tendency to favor the first or second answer in pairwise comparisons), verbosity bias (tendency to give higher scores to longer responses), self-enhancement bias (tendency to prefer outputs generated by models in the same family), and style bias (preference for specific writing styles like using lists or markdown formatting). These biases won't surface in simple accuracy tests — they can only be detected through carefully designed controlled experiments.
Without a rigorous calibration mechanism, directly trusting judge scores is equivalent to handing product quality decisions to a reviewer who has never undergone a qualification exam.
Core Components of a Judge Model Calibration Chain
The "calibration chain" concept proposed by the original poster essentially brings the judge model itself into the quality control system. It contains several key components:
Human Review as the Gold Standard
The first principle of calibration is establishing "ground truth." The human review panel's judgments serve as the primary standard, and the judge model's outputs need to align with them. The key here isn't replacing humans with AI, but having AI learn to mimic human expert judgment criteria while continuously being validated against human decisions.
Continuously Tracking Agreement Rates
The "agreement rate" is the core metric for measuring judge reliability. It answers a simple question: on the same set of samples, what proportion of the judge model's and human reviewers' scores are consistent? If agreement falls below a certain threshold (say 80%), then judge scores shouldn't be trusted. This metric needs to be continuously monitored, not measured once and shelved.
It's worth noting that calculating agreement rates isn't simply a matter of "exact match" percentages. Commonly used measurement methods in the industry include: exact agreement (judge and human give the exact same score), adjacent agreement (allowing ±1 point deviation), and Cohen's Kappa coefficient (measuring true agreement after excluding chance agreement). For continuous scores, Pearson correlation coefficient or Spearman rank correlation are also commonly used to measure overall trend consistency. A mature calibration system typically needs to monitor multiple metrics simultaneously, as a single metric may mask specific types of misalignment.
Trigger-Based Forced Recalibration
The original poster specifically emphasized two trigger conditions requiring forced recalibration:
- Model version upgrades: When you switch your judge from GPT-4 to GPT-4o, or when the provider quietly updates the underlying model, the judge's behavior may change in subtle but significant ways. Previous calibration results immediately become invalid.
- Input distribution drift: If the types of user requests your product handles change (e.g., expanding from technical Q&A to emotional companionship), a judge previously validated on the old distribution may perform poorly on the new distribution.
Input distribution drift is a classic problem in machine learning operations (MLOps), referring to the gradual deviation between the data distribution a model receives in production and the data distribution during training or calibration. In LLM evaluation scenarios, common methods for detecting drift include: generating embedding vectors for input text and calculating statistical distances (such as KL divergence, Wasserstein distance), monitoring changes in input topic distribution (through topic models or clustering analysis), tracking statistical feature changes in input length and complexity, and monitoring whether the distribution of judge scores itself shows abnormal shifts. When these indicators exceed preset thresholds, the recalibration process is triggered.
These two points directly address the reality of production environments: systems evolve dynamically, and one-time evaluation validation cannot cover continuously changing operational states.
"Ship and Pray": The Evaluation Reality for Most Teams
The original poster's phrasing — "shipping on raw judge scores and hoping" — carries obvious sarcasm, but it also speaks to the industry's true state of affairs.
Most teams' evaluation processes suffer from the following problems:
- One-time validation: A single round of judge-vs-human comparison was done at the project's start, never to be verified again
- Lack of drift monitoring: Not tracking changes in input distribution, with no awareness of whether the judge is failing on new data
- Version upgrade blindness: Continuing to use old evaluation configurations after underlying model updates
- Over-trusting scores: Treating the judge's 8.5 score as objective truth rather than an estimate that should be questioned
The danger of this approach is that it creates an illusion of "we're doing rigorous evaluation." The numbers dancing on a polished evaluation dashboard may be built on a judge that has long since lost calibration. You think you're optimizing product quality, but you may actually be optimizing "how to please a biased judge."
How to Build a Trustworthy AI Evaluation System
From this discussion, we can distill a more responsible set of evaluation practices:
Regularly Execute Human-Judge Comparison Validation
Don't treat human review as a one-time cost. Establish a periodic sampling mechanism — pull a subset of samples that have been scored by the judge and submit them for human review, continuously calculating agreement rates. Treat this rate as the core KPI for evaluation system health.
Establish Clear Calibration Trigger Rules
Explicitly write "model version changes" and "input distribution drift" into your operations workflow. The former can be achieved through version monitoring; the latter can be detected through statistical analysis of input data (such as distribution changes in embedding vectors). When either is triggered, automatically initiate the recalibration process.
Do Calibration, Not Just Validation
"Calibration" goes a step further than mere "validation." It's not just checking whether the judge is accurate — it also includes adjusting the judge's scoring criteria, optimizing prompts, and even incorporating anchor examples to correct systematic biases, truly aligning judge scores with human standards.
Anchor examples are an important technical approach for calibrating judge models. The principle is to include in the evaluation prompt several examples that have been annotated with clear scores by human experts, covering various tiers of the scoring scale (e.g., one example each at 2 points, 5 points, and 8 points). After seeing these "reference points," the judge model can more accurately understand the concrete meaning of scoring criteria, reducing bias from subjective interpretation. A more advanced approach is to dynamically select the most relevant anchor examples based on the type of content being evaluated (through semantic similarity retrieval) — this method can improve judge-human agreement by 5-15 percentage points in practice.
Conclusion: Evaluation Itself Needs to Be Evaluated
This brief question from Reddit touches on a serious issue in AI engineering practice that's easily obscured by the romanticized halo of technology: When we automate evaluation, who evaluates the evaluator?
As LLM-as-a-Judge becomes more deeply embedded in product iteration cycles, the reliability of judge models directly determines whether the entire optimization direction is correct. A miscalibrated judge not only fails to help improve the product — it may guide the team to optimize in the wrong direction, with more effort leading further away from users' real needs.
The answer is actually quite simple: treat the judge model like any other critical component and incorporate it into continuous quality control. Human review is the anchor, agreement rate is the gauge, and trigger-based recalibration is the safety belt preventing drift. Less praying, more calibrating.
Related articles

AI-Powered SRC Vulnerability Hunting: A Hands-On Guide to Building the Hermes Agent Workbench
Based on a hands-on Bilibili video: how to build an AI-powered SRC vulnerability hunting workbench—three-step method, four report elements, Agent mode vs web chat, and tool selection.

CLI-Anything Complete Beginner's Guide: How AI Operates Software — Principles and Practice
A complete beginner's guide to CLI-Anything: how AI Agents operate professional software via the command line, covering the three-layer architecture, CLI Hub installation, DrawIO practice, generator principles, and limits.

Carbon-X: A 14.8B Open-Source Model That Handles DNA and Text Simultaneously
Carbon-X is a 14.8B open-source multimodal model on Hugging Face where DNA and text share a token stream. 6-mer tokenization, 302B token mid-training, deployable on a single 80GB GPU, 66.7% average on five DNA benchmarks, Apache 2.0 license.