LLM Judge Bias in Practice: Judge Confidence Intervals Alone Miss Human Ground Truth in 18 of 21 Cases

FewHumans uses PPI++ to fuse human and judge labels, measuring only 9% human annotation savings, and judge confidence intervals are often miscalibrated.
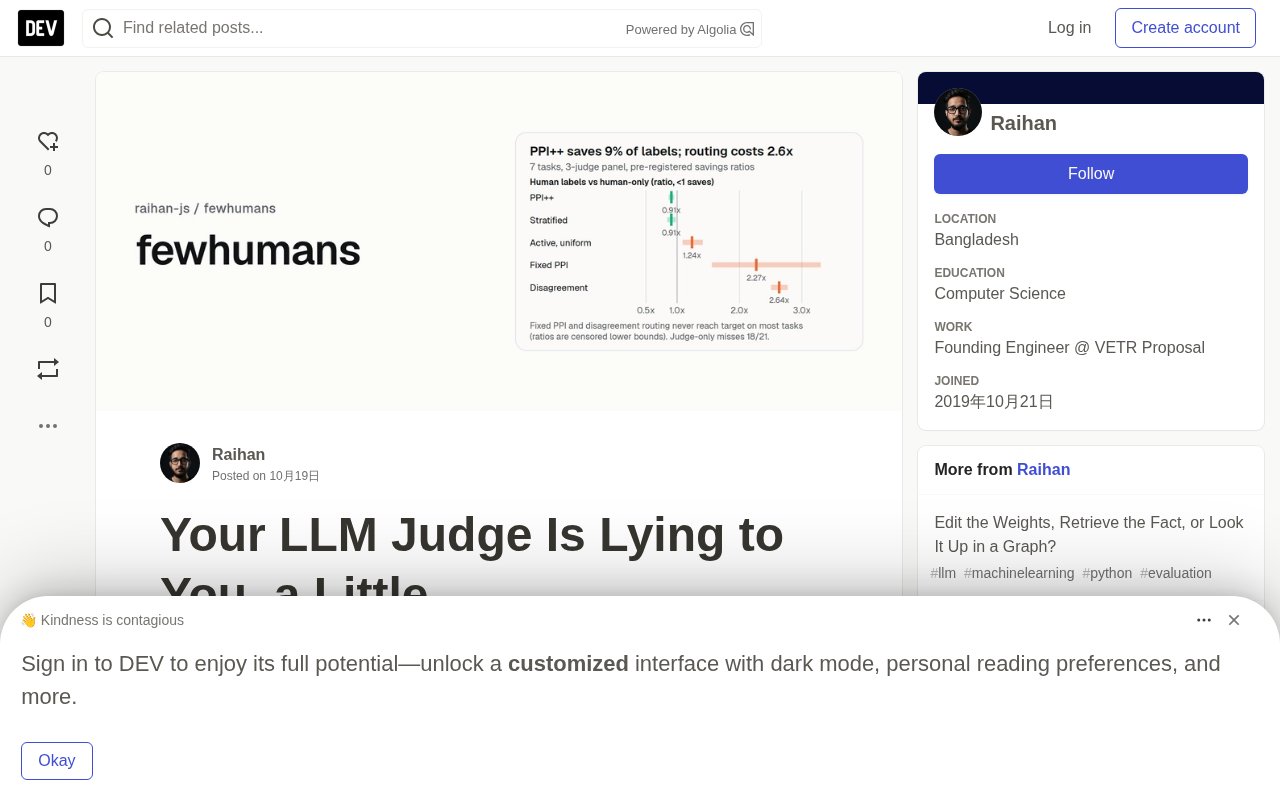
This article introduces the open-source library FewHumans, which uses PPI++ to decide which samples need human annotation, fuse judge and human labels, and provide stopping signals. The preregistered experiment covers 7 English tasks, 3 mid-tier judges, 846 configurations × 2000 repetitions, first validating with a 196-configuration interval coverage gate. Core findings: PPI++ measured savings of only ~9% human labels; untuned fixed PPI consumes 2.27x human annotation; disagreement routing fails on 6/7 tasks with 2.64x costs; judge-only confidence intervals miss human ground truth in 18 of 21 combinations, with verbalized confidence generally overconfident. The authors note the method reduces but does not eliminate human review, and does not yet support ratio metrics like F1.
Your LLM judge says the system scores 72%, but the fully human-annotated ground truth is actually 65%. And the ±1% confidence interval you calculated describes the judge's preferences, not the truth. This isn't theoretical speculation—in a preregistered study, relying solely on the judge's confidence intervals failed to cover the fully human-annotated ground truth in 18 out of 21 task-and-judge combinations.
FewHumans is an open-source library built for this purpose: it decides which samples should be labeled by humans, fuses human labels and judge labels using prediction-powered inference (PPI), and tells you "you can stop" at the appropriate time. But its measured gains are far less dramatic than the hype—saving about 9% of human labels, not 10x.
How the Experiment Was Conducted
The study covers 7 English annotation tasks: HelpSteer2 and SummEval scoring, MT-Bench and Arena preferences, WMT translation quality, toxicity labeling, and OracleBench math judgments. Three mid-tier judges participated: two local models (Qwen 9B/4B, run via Ollama) and one gpt-4o-mini, with total API cost of $0.29. All prompts were frozen before any simulation began, and policies could only see human labels when they "paid to buy" them.
The formal preregistered experiment ran 846 configurations, each repeated 2000 times. Before any policy conclusions were drawn, every default interval first passed a 196-configuration coverage gate (Student-t intervals; stratified methods required n≥100, skewed ground truths required n≥200). This approach of first validating interval validity and then comparing policy performance is not common among similar evaluation tools.
Preregistration refers to the practice of researchers publicly registering and freezing their research hypotheses, experimental design, analysis methods, and primary evaluation metrics before collecting or analyzing data. Its core purpose is to prevent cherry-picking conclusions based on data results after the fact, thereby reducing p-hacking and publication bias. This article froze all prompts before the simulation began, restricted policies to obtaining human labels only through payment, and tested interval coverage across 196 configurations before comparing any policy performance—precisely embodying the spirit of preregistration: lock down the analysis plan first, then run the formal experiment.
Core Findings: Limited Savings, Plenty of Pitfalls
PPI++ does work, but modestly. Measured savings are about 9% of human labels, with interval estimate 0.91 [0.87, 0.95]. Stratified PPI++ results are nearly identical (0.91 [0.84, 0.98]), with simpler assumptions, making it suitable as the default option.
Un tuned PPI incurs net costs. PPI with fixed λ=1 amplifies human label consumption to 2.27x—in medium-quality scenarios where judge agreement is only 45%–77%, an untuned λ is equivalent to injecting noise into the estimate. The conclusion is direct: don't run PPI without power tuning.
Disagreement routing is an intuition that data rejected. Selecting human annotation samples by judge disagreement sounds reasonable, but results show it actually increases costs in 6 of 7 tasks, reaching 2.64x overall. Although disagreement does predict errors (AUROC up to 0.80), the variance inflation from inverse probability weighting outpaces the gains from the signal. The authors themselves cite prior work by Sfyraki & Wang and candidly acknowledge that this failure was expected.
Judge-only intervals are systematically miscalibrated. In 18 of 21 task-and-judge combinations, they failed to cover human ground truth; verbalized confidence was overconfident on all tasks, with calibration error up to 0.98. This means that making decisions directly using the judge's self-reported confidence intervals systematically underestimates risk.
PPI (Prediction-Powered Inference) is a statistical inference framework that fuses a small amount of human annotations with a large amount of cheap model predictions. It doesn't directly treat model predictions as ground truth; instead, it combines "model predictions + a small number of human labels" into an unbiased or low-bias estimate of the target quantity, along with valid confidence intervals. PPI++ is an improved version that adjusts the weight of model predictions in the estimate through power tuning to minimize variance. If the weight λ=1 is fixed without tuning, it's equivalent to giving model predictions and human labels equal weight, which amplifies noise—manifesting in this article as human label consumption increasing to 2.27x.
Inverse Probability Weighting (IPW) is commonly used to handle non-random sampling: when samples have different probabilities of being selected into the annotation set, each sample is assigned the inverse of its selection probability as a weight to restore the population distribution. In disagreement routing, deciding whether to send samples for human annotation based on judge disagreement causes selection probability to correlate with disagreement level; while IPW can correct for selection bias, the weight variance explodes at extreme probabilities. In this article, although the disagreement signal predicts errors (AUROC up to 0.80), the variance inflation from IPW exceeds the signal gains, causing costs to rise to 2.64x.
Positioning from Multiple Perspectives
The value of this work lies not in proposing a stronger judge, but in providing a statistically guaranteed process for hybrid evaluation of "judge + small amount of human." Its conclusions align with multiple independent observations about LLM-as-judge reliability: judges are suitable for scaled signals but not for bearing the ground-truth role alone. FewHumans' contribution is turning "how much to trust, how much human annotation to supplement" into a computable problem rather than a matter of gut feeling.
Interval Coverage is a core metric for evaluating the reliability of confidence intervals: under repeated sampling, the proportion of intervals containing the true parameter value should approach the nominal confidence level (e.g., 95%). If actual coverage is significantly below the nominal value, it indicates the intervals are systematically too narrow, and decisions based on such intervals will underestimate risk. This article first uses a 196-configuration coverage gate to screen valid intervals before comparing policies, precisely to avoid the common trap of "comparing policy performance using miscalibrated intervals." The 18/21 failure to cover when relying solely on judge confidence intervals directly demonstrates that its interval coverage is severely insufficient.
Limitations and Applicable Boundaries
The authors themselves list several hard constraints: the 9% savings is not an order-of-magnitude improvement, and garbage-in-garbage-out still holds; the 7 tasks skew English, there are only three mid-tier judge models, and each configuration was run only once; ratio-type estimators like F1 are not yet supported; active routing requires workflows to record probabilities, and some production systems don't have this logging. In high-risk scenarios, this method reduces the amount of human review, not eliminates it.
How to Get Started
pip install fewhumans
pytest  # 47 tests
python examples/toy_end_to_end.py
The repository is at github.com/raihan-js/fewhumans, and the companion dataset JudgeBank contains judge outputs, cost, and latency data for 8 tasks; a paper draft will be published on arXiv. For teams building LLM evaluation pipelines, it's better suited as a reference implementation for "how to correctly merge judge results with human labels" rather than a money-saving tool to apply blindly.
One-line Summary
FewHumans uses PPI++ to fuse human and judge labels, measured savings of only 9% human annotation, and judge confidence intervals are often miscalibrated.
Paragraph Summary
This article introduces the open-source library FewHumans, which uses prediction-powered inference (PPI++) to decide which samples need human annotation, fuse judge and human labels, and provide stopping signals. The preregistered experiment covers 7 English tasks, 3 mid-tier judges, 846 configurations × 2000 repetitions, first validating with a 196-configuration interval coverage gate. Core findings: PPI++ measured savings of only about 9% human labels, not orders of magnitude; untuned fixed PPI consumes 2.27x more human annotation; disagreement routing fails on 6/7 tasks with costs reaching 2.64x; judge-only confidence intervals fail to cover human ground truth in 18 of 21 task-and-judge combinations, and verbalized confidence is generally overconfident. The authors note the method is suitable for reducing, not eliminating, human review, and does not yet support ratio-type metrics like F1.
Related articles

Beyond the Mainstream World: Security and Privacy Struggles in Overlooked Regions
Human-centered security research has long focused on the West, causing security solutions to fail in the mainstream world. Researcher Collins Minando draws on Kenyan mobile loan apps, internet café authentication dilemmas, and local expert studies across nine countries to reveal how socioeconomic constraints reshape privacy practices, and proposes mobile money privacy redesign and PETs deployment pathways.

Claude Reportedly Able to Hide Secret Messages in Benign Images
A Reddit post claims Claude Fable 5.1 can hide secret messages in benign images. This article reviews the background, image steganography principles, and potential security risks, and suggests a testing path from rumor to verification.

Federal Government Awards $85 Million; CFS to Develop Fusion-Specific Semiconductors
The federal government awards $85 million to Commonwealth Fusion Systems to develop conductors and power semiconductors for fusion plants. This article analyzes the significance of this funding for the fusion supply chain and commercialization path.