Loop Unrolling for Gauss-Seidel Iteration: Breaking the Loop-Carried Dependency Bottleneck
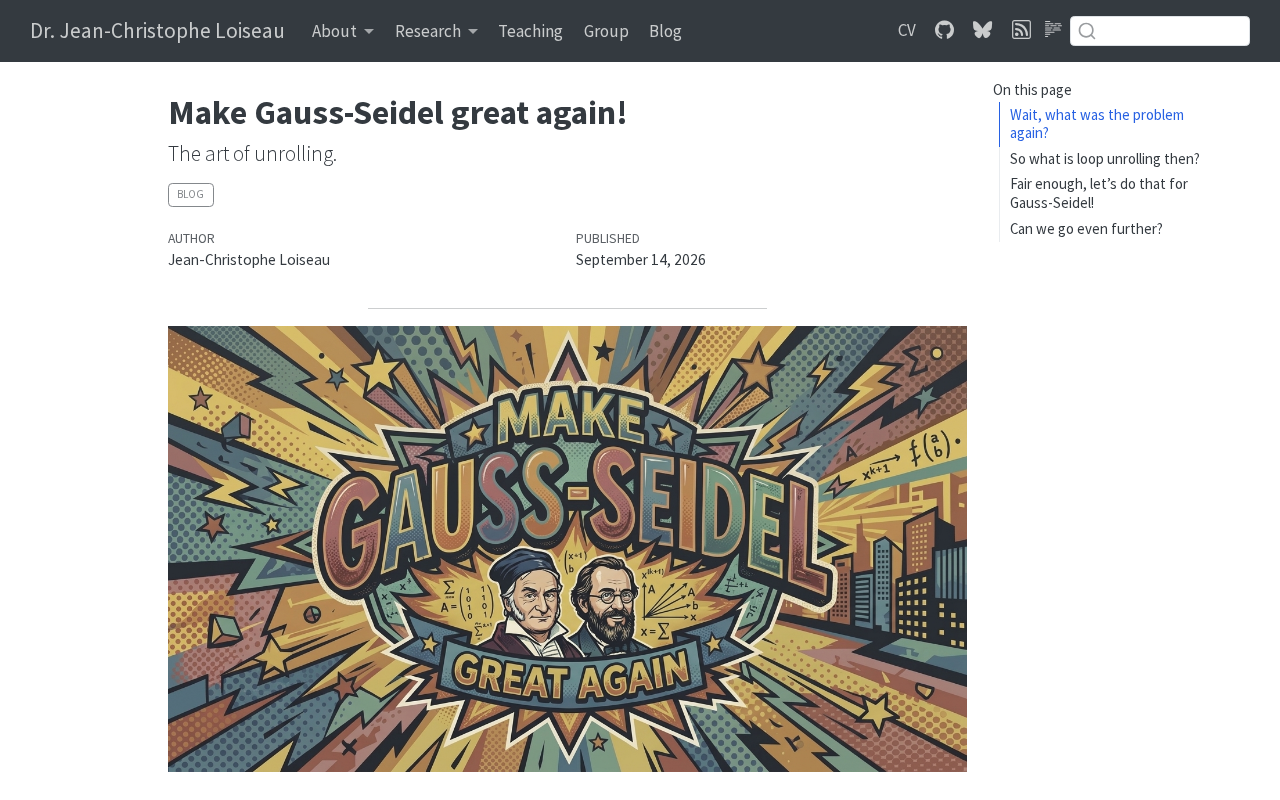
How loop unrolling breaks Gauss-Seidel's serial dependency chains to recover CPU throughput utilization.
Gauss-Seidel iteration's update-and-use-immediately nature creates inherent loop-carried dependencies, forcing each step to wait for the previous result and forming a serial chain. On modern deep-pipeline CPUs, this makes performance latency-bound rather than throughput-bound, leaving execution units idle. Loop unrolling maintains multiple independent computation streams, splitting long chains into shorter parallel ones to hide latency and restore throughput. However, excessive unrolling causes code bloat and register spilling; the optimal factor must be tuned per microarchitecture. At the algorithmic level, red-black ordering decouples element dependencies more fundamentally than microarchitectural tricks alone. The key is a measure-analyze-optimize loop grounded in precise dependency chain profiling.
Introduction: The Hidden Performance Killer in Numerical Computing
The Gauss-Seidel iterative method is a classic numerical technique for solving systems of linear equations, widely used in computational fluid dynamics, finite element analysis, and image processing. Yet its performance on modern processors is often disappointing — and the root cause is loop-carried dependency, a bottleneck that repeatedly surfaces in high-performance computing yet is easy to overlook.
This article analyzes a technical discussion around measuring loop-carried dependencies in Gauss-Seidel and optimizing them via loop unrolling. Given the limited details of the original source material, the content below draws on the broader technical context of this topic.
What Is Loop-Carried Dependency
A loop-carried dependency occurs when the result of one loop iteration depends on a value produced by a previous iteration. In Gauss-Seidel, this dependency is intrinsic to the algorithm: unlike Jacobi iteration, Gauss-Seidel immediately uses already-updated component values from the current sweep when computing the next component.
Mathematically, the update formula for the i-th unknown in iteration k uses components 1 through i-1 that have already been updated in the same sweep. This means every computation must wait for the previous one to finish, forming a serial dependency chain.
This "update-and-use-immediately" property is precisely what makes Gauss-Seidel converge faster than Jacobi — but it also makes parallelization and instruction-level parallelism difficult. Modern CPUs have deep pipelines and multiple execution units, but when instructions carry strong dependencies, the processor cannot fully utilize these resources, causing frequent pipeline stalls.
Why Dependencies Slow Things Down
Understanding the cost of loop-carried dependencies requires focusing on two hardware-level concepts: instruction latency and throughput.
Take floating-point multiply-add (FMA) as an example. A single FMA instruction may take 4 to 5 clock cycles to produce a result (latency), yet the processor can issue multiple FMA instructions per cycle (throughput). When a dependency chain exists within the loop body, each subsequent computation must wait for the previous result to be ready — the processor is forced to advance at the pace of latency rather than throughput, and it cannot leverage its throughput advantage.
In other words, when the critical path of a loop consists of a chain of mutually dependent floating-point operations, actual performance is bounded by instruction latency rather than throughput. In this scenario, multiple execution ports sit idle most of the time, and compute resources are severely wasted.
Common ways to measure this bottleneck include using performance counters to observe instructions per cycle (IPC), analyzing critical path length, and comparing theoretical peak performance against actual throughput. When IPC is far below the processor's theoretical limit, a dependency chain is almost always to blame.
Critical Path is the core tool for analyzing dependency costs. In a data-flow graph of a piece of code, the critical path is the longest dependency chain from input to output — it determines the lower bound on execution time. For a Gauss-Seidel loop body, if each iteration contains a chain of 4 mutually dependent FMA instructions each with 5-cycle latency, the critical path is 20 cycles. Regardless of how many execution units the processor has, each iteration requires at least 20 cycles — this is the essence of the latency-bound scenario.
The contrasting case is throughput-bound: when all operations within the loop are independent, the performance ceiling is determined by execution port bandwidth. Modern processors can issue 2 or more FMA instructions per cycle, and the theoretical limit is far higher than in the latency-bound case. Amdahl's Law manifests itself at the hardware level here: a serial dependency chain is the part that cannot be accelerated by additional execution resources, so identifying and shortening the critical path is the top priority in low-level optimization.
How Loop Unrolling Alleviates the Bottleneck
Loop unrolling is a classic technique in both compiler optimization and manual tuning. The core idea is to process multiple data elements within a single loop body, exposing more independent operations that can be executed in parallel.
For loops with loop-carried dependencies, unrolling alone cannot eliminate the dependency — but it can break the critical path by maintaining multiple independent accumulators or computation streams. For example, what was originally one long dependency chain can be split into several shorter, mutually independent sub-chains, allowing the processor to advance multiple chains simultaneously. Instruction latency is then effectively "hidden" across the parallel streams, and throughput utilization is restored.
This technique is especially effective for operations like vector dot products and reductions. In Gauss-Seidel implementations specifically, it can be combined with the problem's sparse structure, blocking, and red-black ordering to further decouple dependencies between neighboring elements and create room for parallel computation.
Red-Black Ordering is the classic algorithmic strategy for decoupling Gauss-Seidel dependencies and deserves its own explanation. In structured grid problems, grid points are colored like a checkerboard — red and black — so that red point updates depend only on black point values, and vice versa. Within a single-color update phase, there are no data dependencies between any two points, enabling complete parallelization.
The full iteration becomes alternating red-phase and black-phase sweeps, each of which can be vectorized or executed with multiple threads. The tradeoff is that convergence behavior may differ slightly from standard Gauss-Seidel (because the update order changes), but in most practical problems this difference is negligible. High-performance sparse linear algebra libraries such as HYPRE and PETSc both ship red-black Gauss-Seidel solvers, precisely because of their hardware-friendliness.
Compared to loop unrolling, red-black ordering has a stronger advantage at larger parallelism scales. It represents a fundamental algorithmic restructuring rather than a microarchitectural tuning tweak.
Tradeoffs and Costs of Optimization
Loop unrolling is not without its costs. An excessively large unroll factor increases code size, which can raise instruction cache pressure. It also consumes more registers; if the available registers are exhausted, register spilling occurs — variables must be temporarily written back to the stack and reloaded later — which can actually hurt performance.
As a result, the optimal unroll factor typically must be determined experimentally and is highly dependent on the specific processor microarchitecture. A strategy that performs excellently on one CPU may yield little benefit or even regress on another. This is why high-performance numerical libraries generally ship multiple optimized versions targeting different hardware.
Moreover, for inherently serial algorithms like Gauss-Seidel, restructuring the algorithm (e.g., adopting a red-black variant) can sometimes unlock parallel potential more fundamentally than loop unrolling alone.
Register Spilling is the most common negative side effect of excessive loop unrolling, and its mechanism is worth understanding in depth. The CPU register file has limited capacity (x86-64 in AVX-512 mode has 32 512-bit vector registers). When the number of intermediate variables that need to be live simultaneously in an unrolled loop body exceeds the available registers, the compiler or programmer must temporarily write some variables back to stack memory and reload them on demand. This round-trip consumes memory bandwidth and extra instructions, and can disrupt the carefully designed critical path layout.
A useful rule of thumb: unroll factors in the range of 2 to 8 typically yield the best results, and should be coordinated with SIMD vector width. For example, AVX2's 256-bit registers can process 4 doubles at a time, so unrolling 4 or 8 times often works best in conjunction with vectorization. LLVM and GCC's -funroll-loops option heuristically selects an unroll factor, but on performance-critical paths, manual control or #pragma unroll N usually produces more predictable outcomes.
Conclusion: Systems Thinking Behind Micro-Optimization
This discussion around Gauss-Seidel loop-carried dependencies reflects a persistent theme in high-performance computing: there is often tension between an algorithm's mathematical efficiency and its hardware execution efficiency. A faster-converging algorithm does not necessarily run faster, because it may sacrifice parallelism.
By precisely measuring dependency chains, understanding the processor's latency and throughput characteristics, and applying targeted optimizations like loop unrolling, developers can significantly improve real-world runtime without changing the mathematical nature of the algorithm. This closed-loop methodology — measure, analyze, optimize — is the essence of performance engineering.
(Note: This article was written based on limited source material. For specific performance data and implementation details, please refer to the original technical documentation.)
Related articles
The Siberian Ice Maiden and the Archaeological Mysteries of the Scythian World
The Siberian Ice Maiden is a Scythian female mummy from the Ukok Plateau. Her tattoos, silk garments, and grave goods reveal ancient nomadic art, social hierarchy, and cross-regional trade — alongside ongoing repatriation controversies.
SQL Row Pattern Matching: Implementing "Row-Level Regex" with MATCH_RECOGNIZE
MATCH_RECOGNIZE gives SQL regex-like power over row sequences. Detect brute-force attacks, fraud patterns, and user behavior flows with clean, declarative syntax — no more messy self-joins.
Hackers Break Into Flock Surveillance Cameras, Exposing the Inner Workings of License Plate Recognition Systems
Hackers breached Flock Safety's ALPR cameras, exposing how license plate recognition systems collect data and the privacy and security risks they pose.