LoRA in AI Agent Security Governance: From Efficient Fine-Tuning to Behavioral Dependencies

LoRA adapters evolve from efficiency tools to behavioral-dependency trust objects requiring systematic governance in AI agent systems.
This article systematically examines the security governance challenges LoRA low-rank adaptation introduces in AI agent scenarios. As models evolve from chatbots into agents capable of tool use and irreversible actions, a few-megabyte LoRA file can influence planning, tool selection, and real-world behavior — transforming from an engineering optimization into a behavioral-dependency trust object. The core argument is that behavior, capability, and authority must be separated: adapters may change model capabilities but should never automatically expand an agent's authorized operations. Evidence shows fine-tuning causes alignment degradation, shared adapters can carry backdoors, and individually benign modules can produce unsafe behavior when composed. The article distills five governance attack surfaces — identity compatibility, composition safety, supply chain detection, multi-tenant isolation, and distributed revocation — and proposes seven candidate attributes as a research agenda, while honestly acknowledging that security claims await experimental validation.
LoRA (Low-Rank Adaptation) has become one of the most important techniques in large model fine-tuning. By freezing base model weights and training only two low-rank matrices, it achieves model specialization at minimal cost. But as models evolve from chatbots that "answer questions" to AI agents that "take actions," this compact adapter file transforms from an engineering optimization tool into an entirely new trust object — a file of just a few megabytes capable of altering an agent's planning, tool selection, task delegation, and real-world impact.
Brazilian independent researcher Aridio Silva systematically addresses this proposition in the 19th article of his SGAEIA research series. His core argument is clear: LoRA must be governed not merely as a machine learning artifact, but as a behavioral dependency capable of influencing critical actions.
When Models Become Agents, LoRA Takes on New Meaning
LoRA was originally born to solve an economic and engineering problem: adapting an entire model for each task meant training, storing, and running full copies with hundreds of millions of parameters. In their original ICLR 2022 paper, Hu et al. proposed freezing base model weights and representing each update matrix as the product of two low-rank matrices, dramatically reducing trainable parameters while achieving quality close to full fine-tuning on benchmark tasks.
The critical shift is this: in a chatbot, a single behavioral change produces at most one inappropriate response, while in a tool-using agent, the same change can affect API selection, code generation, data access, task delegation, expert routing, and even irreversible operations. The risk doesn't stem from LoRA being inherently malicious — it stems from the combination of "mutable behavioral dependencies" and "systems with external capabilities."
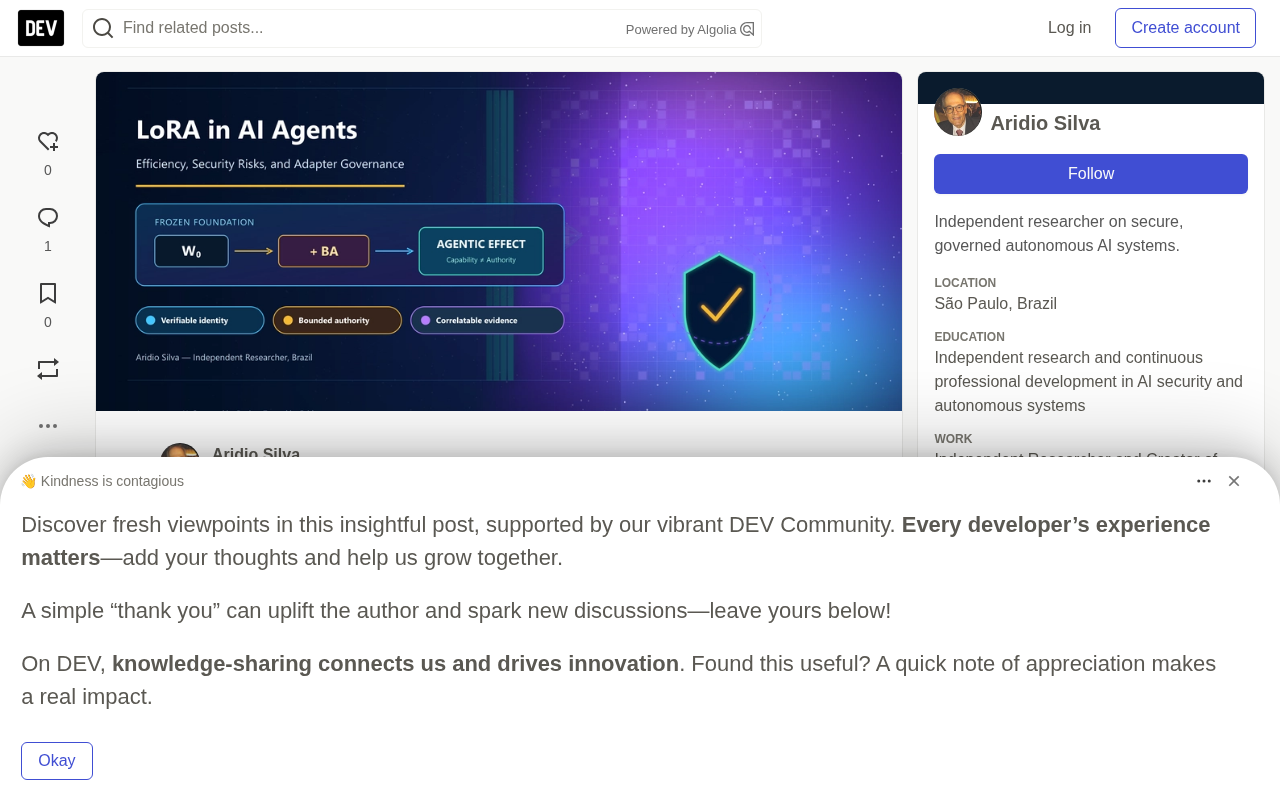
The article draws a central distinction: LoRA provides an efficient pathway to modify capabilities or behavior, but does not itself confer legitimate authority. If loading an adapter silently expands an agent's effective permissions, the problem lies in the governance architecture, not the low-rank algebra itself. The separation of behavior, capability, and authority is the cornerstone of the entire analysis.
The Mechanics and the Supply Chain They Create
Mathematically, for a frozen base matrix W0, LoRA represents the learned update as the product of two smaller matrices: W' = W0 + (alpha/r)BA, where A and B are trainable compact matrices with rank r far smaller than the original matrix dimensions. The parameter savings come from training approximately r(d+k) parameters instead of dk.
The commonly cited "zero additional latency" claim is worth scrutinizing — it applies primarily to static deployments where adapters have been merged into weights. Dynamic loading and multi-adapter serving introduce loading, memory transfer, batching, and routing costs. Systems like Punica and S-LoRA have demonstrated that thousands of specialized versions can share a single base model with significant efficiency gains — meaning multi-tenancy and dynamic switching are real systems engineering challenges, not theoretical possibilities.
Subsequent variants each address different constraints: QLoRA reduces base model memory footprint through quantization, DoRA separates magnitude and direction, LoRA+ uses different learning rates for the two matrices, and PiSSA modifies initialization through singular components. These technical extensions expand the design space but also increase the compatibility and provenance parameters that must be explicitly specified.
Small Files, Large Supply Chains
Compact adapters are easier to distribute, version, and replace than full model copies, enabling domain catalogs, per-customer customization, local updates, and rapid experimentation. But modularity itself constitutes a supply chain: an adapter passes through creation, training, evaluation, packaging, publishing, discovery, downloading, dependency resolution, storage, loading, composition, activation, use, update, and revocation — each step potentially introducing errors, staleness, substitution, version conflicts, or intentional manipulation. The file may be small, but its behavioral effects are disproportionate to its size.
The binding to base models is particularly important. Adapters are produced for a specific combination of architecture, weight version, tokenizer, quantization scheme, target modules, rank, scaling, and loading conventions. Syntactic compatibility does not equal semantic equivalence — a load that "runs successfully" can still produce performance regression or alignment degradation.
The core intuition behind low-rank decomposition is that weight matrix updates in neural networks tend to be "intrinsically low-rank" during fine-tuning — that is, the effective rank of the update ΔW is far smaller than the matrix dimensions. Take a GPT-3 attention layer as an example: the original weight matrix might be a 12288×12288 square (roughly 150 million parameters), while a rank r=8 LoRA decomposition only requires training 2×12288×8≈200,000 parameters — a compression ratio exceeding 700×. The scaling factor alpha/r controls the adapter's influence on base weights, serving as the critical hyperparameter balancing "forgetting old knowledge" against "learning new behaviors." Understanding this mathematical structure helps explain why "syntactic compatibility does not equal semantic equivalence": two adapters targeting the same base model with identical rank configurations have A and B matrices of exactly the same shape, yet can encode entirely different behavioral biases — something type-checking at load time is completely blind to.
From Behavioral Change to Agent Risk
Fine-tuning research shows that customization can undermine safety mechanisms even without malicious intent. Qi et al. (ICLR 2024) observed that just a small number of adversarial examples can cause alignment degradation, and even benign datasets produce smaller negative effects. These results don't mean every LoRA damages safety, but they refute a dangerous assumption: that a base model's alignment is automatically preserved after customization.
In shared ecosystems, LoRATK (EMNLP 2025) demonstrated that backdoors can be embedded in a useful LoRA and propagate to downstream adapters through composition without retraining. Subsequent work on weight-space detection shows that matrix statistics can help flag poisoned adapters in specific experimental datasets, but high accuracy on a particular dataset does not constitute a general-purpose detector. Defenses should combine artifact analysis, behavioral evaluation, provenance tracing, and monitoring rather than relying on any single signal.
Composition Risks Are Even More Treacherous
Colluding LoRA (2026) demonstrates a harder-to-defend class of attack: several adapters that appear benign in isolation can, when combined, undermine safety without any specific text-based trigger. This exposes a compositionality limitation — approving individual modules does not imply approving the set. If the runtime allows arbitrary combinations, the unit of evaluation must encompass the full effective configuration: base model, adapters, ordering, scaling, policies, tools, and execution context.
Adapter composition in engineering typically takes three forms: weight merging (adding BA directly into base weights with no inference overhead), stacked activation (multiple adapters applied sequentially at inference time, with multiplicative effects), and mixture-of-experts routing (dynamically selecting which adapter to activate based on input). The Colluding LoRA attack is so difficult to defend against precisely because it exploits emergent effects in stacked activation scenarios: individual adapter behavior appears completely normal in isolation testing, and the attack effect only manifests when specific combinations are activated — with no text-level trigger required. This is structurally similar to traditional software supply chain attacks where "multiple harmless components combine into malicious functionality," implying that security audits of individual adapters at publication time alone are insufficient — runtime composition state must also be brought within the trust boundary.
Five Critical Attack Surfaces Requiring Governance
The article distills five attack surfaces that must be incorporated into governance, explicitly labeled as SGAEIA "candidate attributes" rather than approved normative requirements.
Identity and Compatibility
An adapter name alone is insufficient as an identifier. A verifiable loading decision should consider artifact digest, provenance, precise base model identity, tokenizer, quantization, target modules, rank, scaling, format, runtime, and applicable policies.
Composition
Separately approved adapters are not automatically approved for summed, merged, stacked, or routed use. Composition must be treated as a new configuration, evaluated proportionate to risk. The goal is not to enumerate every possible combination, but to prevent "untested" from being mistaken for "authorized."
Supply Chain and Detection
Signatures and hashes prove provenance and integrity, but cannot prove behavioral safety. Weight scanning can improve triage, behavioral testing can reveal known triggers, and tool evaluation can measure policy violations — but no single technique eliminates unknown backdoors or emergent effects.
Multi-Tenant Isolation
Shared base models and GPU infrastructure improve efficiency but require isolation between tenant identity, resolved adapters, caches, context, telemetry, and permissions. A routing failure must never allow one tenant's request to use another tenant's adapter.
Distributed Revocation
Revoking an adapter in a central registry does not guarantee that edge nodes, caches, or partitioned worker nodes have stopped using it. Partially disconnected systems require freshness requirements, fail-closed or safe degradation policies, and convergence evidence. The time between a revocation decision and the last authorized execution is an exposure metric, not merely an operational detail.
The distributed revocation problem is structurally analogous to the TLS certificate revocation dilemma: a certificate authority can add a certificate to a Certificate Revocation List (CRL) or publish OCSP responses, but edge node caches, network partitions, and client soft-fail policies (trusting by default when revocation queries fail) can result in revoked certificates still being accepted in practice. LoRA adapter revocation faces similar but more complex challenges: once an adapter file is downloaded to an edge inference node, the local cached copy does not automatically invalidate when the registry updates. In offline scenarios with unstable connectivity, nodes may not even learn that a revocation event occurred. A "fail-closed" policy — refusing to load when adapter validity cannot be confirmed — directly conflicts with the availability-first "fail-open" approach, and system designers must make an explicit policy choice between the two rather than leaving it as an implicit default.
Candidate Attributes and Questions Still to Be Validated
Based on this analysis, the article proposes a clearly non-normative research agenda containing seven candidate attributes: precise binding, no permission amplification, composition-aware approval, invalidation on substitution, tenant and context isolation, time-bounded revocation, and attributable evidence. "No permission amplification" is particularly central — adapters may change capabilities or policies, but must never expand the set of authorized operations.
Commendably, the author maintains honest epistemic boundaries. He notes that until relevant experiments are completed, claiming these attributes can "make agents safe" or that SGAEIA can "empirically reduce risk" would be illegitimate. The current contribution is a technical synthesis, a delineation of problem boundaries, and a research agenda. A derived research program should answer: to what extent do benign, malicious, incompatible, or composed adapters change tool decisions under permission constraints? Which controls reduce policy violations without destroying utility? How much exposure persists on connected, delayed, or offline nodes after revocation?
Value for Three Communities
For software engineering, LoRA makes explicit that behavioral dependencies also require versioning, compatibility control, composition testing, observability, rollback, and configuration management. For AI/ML, the topic connects adaptation efficiency with alignment preservation, utility evaluation, and effects partitioned by layer, rank, quantization, and base model. For cybersecurity, it constitutes an attack surface integrating supply chain, backdoors, detection, multi-tenant isolation, least privilege, incident response, and distributed revocation.
The intersection of all three is the configuration that actually executes. Knowing only which model was requested and which adapter was declared is far from sufficient; real assurance depends on identifying what was actually resolved, loaded, composed, and used, which policy authorized execution, and what operations followed. Observability only upgrades to evidence when it preserves context, integrity, and semantics.
LoRA remains one of the most important techniques for efficient model adaptation. The response is neither to abandon adapters nor to assume that signatures, scanning, or isolated evaluation solves the problem — it is to govern identity and compatibility, constrain permissions outside the model, evaluate composition, isolate tenants, propagate revocation, and preserve attributable evidence.
Related articles

ChatGPT Space Launches: Team Collaboration and New Pages Features Explained
ChatGPT Space is OpenAI's new team collaboration feature with Pages, real-time collaboration, and Slack/Google Drive sync. We break down its privacy design, multi-platform integration, and the full workflow from conversation to document.

Migrating Apache Spark UDFs to GPU Acceleration with AI Agents
NVIDIA developer blog explains how AI Agents rewrite Apache Spark UDFs for GPU acceleration, covering migration criteria, agent rewriting and verification workflows, plus pitfalls like result consistency and CPU-GPU transfer overhead.

Zed Editor v0.40.4-rc2 Released: Usage Credits Now Available Without Upgrading
Zed editor releases v0.40.4-rc2, allowing users to use usage credits for AI features without upgrading to a paid plan, lowering the trial barrier.