M5 Ultra Benchmarked: Up to 4x Faster AI Inference — But at What Cost?

M5 Ultra delivers up to 4.2x AI inference speedup in real tests, but power draw surges to 400W.
Real-world benchmarks confirm Apple's M5 Ultra claims: GPU-side memory bandwidth hits ~1,039 GB/s (1.4x over M3 Ultra), large-model token generation improves ~1.5x, and neural accelerators embedded in every GPU core push prompt processing up to 4.2x faster on long contexts. The gains have a clear threshold — the 4x speedup requires ~4,500+ tokens to materialize, making coding agents the primary beneficiary. The costs are equally clear: the top config runs $14,299, GPU load power jumps from ~100W to 400W+, noise and temperatures rise significantly, and tokens-per-watt efficiency barely improves at ~12%. This machine is built for AI practitioners running large models locally, not general developers.
Apple's latest M5 Ultra chip has finally hit the test bench. Tech blogger Alex Ziskind ran it side-by-side with the previous-gen M3 Ultra, using a series of real-world benchmarks to verify Apple's official claims: up to 4.3x improvement in local AI performance, doubled storage speeds, 1.3x faster CPU, and 1.2 TB/s memory bandwidth. The verdict is straightforward — Apple wasn't exaggerating, but the cost of upgrading is equally real.
Top-Spec Pricing and Hardware
The test unit was a maxed-out Mac Studio: 80-core GPU, 256GB unified memory, 8TB storage, priced at $14,299 (base model starts at $5,499). The 512GB memory configuration is reportedly coming next month at an even higher price.
One noteworthy detail about the chip itself: the M5 Ultra has 36 CPU cores — 24 performance cores and 12 so-called "super cores" — with no efficiency cores. For purely developer-focused tasks, Alex was blunt: this machine is "overkill." Its real value shows up under AI workloads.
To keep things fair, both machines ran identical builds of llama.cpp and MLX with the same model files. llama.cpp is the mainstream cross-platform inference library; MLX is Apple's own AI stack, which typically performs better — though not always.
CPU and Storage: "Double" Is an Understatement
In CPU compilation tests that developers care about, a large .NET build task with 100,000 namespaces and classes took 71.7 seconds on the M3 Ultra and just 52.4 seconds on the M5 Ultra. Python's Mandelbrot calculation test was even more dramatic — dropping from 10.25 seconds to 5.8 seconds, nearly a 2x improvement.
Storage performance also exceeded expectations. In AmorphousDiskMark tests, the M3 Ultra posted sequential read speeds around 6,500 MB/s and writes at 2,700 MB/s. The M5 Ultra blew past that with sequential reads hitting 14,888 MB/s and writes approaching 20,000 MB/s. Alex noted that Apple's official "2x" claim is actually conservative. For AI workflows, this matters a lot — loading a 140GB model from disk is a much shorter wait.
The Core AI Improvement: Neural Accelerators
The most significant architectural change in the M5 generation lies inside each GPU core. M3's GPU cores were standard graphics cores; M5 embeds a dedicated Neural Accelerator for matrix multiplication inside every single GPU core — specialized AI hardware units baked right in.
This change shows up directly in software: with the same llama.cpp build, the M3 Ultra reports has tensor = false at startup, while the M5 Ultra reports has tensor = true. llama.cpp has added a dedicated code path for the M5 generation specifically to leverage these neural accelerators.
When evaluating local LLM inference, there are two key metrics: Token Generation (TG, where the model produces output — bottlenecked by memory bandwidth) and Prompt Processing (PP, where the model reads the input prompt — bottlenecked by GPU compute). The M3 generation's long-standing weakness was PP, and the neural accelerators are designed specifically to address that.
Matrix multiplication is the most compute-intensive operation in LLM inference — whether attention mechanisms or feed-forward layers, it all comes down to large-scale matrix multiplication. Traditional GPU cores are designed for general-purpose graphics rendering and must decompose matrix operations into general instructions, which limits efficiency. Dedicated neural accelerators (similar to NVIDIA's Tensor Cores) use custom silicon-level circuits for matrix multiplication, completing the same computation in fewer clock cycles and at lower power. M5 integrates these accelerators into every GPU core rather than as separate units, meaning all GPU cores benefit directly when processing AI workloads in parallel — no specialized units creating bottlenecks. While Apple's Neural Engine has long existed in Apple Silicon, it primarily handles inference through high-level frameworks like CoreML. The neural accelerators now inside each GPU core let lower-level inference frameworks like llama.cpp and MLX directly access hardware acceleration, covering a much broader range of local AI deployment scenarios.
Memory Bandwidth and Large Model Benchmarks
On the memory bandwidth side, STREAM benchmarks (CPU-side) measured the M5 Ultra at approximately 583.6 GB/s versus the M3 Ultra's 312.9 GB/s. More relevant to AI is the GPU-side bandwidth: the M3 Ultra measured 724 GB/s in practice (vs. 819 GB/s official, ~88% efficiency), while the M5 Ultra hit 1,039 GB/s (vs. 1.2 TB/s official, ~86% efficiency) — about 1.4x the M3's real-world bandwidth.
Testing with the 284-billion-parameter DeepSeekAd V4 Flash, token generation rose from 37 tokens/s to 53 tokens/s — roughly 1.5x, consistent with the memory bandwidth improvement. Prompt processing, however, jumped from 483 tokens/s to 1,485 tokens/s: a 3x leap.
On the 120-billion-parameter GPT-OSS 120B, token generation went from 90 to 130 tokens/s, while PP climbed from ~1,300 to ~3,200 tokens/s. Testing dense models like Qwen3 8B/27B showed ~1.47x token generation improvement, with PP rocketing from 430 to 1,800 tokens/s — more than 4x.
Token generation (TG) speed is tightly coupled to memory bandwidth due to the autoregressive nature of LLM inference: generating each token requires loading the full weight parameters from memory, which for models with tens of billions of parameters can reach hundreds of gigabytes. The compute density is low but data movement is enormous — a classic "memory bandwidth bottleneck" rather than a compute bottleneck. Prompt Processing (PP) is the opposite: processing an entire input prompt allows multiple tokens to be computed in parallel, dramatically increasing compute density. At that point, GPU throughput (especially matrix multiplication throughput) determines speed, not memory bandwidth. This explains why M5 Ultra's neural accelerators deliver far greater gains for PP (up to 4.2x) than for TG (~1.5x): the former is compute-limited, the latter is bandwidth-limited, and real-world memory bandwidth only improved by ~1.4x.
The Real Threshold for 4x Speedup
Apple's official claim of "4x PP improvement" holds up — Alex's real-world tests even reached 4.2x — but with an important caveat.
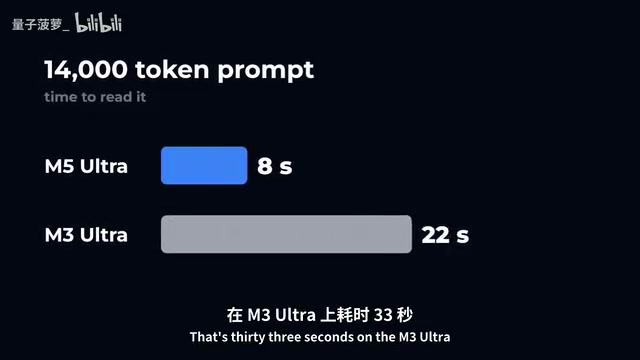
With a ~14,000-token prompt (equivalent to several source files), the M3 Ultra took 33 seconds while the M5 Ultra needed only 8 seconds. But the 4x acceleration only kicks in at around 4,500 tokens or more. At 1,700 tokens it's 3.4x; at ~350 tokens it drops to just 1.6x. In other words, for simple chat interactions you'll barely notice the difference — but feed it entire code files and the gap becomes unmistakable.
This is particularly significant for coding agent scenarios, where large contexts are the norm.
The Cost: Power, Noise, and Heat
The performance gains come with real trade-offs in power consumption and thermal output. At idle, the M3 Ultra draws ~11–12W while the M5 Ultra draws ~8–10W — comparable. But under heavy GPU load, the M3 Ultra consumes around 100W while the M5 Ultra consistently hits 400W and above.
The consequences follow: the M5 Ultra's fan noise is significantly louder — clearly audible on microphone recordings — and temperatures run much higher, around 43–44°C versus noticeably lower on the M3 Ultra. On a tokens-per-watt basis, efficiency only improved by about 12%.
Tokens per watt is a critical metric for AI inference efficiency, especially for local deployments that run continuously. The M5 Ultra's GPU load power consumption jumped from ~100W on the M3 Ultra to over 400W — a ~4x increase — while token generation speed only improved ~1.5x, meaning energy efficiency barely budged. The Mac Studio's compact form factor leaves limited thermal headroom, and 400W of sustained heat means fans must run at high speeds for extended periods. For developers using this at home or in an office, the noise and added electricity costs are real purchase-decision factors — especially when running local model servers 24/7.
Verdict: Who Should Buy It?
Summarizing the results: token generation is ~1.5x faster — a solid improvement; prompt processing delivers 2–4x speedups — a tangible, perceptible upgrade for users running coding agents.
For purely developer workloads, this machine is still overkill — Alex noted that the newly announced M6 mini significantly outperforms it on Speedometer for single-core tasks. The real target audience is AI practitioners who need to run large-parameter models locally and regularly work with long contexts. As for the 512GB configuration, it'll cost more but will run larger models at even higher speeds.
Apple's official numbers hold up to real-world scrutiny. Just don't forget the electricity bill and the noise floor before you hit buy.
Related articles

A Single Prompt Triggers a Global PHP Security Storm: Is AI a Savior or a Hidden Risk?
A single AI prompt triggered a global PHP security crisis affecting Wikipedia and the Internet Archive. This article reviews the incident, analyzes the OpenAI-Amazon controversy, and explores the security paradox of lowered vulnerability discovery barriers in the AI era and developer response strategies.

When AI Is Taken Away: How Reliance on Shortcuts Undermines Your Problem-Solving Resilience
A study of 1,222 people found that after using AI to answer questions, once AI was removed, people gave up on more problems than a control group that never used AI. The article analyzes the impact of AI reliance on learning resilience and metacognition, and explores design implications for AI learning tools.

Carta and NewView Partner to Let Startup Employees Cash Out Equity Early
Carta and NewView Capital partner to simplify startup tender offers, helping employees sell equity early. Analysis of the mechanism, liquidity pain points, and impact.