MAMHOI: Generating Scene-Aware Human-Object Interaction via Affordance Factorization

MAMHOI uses affordance as an intermediate interface to decouple scene understanding and motion synthesis, bypassing the paired data bottleneck.
To address scarce paired data for 3D human-object interaction generation, MAMHOI proposes an affordance-mediated factorization framework with two independently trainable stages: a scene-conditioned model predicts where and how interactions are feasible, then an affordance-conditioned HOI model generates human-object motion. Because affordance is a semantically clear representation decoupled from specific motion, scene understanding learns from human-scene data alone and interaction dynamics from human-object data alone—no paired samples needed.
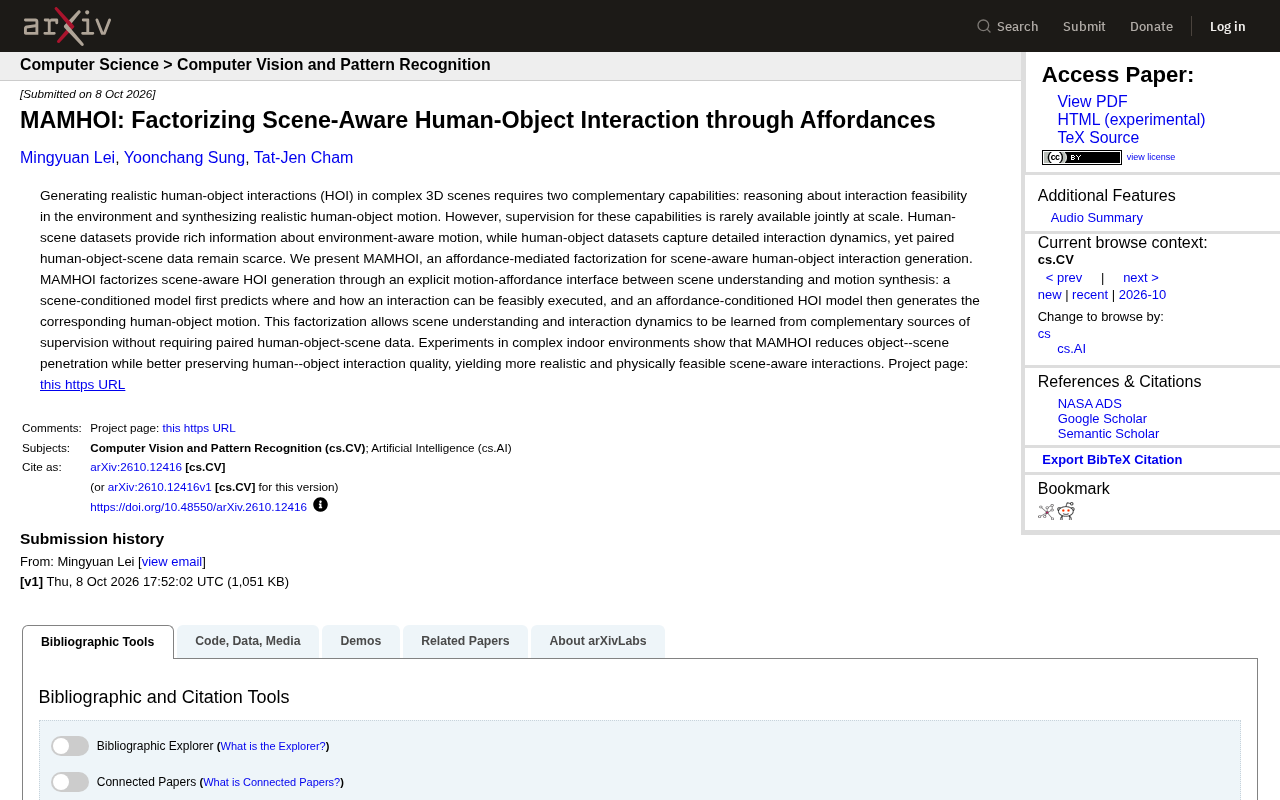
Generating realistic human-object interaction (HOI) in 3D scenes has long faced a structural challenge: understanding whether an environment supports a given interaction and synthesizing natural human-object motion require fundamentally different capabilities, and data that can simultaneously supervise both is extremely scarce.
The latest research, MAMHOI, proposes an "affordance-mediated factorization" framework that splits scene understanding and motion synthesis into two independently trainable modules, thereby bypassing the bottleneck of insufficient paired data. The project page is now publicly available.
Why Human-Object-Scene Triplet Data Is So Scarce
Existing datasets show a clear skew in coverage. Human-scene datasets (such as motion capture in indoor environments) provide rich environment-aware motion information, telling us how people walk, sit, and avoid obstacles in space; human-object datasets focus on interaction dynamics like grasping, carrying, and manipulation—detailed but often detached from specific scenes.
Paired data that truly annotates "human—object—scene" simultaneously is far too limited in scale to support end-to-end training. This leads to a typical dilemma: a model performs reasonably well on a single dataset, but once placed in a complex 3D scene, problems like object penetration and distorted interaction poses emerge.
MAMHOI's core judgment is this—rather than waiting for paired data, change how the problem is decomposed.
To understand why paired data is scarce, consider the cost of collection: annotating human, object, and scene elements simultaneously requires precise human motion capture, pose tracking of the manipulated object, and complete 3D scene reconstruction—all three must be aligned in the same spatiotemporal frame and coordinate system. Existing human-scene datasets (such as indoor motion capture) typically record only human skeletons and coarse environmental geometry, with objects often simplified or ignored; human-object datasets (such as grasping datasets) are usually collected in controlled settings like desktops, with the scene itself highly simplified. The coordinate systems, annotation granularity, and object category systems on both sides are often inconsistent, and simple concatenation does not constitute genuine "paired samples." This is precisely the root cause of why end-to-end methods tend to fail in complex 3D scenes: models perform adequately within the training distribution, but lacking cross-domain alignment supervision, they exhibit penetration, floating, and pose distortion when generalizing to real scenes.
Decomposition Strategy: Connecting Two Worlds with a "Motion-Affordance Interface"
MAMHOI breaks scene-aware HOI generation into an explicit two-stage pipeline:
Stage One: A scene-conditioned model takes 3D environment input and predicts "where and in what manner" an interaction can feasibly be performed. The key concept here is affordance—it describes not the action itself, but the possibilities the environment offers for action, such as a tabletop being suitable for placing objects or a chair seat being suitable for sitting.
Stage Two: An affordance-conditioned HOI model takes the above predictions and generates the corresponding human-object motion sequences.
The significance of this intermediate interface is that the scene understanding module can learn solely from human-scene data, and the interaction dynamics module can learn solely from human-object data. The two connect through affordance representations, requiring no paired human-object-scene samples whatsoever. The original paper summarizes this design as "allowing scene understanding and interaction dynamics to learn from complementary supervision sources."
Affordance as a concept was first proposed by ecological psychologist James J. Gibson in 1979 to describe the action possibilities an environment offers relative to a given agent—it belongs neither to purely objective environmental properties nor to the agent's subjective intentions, but rather to a relationship between the two. For example, the same step might be "sittable" for an adult but merely "holdable" for a toddler. In computer vision and robotics, affordance is typically formalized as a mapping function from scene geometry and object categories to action candidates, with common representations including affordance maps, affordance pose distributions, or contact point distributions. Unlike "action recognition," affordance prediction focuses on "which of many possible actions this environment permits, at which locations, and in what poses"—and thus naturally possesses cross-agent, cross-task shareability. MAMHOI's choice of affordance as the intermediate representation leverages precisely this shareability: it strips away "environment actionability" that is independent of specific human motion from motion synthesis, enabling the two modules to obtain supervision signals from different data sources separately.
Experimental Results: Less Penetration, Better-Preserved Interaction Quality
Experiments in complex indoor environments show that MAMHOI improves both categories of metrics simultaneously:
- Object-scene penetration is significantly reduced. This means the generated motion is more physically feasible—people don't pass through walls or furniture, and objects don't embed into tabletops.
- Human-object interaction quality is better preserved. The factorization does not sacrifice interaction realism for physical plausibility; the trade-off between the two is alleviated.
The researchers conclude that the framework produces "more realistic and physically feasible scene-aware interactions." This result also indirectly supports the effectiveness of the decomposition approach—decoupling feasibility reasoning from motion synthesis actually allows each to be more fully supervised.
Implications of This Approach
MAMHOI's value extends beyond HOI generation itself. It demonstrates a general paradigm for addressing data scarcity: when end-to-end supervision is unavailable, find a semantically clear intermediate representation that can be learned independently, and let data from different sources converge on that representation. Affordance plays exactly this role here.
For directions like robotic manipulation, virtual human animation, and embodied intelligence—which are similarly constrained by insufficient paired data—this "decompose first, then connect" strategy is worth adopting. Of course, the generalization capability of the affordance representation itself, as well as the problem of error accumulation across the two stages, remain areas to watch in future work.
One-line Summary
MAMHOI uses affordance as an intermediate interface to decouple scene understanding from motion synthesis, bypassing the paired data bottleneck.
Paragraph Summary
To address the scarcity of paired data for human-object interaction generation in 3D scenes, MAMHOI proposes an "affordance-mediated factorization" framework that splits the task into two independently trainable stages: a scene-conditioned model first predicts "where and in what manner" interactions can be performed in the environment, then an affordance-conditioned HOI model generates the corresponding human-object motion. Because affordance serves as a semantically clear intermediate representation decoupled from specific motion, the scene understanding module can rely solely on human-scene data and the interaction dynamics module solely on human-object data—no paired human-object-scene samples needed. Experiments show that the framework significantly reduces object-scene penetration in complex indoor environments while better preserving human-object interaction quality, alleviating the trade-off between physical plausibility and interaction realism, and offering a transferable decomposition paradigm for scene-aware interaction generation under data-scarce conditions.
Related articles

JobRunner MCP Server: AI Agents Can Now Fix Failed Java Jobs
JobRunner launches an open-source MCP server enabling AI agents to view cluster status, diagnose failures, and recover Java jobs—incident response from any cloud coding environment or existing agent.

MLAI Digital Launches 9 Security Agents: MCP Server Safeguards the Full Lifecycle of Agentic AI
MLAI Digital launches Security MCP Server with nine built-in specialized security agents covering vulnerability discovery, attack simulation, prompt injection detection, API and infrastructure assessment, and accelerated remediation—embedding security validation across the full Agentic AI lifecycle from development to production.

Running Isaac Lab on H100 GPUs: Exploring Better Approaches
Exploring optimization methods for running Isaac Lab on NVIDIA H100 GPUs, including MIG configuration, mixed precision, TensorRT acceleration, and community experience to improve robotics simulation and reinforcement learning efficiency.