Memory Retrieval for the Future: A Zero-Inference-Cost Prospective Retrieval Mechanism

A prospective retrieval term lifts AI memory recall@5 from 0 to 0.955 on hard tasks at zero inference cost.
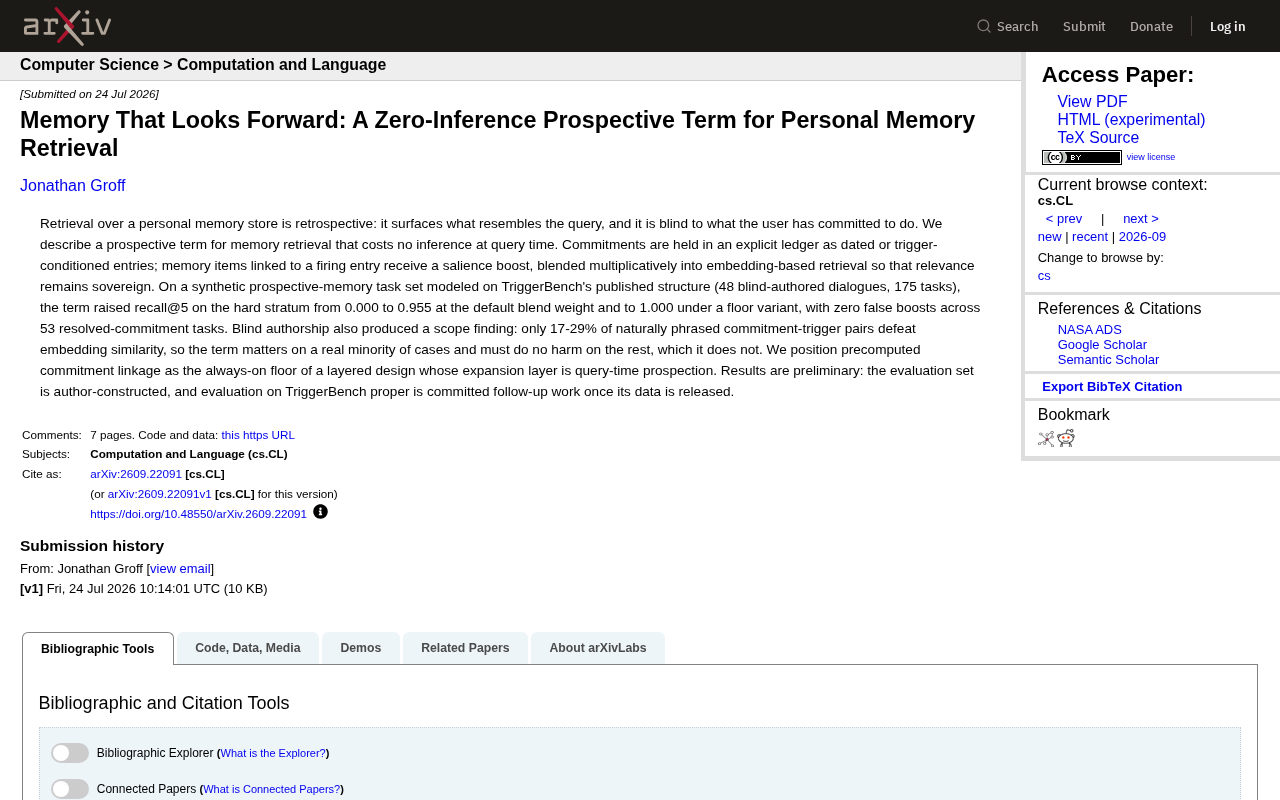
This arXiv paper addresses a long-standing blind spot in personal AI memory systems — the inability to look forward — by adding a prospective retrieval term on top of traditional embedding similarity search. User commitments are stored in an explicit ledger; when trigger conditions activate, relevant entries receive a multiplicative salience boost that preserves semantic relevance while filling retrieval gaps. On a synthetic prospective task set, recall@5 on the hard stratum jumps from 0.000 to 0.955 with zero false boosts across 53 resolved commitment tasks. Blind-authored testing also reveals the scope boundary: only 17–29% of natural commitment-trigger pairs actually need this mechanism, making it a "critical when needed, harmless otherwise" addition. The authors plan follow-up evaluation on TriggerBench once officially released.
From "Recalling the Past" to "Looking Ahead": A New Paradigm for Memory Retrieval
Retrieval in Personal Memory Stores has long been retrospective: the system finds historically stored entries that are semantically most similar to the current query. This works well for answering "what did I say before," but is completely blind to "what has the user committed to doing." A newly published arXiv paper (arXiv:2609.22091) proposes an elegant solution — adding a prospective term to memory retrieval, so the system not only looks back at the past but also "looks forward" into the future.
The core pain point is intuitive. When you tell an AI assistant "remind me to discuss the budget when I meet with Manager Zhang next week," that commitment tends to get buried by the retrieval mechanism when queried later, because the phrasing doesn't have high semantic similarity to the trigger scenario. Traditional embedding-based similarity retrieval simply cannot capture the causal link between a "commitment" and its "trigger."
Embeddings and semantic similarity retrieval form the dominant technical foundation of current AI memory systems. The idea is to convert text into high-dimensional numerical vectors, so that semantically related content sits close together in vector space. At retrieval time, results are ranked by computing cosine similarity between the query vector and stored entry vectors. This approach excels at "finding similar content," but is fundamentally a static semantic match — it cannot understand the temporal causal relationship between "current context" and "past commitments." For example, "meeting Manager Zhang next week" and "budget meeting" are not directly semantically related, so embedding retrieval cannot link them to trigger a reminder. This is precisely what cognitive science defines as prospective memory — remembering to perform a specific action at a future point in time — a dimension where existing AI memory systems are nearly nonexistent.
Core Mechanism: The Commitment Ledger and Explicit Linking
One of the key design choices in this paper is storing user commitments in an explicit ledger, where each commitment carries a date or trigger condition. When a trigger condition is activated, the associated memory entries receive a salience boost.
The critical detail lies in how this boost is blended — it is incorporated into the embedding-based retrieval score in a multiplicative fashion, rather than simply added on top. The advantage of this design is that it ensures "relevance remains sovereign": the prospective weighting only modulates on top of existing relevance scores, rather than forcibly promoting unrelated content.
More importantly, this mechanism incurs zero additional inference cost at query time (zero-inference). Commitment links are precomputed and always available, serving as an "always-on floor" in the layered system design. More complex query-time prospective reasoning exists as an optional extension layer. This layered approach makes the solution both efficient and scalable.
Multiplicative fusion vs. additive fusion is an engineering choice with significant implications in information retrieval. With an additive approach (final_score = embedding_score + salience_boost), a trigger activation could push an entry to the top of results even if it's completely irrelevant to the current query, generating false positives. The multiplicative approach (final_score = embedding_score × salience_multiplier) naturally requires that baseline relevance be non-zero before amplification occurs — entries with low relevance receive smaller absolute boosts, preserving the semantic quality of retrieval results. This aligns with how multi-factor weighting is handled in retrieval models like BM25, and is the key reason this design achieves both "improved recall" and "zero false positives" — two goals that might seem contradictory.
Experimental Results: Recall Jumps from 0 to 0.955
The researchers evaluated their approach on a synthetic prospective memory task set built following the structure of the released TriggerBench, comprising 48 blind-authored dialogues and 175 tasks.
The results are striking:
- On the hard stratum, recall@5 jumps from 0.000 to 0.955 (under default blending weights);
- With the "floor variant," recall reaches 1.000;
- Across 53 resolved commitment tasks, there are zero false boosts — no incorrectly weighted entries.
This leap from 0 to near-perfect demonstrates that traditional embedding retrieval almost completely fails on these difficult tasks, while the prospective term fills exactly that gap. The zero false-positive result also validates the design goal that multiplicative fusion "does no harm to remaining cases."
Recall@K is a core evaluation metric in information retrieval: it measures the proportion of relevant items successfully retrieved within the top-K results returned by the system. This paper uses recall@5, evaluating whether the correct commitment entry appears within the top 5 results. This metric is especially appropriate for "proactive reminder" scenarios — the user doesn't need to manually search; it counts as a success if the correct answer appears among a small number of pushed results. The jump from 0.000 to 0.955 means: traditional embedding retrieval almost never ranked the correct entry in the top 5 for hard-stratum tasks, while introducing the prospective term puts the correct entry in the top 5 in 95.5% of cases. The "hard stratum" typically refers to the subset where commitment descriptions and trigger scenarios differ most in wording — precisely the cases that best reveal the true gap between the two approaches.
An Honest Discovery of Boundaries
What makes this paper noteworthy is its self-examination. Through blind-authored task construction, the researchers uncovered an important fact about the scope of applicability: among naturally phrased commitment-trigger pairs, only 17%–29% would actually defeat embedding similarity retrieval.
In other words, the prospective term truly matters for only a small fraction of real-world cases. This means the mechanism's value lies not in wholesale replacing existing retrieval, but in: (1) resolving those difficult edge cases that embedding retrieval genuinely misses, and (2) causing no harm in the remaining majority of cases. The experimental data shows it achieves both.
This positioning — "critical for a minority, harmless for the majority" — is precisely what engineering practicality looks like: a baseline capability that won't drag the system down, yet steps in when it matters most.
Limitations and Future Work
The authors remain measured in how they frame their results, explicitly noting these are preliminary. The primary limitation is that the evaluation set is a synthetic dataset constructed by the authors themselves, rather than an independent benchmark. The researchers have committed to conducting formal evaluation on TriggerBench once its official data is released.
This candid stance reflects rigorous research norms. For application areas like personal memory systems and long-term AI assistant memory, prospective retrieval offers a low-cost, conceptually clear supplementary dimension that warrants further validation of its generalization capabilities on real benchmarks.
TriggerBench is a standardized benchmark dataset specifically designed to evaluate "trigger-based memory" tasks, testing whether AI systems can accurately recall relevant commitments or intentions when specific contextual triggers occur. The importance of independent benchmarks lies in the fact that synthetic evaluation sets constructed by the researchers themselves carry a potential "self-fitting" risk — task designers may inadvertently bias the test distribution toward cases their own algorithm handles well. TriggerBench, released by an independent party, provides more objective validation of generalization ability. The authors proactively committing to re-evaluation upon official release is an encouraged norm in the AI research community — especially in application-oriented domains like memory systems, where the ability to maintain performance across diverse real-world user intents directly determines a solution's practical deployability.
Implications for AI Memory Systems
The broader significance of this work is that it redefines the temporal dimension that "memory retrieval" should encompass. A large number of AI assistants and agents today are actively building out long-term memory capabilities, yet the vast majority remain stuck in retrospective retrieval. Explicitly modeling users' "future intentions" and incorporating them into retrieval may be the critical step toward giving AI assistants genuine "reminder" and "proactive notification" capabilities.
The zero-inference-cost design also means this type of mechanism can be embedded into existing retrieval pipelines with low friction, without incurring expensive real-time inference costs — making it particularly friendly for real-world deployment.
Related articles

Free Unlimited Claude Code Solution: Agnes AI + CC Switch Setup Guide
No paid subscription needed — pair the free AI platform Agnes AI with the open-source tool CC Switch to provide a backend for Claude Code, enabling unlimited free calls to text, image, and video models. This guide covers the full setup, test results, and usage boundaries.

A Complete Zero-Cost Guide to Getting Started with Claude Code for Beginners in China
A beginner's guide to Claude Code for users in China: two installation methods (command line and IDE plugin), full configuration steps for replacing the official API with the free domestic LongCat model, and a hands-on demo of building a small tool with natural language, plus tips.

When the NSA Gets Involved: The AI Supply Chain Crisis Behind Open-Source CVEs and API Key Hijacking
Multiple open-source projects disclosed severe CVEs in one day, PHP flaws alarmed the FBI, and Railway and OpenCode were breached with API keys stolen. This article breaks down the vulnerability window, AI-accelerated exploitation, and the AI supply chain crisis behind the API key black market, with a developer defense checklist.