Mistral Large 4 Deep Dive: The Agent Ambition Behind a Trillion Parameters

Mistral Large 4 bets on trillion-parameter MoE and trajectory RL to power long-chain Agent tasks.
Mistral Large 4 (codename LeChunk) totals 1.05 trillion parameters but activates only ~49.1 billion per inference via fine-grained MoE, scaling capacity without proportionally scaling compute. Rather than chasing benchmarks, the model targets Agent workflows — its vision encoder actually shrank from 2.5B to 1.6B parameters, shifting focus to multi-step tool use. Training uses trajectory reinforcement learning across code execution, scientific computation, and fact-checking, optimizing entire action chains rather than final answers alone. Trained from scratch on 3,800 Grace Blackwell GPUs in European data centers with no distillation, and planned for full open-source release.
French AI company Mistral has released a new model called Mistral Large 4, with the rather playful codename LeChunk — French slang for "fat cat." The name isn't exactly modest, given the model's total parameter count sits at 1.05 trillion. But at runtime, only around 49.1 billion parameters are actually activated — making it "fat, but with restraint." Not all parameters are mobilized for every inference pass.
The real story here isn't how big it is — it's why it's designed this way.
The Design Philosophy Behind Parameter Growth
From Large 3 to Large 4, total parameters grew by 56%, while activated parameters increased by only 20%. This gap reveals Mistral's approach: rather than making each inference heavier, they spread the expert network wider.
Specifically, Mistral has adopted a finer-grained MoE (Mixture of Experts) architecture — slicing experts into smaller, more numerous units, giving the model a broader combinatorial space to draw from during each inference pass.
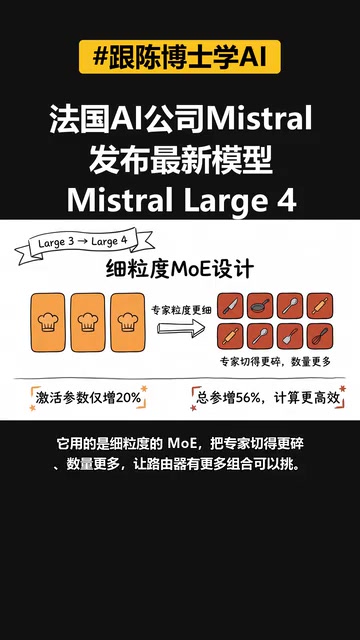
Think of it this way: a standard MoE is like a few master chefs taking turns in the kitchen. Fine-grained MoE is more like a large crew of specialists — for each dish, only the most suitable few are called in. More experts, but the per-inference compute barely budges.
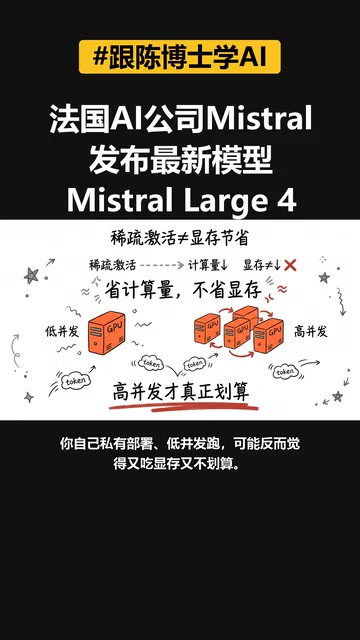
One important clarification, though: sparse activation saves compute, not VRAM. The full set of weights still needs to reside across a multi-GPU cluster, and routing tokens to the right experts across devices introduces communication overhead. The scenario where this architecture truly shines is high-concurrency serving — when a flood of requests arrives simultaneously, expert utilization stays high. Conversely, if you're running a private deployment at low concurrency, you might end up paying the VRAM cost without capturing the efficiency benefits.
MoE Primer: In a Mixture of Experts architecture, instead of a single dense feed-forward network at each layer, the model places multiple "expert" sub-networks at key layers. A lightweight "router" dynamically decides which experts handle each token. This lets total parameter count scale up dramatically while keeping per-forward-pass compute — determined only by the selected experts — to a small fraction of total parameters.
Fine-grained MoE takes this further by splitting each expert into smaller units and increasing their count, giving the router finer selection granularity. Compared to having just a few large experts per layer, this approach improves specialization and combinatorial flexibility — but also raises the bar for routing algorithms and load balancing, since you need to prevent "expert collapse," where a handful of popular experts are repeatedly called while others sit idle.
Multimodal Capabilities Oriented Toward Agent Workflows
The second notable aspect of Mistral Large 4 is how it pushes multimodal capabilities toward actual Agent workflows.
A counterintuitive detail: the vision encoder shrank from 2.5 billion parameters in the previous generation down to 1.6 billion. This isn't regression — it's a shift in priorities. Mistral isn't chasing ever-finer image perception; they're focused on what happens after visual information enters the language model — how it gets used for localization, reasoning, tool invocation, and ultimately completing a multi-step task end to end.
Imagine a task chain like this: find a chart in a PDF, zoom in and inspect it, retrieve related references, then validate a conclusion with code. This kind of multi-step task doesn't demand pixel-perfect vision — it demands the ability to act on what's seen.
Trajectory Reinforcement Learning: Training the Entire Action Chain
Training multi-step Agent tasks is where things get genuinely hard. You can't just reward the model based on whether the final answer is correct — if one intermediate step retrieves the wrong object, everything downstream falls apart.
Mistral's approach integrates code execution, scientific computation, fact-checking, and tool invocation all into a single reinforcement learning environment: code can be run against tests, calculations can be verified directly, and ambiguous outputs are evaluated by a Reward Model.
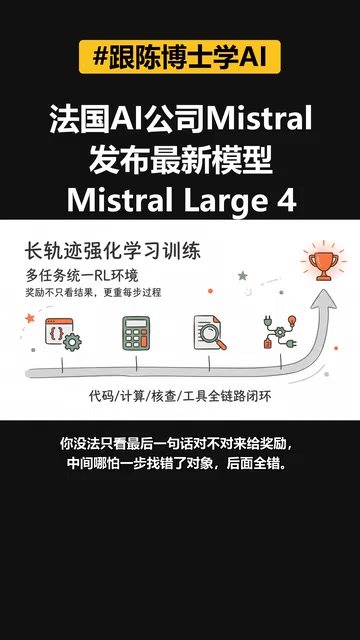
This means the model isn't trained on "final answers" — it's trained on entire action trajectories. But longer trajectories slow training down considerably. To address this, the team uses an architecture where a large pool of Actors generate data in one step while the Trainer continuously updates weights. The trade-off: Actors may be running a stale version of the model, meaning collected samples can become outdated almost immediately — a problem known as off-policy bias that requires dedicated handling.
This also explains why the model's strengths cluster around code, cybersecurity, and spreadsheets — tasks with clear, verifiable acceptance criteria.
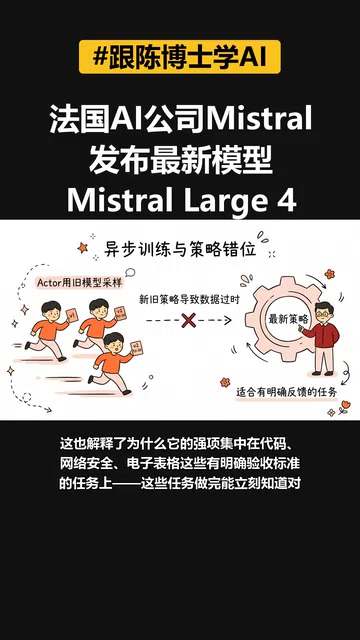
When you can immediately tell whether a task was completed correctly, the feedback is clean, and long-trajectory reinforcement learning can be applied effectively. The clearer the feedback signal, the more reliable the training gradient.
Off-Policy in RL: The "stale policy mismatch" described above corresponds to the off-policy problem in reinforcement learning. Algorithms like PPO (Proximal Policy Optimization) require that the "behavior policy" collecting experience stay close to the "target policy" being optimized — large divergence corrupts gradient estimates and destabilizes training. In large-scale distributed training, many Actors sample in parallel for throughput, but the Trainer continuously updates weights, so Actors always operate on a slightly outdated model version. Common mitigations include importance sampling corrections for stale data, expiration thresholds to discard overly old samples, and algorithms like GRPO (Group Relative Policy Optimization) that are more tolerant of off-policy data. Mistral's specific handling hasn't been fully disclosed, but this remains a recognized engineering challenge in large-scale RLHF/RLVR training.
Trained from Scratch, with Open-Source Plans
One more notable detail: this model was trained entirely from scratch in Mistral's own European data centers using 3,800 Grace Blackwell GPUs — no distillation — with plans to open-source the full weights.
From a technical standpoint, this is an attempt to redefine where a model should be "fat." What Mistral is really betting on isn't benchmark leaderboard placement — it's the kind of long-chain, step-by-step, verifiable capability that Agent scenarios demand.
Whether this approach pays off should become clear soon after the weights are released. For developers tracking open-source LLMs and Agent applications, Mistral Large 4 offers a meaningful reference point — one that diverges from the mainstream "benchmark-chasing" playbook.
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.