Mistral Large 4 Fails the Rubik's Cube Test: Is It the Model or the Framework?

Mistral Large 4 fails the Rubik's Cube test, but the culprit may be the evaluation framework, not the model.
A tester used the classic "build an interactive Rubik's Cube simulator" task to evaluate Mistral Large 4's coding ability — and the result was a failure. The initial 3D cube looked great and supported rotation, but the Scramble button did nothing; after iteration, a new bug emerged where colors disappeared during face rotations, pointing to a state management and render sync breakdown. Notably, the tester didn't blame the model itself, but rather the interaction between the model and the evaluation harness. The article draws a broader methodological lesson: behind every "model fails" headline, the engineering details of the evaluation environment may be equally responsible, and a single test case is never enough to judge a model's overall coding ability.
A Classic Coding Capability Test
When evaluating large language models on programming ability, many testers have their own go-to benchmarks. Building an interactive Rubik's Cube simulator is one of them — it looks simple on the surface, but actually demands a well-rounded combination of spatial logic, 3D rendering comprehension, and interaction handling. This time, the model on the hot seat is Mistral Large 4.
Based on the tester's conclusion, this attempt was "absolutely a failure." But the reasons behind that failure turn out to be far more nuanced than a simple "the model isn't good enough."
First Impressions Weren't Bad
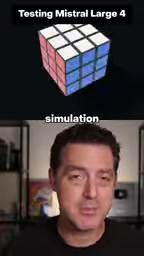
The initially generated Rubik's Cube simulator actually looked quite good. The tester admitted: "It is a cube, I can rotate it, it looks pretty nice, no complaints there."
This suggests that Mistral Large 4 handles the fundamentals of 3D modeling and rendering reasonably well. Correctly rendering a three-dimensional cube with support for viewpoint rotation already requires the model to have a solid grasp of geometric structures and front-end rendering stacks — typically something like Three.js or WebGL.
Three.js is currently the most widely used WebGL wrapper library, allowing developers to render complex 3D scenes in the browser with relatively little code. Generating Three.js code is no small feat for a large language model: the model needs to understand the triangle of Scene, Camera, and Renderer, as well as correctly combine Geometry, Material, and Light. The unique challenge of a Rubik's Cube is that it consists of 26 visible sub-blocks (cubies), each with multiple colored faces, and rotation operations require dynamically reorganizing the parent-child hierarchy of these sub-blocks. Successfully producing this structure on the first attempt indicates that the model has a reasonable grasp of Three.js's overall architecture.
The Problems Start with Interaction
The real trouble began when the tester clicked the "Scramble" button. As described: "When I click scramble, nothing happens, so I have to go back and iterate."
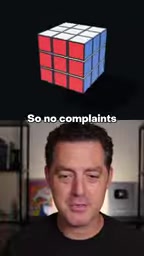
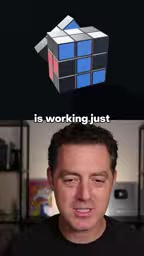
After one round of iteration, things changed — but new bugs surfaced. The rotation of individual faces worked correctly, but once a face was turned, the colored tiles disappeared.
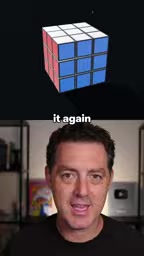
In other words, the model understood the logic of "how to rotate a face," but broke down on state synchronization — keeping the color mapping or face shading consistent after a rotation. This type of bug is a classic pitfall in front-end interactive development, typically occurring at the junction between state management and render updates.
State management and render synchronization are among the most error-prone aspects of front-end 3D interactive development. In a Rubik's Cube simulator, every rotation changes the position and orientation of sub-blocks in 3D space. This requires updating both the internal data structure (tracking which color belongs to which face) and synchronizing the transformation matrices of Three.js objects. When these two states fall out of sync — for example, if the geometry position updates but the color texture still references the old face — you get the symptom of "rotation works but colors disappear or get misplaced." This type of bug is common even for human developers, because 3D rendering engines don't automatically cascade state updates to the business logic layer — explicit synchronization is required.
Who's to Blame: The Model or the Framework?
Perhaps the most thought-provoking aspect of this test is the tester's attribution. He explicitly stated: "I don't actually blame the model itself — I blame the interaction between the model and the testing harness."
This is a critical point that often gets overlooked. When evaluating a model's coding ability today, the model doesn't run in isolation — it's embedded within a harness (an execution and feedback framework). Code generation, execution, error reporting, and iterative correction each introduce their own variables. If the harness misparses the model's output, or if the execution environment doesn't match what the model expected, even perfectly reasonable generated code can produce a "failed" result.
This is a reminder to approach conclusions like "Model X failed" with caution: failure doesn't necessarily reflect the model's capabilities directly — the engineering details of the evaluation environment matter just as much.
A harness (evaluation execution framework) refers to the toolchain responsible for receiving code output from the model, running it in a sandbox environment, capturing error information, and feeding that feedback back to the model. Implementations vary significantly: some harnesses pass along full browser console runtime errors, others only pass static compilation-stage errors, and some re-parse or truncate the model's output. When the harness fails to deliver the correct error context back to the model, the next iteration is essentially "blind debugging" — the model has no way of knowing the true cause of failure, making precise fixes much harder. This is also why the same model can show dramatically different coding performance across different evaluation platforms.
Implications for Model Evaluation
"Fun benchmarks" like the Rubik's Cube test spread widely on social media, but their methodological value lies in exposing the complexity of end-to-end evaluation. A single failed test case is neither sufficient to dismiss a model's coding capabilities entirely, nor strong enough evidence for cross-model comparisons.
For developers who care about AI coding ability, a more meaningful approach is to observe models across multiple harnesses, multiple iterations, and multiple task types — while clearly distinguishing between "model logic errors" and "toolchain issues." Only then can you form a reasonably fair assessment of a model's true capabilities.
Since this material comes from a single tester's real-time experience, the conclusions above represent observations from one specific scenario and should not be taken as a definitive verdict on Mistral Large 4's overall coding ability.
Related articles

Felix Rieseberg Personal Homepage
Felix Rieseberg's personal homepage sparks attention on Hacker News. This article covers the Slack engineer's technical background, the rise and fall of nativefier, and the value of a developer homepage as a tech calling card.

@ai-sdk/vue 3.0.306 Patch Release Syncs with [email protected] Update
@ai-sdk/vue 3.0.306 released, synced with [email protected]. A routine patch release for the Vercel AI SDK ecosystem with no public API changes; the Vue adapter layer stays version-aligned with the core package.

Gemini 4 Argon API Launches: The Era of Million-Token Output Begins
Google launches Gemini 4 Argon with sparse MoE architecture, up to 1M output tokens, and a 68.90% Vals Index score, available across API, AI Studio, and the Gemini app.