Mistral Large 4 'The Chonk' Decoded: Can a Trillion-Parameter Model Outrun Chinese Open-Source AI?

Mistral's trillion-parameter 'Chonk' challenges Chinese open-source models — but key proof is still locked in the box.
French AI company Mistral has released Mistral Large 4, codenamed 'The Chonk,' a flagship model claiming one trillion parameters and native multimodality via a MoE architecture that activates roughly 52 billion parameters per query. Launch-day coverage from CNBC and Reuters framed it squarely against Chinese open-source models, reflecting a broader narrative of Western labs playing catch-up. Mistral's key differentiator is data sovereignty — on-premise deployment suited for sensitive use cases like cybersecurity, a compelling pitch under EU GDPR. However, the CEO's claim of outperforming Chinese models in certain areas lacks published benchmark data or third-party verification. Full details arrive when the countdown ends; watch for the official parameter confirmation, specific benchmark comparisons, and commercial license terms.
A European AI company built a trillion-parameter flagship model and gave it a codename: The Chonk. In internet slang, a "chonk" is a gloriously round, pleasantly fat cat. Pairing a trillion parameters with that nickname creates quite the contrast. This is Mistral Large 4.
What's even more interesting is who it's being measured against. On launch day, both CNBC and Reuters framed their coverage around comparisons with Chinese open-source models. A French company drops a new model, and the most prominent point of reference is work coming out of Chinese teams — that framing alone says something. And the cat hasn't fully shown itself yet: the official page features a countdown timer, with full technical details to be released on a specific date. What everyone is debating right now is, essentially, an unopened box.
Just How "Chonky" Is This Trillion-Parameter Model?
Let's go straight to the source. Hugging Face is essentially the central warehouse of the AI world, where companies upload models for anyone to download. On Mistral's official model page, two facts stand out: one trillion parameters and native multimodality.
Native multimodality means the model was designed from the ground up to handle more than just text — not a module bolted on afterward. As for parameters, think of them as dials inside the model's brain. A few dials can only tune something like volume or brightness; a trillion dials can tune the subtle nuances of language. By that count alone, this cat is genuinely hefty.
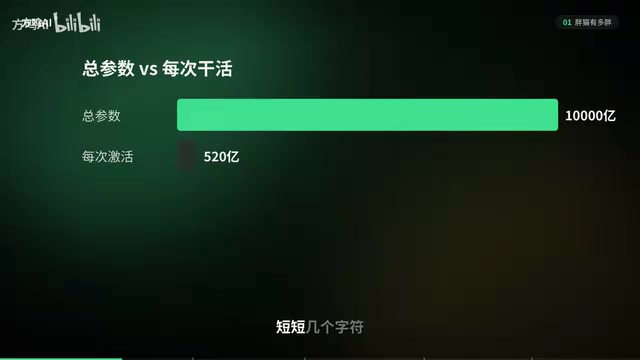
But does every single one of those trillion dials turn every time the model answers a question? No. The secret is in a small detail in the repository name: A52B. By industry convention, the "A" stands for activated parameters, and "52B" means 52 billion. In plain English: the total is one trillion parameters, but only around 52 billion are actually doing the work on any given response.
Here's a useful analogy: think of it like a vast hospital with more doctors than you can count. When you walk in, you don't get surrounded by the entire staff — triage sends you to the handful of specialists who are actually relevant to your case. The hospital's scale determines what conditions it can treat; what it costs per visit depends only on the doctors who actually see you. This is the core idea behind the Mixture of Experts (MoE) architecture. Generating every single word requires a round of computation — if you engaged all trillion dials each time, it would be slow and expensive. Activating only a small fraction keeps things fast and the bills manageable.
One caveat: the 52 billion figure is currently inferred from repository naming conventions. Official documentation hasn't been released yet, so treat it as a working estimate until confirmed.
A note on MoE architecture: Traditional "dense" models engage all parameters during every inference pass. MoE splits the model into many "expert" sub-networks, with a component called a router deciding which experts to activate for each input. This lets model makers scale up total parameter counts without proportionally increasing compute costs — total parameters determine knowledge capacity; activated parameters determine actual inference cost and response speed. Flagship models like GPT-4 and Gemini 1.5 are widely believed to use similar architectures. MoE isn't without trade-offs: the routing logic requires careful tuning, or you risk "load imbalance" where some experts are overused while others sit idle — a key quality indicator when evaluating any MoE model.
Why Are Western Open-Source Labs All Benchmarking Against China?
Rewind to launch day. CNBC reported that Mistral had released the new model and called it "among the best open-source models in the world," then set a tone for the whole industry: Western developers are catching up to Chinese open-source models. Those two words carry weight — in that framing, the ones out front aren't the Western companies; it's the Chinese open-source models.
Reuters ran an even more direct headline the same day: Mistral's CEO says the new model outperforms Chinese models in certain areas. Notice "certain areas" — not across the board. Which areas, and which specific rival, remain to be seen.
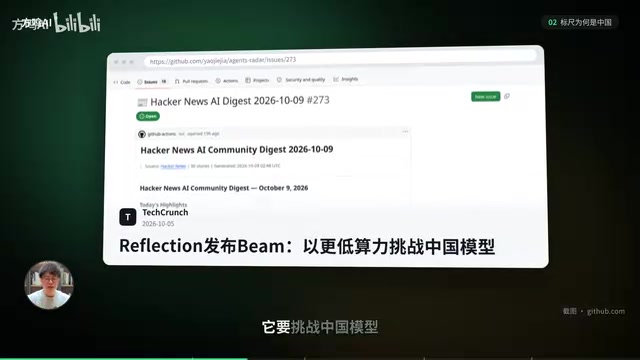
Mistral isn't alone in this framing. The day before, US company Reflection released an open-source model, and TechCrunch's headline called it a challenge to Chinese models — emphasizing "at lower compute cost." Two Western companies, back to back, each releasing a major open-source model and each pointing to the same reference point. The logic is simple: in a race, you only watch the runner ahead of you. According to CNBC's framing, the runner being watched on the open-source track right now is China. When everyone uses you as their measuring stick, you become the standard.
And the team being measured hasn't slowed down either. That same week, Stepped Star's Step 5 preview appeared on the model platform OpenRouter. The whole scene resembles a marathon: the leaders are accelerating, the chasers are pushing hard, and nobody can afford to ease up.
Mistral's Other Card: Data Sovereignty
If Mistral were only trying to prove it runs fast, the story would be straightforward. But it's holding another card — one with a distinctly European flavor. ZDNet's coverage focused on two things: AI-powered cybersecurity capabilities for enterprises, and the fact that you control it yourself.
"You control it yourself" is the real headline. Once Mistral releases the model weights, enterprises can download the entire model and run it on their own infrastructure — no data ever leaves for a third-party server. It's the difference between renting and owning: calling someone else's API is like renting, where the landlord can change the rent or the rules at any time; running the model on your own servers is like owning, where you decide who has the keys.
This concept has a more formal name: data sovereignty.
Why cybersecurity specifically? Because the data security teams handle is often a company's most sensitive. AI can do a lot here — scanning massive logs, flagging anomalies, writing incident reports — all high-volume, repetitive work that's well-suited for a model. Imagine a European bank's security director who wants to use AI to analyze system logs for anomalies. Those logs are the most sensitive data the bank owns. Ask him to send them to a remote overseas API endpoint, and he'll probably say no on the spot. For that kind of customer, a model you can host in-house is the only model that's actually usable.
That said, don't applaud too quickly. Owning has its own costs: even if only 52 billion parameters activate per query, you still have to house the entire trillion-parameter cat on your premises, and you need a big enough "home" for it. Being able to deploy it and being able to afford to deploy it are different things — trivial for large enterprises, but a real barrier for smaller teams. An open-source cat does not come with free cat food.
On the European data sovereignty context: The EU's General Data Protection Regulation (GDPR) places strict limits on cross-border personal data transfers, especially outside the EU, with fines of up to 4% of global annual revenue for violations. This has sharply increased European enterprise demand for "data doesn't leave the country" solutions. The EU's Data Act and AI Act are further tightening localization requirements for critical infrastructure and high-risk AI applications. As a French company, Mistral occupies a natural compliance advantage — it can credibly promise European clients that their entire AI processing chain stays local, never crossing any regulatory line. This explains why "deployable in your own data center" functions not as a feature footnote but as a core selling point in the European market.
"Outperforms" — Where's the Evidence?
How much evidence actually supports the claim of "outperforming Chinese models"? After going through everything currently verifiable, the picture is a bit awkward: which specific domains, which exact rival model, and what the underlying benchmark data looks like — none of this is on the table yet.
A credible scorecard needs to answer at least four questions: what tests were run, who else was tested, who administered them, and whether the results are publicly auditable. Ideally the tests are public benchmarks, the rivals are named specifically, and evaluation is third-party. Right now, none of that is confirmed.
Some people aren't waiting. A company called MindStudio accessed the model via OpenRouter and tested its coding ability — and their article title itself was a question mark. That's exactly the right question to ask, because benchmark scores and real-world performance are very different things. Acing a written driving test doesn't mean you can smoothly navigate a narrow old-city alley during evening rush hour. A leaderboard score is one thing; helping you build a real project from scratch is another.
There's also an important distinction to draw: the "outperforms" claim comes from Mistral itself. CNBC and Reuters reported that claim — reporting it is not the same as verifying it. Until the raw data is public, "outperforms" is Mistral's assertion, not an established fact. The good news is this uncertainty has an expiration date: the scorecard may arrive alongside the full parameter release.
What to Watch When the Box Opens
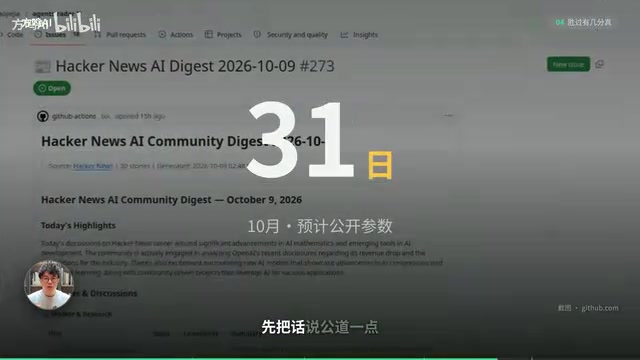
As of this writing, hundreds of people have already clicked "notify me" on the Hugging Face page for a model whose parameters haven't even been published yet. The page itself says "Current ETA" — and "estimated" means it could slip.
When opening day comes, three things are worth watching closely:
- The official model card: How many parameters actually activate per call — does the 52 billion estimate hold up?
- Benchmark results: In which specific tasks does it "outperform Chinese models," and compared against which models exactly?
- The open-source license: Can enterprises actually use it freely for commercial deployment? This sounds like the dullest item on the list, but it's arguably the most consequential. "Open-source" covers a wide spectrum — some licenses allow unrestricted commercial use, others come loaded with conditions. For companies planning to run The Chonk in their own data center, the license terms may matter more than any benchmark score.
And there's one thing outside Mistral's control: what independent third-party testing shows after the release.
Zooming out, in the span of just a few days, Reflection, Mistral, and Stepped Star each played a card on the same table. The open-source model arena is getting crowded fast. If The Chonk opens on schedule and the scorecard holds up to third-party scrutiny, there will be a genuine European seat at that table. But if the release slips, or if real-world tests fall short of the headlines, what people will remember is probably just the adorable nickname.
On AI open-source license complexity: Common license types range from permissive to restrictive: Apache 2.0 (allows commercial use, modification, and redistribution with minimal constraints), MIT (similar, even more concise), and custom "community licenses" that have become common practice among AI companies. The latter look open on the surface but often include restrictions on commercial-scale use, competitive deployment, or specific industry applications. Meta's Llama series and some of Mistral's earlier models have used custom licenses with added conditions. For enterprise users, "open-source" does not automatically mean legally free to commercialize. Before deploying, you must read the license text carefully — especially clauses around user-scale thresholds, prohibited uses, and redistribution rights.
Related articles

AgentCore in Practice: Connecting Custom Tools and MCP Servers to Agents
DebuggerCafe tutorial shows how to connect custom tools and MCP servers to Amazon Bedrock AgentCore agents, covering tool contract design, MCP reuse, and production concerns.

816B Parameters Scores Only 39? The Real Cost-Effectiveness of the Open-Source LLM Parameter Race
Meta's 816B Muse Spark Open scores just 39 on Artificial Analysis, while 180B Qwen3.8-Flash-Next scores 40. This article analyzes 11 open-weight models' parameters vs. scores, exploring the real impact of activated parameters, quantized size, and deployment cost.

Aerial Manipulators: The Next Step for Drones from 'Seeing' to 'Changing'
Starting from a Reddit discussion, this article analyzes the technical challenges, potential applications, and deployment bottlenecks of aerial manipulators, exploring the key challenges for drones moving from environmental perception to physical manipulation.