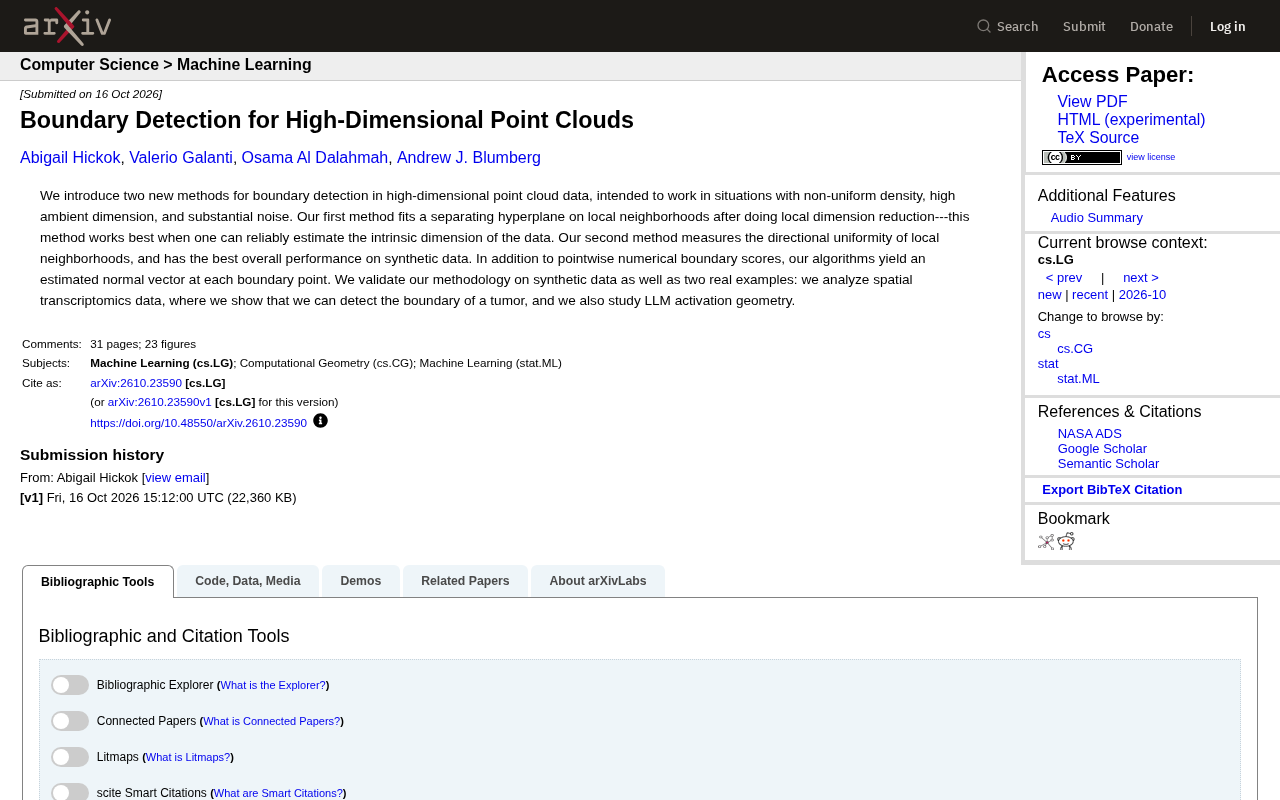
New Breakthrough in High-Dimensional Point Cloud Boundary Detection: Dual Algorithms Tackle Noise and Non-Uniform Density

Two new methods for high-dimensional point cloud boundary detection, validated in tumor boundary and LLM activation analysis.
Addressing challenges of non-uniform density, high ambient dimensionality, and noise in high-dimensional point cloud boundary detection, the article introduces two new methods: one based on local dimensionality reduction followed by fitting a separating hyperplane, and another scoring via a directional uniformity measure. Method 1 relies on intrinsic dimension estimation, is highly interpretable, and outputs normal vectors; Method 2 has low computational complexity, is more robust to noise and non-uniform density, and performs best on synthetic data. Both methods demonstrate practical value in two real-world cases: tumor boundary detection in spatial transcriptomics and LLM activation geometry analysis. The article also discusses limitations and future directions, such as adaptive neighborhood selection and integration with deep learning.
Why Is High-Dimensional Point Cloud Boundary Detection So Difficult?
Point cloud boundary detection aims to identify regions in a data distribution where density changes abruptly or structure shifts. In low-dimensional spaces, methods based on density gradients or geometric topology are usually effective, but high-dimensional data brings the curse of dimensionality: sparse samples, failing distance metrics, and accumulated noise. Non-uniform density means boundaries may occur in regions with vastly different densities, while high ambient dimensionality makes local neighborhood structure hard to estimate reliably. Existing methods often assume uniform density or low-dimensional manifolds, leading to degraded performance in real-world scenarios.
According to the original description, the new methods are specifically designed for "non-uniform density, high ambient dimensionality, and significant noise," aiming to provide more robust boundary scoring and normal vector estimation.
Method 1: Local Dimensionality Reduction + Separating Hyperplane
The core idea of the first method is to perform dimensionality reduction within the local neighborhood of each point, then fit a separating hyperplane to distinguish the two sides of a boundary. Specific steps include: selecting a local neighborhood for each point, estimating its intrinsic dimension, projecting the neighborhood into a low-dimensional space, then fitting a hyperplane and computing the distance from the point to the hyperplane as the boundary score. This method relies on reliable intrinsic dimension estimation—if the estimate is accurate, it can effectively capture local geometric boundaries.
The advantage of this method is its strong interpretability; it also outputs estimated normal vectors for boundary points, providing directional information for subsequent analysis. However, intrinsic dimension estimation may be unstable in high-noise or extremely sparse regions, limiting its robustness. The original text notes that this method "works best when the intrinsic dimension of the data can be reliably estimated."
Intrinsic dimension refers to the dimensionality of the low-dimensional manifold or subspace in which high-dimensional data points actually reside; it is typically much smaller than the ambient dimension. For example, a curved surface in three-dimensional space has an intrinsic dimension of 2. In point cloud boundary detection, estimating the intrinsic dimension of local neighborhoods helps project high-dimensional data into a low-dimensional space, thereby avoiding the curse of dimensionality and reliably fitting a separating hyperplane. Common estimation methods include maximum likelihood estimation based on nearest-neighbor distances (such as the Levina-Bickel method) or eigenvalue analysis based on local principal component analysis. The accuracy of intrinsic dimension estimation directly affects the quality of dimensionality reduction and hyperplane fitting, and may be biased especially under noise and non-uniform density.
Method 2: Directional Uniformity Measure
The second method does not rely on dimensionality reduction; instead, it directly measures the uniformity of the directional distribution of points within a local neighborhood. For boundary points, the points in their neighborhood tend to be denser in a certain direction, resulting in a non-uniform directional distribution; whereas for interior points, the neighborhood directional distribution is more uniform. By quantifying this directional uniformity (e.g., using statistics or entropy), a boundary score can be obtained for each point. This method performs best on synthetic data and is more robust to noise and non-uniform density.
The computational complexity of the directional uniformity method is relatively low because it avoids dimensionality reduction and hyperplane fitting, making it suitable for large-scale point clouds. The original text mentions that this method "has the best overall performance" on synthetic data, indicating its advantage in controlled experiments.
Directional uniformity measure is a non-parametric statistical method used to assess whether the directional distribution of data points within a local neighborhood is uniform. Specifically, for each point, compute the direction vectors of all points in its neighborhood relative to the center point, then analyze the distribution of these direction vectors on the unit hypersphere. If the directional distribution is uniform (e.g., measured by entropy or a uniformity test), the point is more likely to be in an interior region; conversely, if the directional distribution is concentrated in certain directions, it indicates that the point is near a boundary. This method avoids dimensionality reduction and hyperplane fitting, offering higher computational efficiency, but it is sensitive to neighborhood size and noise, and its statistical efficiency may decrease in very high dimensions.
Experimental Validation: From Tumor Boundaries to LLM Activation Geometry
The authors validated the methods on synthetic data and two real-world cases. In spatial transcriptomics data, point clouds represent cell positions in tissue slices, with each point carrying gene expression information. The new method successfully detected tumor boundaries that matched known pathological boundaries, demonstrating practical value in biomedicine. Another case is LLM activation geometry: analyzing the point cloud structure of internal activation vectors in large language models, where boundary detection helps understand the geometric properties of the model's representation space, such as the separation boundaries between different semantic clusters.
Both cases involve high dimensionality, noise, and non-uniform density, validating the generalization ability of the methods. The original text emphasizes that the algorithms not only output per-point numerical boundary scores but also provide normal vector estimates for boundary points, which is very helpful for subsequent surface reconstruction or region partitioning.
Spatial transcriptomics is a technology that simultaneously measures cell spatial positions and gene expression in tissue slices, producing high-dimensional point cloud data where each point represents a cell, its coordinates are spatial positions, and its attributes are gene expression vectors. Tumor boundary detection aims to identify cells at the interface between tumor tissue and normal tissue, where boundaries exhibit abrupt changes in gene expression and spatial distribution. By applying high-dimensional point cloud boundary detection methods, these boundary regions can be identified in an unsupervised manner, helping to understand the tumor microenvironment and invasion mechanisms. LLM activation geometry refers to analyzing the high-dimensional point cloud formed by internal neuron activation vectors in large language models; boundary detection can reveal separation interfaces between different semantic or functional clusters, providing a geometric perspective for model interpretability.
Limitations and Future Directions
Method 1 relies on the accuracy of intrinsic dimension estimation and may fail under extremely high noise; Method 2, while robust, may be insensitive to certain boundary types. Future work could explore adaptive neighborhood selection, integration with deep learning features, and extension to dynamic point clouds. In addition, the statistical efficiency of the directional uniformity measure in very high dimensions still requires theoretical analysis.
Overall, this research provides two complementary tools for high-dimensional point cloud boundary detection, advancing geometric analysis in fields such as spatial transcriptomics and LLM interpretability.
Related articles

Apple Opens Multiseat Subscription Purchasing: App Subscriptions Can Now Be Sold in Bulk to Businesses and Schools
Apple opens multiseat purchasing for auto-renewable subscriptions: businesses and schools can bulk-buy via Apple Business and Apple School Manager, adding or removing seats anytime. Enabled by default in App Store Connect—developers should verify settings; group purchasing sandbox testing opens October 2026.
Meta Restarts Muse Sharing Feature: A Security Gamble After Privacy Controversy
Meta re-enabled Muse AI sharing after researchers found public chat links exposed sensitive data like revenue reports and loan applications. Privacy vs. convenience.

X-Hinges: Giving Everyday Objects Sensing Capabilities Through 3D Printing
X-Hinges is a design software that automatically embeds sensors into 3D-printed objects, enabling lamps, gloves, and other everyday items to sense human contact and respond adaptively. This article covers its core features, design approach, and potential limitations.