One-Year-Old AI Lab Flapping Airplanes Raises $1B Series A at $6B Valuation
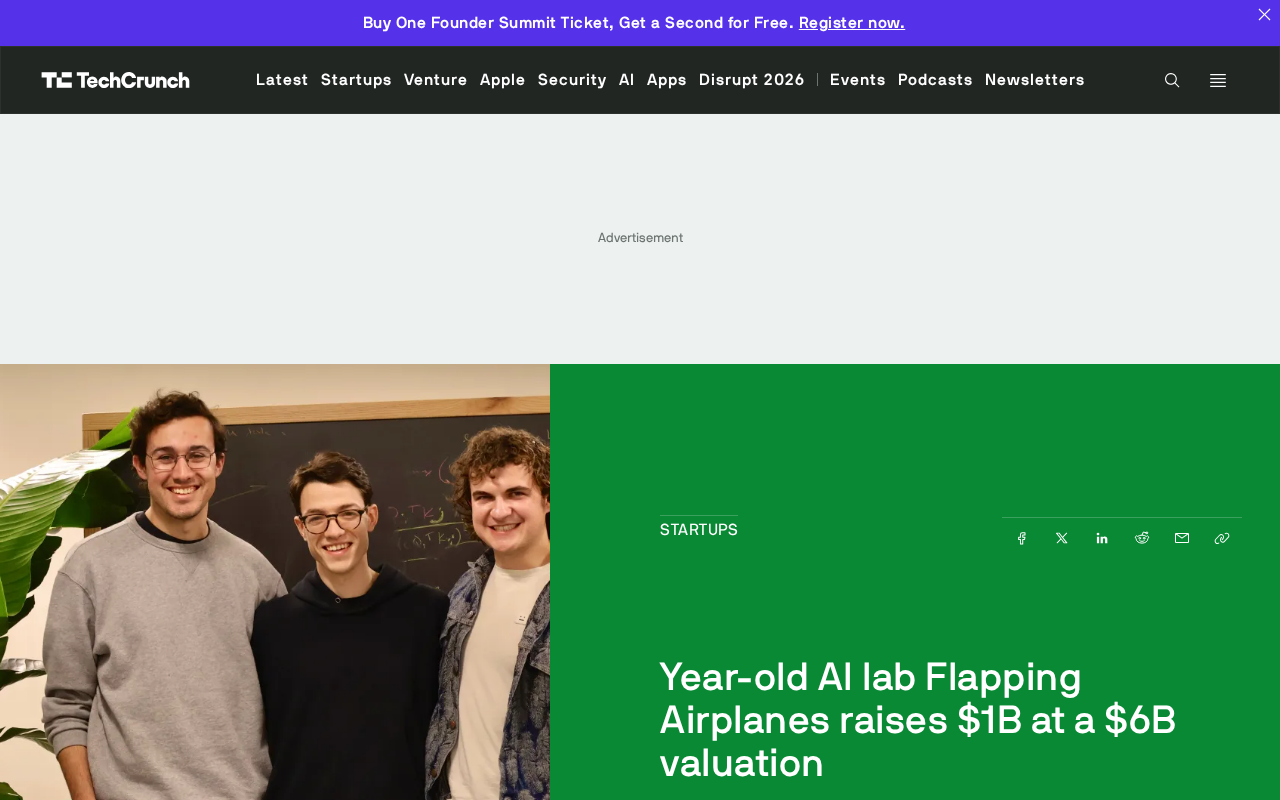
One-year-old AI lab Flapping Airplanes raises $1B Series A at $6B valuation, betting on a new training approach free from massive internet data.
AI lab Flapping Airplanes, founded just over a year ago, has completed a $1 billion Series A at a $6 billion valuation, only nine months after its $180 million seed round. Its core proposition is to build AI models that "don't have to swallow half the internet"—reducing reliance on massive internet-scraped data and directly challenging the mainstream "data scale above all" paradigm. This approach aligns with industry anxiety over data bottlenecks, copyright litigation, and rising training costs, but technical details remain undisclosed. The article argues the $6 billion valuation is not based on revenue or products but is capital's option on a "paradigm shift," carrying extremely high execution expectations and technical validation risks.
The AI lab Flapping Airplanes, founded just over a year ago, has announced the completion of a $1 billion Series A funding round at a valuation of $6 billion. This comes only nine months after its $180 million seed round—such rapid capital accumulation is rare in the AI field.
According to the original report, the lab aims to build AI models that "don't have to swallow half the internet"—that is, to train AI systems without relying on massive amounts of public web data. This technical approach directly challenges the current mainstream paradigm of "data scale above all" for large models, and forms the core narrative behind its massive funding.
Funding Pace and Valuation Leap
Flapping Airplanes' funding curve is remarkably steep. The $180 million seed round was replaced by a $1 billion Series A within nine months, with the valuation simultaneously pushed to $6 billion. This means investors have assigned an extremely high premium to its technical direction in a very short time.
Such a pace is not uncommon at the AI infrastructure layer, but it remains aggressive in the niche of "alternative training methods." The willingness of capital to place heavy bets on a technical path not yet validated at scale reflects the market's anxiety over the data bottleneck of existing large models—the stock of high-quality public text is approaching its ceiling, and the marginal returns from continuing to pile on data are diminishing.
What "Not Swallowing Half the Internet" Means
The lab's public statements point to a clear technical proposition: reducing dependence on internet-scraped data. This could involve multiple directions such as synthetic data, curated domain data, reinforcement learning signals, or novel pretraining objectives, but the original report did not disclose specific technical details.
From an industry perspective, this direction aligns closely with recent discussions around data compliance, copyright litigation, and rising training costs. If comparable performance can be achieved with a smaller data footprint, it would simultaneously mitigate legal risks and compute expenses. But the challenges are equally obvious: improvements in data efficiency often come with trade-offs in generalization ability, and no public benchmark currently proves that this approach can support general capabilities.
Data Wall is the key context for understanding the lab's technical proposition. In recent years, AI researchers have widely warned that the stock of high-quality public text is nearing exhaustion, and existing mainstream large models have already consumed most of the accessible high-quality corpus on the internet. Estimates from organizations such as Epoch AI suggest that if current training data growth rates continue, high-quality language data may be largely used up around 2026—a phenomenon aptly called the "data wall." Beyond the data wall, continuing to scale models will face the dilemma of having no data available, with marginal returns dropping sharply. This is precisely the real-world basis for Flapping Airplanes' "not swallowing half the internet" narrative—it seeks to explore alternative training paths that do not rely on massive web scraping before the data wall arrives, thereby bypassing this structural bottleneck.
Synthetic Data is one of the most frequently discussed technical directions in the "less data" approach. The basic idea is to use existing models to generate training corpus rather than relying entirely on real internet text, thereby extending training signals on the basis of limited real data. The advantages of synthetic data lie in strong controllability, the ability to cover rare scenarios in a targeted manner, and avoidance of copyright and privacy risks; but the risks are equally prominent: training a model on its own generated data can easily lead to "model collapse"—a gradual degradation of distribution and loss of diversity. Therefore, how to strike a balance between synthetic and real data, and how to design filtering and validation mechanisms, are the core challenges determining whether this approach can succeed. The original report did not disclose Flapping Airplanes' specific technical details, but synthetic data is one of the most likely directions involved in its "not swallowing half the internet" proposition.
Why Capital Is Betting on an Early-Stage Lab
A $6 billion valuation for a one-year-old company is not priced on revenue or products, but on the scarcity of its team background and technical approach. In an environment where AI investment is generally concentrating toward the leaders, institutions willing to offer high valuations to early-stage labs are essentially buying options on a "paradigm shift."
The risks are equally clear. A $1 billion funding round implies extremely high execution expectations, and any delay in technical milestones could trigger a valuation correction. In addition, talent competition in this field is fierce, and the lab needs to maintain the purity of its research culture during expansion—often the first element sacrificed during rapid scaling.
The term Paradigm Shift in the context of AI investment specifically refers to a fundamental replacement at the level of training methodology, rather than incremental improvements in model performance. The current mainstream paradigm centers on "Scaling Law"—simultaneously expanding parameters, data, and compute yields predictable performance gains. The "data efficiency" path represented by Flapping Airplanes seeks a new performance growth curve outside the scaling law; once validated, it would restructure the entire industry's cost structure and competitive landscape. Capital betting on a lab founded just one year ago at a $6 billion valuation is essentially pricing the possibility of such a paradigm shift: if the approach succeeds, early entrants will gain enormous first-mover advantage; if it fails, it corresponds to extremely high valuation correction risk. This "option-style" pricing logic is a typical reaction of the current AI primary market to disruptive technical approaches.
Editorial View
The Flapping Airplanes funding event is more a signal than a conclusion. It shows that capital is positioning early for AI training methods in the "post-data-wall era," but technical validation remains at a very early stage. For practitioners focused on AI infrastructure, what is worth tracking is not the valuation figure, but whether the lab subsequently publishes reproducible training efficiency data—that is the key to judging whether this approach is real or not.
One-line Summary
One-year-old AI lab Flapping Airplanes raises a $1 billion Series A at a $6 billion valuation, betting on a new training approach that does not rely on massive internet data.
Paragraph Summary
AI lab Flapping Airplanes, founded just over a year ago, has completed a $1 billion Series A at a $6 billion valuation, only nine months after its $180 million seed round. The lab's core proposition is to build AI models that "don't have to swallow half the internet"—reducing reliance on massive internet-scraped data and directly challenging the current mainstream "data scale above all" paradigm. This approach aligns with industry anxiety over data bottlenecks, copyright litigation, and rising training costs, but specific technical details have not been disclosed. The article argues that the $6 billion valuation is not based on revenue or products, but is an option purchased by capital for a "paradigm shift," corresponding to extremely high execution expectations and technical validation risks.
Related articles

Cursor AI Programming in Practice: Build a Student Management System from Scratch in 30 Minutes
A Bilibili creator demonstrates Cursor AI programming: generating a student management system in 30 minutes with natural language. Details on Agent mode, Claude selection, prompt techniques, and thresholds.

Top 20 AI Coding Tools Ranking: From Rock-Solid to Lackluster, a Scored Matrix
Bilibili creator releases top 20 AI coding tools ranking, tiered T0–T4 from rock-solid to lackluster, with Claude Code and Codex tied at T0. This article details the scoring dimensions (capability, reliability, robustness, durability, cost, domestic availability) and tool performances to help developers choose the right AI coding assistant.

Vibe Coding Systematic Tutorial: Master AI-Assisted Programming from Zero
A three-month Vibe Coding tutorial from a Bilibili creator covering Codex, ClaudeCode, and Cursor, from core logic to commercial project practice for beginners.