OpenAI Introduces Decisions API: Enabling AI to Make Choices in Milliseconds

OpenAI's Decisions API turns large models into millisecond-speed decision engines using constrained output.
OpenAI's Decisions API, powered by GPT-6 Luna, limits output to a small set of predefined options to achieve nearly 10x faster responses and sub-100ms server-side latency. It supports both text and image input for use cases like ticket routing, sales lead classification, real-time lane detection, voice-driven character expressions, and robot head control. A standout feature is its semantic reasoning on ambiguous instructions—distinguishing "apple" from "more fun thing"—rather than relying on pixel matching. Performance data awaits third-party verification, but the API signals a meaningful shift from AI as a content generator to AI as a real-time decision maker.
What Is the Decisions API
When an application needs to make intelligent judgments in an extremely short window of time — routing a request, classifying an image, or determining an agent's next action — conventional large model inference is often too slow. The Decisions API, showcased in OpenAI's latest demo, is a lightweight decision-making interface designed precisely for these scenarios.
According to the demonstration, the Decisions API runs on a model called GPT-6 Luna. The core idea is to have the model focus on just a small set of candidate options, boosting response speed by nearly ten times. The usage pattern is straightforward: developers pass in a piece of text or an image, define a question along with a set of possible answers, and the model returns the selected result in a fraction of a second.
This "constrained output" design doesn't aim for open-ended generation. Instead, it treats the model as a high-speed classifier and decision engine. It retains capabilities such as image understanding, multilingual support, and safety guardrails, making it well-suited for embedding into latency-sensitive interaction pipelines.
"Constrained output" is not an entirely new concept in the large model space. Its technical roots trace back to Constrained Decoding and Structured Generation. Traditional autoregressive language models perform softmax sampling over the entire vocabulary — typically tens of thousands to hundreds of thousands of tokens — during each generation step, with computational overhead scaling linearly with vocabulary size. When the output space is limited to a few discrete options, the model can skip the vast majority of unnecessary candidates and simply compare the logits of the specified options, dramatically reducing the compute and memory bandwidth required per inference pass. This is analogous to converting an open-ended essay question into a multiple-choice question — the model still needs to understand semantics, but the cost of "answering" drops significantly. Open-source frameworks such as Outlines, Guidance, and LMQL have already implemented similar mechanisms. The Decisions API can be seen as OpenAI productizing this approach and specifically optimizing it for low-latency scenarios.
Text Scenarios: From Unstructured Content to Automated Routing
The most basic use case shown in the demo is extracting form fields from long, unstructured text. But the real value lies in automated routing — for example, categorizing support tickets for dispatch, or precisely routing inbound sales leads to the right team.
The demo showed multiple pieces of free-form user input being rapidly classified as sales leads — and reportedly without any additional acceleration applied, with server-side response times under 100 milliseconds. For businesses that need to process massive text streams in real time, this latency level means AI decision-making can be placed directly in the main flow without worrying about degrading the overall user experience.
Visual Scenarios: Decisions Driven by Real-Time Imagery
The more surprising capability of the Decisions API lies in image input. The demo illustrated this with a small game: the API captured real-time footage of a road with obstacles and quickly determined whether a car should stay in its current lane or shift left or right. Even at higher speeds, it consistently guided the car into the correct lane — in a fraction of the time a traditional inference model would take.
This capability naturally points toward basic "computer use" tasks — capturing a screen and quickly returning an action command. The presenters acknowledged that for highly complex computer or browser operations, dedicated Astra capabilities would still be needed. The Decisions API is better suited for scenarios with a limited set of options requiring frequent, rapid judgments.
Using visual models for real-time control decisions faces two critical engineering bottlenecks: image encoding latency and inference throughput. Mainstream vision-language models (VLMs) typically first encode an image into high-dimensional feature vectors using a visual encoder (such as the ViT family), then pass them to the language model component for interpretation. End-to-end latency for this entire pipeline often ranges from hundreds of milliseconds to several seconds, making it ill-suited for real-time control. The Decisions API's claimed latency of "a fraction of a traditional inference model" suggests it likely applies specialized optimizations to the visual encoding path as well — for example, reducing image resolution, using a smaller visual backbone, or skipping per-token generation entirely in favor of directly outputting candidate scores for classification tasks. This aligns closely with the "lightweight perception head + heavyweight planning model" division of labor commonly used in industrial applications like autonomous driving perception and robotic grasping — using fast, specialized modules for high-frequency perceptual decisions while offloading complex reasoning to slower but more capable models running offline or at lower frequency.
Multimodal Combinations with Voice and Robotics
The demo combined the Decisions API with voice modality, using GPT Live 1 to handle voice conversation while the Decisions API determined in real time which facial expression an animated character should display during the dialogue. The character selects from a set of preset expressions, allowing subtle reactions to blend naturally into the conversation's rhythm.
Even more interesting was the robotics demo. Using a soon-to-be-released MicroDuck prototype (nicknamed Lavender) provided by Hugging Face, the team used GPT Live for voice intelligence and the Decisions API to determine the robot's head orientation based on camera feed.
The decision options were simple — turn head left or turn head right. Frames from the camera were fed to the Decisions API every few frames; it identified which object was the "apple" and directed the robot to look toward the target.
MicroDuck is one of Hugging Face's low-cost, open-source robot projects aimed at developers, positioned as a programmable and accessible physical AI experimentation platform. Hugging Face has been investing heavily in Embodied AI in recent years; its LeRobot project has already open-sourced training frameworks and datasets for multiple robotic arms and mobile robots, with the goal of enabling researchers to reproduce robotic manipulation experiments using consumer-grade hardware. Pairing a low-latency decision layer like the Decisions API with physical robots fills the gap between "large models being too slow" and "traditional control algorithms being too rigid" — semantic understanding goes to the language model, high-frequency action decisions go to the constrained output interface, and low-level motor control remains with the embedded system. This forms a three-layer division of labor that closely aligns in philosophy with the "Fast-Slow Systems" robot control framework gaining traction in recent academic literature.
Conceptual Understanding and Ambiguous Instructions
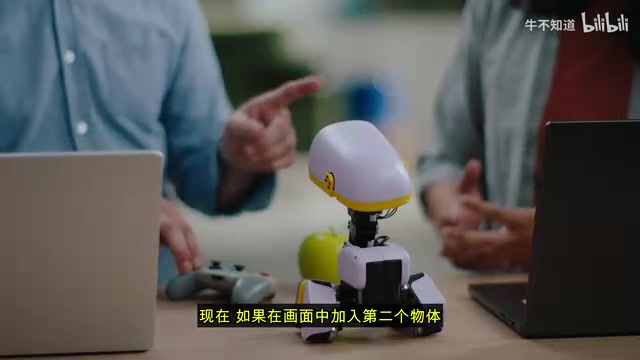
What truly demonstrates the model's comprehension is its handling of ambiguous instructions. When the operator said "keep an eye on the fruit," Lavender understood the concept and tracked the corresponding object. When an apple and a game controller both appeared on camera and the question was "which one is more fun?", the robot looked at the controller — because it is obviously "more fun." Even when the objects were swapped in position, it made the same consistent judgment and continued tracking accordingly.
This shows that the Decisions API is not doing simple pixel matching, but rather weighing options with commonsense reasoning and semantic understanding. For scenarios that require "lightweight judgment + real-time response" — such as robots, interactive toys, and assistive devices — this capability opens up considerable possibilities.
A Note of Measured Caution
The Decisions API has a clear positioning: trade constrained output for speed, turning large models into high-speed decision engines that can be embedded directly in the main application flow. It supports both text and visual input and can integrate with voice interaction, covering use cases from ticket routing to robot control.
That said, it's worth noting that the above content comes from a single demo source. Model names such as GPT-6 Luna and the performance figures cited have not been independently verified by third parties, and real-world latency, accuracy, and behavior in complex scenarios remain to be seen. For developers, what's truly worth watching is the product philosophy this "low-latency decision API" represents — shifting AI from "generating content" to "directly making decisions." That shift could give rise to an entirely new generation of real-time interactive applications.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.