OpenAI Responds to 6.1 Sol Load Issues: Performance Optimized for Its Fastest-Growing Model

OpenAI says 6.1 Sol's rapid growth slowed responses; optimizations are now complete.
OpenAI announced via an official tweet that 6.1 Sol is its fastest-growing model ever, and the load pressure from surging users after launch caused slower response times. The team has now completed optimizations, with performance "should be much better." The article notes this is a capacity bottleneck at the service engineering level, not a defect in model inference capabilities. LLM inference costs far exceed traditional web services, and unpredictable request patterns during new model launches make capacity planning extremely difficult. OpenAI's lightweight tweet communication suggests the issue is nearing resolution while signaling market acceptance beyond expectations.
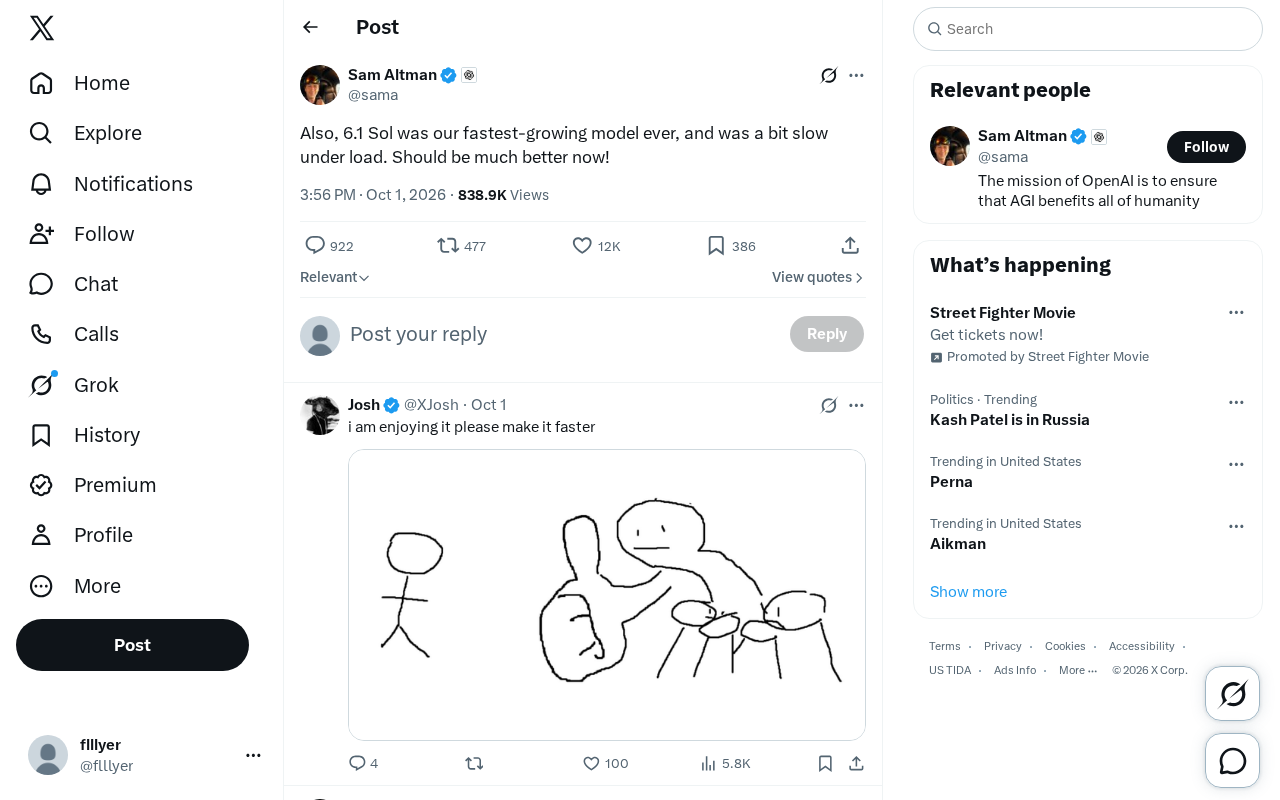
OpenAI posted a brief but informative update via its official Twitter account: its 6.1 Sol model experienced the fastest user growth in the company's history after launch, and the resulting load pressure caused a decline in response speed. The team has now completed optimizations, and model performance "should be much better."
This tweet did not come with a technical blog post or detailed explanation — it's a typical stability notice from a product team to users after a peak period.
The Sweet Burden of Growing Too Fast
6.1 Sol has been called "the fastest-growing model ever" by OpenAI, and that phrasing itself is worth unpacking. It means that call volume, new user counts, or API request frequency in the early days after launch surpassed the comparable performance of any previous model generation.
Fast growth is a good thing, but online inference services have physical limits — GPU cluster scaling, request queue scheduling strategies, cache hit rates, and other components all take time to refine. When traffic floods in faster than expected, the most direct symptoms are rising latency, higher timeout rates, and some users perceiving the model as "slower" or even occasionally unavailable.
OpenAI's use of "under load" suggests the problem is not a defect in the model's inference capabilities, but rather a capacity bottleneck at the service engineering level.
The difference between online inference and training is a prerequisite for understanding this type of load issue. Training refers to repeatedly iterating model parameters with large-scale data — it's an offline, long-cycle task. Inference, on the other hand, is the forward computation process that responds to each user request after the model goes live — it's a real-time, high-concurrency online task. The resource characteristics of the two are entirely different: training can tolerate longer queuing and fault tolerance, while inference is extremely sensitive to latency. The pressure facing 6.1 Sol occurred on the inference side — a surge in users means a sharp increase in requests per second (QPS), and each request consumes GPU memory to complete its computation.
Batching and the throughput-latency tradeoff is at the core of inference service tuning. GPUs excel at parallel computing, so the server side packs multiple requests into a batch for processing together, improving hardware utilization and reducing costs. But the larger the batch, the longer each individual request waits to be grouped, and time-to-first-token rises accordingly. Engineering teams must therefore find a balance between throughput (how many requests can be processed per unit time) and latency (how quickly a single request returns). When traffic surges and request distribution shifts abruptly, a previously well-tuned batching strategy may become unbalanced — this is one of the typical mechanisms behind slower responses under high load.
Why Load Issues Are So Common in AI Products
This is not the first time OpenAI has faced stability challenges from growth. From ChatGPT's frequent "at capacity" messages in its early days to rate-limiting measures during subsequent rounds of model iteration, the tension between rapid growth and stable service is a shared challenge for virtually all leading AI products.
Inference costs for large language models are far higher than traditional web services. Each conversational request may trigger computations involving billions of parameters — large memory footprint, narrow batching windows, complex GPU scheduling — these characteristics mean that simply adding more servers doesn't always solve the problem linearly. Service teams must continuously balance throughput, latency, and cost.
Another easily overlooked factor is user behavior patterns. When a new model launches, large numbers of users concentrate on testing new features or integrating it into production environments, resulting in highly unpredictable request patterns. This "stress-test-style" usage behavior is precisely the hardest to plan capacity for.
The economics of inference costs deserve separate discussion. The computation per request for a large language model is on a completely different scale from traditional web APIs: a medium-sized model performs billions of multiply-add operations for each token generated, and a few-hundred-word response may correspond to hundreds of millions of parameter reads, with memory bandwidth and GPU utilization becoming bottlenecks. This has two consequences: first, scaling costs are high — adding GPUs is not as cheap as adding ordinary servers; second, scaling speed is constrained by hardware supply chains and cluster deployment cycles, making it impossible to complete on the same day traffic spikes.
Caching and prompt reuse are key methods for alleviating load. Since many requests contain identical system prompts or prefixes, the server side can reuse already-computed portions through KV cache, significantly reducing redundant computation. The higher the cache hit rate, the more requests the same hardware can handle. When a new model launches and user input patterns are fragmented, cache hit rates tend to decline, further amplifying load pressure. This explains why a cluster of the same size appears strained during a new model's early days.
"Should Be Much Better Now": What Users Should Expect
"Should be much better now" is a typical engineering optimistic phrasing — it conveys confidence that the fix is complete while leaving room for caveats.
For developers currently using 6.1 Sol, if you previously experienced response delays or timeouts, you can now re-test the performance of critical paths. For new users preparing to integrate, the current period may be a relatively stable window.
However, given 6.1 Sol's growth rate, the possibility of capacity strain recurring in the future still exists. It's advisable for production systems that depend on this model to prepare degradation plans — such as configuring backup models, setting reasonable timeout and retry strategies, and using lighter models for non-critical paths.
OpenAI's Strategy as Seen Through Product Rhythm
It's worth noting that OpenAI chose to communicate this information through a brief tweet rather than a formal announcement. This approach is generally viewed in the developer community as a "lightweight ops communication" — indicating that the team internally believes the problem has been or is close to being resolved, and doesn't require extensive explanation.
At the same time, emphasizing "fastest-growing model ever" also carries a product-level signal: 6.1 Sol's market acceptance has exceeded expectations, which is a positive reference for OpenAI's subsequent resource allocation and roadmap planning. Growth itself is not the problem — how to make service capacity keep up with growth is.
For practitioners focused on AI infrastructure, the value of this tweet lies in reaffirming a pattern — beyond competition in model capabilities, inference service engineering is becoming a key dividing line in AI product experience. Whoever can maintain stability under high load faster will gain an advantage in user retention.
OpenAI's current answer is: the problem has been identified, and the fix is live. What remains to be seen is whether actual performance matches that "much better."
One-line Summary
OpenAI says 6.1 Sol's rapid growth slowed responses; optimizations are now complete.
Paragraph Summary
OpenAI announced via an official tweet that 6.1 Sol is its fastest-growing model ever, and the load pressure from surging users after launch caused slower response times. The team has now completed optimizations, with performance "should be much better." The article notes this is a capacity bottleneck at the service engineering level, not a defect in model inference capabilities. LLM inference costs far exceed traditional web services — large memory footprint, complex batching and GPU scheduling — and the concentrated testing by users at launch creates unpredictable request patterns, making capacity planning extremely difficult. OpenAI's choice of lightweight tweet communication suggests the issue is nearing resolution while signaling market acceptance beyond expectations. For developers, it's advisable to prepare degradation plans for production systems relying on this model.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.