OpenAI's First AI Chip Jalapeño Named a TIME Invention of the Year

OpenAI's first AI acceleration chip Jalapeño was named a TIME Invention of the Year, signaling full-stack vertical integration.
OpenAI VP of Hardware Richard Ho announced that the company's first AI acceleration chip, Jalapeño, was named to TIME's Best Inventions of 2026. The official emphasis on full-stack innovation "from model to silicon" marks the model-first company's extension toward the compute foundation. The article argues this signals vertical integration, but with no process, compute, or power specs disclosed, it is better read as strategic positioning than performance disruption. The trend of model companies and cloud providers building custom accelerators stems from cost structure, supply chain resilience, and software-hardware co-design. Whether the efficiency narrative materializes depends on software stack maturity and ecosystem adaptation; list inclusion is not third-party validation. If deployed at scale, it could affect OpenAI's inference costs and API pricing and reshape upstream chip order structures.
OpenAI's First AI Chip Jalapeño Named a TIME Invention of the Year
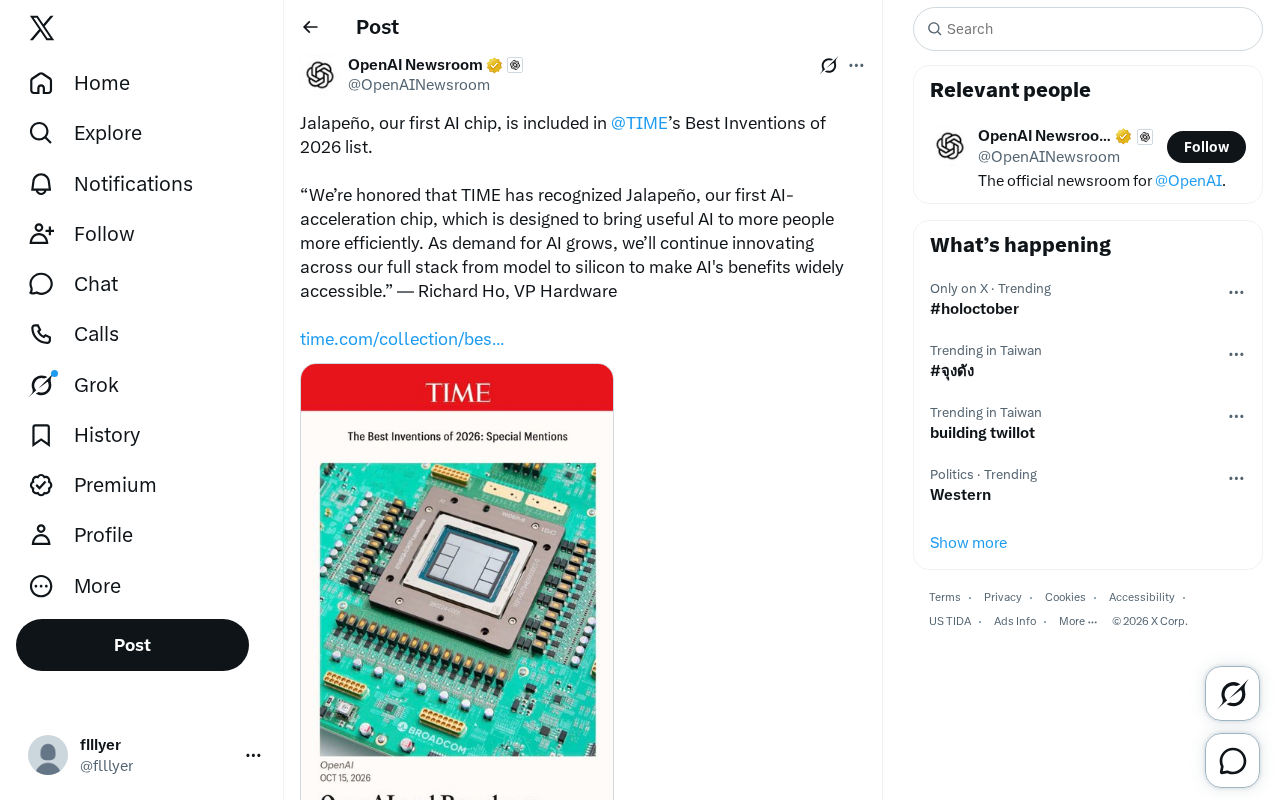
OpenAI VP of Hardware Richard Ho announced on social media that the company's first AI acceleration chip, Jalapeño, has been named to TIME's Best Inventions of 2026 list. The message itself is brief, but against the backdrop of today's AI compute competition, the signal it sends is anything but simple: a company built on models is now reaching into the silicon layer.
From Model to Chip: The Signal of OpenAI's Vertical Integration
In his statement, Richard Ho said: "We're honored that TIME has recognized Jalapeño—our first AI acceleration chip, designed to bring useful AI to more people more efficiently. As AI demand grows, we'll continue to innovate across the full stack from model to silicon, so the benefits of AI are broadly accessible."
The key phrase here is "full stack from model to silicon." Over the past few years, OpenAI's core assets have centered on the model training and inference algorithm layer, with hardware sourced from external vendors. Jalapeño's arrival means it is beginning to extend toward the compute foundation. The direct benefit of vertical integration is software-hardware co-optimization—the model team can tailor work to its own chip's instruction set and memory hierarchy, cutting the redundant overhead of general-purpose GPUs.
It should be noted that the official disclosure is very limited: no process node, compute specs, power figures, or deployment scale were revealed. So the more reasonable reading at this stage is "strategic positioning" rather than "performance disruption." TIME's inventions list leans toward product-innovation narratives; inclusion itself is brand and industry recognition, not a third-party benchmark conclusion on technical metrics.
Vertical Integration in the semiconductor industry refers to a single company controlling multiple stages from design and manufacturing to the software ecosystem. Apple is a classic example: it designs its own A/M-series chips and deeply optimizes them alongside its own operating system, gaining an edge in performance-per-watt. For OpenAI, vertical integration means it can account for the target chip's instruction set, on-chip cache size, and data movement paths at the model architecture design stage, bringing optimization space that once depended on general-purpose GPU compilers (like CUDA) back in-house. This approach is known in the industry as "co-design"; Google's pairing of TPU with its own Transformer models is an earlier industry precedent. However, vertical integration also means massive R&D investment and long-term ecosystem building, and it will be hard-pressed to replace the mature GPU supply chain in the short term.
Why Companies Beyond Chip Vendors Are Building Chips
The player structure in the AI chip race is changing. Beyond traditional GPU vendors like NVIDIA and AMD, cloud service providers and model companies are all pushing custom accelerators. The underlying logic of this trend has three parts:
- Cost structure: Compute procurement accounts for a very high share of the marginal cost of large-scale inference. Custom chips can compress per-token costs on specific workloads.
- Supply chain resilience: Dependence on a single supplier concentrates risk when capacity is tight; custom chips provide an alternative path.
- Software-hardware co-design: Model architecture and chip design iterate in sync, giving finer-grained control over operator fusion and quantization strategies.
Jalapeño is described as an "AI-acceleration chip" rather than a general-purpose processor, indicating it targets inference or training acceleration rather than replacing CPUs. This aligns with the industry's division of labor between "dedicated accelerators + general-purpose computing."
The difference between AI accelerators and general-purpose GPUs is worth clarifying. General-purpose GPUs must handle graphics rendering, scientific computing, and many other workloads, retaining a great deal of hardware flexibility; AI accelerators (such as Google TPU and AWS Trainium) typically design dedicated circuits for specific operators like matrix multiplication and attention mechanisms, trading generality for higher throughput per unit of power. Such chips often adopt architectures like systolic arrays to maximize data reuse and reduce memory-access bottlenecks. The cost is a more closed programming model, requiring dedicated compilers to map model graphs onto the hardware. So the very phrase "AI-acceleration chip" implies Jalapeño takes the dedicated route, and its success depends heavily on whether the accompanying software stack lets mainstream frameworks (PyTorch, etc.) plug in smoothly.
The Real Constraints Behind the Efficiency Narrative
"Bringing AI to more people more efficiently" is the official core selling point. Efficiency can be understood along two dimensions: energy consumption per unit of compute, and throughput per unit of cost. But between a chip's launch and large-scale deployment lie manufacturing yields, software stack maturity, developer ecosystem adaptation, and more.
Historical experience shows that the biggest barrier for a new accelerator is often not the hardware itself but compiler and framework support. If the model team and chip team belong to the same company, internal friction at this step is lower, but how open it will be to external developers remains unknown.
Also, inclusion on the TIME list helps with recruiting and capital-market narratives, but it does not constitute technical validation. Assessing Jalapeño's true level will require independent benchmarks or real deployment data.
The software stack and compiler ecosystem is the most easily underestimated barrier when a new accelerator lands. NVIDIA's moat is not just the chip itself but the CUDA ecosystem built over more than a decade: mature operator libraries, debugging tools, and the developer community that grew up around it. Even if a new chip has impressive peak compute, without an efficient graph compiler, full operator coverage, or seamless integration with mainstream training frameworks, real-world throughput can fall far below theoretical values. The common industry practice is to first let internal teams refine the software stack on their own workloads before gradually opening it up. If OpenAI's model and chip teams share the same origin, internal adaptation friction will be smaller, but whether external developers get an equivalent experience depends on its willingness to invest in documentation, SDKs, and community support—work that outsiders often overlook.
Potential Impact on the Industry Landscape
If Jalapeño ships as the official narrative suggests, the most direct change is stronger bargaining power for OpenAI on inference costs, which in turn affects API pricing strategy. For upstream chip suppliers, top customers' leanings toward custom silicon will reshape order structures; for smaller model companies, it means another variable in the competitive landscape for compute access.
Longer term, the coupling of models and chips could spawn new optimization paradigms—for example, sparse compute units customized for specific model structures. Such explorations are already discussed in academia, while large-scale validation in industry is just beginning.
At present, the only public information about Jalapeño is the executive statement and the list inclusion; specs, timelines, and business model are all undisclosed. What's worth watching next: whether it will be opened externally, whether there will be third-party benchmarks, and what share of OpenAI's internal workloads it actually handles.
One-line Summary
OpenAI's first AI acceleration chip Jalapeño was named a TIME Invention of the Year, signaling full-stack vertical integration.
Paragraph Summary
OpenAI VP of Hardware Richard Ho announced that the company's first AI acceleration chip, Jalapeño, was named to TIME's Best Inventions of 2026 list. The official emphasis on "from model to silicon" full-stack innovation marks the model-first company's extension toward the compute foundation. The article argues this signals vertical integration, but with no disclosed process, compute, or power figures, it is better read as strategic positioning than performance disruption. The trend of model companies and cloud providers building custom accelerators stems from three logics: cost structure, supply chain resilience, and software-hardware co-design. Whether the efficiency narrative materializes depends on software stack maturity and ecosystem adaptation; list inclusion is not third-party validation of technical metrics. If deployed at scale, it could affect OpenAI's inference costs and API pricing and reshape upstream chip order structures.
Related articles

Cursor Can Now Control Your Computer: AI Agents Can Drive Desktop Apps for Testing
Cursor adds desktop control: AI agents can drive desktop apps like the iOS Simulator to test their own features. We analyze the impact on dev workflows, possible technical approaches, and reliability concerns.

Vibecoding a Custom Inference Engine: High Hopes, Harsh Reality
A Reddit developer shares the real experience of vibecoding a custom inference engine: running GGUF Q4 models in the browser with WebGL2 and GLSL, only to fall into tokenizer debugging hell. This article analyzes the engineering challenges of browser-side LLM inference and why cloning llama.cpp is the more rational choice.

How High Are Anthropic's Early Investor Paper Returns Ahead of IPO?
Anthropic's early investor paper returns draw attention ahead of IPO. This article analyzes sources of book gains, capital structure, pre-IPO games and risks, and implications for the AI startup ecosystem.