Pelican Test in Practice: Comparing DeepSeek Harness Across Different Modes

The Pelican Test benchmarks DeepSeek Harness across three modes to reveal reasoning capability boundaries.
The "Pelican Test" evaluates large language models by asking them to generate code that draws a pelican riding a bicycle, testing spatial reasoning and drawing logic. Running DeepSeek Harness across three configurations — Minimal Mode + Max, Standard Mode + Max, and Standard Mode + short reasoning — Minimal Mode + Max delivered the strongest output quality, Standard Mode + Max was faster but slightly weaker on details, and the short reasoning combo prioritized efficiency at the cost of proportional accuracy. Across all modes, spatial contact between the pelican and bicycle remained consistently imprecise, highlighting fine-grained spatial reasoning as a persistent weak point. Disabling web search is also recommended for clean capability benchmarking.
What Is the Pelican Test
A benchmark known as the "Pelican Test" has been making the rounds in the AI community. It originated from an experiment proposed by a researcher: ask a large language model to generate code that draws an image of a pelican riding a bicycle, as a practical way to evaluate the model's spatial understanding, drawing logic, and reasoning ability. Because both a pelican's body structure and a bicycle's mechanical components are relatively complex, models tend to stumble on the details — making this deceptively simple task a fun and revealing gauge of a model's overall capabilities.
For this hands-on test, I tracked down the original source of the benchmark, including the prompt and evaluation records used by its creator, then ran it through DeepSeekAd Harness with a focus on comparing output differences across different operating modes.
At its core, the Pelican Test is a compound benchmark combining code generation and visual reasoning: the model must use a programming language (typically Python with libraries like matplotlib, turtle, or SVG) to translate an abstract visual concept into executable coordinates and path instructions. This requires three simultaneous capabilities — biological knowledge of a pelican's body structure, spatial-topological understanding of a bicycle's mechanical parts (frame, wheels, pedals, handlebars, etc.), and the ability to calculate proportions and contact relationships when combining the two. Since every coordinate value in the drawing code must remain consistent within a global coordinate system, any local spatial misjudgment shows up directly in the final image. This makes it harder to "fake" than a pure text reasoning problem, and more reflective of a language model's own reasoning depth than simply calling a text-to-image model.
Minimal Mode: Unlocking the Strongest Reasoning
The first round used Minimal Mode. Based on community experience, pairing DeepSeek's Minimal Mode with Max tends to unlock the model's strongest reasoning capabilities, while other mode combinations are comparatively more conservative. The prompt itself was very concise — a generic type with minimal scaffolding.
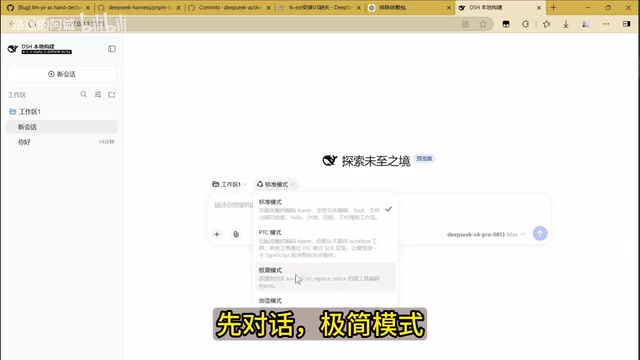
One noteworthy detail during the run: whether or not search is disabled affects the model's behavior. If you don't explicitly turn off search, the model may invoke a web browsing tool to look up relevant content. You can actually observe from the tool-call logs whether search was triggered — which is an important signal for determining whether the output is pure reasoning or mixed with external information.
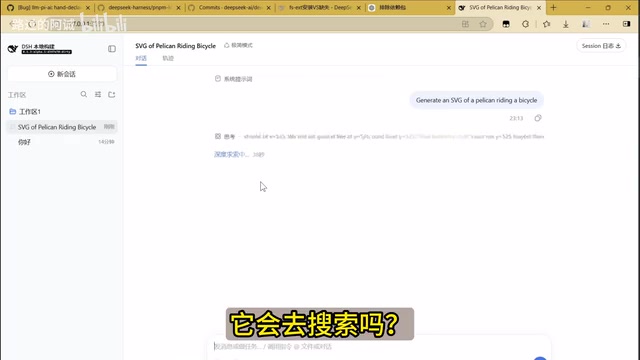
The first result was a bit rough around the edges — the code placed certain elements in positions that didn't quite make sense. For instance, some components that should have been drawn within the target structure ended up somewhere else. The code ran successfully overall, but the detail handling wasn't exactly polished.
The key difference between "Minimal Mode" and "Standard Mode" in DeepSeek Harness lies in the complexity of the system prompt and the level of constraints placed on model behavior. Minimal Mode strips away most formatting instructions and safety-rail prompts, letting the model engage more directly with user input — theoretically reducing mid-layer interference with the reasoning chain. "Max" typically refers to the upper limit on chain-of-thought reasoning budget, allowing the model to perform longer, more multi-step internal inference before generating output. Together, these two settings mean the model faces fewer formatting constraints while having ample "thinking space" — which tends to produce stronger results on tasks requiring multi-step spatial reasoning. The trade-off is longer response latency and higher token consumption.
Standard Mode + Max: A Side-by-Side Comparison
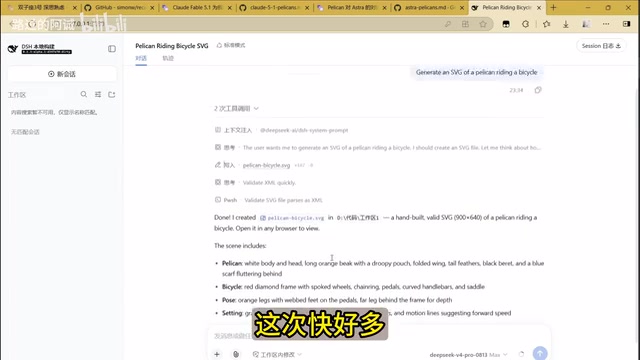
To create a direct comparison, I started a new conversation, switched to Standard Mode with Max, and ran the test again. Generation speed was noticeably faster this time — likely because the model planned the main structure in one pass at the start, resulting in smoother output throughout.

Looking at the results, the pelican drawn in Standard Mode showed clear differences in the wheels and auxiliary components compared to Minimal Mode. However, the familiar problem persisted: the pelican's "hands" couldn't quite reach the handlebars, and the spatial relationship between the limbs and the bicycle wasn't fully aligned. This type of issue is nearly universal across all models when handling complex mechanical structures, reflecting the inherent limitations of current models in fine-grained spatial reasoning.
Standard Mode + Short/Medium Reasoning
The third configuration used Standard Mode with a short-to-medium reasoning setting. Compared to the previous two rounds, this combination uses a shorter reasoning chain — theoretically trading some detail quality for efficiency.
The test results confirmed this: the generated image showed a "stubby arms" problem, with disproportionate pelican limbs and an overall aesthetic that could only be described as mediocre. That said, it wasn't terrible — the basic form was intact, just lacking the detail and visual quality of the Minimal Mode + Max combination.
Key Observations and Conclusions
Looking at all three rounds together, a few clear takeaways emerge:
- Mode selection directly impacts output quality: Minimal Mode + Max tends to release the model's full reasoning potential, while the short/medium reasoning mode prioritizes efficiency.
- The search toggle is a variable: Whether web access is enabled changes the model's processing path. For pure capability benchmarking, it's recommended to disable search to avoid results being influenced by external information.
- Complex spatial relationships remain a challenge: Regardless of mode, details like limb contact between the pelican and the bicycle, and wheel structure, were prone to errors across all configurations — indicating this type of task is still genuinely challenging for current models.
The value of the Pelican Test lies not in producing an absolute ranking, but in using a unified, engaging task to visibly expose the capability boundaries between different models and different runtime configurations. For users looking to evaluate the real-world performance of DeepSeek or other large language models, it offers a low-cost, reproducible reference method.
It's worth noting that this test is based on single-run subjective observations with a limited sample size, and the results should be taken as reference only. More rigorous conclusions would require multiple repeated runs and more objective scoring criteria.
Related articles

Felix Rieseberg Personal Homepage
Felix Rieseberg's personal homepage sparks attention on Hacker News. This article covers the Slack engineer's technical background, the rise and fall of nativefier, and the value of a developer homepage as a tech calling card.

@ai-sdk/vue 3.0.306 Patch Release Syncs with [email protected] Update
@ai-sdk/vue 3.0.306 released, synced with [email protected]. A routine patch release for the Vercel AI SDK ecosystem with no public API changes; the Vue adapter layer stays version-aligned with the core package.

Gemini 4 Argon API Launches: The Era of Million-Token Output Begins
Google launches Gemini 4 Argon with sparse MoE architecture, up to 1M output tokens, and a 68.90% Vals Index score, available across API, AI Studio, and the Gemini app.