Pretraining from Scratch on an Inference-Only NPU: VKORE-46M-NPU Achieves Backpropagation

VIDRAFT ran backpropagation on an inference-only NPU, training a 46M model from scratch with a 0.99 loss-curve correlation to GPU.
VIDRAFT broke the assumption that inference NPUs can't train by completing full backpropagation on a first-generation inference-only NPU with 32 chips, pretraining the 46M-parameter VKORE-46M-NPU from scratch. Under identical conditions, NPU and GPU loss curves reached a 0.99 correlation coefficient, proving numerical equivalence to GPU training. The same NPU stack covers LoRA fine-tuning, inference acceleration, and quantized execution, and is being integrated into a CUDA-like VKORE software layer. The model is on Hugging Face, but the core training technique is patent-pending and not open-sourced.
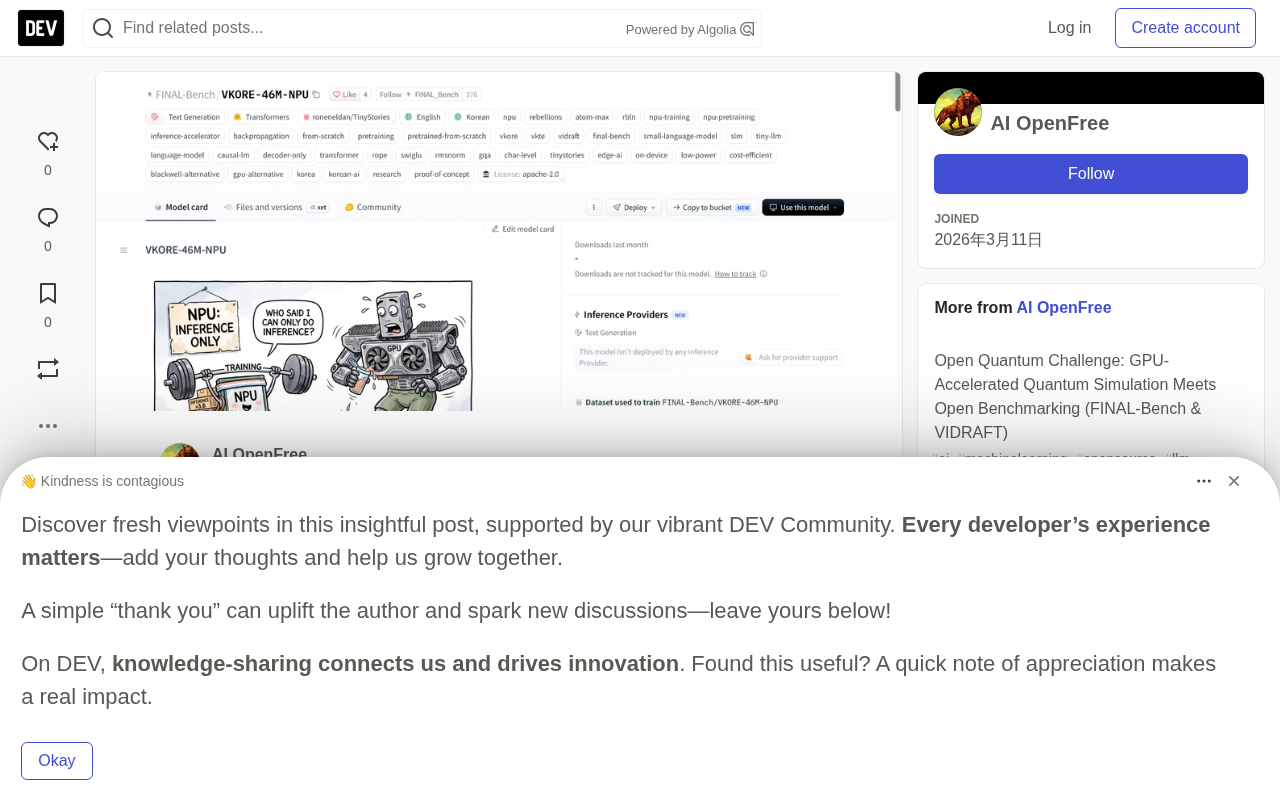
Inference-only NPUs are typically assumed to be capable of forward computation only—static graphs, low precision, fixed weights—and the computation graphs, gradient synchronization, and optimizer states required for training simply don't exist in their software stacks. VIDRAFT has broken this default assumption with real work: they completed full backpropagation on an inference-only NPU, pretrained a language model from scratch, and released the result as VKORE-46M-NPU.
Why training on an inference NPU is so difficult
Inference NPUs are designed to align completely with the forward path: static computation graphs, low-precision arithmetic, and weights fixed as constants in hardware. Training, by contrast, requires an almost opposite set of capabilities—a backward graph with saved activations, optimizer state management, numerical stability under small gradients, and gradient synchronization across multiple chips. These paths typically don't exist in inference software stacks.
For this reason, "NPUs can't do backpropagation, therefore they can't train" has long been treated as the industry's default conclusion. VIDRAFT's work runs backpropagation directly on this class of chip, trains a model from scratch without any pretrained weights, and answers that judgment with engineering implementation.
Backpropagation is the core algorithm for training neural networks. Its essence is the reverse application of the chain rule over a computation graph: during forward propagation, intermediate activations are computed and saved layer by layer; during backward propagation, starting from the loss function, the gradient of the loss with respect to each parameter is computed layer by layer, then handed to the optimizer to update the weights. Unlike inference, which requires only a single forward pass, training requires saving activations from the entire forward process, constructing a backward computation graph, and maintaining optimizer states such as momentum and variance—memory/on-chip storage usage is typically several times that of inference.
Low-precision training further amplifies the difficulty. The FP16, INT8, or even INT4 commonly used for inference are sufficient, but gradients during backpropagation are often extremely small and prone to underflow or being drowned out by rounding noise at low precision, preventing parameters from updating effectively. Low-precision training therefore typically requires techniques such as loss scaling, FP32 master weight copies, or stochastic rounding to maintain numerical stability. Inference NPU software stacks usually don't provide these mechanisms—this is precisely the technical root of the judgment that "NPUs can't do backpropagation."
Core evidence: the same model, two kinds of hardware
The most compelling part of this work lies in its experimental design. Under completely identical initialization, data, and learning rate schedules, the research team trained the same model from scratch on both a 32-chip NPU and a GPU.
- The correlation coefficient of the two loss curves reached 0.99
- Throughput (tokens per second) converged to comparable levels
A single descending loss curve by itself proves nothing. If the low-precision kernels were corrupting gradients, the curve would gradually diverge from the GPU reference run. Achieving a 0.99 correlation coefficient with the GPU reference under identical conditions is strong evidence that backpropagation and optimizer updates are numerically doing the same work as the reference implementation. In other words, this isn't "looks like it's training"—it's "numerically equivalent to GPU training."
This is also the core fact repeatedly confirmed across multiple sources: the training path on the NPU works in the mathematical sense.
The Pearson correlation coefficient is a metric that measures the degree of linear correlation between two curves, ranging from -1 to 1, where 1 indicates perfect positive correlation. In training comparison experiments, it is used to quantify how closely the shapes of the NPU and GPU loss curves match.
Choosing the correlation coefficient rather than simply comparing final loss values is because it captures dynamic consistency across the entire training process. If the low-precision kernels systematically damaged gradients at some stage, the loss curve would diverge at that stage and the correlation coefficient would drop accordingly. A value of 0.99 means the two curves descend and converge almost in sync, indicating that every parameter update on the NPU matches the GPU reference closely in both direction and magnitude. This is stronger proof of the numerical validity of the training process than a single endpoint metric.
Old chips work; new chips have even more room
This training ran on a first-generation inference-only NPU released in 2025, using 32 chips—not the latest hardware. The fact that an older-generation chip can complete pretraining from scratch means there is clear headroom for improvement in compute, precision, and interconnect bandwidth on newer-generation NPUs.
For hardware vendors and model teams, this signal is more valuable than "new chips can do it"—it shows that training capability doesn't depend on the latest process node or dedicated training units, but is an engineering problem at the software stack level.
A single NPU covering the full pipeline
VIDRAFT's work doesn't stop at pretraining. The same NPU solution already covers multiple stages of the model lifecycle:
- Pretraining from scratch
- LoRA fine-tuning
- Inference acceleration (also validated on general open-source models)
- Quantized model execution and acceleration
The company is integrating these capabilities into an NPU software layer called VKORE. Its positioning is similar to the ecosystem advantage Nvidia built through CUDA—not relying on a single GPU's hardware, but reducing dependence on specific GPUs and their software ecosystems through a general acceleration layer. VIDRAFT describes it as "CUDA for NPUs."
The deeper logic of this strategy: hardware replaceability depends on the stickiness of the software stack. If both training and inference can run on the same general NPU software layer, the migration cost for enterprises when choosing hardware will drop significantly.
CUDA (Compute Unified Device Architecture) is a general-purpose parallel computing platform and programming model that Nvidia has built since 2007. Its significance goes far beyond a toolchain: through a unified programming interface, a rich library of operators (cuBLAS, cuDNN), and a mature developer ecosystem, CUDA makes it extremely difficult for developers to migrate to other hardware once they've written code based on it, creating powerful ecosystem lock-in. Much of Nvidia's moat comes from CUDA rather than raw chip performance.
The phrase "CUDA for NPUs" points to the same strategic logic: if there exists a general acceleration layer that lets training, fine-tuning, inference, and quantization all run on the same software stack, then enterprises' dependence on specific hardware (especially Nvidia GPUs) when making selections will decrease, and migration costs will fall accordingly. For latecomers, the generality of the software ecosystem may matter more than single-point hardware performance in determining hardware replaceability.
Why this matters
High-end GPU servers are expensive, have long delivery cycles, and consume a lot of power. A cheaper, low-power NPU that can simultaneously handle training tasks lets enterprises scale models locally on their own—deploying it like installing a desktop device in the office, without waiting for GPU deliveries or sending sensitive data off-site.
The released model was trained on public datasets and can generate short English stories. The core training technique is proprietary, with patents pending, and details will be disclosed in a follow-up paper; the core training code is not open-sourced for the time being due to intellectual property protection.
To be objective, the 46M-parameter model is very small in scale, and its significance lies in validating that the NPU training path is feasible, not in the model's own quality. According to VIDRAFT, scaling to larger models and real data is the next step. A single source notes that the core training technique has not yet been disclosed, meaning independent reproduction is not currently possible.
LoRA (Low-Rank Adaptation) is a parameter-efficient fine-tuning method. It introduces a pair of small low-rank matrices alongside the weight matrices of a pretrained model, updating only these newly added parameters during training while freezing the original weights. Since the number of trainable parameters is typically only one-thousandth to one-hundredth of the original model, LoRA greatly reduces the memory and compute requirements for fine-tuning, while also making it easy to save multiple lightweight adapters for different tasks.
Quantized model execution refers to compressing model weights and/or activations from high-precision formats such as FP16 and FP32 into low-bit representations such as INT8 and INT4, in order to reduce storage usage, improve inference throughput, and lower power consumption, usually at the cost of slight precision loss.
46M parameters is worth understanding within a frame of reference: GPT-2 Small has about 124 million parameters, so 46M is roughly one-third of that, far smaller than current mainstream large models. The significance of this scale is to validate at minimal cost whether "the NPU can complete the full training path," not to pursue model capability. VIDRAFT listing scaling to larger models and real data as the next step is exactly the natural path from feasibility validation toward practicality.
Frequently asked questions
Did backpropagation really run on an inference-only NPU? Yes. Backpropagation ran directly on a chip designed for inference, completing pretraining from scratch.
What does a correlation coefficient of 0.99 mean? The NPU's loss curve almost overlaps with the GPU reference under identical conditions, proving that training is numerically valid.
How large is the model? 46M parameters. The point is to validate that the NPU training path is feasible, not the model quality. Scaling to larger models and real data is the next step.
Where can the model be obtained? It has been released on Hugging Face: FINAL-Bench/VKORE-46M-NPU, including weights, a model card, and comparison data.
One-line Summary
VIDRAFT completed backpropagation on an inference-only NPU and trained a 46M model from scratch whose loss curve correlates with GPU at 0.99.
Paragraph Summary
VIDRAFT broke the industry's default assumption that "inference NPUs can't train" by using 32 chips on a first-generation inference-only NPU to complete full backpropagation and pretrain a 46M-parameter language model, VKORE-46M-NPU, from scratch. The key evidence: under identical initialization, data, and learning rate conditions, the NPU and GPU loss curves reached a correlation coefficient of 0.99, and throughput converged to comparable levels, proving that training is numerically equivalent to the GPU reference rather than merely "looks like it's training." The same NPU solution also covers LoRA fine-tuning, inference acceleration, and quantized execution, and the company is integrating it into a VKORE software layer positioned similarly to CUDA. The model has been released on Hugging Face, but the core training technique is patent-pending and the code is not open-sourced, so independent reproduction is not yet possible.
Related articles

OpenAI Partners with Shield: How the Astra Agent Revolutionizes IT Troubleshooting
OpenAI and Shield launch the Astra agent, which autonomously logs into computers and legacy systems to fix IT issues in real time, 35-40% faster than traditional models, with humans involved only when judgment is needed.

iPhone Duo Battery Life Tested: One Charge a Day Is Unavoidable, and the Large Screen Is the Culprit
iPhone Duo battery test: heavy use needs at least one charge a day, and about 30% remains after 6.5 hours of screen-on time. How often the large screen is unfolded is key; a MagSafe battery pack helps, and long-term degradation is also worth watching.

Kimi K3.1 Pro Open-Sourced: 2.8 Trillion Parameters Close In on Opus
Moonshot releases the open-source MoE model Kimi K3.1 Pro, with 2.8T total parameters and 104B activated, trailing Opus 5.5 by under 1 point on Terminal Bench 4.0.