PrismaCoder: Reshaping Open-Source Multimodal Code Intelligence with Decomposed Rubrics

PrismaCoder uses verifiable rubrics to unify data filtering and RL rewards, breaking multimodal code intelligence bottlenecks.
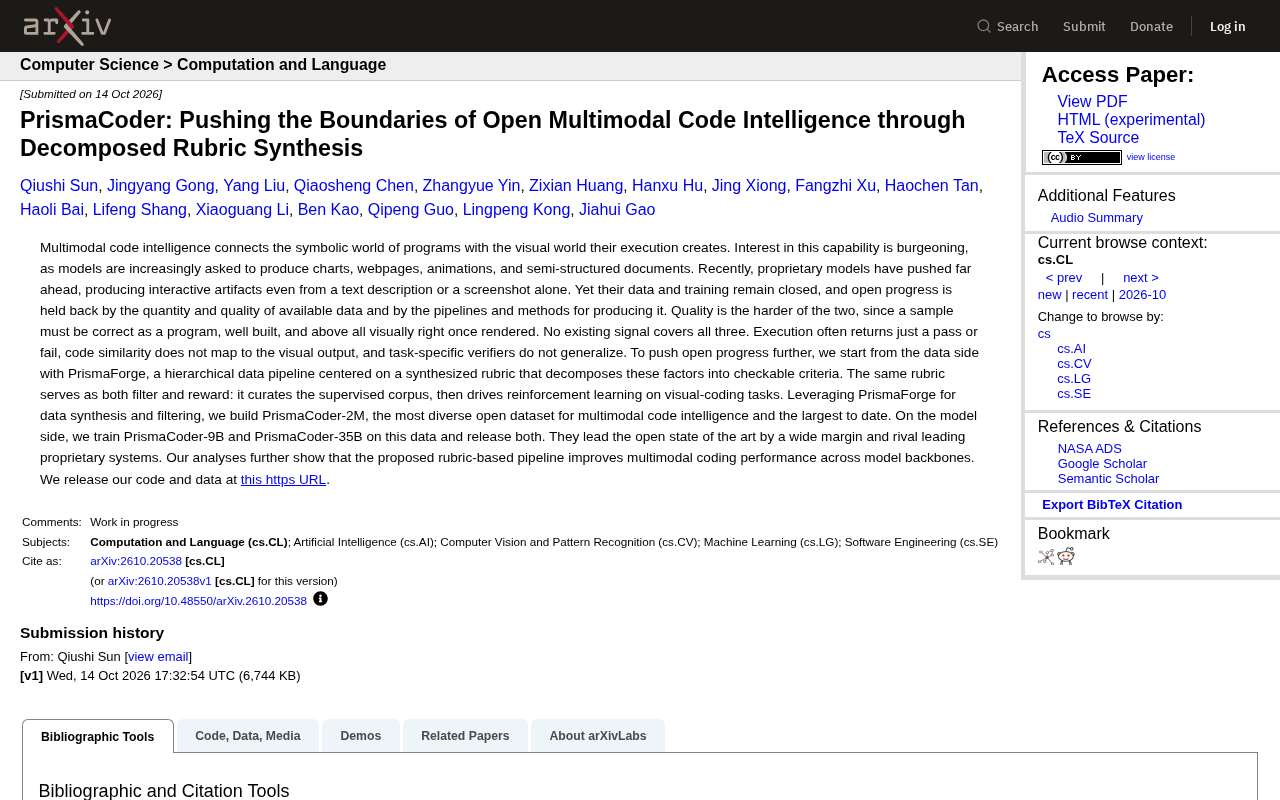
PrismaCoder is an open-source project for multimodal code intelligence that tackles the challenge of models needing to satisfy program correctness, engineering standards, and visual correctness when generating charts, web pages, and other artifacts. The team built PrismaForge, a hierarchical data pipeline centered on synthetic rubrics, decomposing constraints into checkable items used both as data filters and RL reward signals. Based on this, they constructed PrismaCoder-2M, described as the most diverse and largest open-source multimodal code dataset, and trained PrismaCoder-9B and PrismaCoder-35B, claiming substantial leadership over open-source SOTA and competitiveness with leading proprietary systems.
Multimodal code intelligence is emerging as a new battleground for large model competition—it demands that models not only write code, but also make what the code produces visually "correct." Recently, an open-source project called PrismaCoder has attempted to break through this challenge from both the data and methodology ends simultaneously, with a core idea that is quite illuminating: decompose "what constitutes good code" into verifiable rubrics, then use the same set of standards to simultaneously handle data filtering and reinforcement learning rewards.
Why Multimodal Code Intelligence Is Hard
Multimodal code intelligence bridges two worlds: the symbolic world represented by programs, and the visual world created after program execution. When a model is asked to generate charts, web pages, animations, or semi-structured documents, it must simultaneously satisfy three layers of constraints: program correctness, engineering standards, and expected rendering results.
The problem is that none of the existing evaluation signals cover all three. According to the paper, code execution feedback is often just a boolean "pass/fail" with overly coarse granularity; code similarity cannot map to the final visual output; and verifiers trained for specific tasks lack generalization ability. This has left open-source models stuck on this front, bottlenecked by both data quality and production pipelines. Although proprietary models can already generate interactive artifacts from just a text description or a single screenshot, their data and training details are entirely closed-source, making it difficult for the open-source community to catch up.
Supervised Fine-Tuning (SFT) is a foundational step in the large model alignment process, referring to further training a pre-trained model with high-quality task input-output pairs so that it learns to respond in the expected format and style. Unlike reinforcement learning, SFT directly imitates demonstration data, so corpus quality almost determines the model's ceiling: if the demonstration samples themselves have rendering errors or chaotic structures, the model will learn these flaws as well. This is precisely why PrismaForge first uses rubrics to filter the corpus.
Reinforcement Learning (RL) in such tasks typically refers to having the model generate multiple candidate answers to the same question, then strengthening high-scoring outputs and suppressing low-scoring ones based on reward signals. Its success hinges on whether the reward accurately reflects the true objective: poorly designed rewards can induce "reward hacking" behavior—for example, code that passes syntax checks but is completely visually misaligned. PrismaCoder lets rubrics serve simultaneously as rewards, precisely to narrow the gap between reward and true quality.
Verifier here refers to an independent model or program used to judge whether a model's output is acceptable. Task-specific verifiers typically perform well within their training distribution, but quickly fail when switching to another task category (e.g., from charts to web layouts), showing weak generalization. This is also an important motivation for researchers to turn to verifiable rubrics rather than single verifiers.
PrismaForge: Breaking Down "Good or Bad" into Checkable Items
PrismaCoder's starting point is on the data side. The research team built PrismaForge, a hierarchical data pipeline centered on synthetic rubrics. Its key design is to decompose the aforementioned three-layer constraints—program correctness, build quality, and visual correctness—into individually checkable rubric items, rather than relying on a single holistic score.
The cleverness of this rubric system lies in its "dual use." It serves as both a filter for selecting supervised fine-tuning corpora and as a reward signal for driving reinforcement learning on visual coding tasks. The same rubric remains consistent across both stages, avoiding the disconnect between filtering criteria and training objectives in traditional pipelines. The team's analysis shows that this rubric-based pipeline delivers improvements in multimodal coding performance across different model backbones, indicating that its benefits are not tied to any specific architecture.
Rubric originally referred to a detailed scoring table used in education to evaluate assignments across multiple dimensions. In recent years, it has been introduced into the large model field, referring to decomposing vague holistic quality into several independently judgeable items (e.g., "code has no syntax errors," "rendered elements do not overlap," "color contrast meets standards"), each with clear judgment conditions. Compared to a single vague score, rubric items can be checked one by one, pinpoint defects, and are also easy to execute programmatically.
Reward Signal is the numerical feedback in reinforcement learning that guides model updates. It can be either a continuous score or a boolean judgment. The granularity and accuracy of the reward signal directly determine the training direction: a boolean "pass/fail" is simple but cannot distinguish between "almost there" and "completely wrong," leaving the model without direction for improvement. Structured rubrics break a single reward into multiple items, effectively providing the model with finer-grained gradient information.
PrismaCoder-2M and Two Open-Source Models
Using PrismaForge for data synthesis and filtering, the team constructed PrismaCoder-2M. According to the paper, this is currently the most diverse open-source multimodal code intelligence dataset, and also the largest in scale.
At the model level, the team trained and open-sourced PrismaCoder-9B and PrismaCoder-35B on this data. The paper states that both substantially outperform existing open-source state-of-the-art levels and possess the capability to compete with leading proprietary systems. For the open-source camp, which has long been at a disadvantage in data and compute, a meticulously filtered dataset at the two-million scale plus a reproducible training recipe may be worth no less than the model's scores themselves.
The Next Step for Open-Source Multimodal Coding
PrismaCoder's significance goes beyond leaderboard climbing. The approach it proposes—using structured, decomposable rubrics to unify data processing and training rewards—provides a scalable supervision paradigm for multimodal tasks. Once goals that are difficult to quantify, such as visual correctness, are decomposed into specific items, they can be reliably handled by automated pipelines.
Of course, the quality of rubrics themselves depends on the judgment of their designers, and how to control the completeness and bias of the decomposition dimensions remains a question requiring long-term validation. The research team has made the code and data publicly available at https://qiushisun.github.io/PrismaCoder-Home/, leaving room for further community scrutiny and iteration.
One-line Summary
PrismaCoder unifies data filtering and reinforcement learning rewards with verifiable rubrics, breaking through multimodal code intelligence bottlenecks.
Paragraph Summary
PrismaCoder is an open-source project for multimodal code intelligence, attempting to solve the challenge that models generating charts, web pages, and other artifacts must simultaneously satisfy program correctness, engineering standards, and visual correctness. The research team built PrismaForge, a hierarchical data pipeline centered on synthetic rubrics, decomposing the three-layer constraints into checkable items and letting the same rubric serve as both data filter and reinforcement learning reward signal, avoiding disconnection between filtering criteria and training objectives. Based on this pipeline, the team constructed PrismaCoder-2M, described as the most diverse and largest open-source multimodal code dataset, and trained PrismaCoder-9B and PrismaCoder-35B, claiming substantial leadership over open-source state-of-the-art and the ability to compete with leading proprietary systems. This work provides a scalable supervision paradigm for difficult-to-quantify goals such as visual correctness, but the completeness and bias control of the rubric design itself still require long-term validation.
Related articles

Instacloud in Practice: Deploying LeetCode-Grade Infrastructure with an Agent
A hands-on test of Instacloud: how an AI Agent deploys LeetCode-grade judging infrastructure from scratch, including Redis queues, APIs, and sandboxed Workers, plus real issues and platform limits.

Gemini 4 Argon Generates a Cyberpunk 3D City from a Single Prompt, Running at 60 FPS in the Browser
Google Gemini 4 Argon generates a cyberpunk 3D city animation from a plain prompt, built with Three.js, running at a stable 60 FPS in the browser in about 30 minutes, showcasing AI's engineering ability to generate executable 3D code.

Mamba2-8B Compression Research: 27MB Cache and 3.14GB Model
Mamba2-8B compression research achieves a 27.18 MiB recurrent cache and 3.141 GB model storage, exploring SSM efficiency advantages for edge deployment and long-context inference, offering new ideas for AI inference optimization.