Probabilistic Numerics with Constraints: A New Breakthrough in Gaussian Process Solvers for Linear PDEs

GP PDE solvers can now enforce inequality constraints via sequential conditioning, making admissibility part of inference.
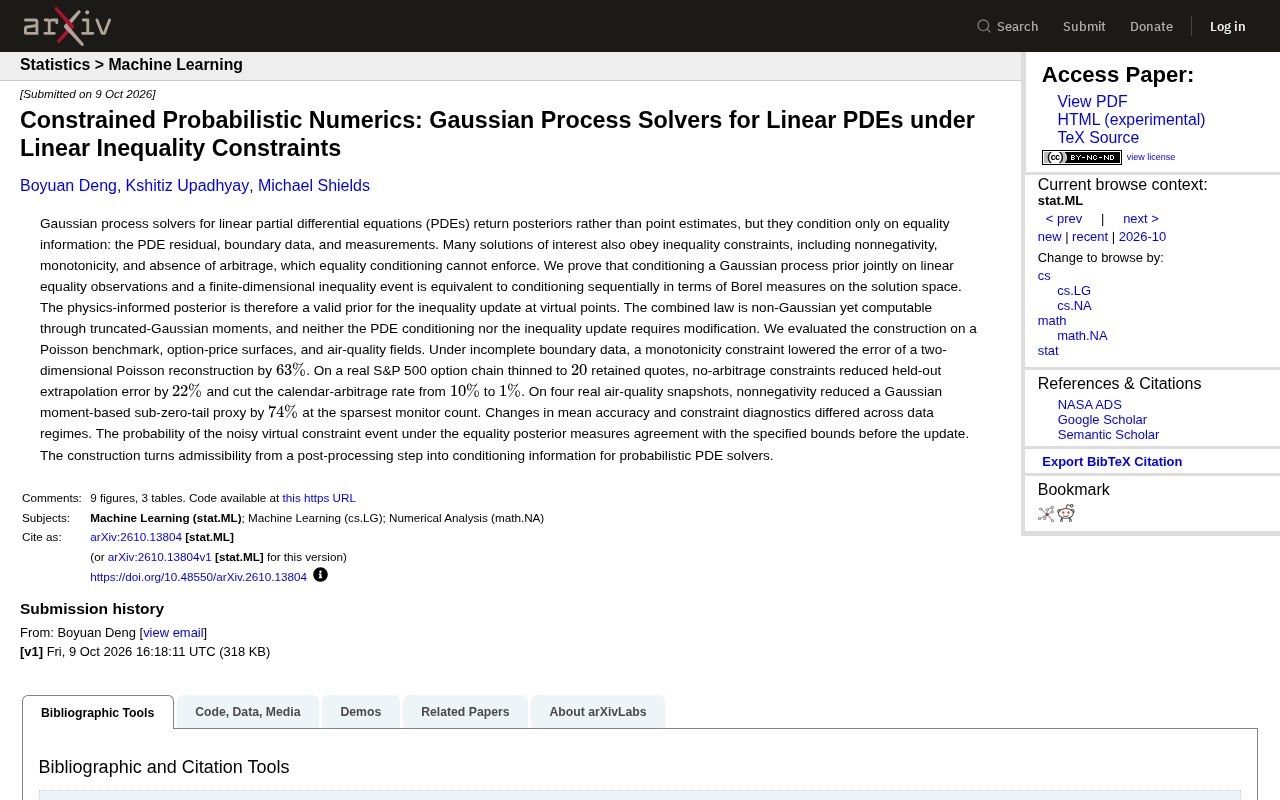
This study addresses a long-standing limitation of Gaussian process PDE solvers — their inability to handle inequality constraints — by proposing a theoretical framework that incorporates non-negativity, monotonicity, and no-arbitrage conditions into probabilistic numerics. The key contribution proves that joint conditioning on equality and inequality constraints is equivalent to sequential conditioning, meaning the physics-informed posterior serves as a valid prior for inequality updates without modifying existing pipelines. The resulting non-Gaussian posterior is tractable via truncated-Gaussian moments. Experiments across Poisson reconstruction, S&P 500 option pricing, and air quality fields show error reductions of 63%, 22%, and a calendar-arbitrage rate drop from 10% to 1%, demonstrating that admissibility can be built into inference rather than enforced through post-processing.
From Equality Conditions to Inequality Constraints: A Gap in Probabilistic Numerics
Gaussian Process (GP) solvers have demonstrated unique value in solving linear partial differential equations (PDEs) in recent years. Unlike traditional numerical methods that return only point estimates, GP solvers return posterior distributions, naturally quantifying solution uncertainty. This property is particularly valuable in physics-informed modeling, financial pricing, and environmental monitoring.
However, existing methods have a long-overlooked limitation: they can only condition on equality information, including PDE residuals, boundary data, and observational measurements. Yet many real-world solutions must also satisfy inequality constraints — non-negativity, monotonicity, no-arbitrage conditions, and more. These constraints cannot be directly enforced through equality conditioning. In other words, traditional GP solvers may produce solutions that are mathematically consistent with the equations but physically or economically inadmissible — such as negative concentration values or option prices that violate no-arbitrage principles.
GP solvers belong to the broader framework of Probabilistic Numerics, which treats numerical computation itself as a statistical inference problem: rather than returning a single value, algorithms return a posterior distribution reflecting uncertainty from discretization, finite observations, or model error. In PDE solving, the standard approach is to place a GP prior over the solution function, apply the PDE operator to the prior, and treat equation residuals and boundary conditions as "observations" for updating the posterior — a structure mathematically identical to Bayesian linear regression extended to function spaces. Virtual points are an important tool in this framework: artificially placed pseudo-observation points in regions without real observations, used to convey structural prior knowledge (such as monotonicity or non-negativity), allowing constraint information to enter the inference pipeline as equality/inequality observations without redesigning the core solver structure.
Core Theory: Joint Conditioning Is Equivalent to Sequential Conditioning
The theoretical contribution of this work lies in proving a key equivalence: jointly conditioning a Gaussian process prior on linear equality observations and finite-dimensional inequality events is equivalent to sequential conditioning in the sense of Borel measures on the solution space.
The practical implication of this result is direct. It means that the physics-informed posterior is itself a valid prior for inequality updates. Researchers can therefore first complete equality conditioning for the PDE in the conventional way, then apply inequality constraint updates at virtual points — with neither step requiring any modification to the existing pipeline.
The resulting joint distribution is no longer Gaussian, but remains tractable — computable via truncated-Gaussian moments. This design elegantly preserves the analytical advantages of the GP approach while extending its expressive power. More importantly, the probability of noisy virtual constraint events under the equality posterior measure provides a diagnostic indicator for assessing how well the solution conforms to the specified bounds before the update is applied.
The Truncated Gaussian distribution restricts a multivariate Gaussian to a convex polyhedral region (i.e., the feasible region defined by inequality constraints). Its moments (mean and covariance) have no closed-form analytical expression and typically require quasi-Monte Carlo sampling, Mini-max tilting algorithms, or variational approximations. These methods are efficient in low dimensions but incur significantly higher computational cost as dimensionality grows. The "truncated-Gaussian moments" referenced in this paper use this tool to represent posterior statistics after imposing inequality constraints, incorporating inequality information while preserving the analytical tractability of the GP framework. The Gaussian posterior from equality conditioning provides the known mean and covariance for the truncation step, so the truncation computation acts only on the finite-dimensional virtual point projection, effectively controlling computational scale.
Experimental Validation Across Three Real-World Scenarios
The study validates this construction across three distinct problem types, spanning physics, finance, and environmental science.
Poisson Equation Reconstruction
In a 2D Poisson benchmark test with incomplete boundary data, imposing monotonicity constraints reduced reconstruction error by 63%. This demonstrates that structural prior constraints can effectively compensate for data deficiencies under information-sparse conditions.
S&P 500 Option Pricing Surface
On a real S&P 500 option chain, researchers reduced the data to only 20 quotes. Introducing no-arbitrage constraints reduced out-of-sample extrapolation error by 22%, while the calendar-arbitrage violation rate dropped from 10% to 1%. For financial applications, this not only improves accuracy but — more critically — guarantees the economic validity of the pricing surface.
No-arbitrage conditions are fundamental economic constraints in option pricing that rule out risk-free arbitrage opportunities. For European call option pricing surfaces, common no-arbitrage constraints include: monotone decreasing prices with respect to strike price (static arbitrage), monotone increasing prices with respect to expiration time (calendar arbitrage), and convexity with respect to strike price (butterfly arbitrage). Calendar arbitrage specifically refers to pricing errors where options on the same underlying with the same strike but different maturities violate time monotonicity — i.e., a short-dated option is priced higher than a long-dated one — which implies a zero-cost certain profit in a frictionless market. With sparse data, interpolation or regression models easily produce surfaces that violate these constraints, rendering pricing models unusable in practice.
Air Quality Fields
Across four real-world air quality snapshot datasets, imposing non-negativity constraints reduced the Gaussian-moment-based proxy metric for "sub-zero tail probability" by 74% in the most monitor-sparse settings. This means the risk of the model producing negative concentrations — physically impossible — was dramatically reduced.
Performance Differences Across Data Regimes
Notably, improvements in mean accuracy and constraint diagnostic indicators behave differently across data regimes. This suggests that the benefits of constraints are highly dependent on data availability and constraint type for each specific problem. When data is sparse or boundary information is incomplete, the improvements from constraints tend to be most significant; when data is abundant, constraints more often serve to guarantee admissibility rather than substantially improving accuracy.
This differentiated behavior is itself a valuable research finding, providing practitioners with empirical guidance on when to introduce constraints and which constraints to apply.
Significance: Turning Admissibility from Post-Processing into Conditioning Information
The most fundamental shift in this work is transforming solution admissibility from a traditional post-processing step into conditioning information within the probabilistic PDE solver.
The conventional approach — solve first, then project or clip to force constraint-violating solutions back into the feasible region — risks destroying the statistical consistency of the solution through such ad hoc corrections. This paper's approach instead incorporates constraints directly into the inference process, so the resulting posterior distribution inherently respects those constraints. This is not only more theoretically elegant but also more practically reliable — constraint information becomes an organic part of the solution process rather than an external patch.
For engineering and scientific applications that must simultaneously satisfy mathematical correctness and physical/economic validity, these constrained probabilistic numerical methods offer a new path that reconciles uncertainty quantification with hard constraints.
Related articles

JobRunner MCP Server: AI Agents Can Now Fix Failed Java Jobs
JobRunner launches an open-source MCP server enabling AI agents to view cluster status, diagnose failures, and recover Java jobs—incident response from any cloud coding environment or existing agent.

MLAI Digital Launches 9 Security Agents: MCP Server Safeguards the Full Lifecycle of Agentic AI
MLAI Digital launches Security MCP Server with nine built-in specialized security agents covering vulnerability discovery, attack simulation, prompt injection detection, API and infrastructure assessment, and accelerated remediation—embedding security validation across the full Agentic AI lifecycle from development to production.

Running Isaac Lab on H100 GPUs: Exploring Better Approaches
Exploring optimization methods for running Isaac Lab on NVIDIA H100 GPUs, including MIG configuration, mixed precision, TensorRT acceleration, and community experience to improve robotics simulation and reinforcement learning efficiency.