Production-Grade PPE Safety Dataset Procurement Guide: Channels, Quality, and Build-vs-Buy Tradeoffs

For industrial PPE vision systems, high-quality compliant data — not algorithms — is the real bottleneck.
A developer's Reddit post seeking production-grade PPE detection datasets surfaces a common pain point in industrial vision deployment. The article covers three core data requirements (commercial licensing, high-precision annotations, edge-case scale), reviews procurement channels including Scale AI, Appen, Dataloop, and Dataset Ninja, and analyzes the buy-vs-build tradeoff. A hybrid strategy — public data for baselines, self-collected edge cases for fine-tuning, and active learning post-deployment — is recommended as the most practical path to production accuracy.
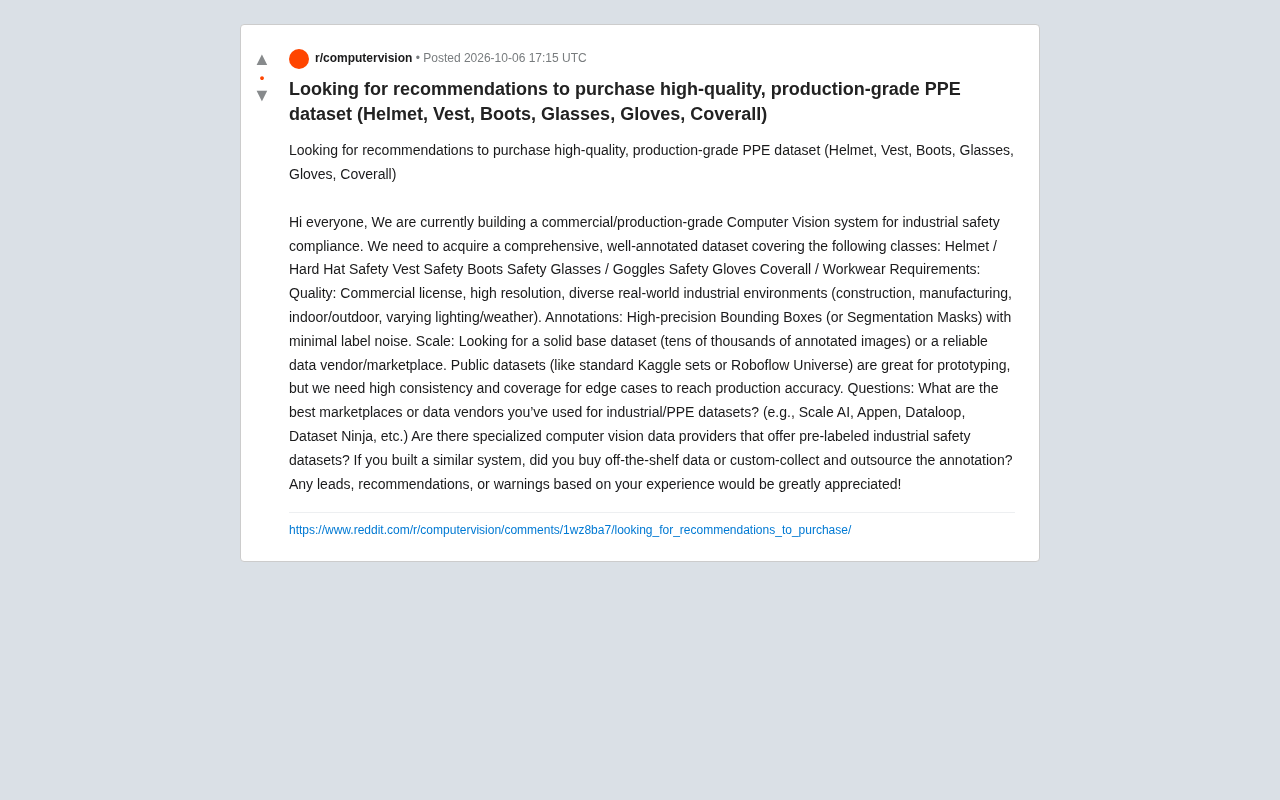
Computer vision systems for industrial safety compliance are being deployed at a rapid pace, and the core asset powering these systems is often not the model architecture — it's high-quality annotated data. A developer recently sparked a discussion on Reddit seeking advice on procuring production-grade Personal Protective Equipment (PPE) detection datasets, covering six target categories: hard hats, reflective vests, safety boots, goggles, protective gloves, and coveralls. The need behind this request reflects a universal engineering reality: public datasets are fine for prototyping, but achieving production-level accuracy hinges on data consistency and edge case coverage.
How Demanding Are the Data Requirements for PPE Detection Systems?
The developer laid out hard requirements across three dimensions — a useful reference for any team building a similar system.
Quality
The top requirement is commercial licensing. Many public datasets are free but carry license terms that prohibit commercial use, creating legal risk when deployed in production. Beyond licensing, the data needs high-resolution images covering diverse, real-world industrial environments — construction sites, manufacturing floors, indoor and outdoor scenes, varying lighting conditions and weather. Models trained on a single scene type generalize poorly in real deployments; this is one of the most common pitfalls in industrial vision.
Annotation
The requirements call for high-precision bounding boxes or segmentation masks with minimal label noise. PPE detection is tricky because targets are easily confused — a regular hat versus a hard hat, everyday clothing versus protective coveralls. Annotation consistency directly determines whether the model can learn effective discriminative features. At a scale of tens of thousands of images, label noise compounds and degrades final accuracy significantly.
Bounding boxes and segmentation masks represent two levels of annotation precision. Bounding boxes simply draw a rectangle around a target — fast, cheap, and suitable when occlusion between objects is minimal. Segmentation masks trace object contours pixel by pixel, enabling precise separation of overlapping hard hats and faces, or vests and shirts — but at roughly 3–5× the cost of bounding boxes. For PPE detection, when targets are heavily occluded or boundaries are ambiguous (e.g., coveralls vs. regular clothing), instance segmentation masks provide stronger discriminative signal. A common engineering approach: use bounding boxes for primary categories (hard hats, reflective vests) and segmentation masks for frequently occluded fine-grained categories (goggles, gloves), balancing cost against accuracy.
Scale
The post mentioned wanting a solid base dataset of tens of thousands of annotated images, or a reliable data vendor or marketplace. Scale isn't just about raw quantity — it's about whether enough edge cases are covered, which is precisely what separates "it runs" from "it ships."
The Main Channels for Commercial Data Procurement
The original poster listed several well-known data service platforms, and these are worth evaluating first when building industrial vision systems.
Scale AI is known for high-quality annotation services, well-suited to commercial projects with demanding accuracy requirements and sufficient budget, supporting custom data collection and labeling workflows. Appen is a veteran crowdsourced data platform with broad coverage, ideal for large-scale annotation tasks. Dataloop provides an integrated data management and annotation platform, more oriented toward teams that want to own and manage their own data pipelines. Aggregation catalogs like Dataset Ninja can help quickly surface existing open or semi-open resources.
For a relatively niche industrial safety domain like PPE, one of the key questions raised in the thread is whether vendors specifically offering pre-labeled industrial safety datasets exist. In practice, PPE data on general data marketplaces often comes from specific regions or industries, and may not provide sufficient coverage when applied to a new deployment context.
Buying Ready-Made Data vs. Self-Collection with Outsourced Labeling: The Core Tradeoff
One of the most broadly useful questions in the thread is: when building this type of system, should you buy ready-made data or collect your own and outsource the annotation? This is a decision nearly every industrial CV project must face.
Buying ready-made datasets offers fast time-to-start and predictable costs, making it good for quickly validating commercial feasibility. But the downsides are just as clear — off-the-shelf data rarely precisely matches the camera angles, worker types, and regional differences of the target deployment environment, creating a systematic gap between the training distribution and actual inference conditions.
Self-collection with outsourced annotation offers the best fit for the real deployment context. Teams can capture images on-site at target factories or construction sites, ensuring data distribution matches the deployment environment, then outsource labeling to a professional team. The tradeoff is high upfront investment, longer timelines, and the need to establish rigorous annotation quality control processes.
A pragmatic middle ground is a hybrid strategy: use public datasets (e.g., PPE data on Roboflow Universe or Kaggle) to build a prototype and baseline model, then self-collect targeted edge case data for incremental training, and continuously gather hard samples from the real deployment environment for ongoing iteration. This approach balances speed with final accuracy.
The systematic gap between training and inference distributions is known in machine learning as Dataset Shift, and it's one of the leading causes of failure when deploying industrial vision systems. In PPE-specific terms, camera mounting height, focal length, compression bitrate, and regional workwear standards (hard hat color conventions differ by country) all introduce distribution differences. A model trained on European construction site data and deployed directly to a Southeast Asian manufacturing floor will commonly see mAP (mean Average Precision) drop by 10–20 percentage points, due to differences in lighting, worker body types, and equipment styles. When evaluating ready-made datasets, look beyond total sample count — check the source country, industry type, and capture device specs. These details are key to assessing distribution alignment.
Practical Recommendations for Industrial Vision Teams
Building on this real-world use case, a few guiding principles emerge for building production-grade PPE detection systems.
When evaluating data vendors, always verify the commercial licensing terms to avoid compliance risk down the road. Before committing to large-scale procurement, request sample data for small-scale validation — focus on annotation consistency and scene coverage, not just total volume. For high-regulatory categories like hard hats and vests, the cost of missed detections is severe; edge case coverage (backlighting, occlusion, small distant targets) should be a top priority in procurement or collection.
Finally, data work in industrial vision projects is typically not a one-time purchase — it's a continuously operating feedback loop. Feeding real-world false positives and false negatives back into the training set after deployment usually drives more improvement in production accuracy than buying a massive dataset upfront.
This Reddit thread surfaces a shared pain point across the industrial AI deployment landscape: algorithms are no longer the primary bottleneck. Reliable, compliant, context-matched data is what truly determines whether a system can ship.
Continuously collecting "hard samples" is typically implemented in practice through an Active Learning framework: the model outputs confidence scores at inference time, automatically routing low-confidence samples to an annotation queue. These edge cases are prioritized for human review and labeling, then folded into the next training round. Compared to random sampling, active learning achieves greater accuracy gains with a smaller annotation budget — especially well-suited to PPE, where hard samples (backlighting and occlusion, small distant targets, non-standard wearing postures) are rare in the data but have an outsized impact on real-world performance after deployment. Building this data flywheel mechanism during the deployment phase typically delivers better long-term returns than a one-time expansion of the training set.
Related articles

Reinforcement Learning Takes On Getting Over It: Distributed Training Strategies Behind 63% Progress
A developer uses deep reinforcement learning to tackle Getting Over It. The agent climbs from the bottom to 63% progress but gets stuck at the anvil. The project is open-sourced, using divide-and-conquer training and CPU-only training, seeking community collaboration to break the bottleneck.

Sigma FP2 Released: The World's Smallest Full-Frame Camera Gets Sensor and Screen Upgrades
Sigma launches the FP2 full-frame camera, retaining its smallest-and-lightest design with three key upgrades: improved sensor, articulating LCD screen, and longer battery life—built for portable video creators.

AAAI 2027 Phase 2 Decisions Imminent: Community Debates Review Fairness and Submission Ecosystem
AAAI 2027 phase 2 review results are imminent, with the Reddit community debating reviewer consistency and process transparency. This article examines pre-decision sentiment, structural tensions in top conference review, and practical strategies for authors.