Qwen3.6 35B Open-Source Model Approaches Claude in Tests, xAI Voice Cloning API Officially Launches
AI industry updates: Alibaba open-sources Qwen3.6, xAI launches Voice Cloning API, NVIDIA open-sources security sandbox
On May 3, 2026, the AI industry saw several major technical updates. Alibaba open-sourced the Qwen3.6 35B model with a 256-expert MoE architecture that activates only 3B parameters yet approaches closed-source frontier performance, scoring 73.4% on SWE-Bench. xAI released its Voice Cloning API supporting custom voice creation in under 2 minutes across 28 languages. NVIDIA open-sourced OpenShell, an enterprise-grade Agent security sandbox. Open-source models are shifting from budget alternatives to directly deployable frontier-capable foundations.
On May 3, 2026, the AI industry saw a wave of intensive technical updates. Alibaba open-sourced the Qwen3.6 35B model featuring an extremely sparse architecture, xAI officially launched its Voice Cloning API, NVIDIA open-sourced OpenShell—an enterprise-grade Agent security sandbox—and Sam Altman publicly stated his priorities for model development. Each piece of news is reshaping the landscape of AI's trajectory. Here's an in-depth breakdown of today's key developments.
Alibaba Open-Sources Qwen3.6 35B: 256-Expert MoE Architecture Approaching Closed-Source Frontier
Alibaba officially open-sourced the 35B model from its Qwen3.6 series, featuring an extremely sparse Mixture of Experts (MoE) architecture.
About MoE Architecture: Mixture of Experts is a design paradigm that divides a neural network into multiple "expert" sub-networks. Its core concept originated from research by Jacobs et al. in 1991 and has been widely adopted by large language models in recent years. Unlike traditional Dense Models, MoE activates only a subset of expert networks during each forward pass, with a "Router" determining which experts should process each token. This design allows models to have parameter counts far exceeding their actual computational load—a separation of "total parameters" from "active parameters." Google's Switch Transformer (2021) and Mixtral 8x7B (2023) represent important milestones for MoE architecture in large models. The extremely sparse design with 256 experts is where Qwen3.6 gets aggressive: the more experts there are, the higher the degree of specialization per expert, but the load-balancing difficulty for the router also increases. How to avoid "expert collapse" (where some experts are overused while others sit idle) is the core engineering challenge.
The model contains 256 experts, but each token activates only 8 routed experts and 1 shared expert, resulting in approximately 3B active parameters during inference. This means users can run this model at a computational cost far below that of a full 35B-parameter model.
Community test results are quite impressive: on the SWE-Bench Verified leaderboard, Qwen3.6 35B achieved a score of 73.4%, just 1.6 percentage points behind Claude Opus 4.6.
About the SWE-Bench Evaluation Benchmark: SWE-Bench (Software Engineering Benchmark) is a code capability evaluation benchmark proposed by Princeton University in 2023, specifically designed to measure AI models' ability to solve real-world software engineering problems. Unlike traditional code completion tests, SWE-Bench requires models to read real GitHub issue descriptions and generate patches that pass unit tests in the corresponding code repository. SWE-Bench Verified is a curated subset with human verification ensuring task quality, and is considered one of the gold standards for measuring practical programming ability in the industry. The benchmark is challenging because it tests not only code generation ability but also understanding of large codebases, cross-file dependency analysis, and debugging reasoning capabilities. A score of 73.4% means the model can independently resolve over 70% of real software engineering defects—a level that just a year ago was the exclusive domain of top-tier closed-source models.
Another community test showed that the 27B version of Qwen3.6, paired with a retrieval Agent, can run locally on a single RTX 3090 and achieve 95.7% accuracy on the Simple QA test.
These numbers send a clear signal: open-source models are evolving from "budget alternatives" into frontier-capable foundations ready for direct deployment. When an open-source model with only 3B active parameters can approach the coding capabilities of top closed-source models, the economics of enterprises building their own AI infrastructure are being fundamentally rewritten.
xAI Launches Voice Cloning API: Voice Cloning Enters Production-Ready Stage
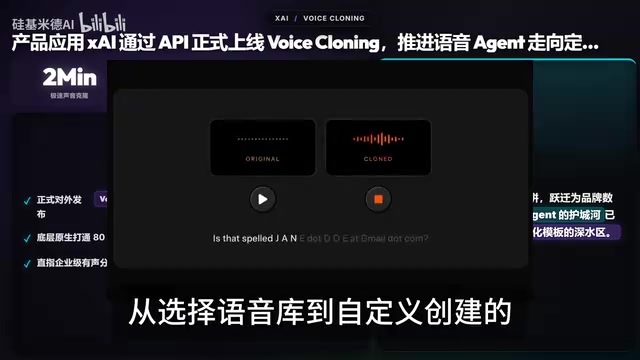
xAI officially released its Voice Cloning API, enabling users to create custom voices in under 2 minutes or directly use over 80 pre-built voices covering 28 languages. The official demo video showcases the complete interface workflow from selecting a voice library to creating custom voices, with application scenarios spanning voice Agents, audiobooks, and game character voiceovers.
Voice Cloning Technology and Compliance Challenges: Voice cloning technology uses deep learning to extract speaker voiceprint features from a small number of audio samples and transfers them to speech synthesis for arbitrary text. Early approaches required hours of recordings, but modern zero-shot or few-shot learning-based TTS models (such as VALL-E, Tortoise TTS) have compressed the required samples to just a few seconds. From a technical implementation perspective, voice cloning typically consists of three modules: a Speaker Encoder, a Synthesizer, and a Vocoder. However, the commercialization of voice cloning has long been constrained by compliance risks: deepfake audio has been used for phone scams and identity impersonation. xAI positioning its API as "production-ready"
Related articles
 Tech Frontiers
A Rare Quiet Day in AI: Recursive Self-Improvement Stirs Beneath the Surface
A rare quiet day in AI sees multiple sources go silent simultaneously. Behind the calm, Recursive Self-Improvement (RSI) research continues. What this means for the industry.
 Tech Frontiers
Reve 2 vs. Ideogram 4: A Deep Dive into Layout Control in AI Image Generation
A deep comparison of Reve 2 and Ideogram 4's layout control capabilities, covering technical approaches, real-world use cases, and industry trends for designers and creators.
 Tech Frontiers
In the Weights: Check Your Influence Score in the AI World
In the Weights is an AI influence search engine that quantifies your presence in the AI world with a score. Explore how it evaluates practitioners and what it means for digital identity.