Qwen3.6 MTP Acceleration Benchmarked: Single GPU Inference Hits 220 token/s

Qwen3.6's MTP-GGUF version achieves 220 token/s on a single GPU, 1.4x faster with zero accuracy loss.
Daniel Han released an experimental MTP-GGUF version of Qwen3.6 that builds multi-token prediction directly into the model's training phase, pushing the 35B-A3B model to 220 token/s on a single GPU — over 1.4x faster than the original with zero accuracy loss. Testing revealed that setting Draft Tokens to 2 is optimal, achieving 80%+ acceptance rates. The solution requires no extra draft model and activates with a single command, marking a new era for high-performance local LLM inference.
Daniel Han (founder of Onslaught AI, former NVIDIA ML engineer) just released an experimental MTP-GGUF version of Qwen3.6, pushing the 35B-A3B model's inference speed to 220 token/s on a single GPU — over 1.4x faster than the original GGUF with zero accuracy loss. This marks a new phase for local LLM inference — no longer a "good enough to run" compromise, but a genuinely high-performance solution.
What Is MTP? From Speculative Decoding to Built-in Multi-Token Prediction
To understand the nature of this speedup, you first need to grasp what MTP (Multi-Token Prediction) actually does.
Traditional LLM inference is sequential: each step predicts only one token, and the next can't be generated until the current one is complete. The bottleneck here isn't compute — it's memory bandwidth. The GPU spends most of its time waiting for data transfers while its compute units sit idle.
This phenomenon has deep hardware roots. Take the RTX 4090 as an example: its theoretical FP16 compute is a staggering 82.6 TFLOPS, but memory bandwidth is only 1008 GB/s. During autoregressive decoding, generating each token requires moving billions of parameters from VRAM to compute units, while the actual computation is minimal. This "lots of moving, little computing" characteristic means GPU utilization often falls below 10%. This is known as a "Memory-Bound" operation, in stark contrast to "Compute-Bound" operations like matrix multiplication. This is precisely where MTP's core value lies: by predicting multiple tokens per data transfer, it compresses what would be multiple sequential IO operations into one, fundamentally improving memory bandwidth utilization.
Traditional Speculative Decoding uses a small "draft model" to accelerate inference: the small model quickly guesses several tokens, then the large model verifies them in parallel — correct guesses are accepted directly, incorrect ones trigger a rollback. This approach was first systematically proposed by Google DeepMind in 2023, based on the core insight that "verification is cheaper than generation for large models" — due to the Transformer's parallel attention mechanism, verifying N tokens costs roughly the same as verifying 1. However, traditional speculative decoding faces numerous engineering challenges: the draft model and target model must have perfectly aligned vocabularies, hosting both models simultaneously doubles memory pressure, and distribution bias from the draft model can affect output quality.
MTP takes a more elegant approach: it builds multi-token prediction capability directly into the model during training. Meta first introduced MTP as a training objective in the LLaMA 3 technical report, demonstrating that directly optimizing for multi-token prediction during training can simultaneously improve model capability and inference efficiency. Qwen3.6 adopts and strengthens this design by incorporating MTP heads during training, giving the model the native ability to predict multiple future tokens at once. The Unsloth team quantized and packaged these MTP weights into the GGUF format, and llama.cpp adapted its kernels accordingly — the entire pipeline is now connected.
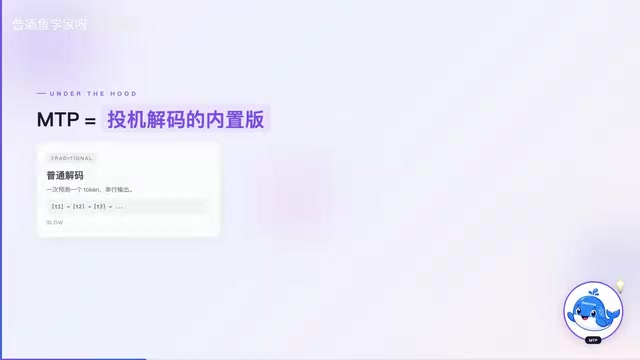
No extra small model needed, no complex configuration — acceleration is enabled with a single command. This is the advantage of architectural simplicity.
Optimal Strategy: Draft Tokens Set to 2 Is the Performance Sweet Spot
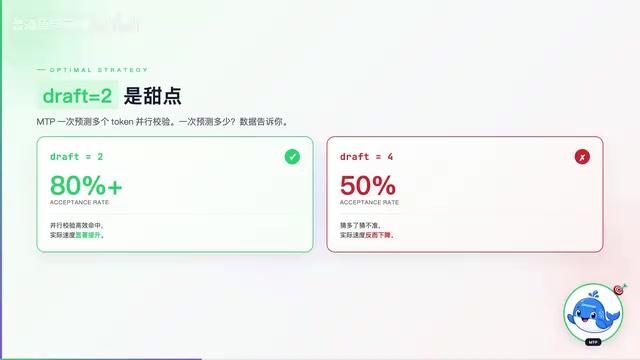
Daniel Han's team discovered a crucial optimal strategy during testing: setting Draft Tokens to 2 is the best choice.
This is backed by precise mathematical logic. Acceptance Rate is the core metric for measuring speedup in speculative decoding. Given a draft length k and per-token acceptance rate α, the expected number of tokens generated per decoding step is approximately (1-α^(k+1))/(1-α). When α=0.8 and k=2, the expected token generation is about 2.44, yielding a theoretical speedup close to 2.44x; when α=0.5 and k=4, the expected generation is about 1.97, resulting in a lower speedup. This pattern reveals that optimal draft length must be dynamically calibrated based on the model's prediction confidence — beyond the point of diminishing returns, longer draft windows only produce more wasted computation.
With draft length set to 2, the acceptance rate exceeds 80% — meaning both predicted tokens are most likely correct, effectively eliminating half the decoding steps. But if you greedily extend the draft to 4, the acceptance rate plummets to around 50%. The further you predict, the greater the uncertainty, error rates spike, and more rollbacks and recomputation are needed. In Daniel's own words: "Any more and it becomes counterproductive."
This finding is highly instructive for real-world deployment: don't blindly chase larger speculative windows — finding the balance between acceptance rate and parallelism is what matters.
RTX 5090 Benchmark Data: 27B vs 35B Model Comparison
The benchmark results on RTX 5090 are quite impressive:
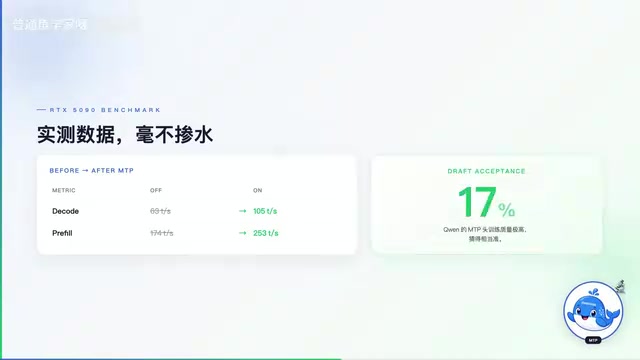
27B Model (Q4 Quantization):
- Without MTP: ~63 token/s decode speed
- With MTP: decode speed jumps to 105 token/s
- Prefill speed: from 174 to 253 token/s
- Draft acceptance rate: stable at ~80%
- VRAM usage: ~18GB
35B-A3B (MoE Version):
- Inference speed: 220 token/s
- VRAM usage: ~23GB
It's worth noting that "MoE" in 35B-A3B refers to Mixture of Experts architecture — "35B" is the total parameter count, while "A3B" indicates that only about 3B parameters are actually activated per inference. MoE's core mechanism is the Router: for each input token, the router selects from dozens of "experts" to process it, enabling massive total model capacity while keeping per-inference compute costs low.
Related articles
 Tech Frontiers
A Rare Quiet Day in AI: Recursive Self-Improvement Stirs Beneath the Surface
A rare quiet day in AI sees multiple sources go silent simultaneously. Behind the calm, Recursive Self-Improvement (RSI) research continues. What this means for the industry.
 Tech Frontiers
Reve 2 vs. Ideogram 4: A Deep Dive into Layout Control in AI Image Generation
A deep comparison of Reve 2 and Ideogram 4's layout control capabilities, covering technical approaches, real-world use cases, and industry trends for designers and creators.
 Tech Frontiers
In the Weights: Check Your Influence Score in the AI World
In the Weights is an AI influence search engine that quantifies your presence in the AI world with a score. Explore how it evaluates practitioners and what it means for digital identity.