Qwen3.6 Unofficial Derivative Models: 34B Depth Extension and 14B Extreme Compression Explained

Two unofficial Qwen3.6 derivatives: 34B depth extension for reasoning and 14B MoE compression for lightweight deployment.
Community developers created two Qwen3.6 derivatives taking opposite approaches. The 34B model extends the 27B from 64 to 80 Transformer layers, improving multi-step reasoning, distillation capacity, and MTP acceptance rates. The 14B model uses REAP pruning to remove 50%+ idle experts from the 35B MoE, retaining 95.9% coding ability while fitting on 8GB GPUs. Both reveal key insights about Transformer depth scaling and MoE expert redundancy.
Community developers are pushing beyond official model boundaries with innovative approaches—one stretches Qwen3.6 27B into a 34B model, while another slims the 35B MoE down to 14B. These two unofficial derivative models take completely opposite paths, yet both target the core pain points of local deployment users.
34B 80-Layer: Capability Leap Through Transformer Depth Extension
The official Qwen3.6 only released 27B Dense and 35B MoE versions—there's no official 34B specification. The origin of this model is quite straightforward: the developer extended Qwen3.6 27B's 64-layer Transformer network to 80 layers, growing the parameter count from 27B to 34B, an increase of approximately 26%.
The extension method is remarkably "clean"—four complete processing modules were added on top of the original architecture (from 16 groups to 20 groups), while preserving the original hybrid attention mechanism and MTP speculative decoding support. Attention head count, vocabulary size, and context length (262K) all remain unchanged. This means it's not a haphazardly patched modification, but a methodical depth extension.
Technical Principles of Depth Extension
The Transformer architecture consists of multiple stacked layers of self-attention mechanisms and feed-forward networks, with each layer performing a nonlinear transformation on the input representation. Depth scaling is a classic model expansion strategy, with its theoretical foundation rooted in residual network research—thanks to residual connections, adding layers doesn't cause gradient vanishing but instead allows the model to learn more refined feature transformations. In practice, depth scaling is typically more efficient than width scaling (increasing hidden dimensions) because it doesn't change the computational complexity of each layer, only linearly increasing total computation. The GQA (Grouped Query Attention) mechanism used in Qwen3.6 27B is particularly extension-friendly, as KV cache size doesn't grow linearly with layer count, keeping the memory overhead increase manageable for the 80-layer version in long-context scenarios.
What Do Deeper Layers Mean for Reasoning Ability?
In Transformer architectures, each layer learns different levels of features. Shallow layers (1-20) handle basic grammar, middle layers (21-50) understand logical relationships, and deep layers (51+) handle reasoning and planning. Extending from 64 to 80 layers essentially adds 4 complete processing modules in the higher-order reasoning region, representing approximately a 25% increase.
This increase is particularly critical for repository-level code comprehension. Function signatures, call chains, module design, overall architecture—these highly abstract concepts require the model to have sufficient deep-layer processing capability. The 27B tends to "not fully grasp" complex code projects, while the 34B achieves significant improvement in this area.
Four Core Advantages of the 34B 80-Layer Model
1. Longer and More Stable Reasoning Chains
Compared to the original 27B, the 80-layer model shows significantly improved accuracy in multi-step reasoning. The original might start making errors after three reasoning steps, while the 80-layer version can maintain accuracy for five or more steps, with substantially reduced intermediate step error accumulation in mathematical reasoning.

2. Better Distillation Performance
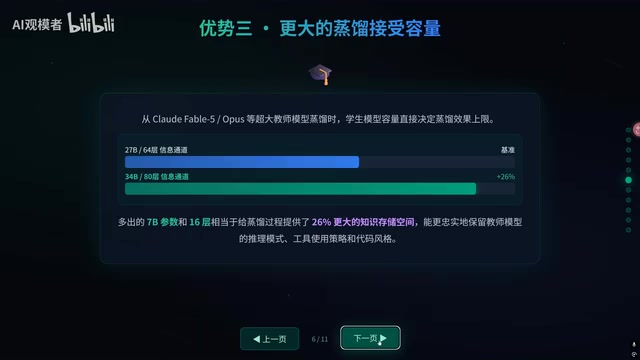
This is an easily overlooked but extremely important advantage. The community currently favors distillation using Claude Fable and Opus, but the 27B has limited "knowledge capacity"—it's like having a university professor teach an elementary school student: the professor can only teach problem-solving steps, while deeper knowledge simply won't fit. The 34B is like upgrading the "elementary student" to a "high schooler," capable of absorbing more of the teacher model's reasoning chains and problem-solving logic, with distillation support capacity improved by approximately 26%.
The core challenge of Knowledge Distillation lies in the student model's capacity bottleneck. The student model's parameter count determines how much of the teacher's knowledge it can "hold"—when capacity is insufficient, "distillation saturation" occurs: regardless of how strong the teacher model is, the student model's performance cannot continue improving. The current popular approach in the community is to use top-tier models like Claude to generate high-quality Chain-of-Thought data, then fine-tune open-source models with this data. The 34B has approximately 7B more parameters than the 27B, and these extra parameters provide a larger "knowledge container" that can more completely reproduce the teacher model's reasoning patterns, especially those complex reasoning paths requiring multiple steps and branches.
3. Stronger Long-Context Retention
Although the 27B nominally supports 262K context, long-range tasks tend to "forget" in actual use. The 80 layers provide more capacity to encode and retain contextual information, with more precise memory and less forgetting.
4. Improved MTP Speculative Decoding Acceptance Rate
The original 27B's speculative decoding acceptance rate on LM Studio is only about 57-58%, while the 80-layer version achieves approximately 78%. A higher acceptance rate means predicted tokens are more likely to be valid, reducing the need for frequent rollbacks and regeneration, thereby improving actual inference speed.
MTP (Multi-Token Prediction) speculative decoding is an important technique for accelerating autoregressive generation. Traditional Transformers predict only the next token at a time, while MTP allows the model to simultaneously predict multiple future tokens. During inference, the model first uses a lightweight "draft head" to quickly predict multiple candidate tokens, then uses the main model to verify whether these predictions are correct. The "acceptance rate" refers to the proportion of draft predictions accepted by the main model—the higher the acceptance rate, the more tokens effectively generated per verification step, reducing the number of forward passes through the main model. The 80-layer model's acceptance rate improvement from 57% to 78% is fundamentally because the deeper network makes the draft head's predictions more consistent with the main model's judgments, allowing more tokens to be "guessed correctly" per speculation, thereby partially offsetting the 18% increase in inference time through higher acceptance rates.
Of course, the trade-off is clear: the 34B takes approximately 18% longer to infer than the 27B—an inevitable consequence of increased size.
14B MoE: An Extremely Compressed Lightweight Model
If the 34B is "addition," then the 14B is "subtraction"—and dramatic subtraction at that.
This model is compressed from Qwen3.6 35B MoE, with total parameters cut from 35B to 14B, yet the active parameters per inference remain 3B, identical to the original 35B. After Q4 quantization, it requires only 8.4GB of VRAM—barely runnable on an 8GB GPU and completely comfortable on 12GB.

MoE Architecture Basics: Why Is Such Dramatic Compression Possible?
MoE (Mixture of Experts) is a sparse activation architecture whose core idea is to replace a single feed-forward layer with multiple parallel "expert" sub-networks, activating only a few experts during each inference pass. The Router is a lightweight network responsible for deciding which experts to assign each input token to based on its features. Qwen3.6 35B MoE is designed with 35B total parameters but only 3B activated per pass, meaning the model has many experts but each token only passes through a few. The advantage of this design is that all parameters can be leveraged for learning during training, while only minimal computation is needed during inference. However, this also creates "uneven expert utilization"—some experts are frequently called upon (becoming "hot experts") while others are rarely activated (becoming "cold experts"). It's precisely this imbalance that makes dramatic compression possible.
Compression Method: REAP Pruning Strategy Explained
The model uses REAP (a MoE compression algorithm) for expert pruning, removing over 50% of experts in one pass. Here's the key finding: most experts in the original 35B are essentially "idle"—over 90% of tasks are completed by a small subset of experts, with most experts contributing almost nothing.
REAP (Routing-Expert Activation Pruning) is a structured pruning method specifically designed for MoE models. Unlike traditional weight pruning (removing individual unimportant parameters), REAP prunes at the expert granularity—it analyzes the router's historical activation statistics, identifies experts that are almost never selected across a large number of input samples, then removes these "zombie experts" entirely. The key advantage of this approach is that it doesn't disrupt the internal weight structure of retained experts, resulting in minimal performance loss.
There are two paths for MoE compression: merging experts or direct pruning. The merging path leads to severe performance degradation (losses of 35-40%), because averaging or weighted fusion of multiple experts' weights destroys the specialized knowledge each expert has learned. The pruning path—cutting experts that aren't working—retains 95.9% of coding capability, with only about 4% loss. This also validates a known issue in MoE training—load imbalance, where the router tends to repeatedly select a few "star experts" while large numbers of experts remain essentially idle after later training stages.

A New Paradigm: AI Training AI
Another highlight of this model is that the entire pruning and training process was autonomously completed by an AI Agent. From deciding which experts to cut, to data preparation, to training monitoring—everything was executed by an autonomous AI Agent named Steve, requiring no manual hyperparameter tuning. The developer believes this may be the future trend for distilled models—humans set the goals, AI completes the actual work.
Regarding training data, approximately 4,600 COT reasoning traces from Claude Fable were used, supplemented with Opus reasoning data and Qwen's native tool-calling data to maintain the model's native capabilities.
Positioning: General Assistant, Not a Coding Powerhouse
It needs to be clear that the 14B with 3B active parameters defines its ceiling. The gap from Fable is larger than with the 27B, making it unsuitable for complex coding tasks. Its positioning is as a lightweight general reasoning assistant—daily conversation, simple task processing, and basic reasoning.
Notably, this model is an uncensored version, with a KLD (divergence metric from the original model) of only 0.0015 (approximately 0.15%), meaning the removal of safety filters barely affects performance. KLD (Kullback-Leibler Divergence) is a classic information theory metric measuring the difference between two probability distributions. In the context of model uncensoring, it quantifies how much the modified model's output distribution deviates from the original. A KLD of 0.0015 means that for the vast majority of inputs, the uncensored version's output probability distribution is nearly identical to the original, differing only in the very few scenarios involving safety filtering. This indicates the uncensoring operation precisely modified only the safety alignment layer's behavior without "collateral damage" to the model's general reasoning capabilities.
The "Expert Redundancy" Problem in MoE Models Deserves Attention
The birth of this 14B model reveals a thought-provoking phenomenon: over 50% of experts in the 35B MoE are idle most of the time. What about larger MoE models? For architectures like MiniMax M3 with hundreds of billions of parameters, the experts actually doing work might only be 10%, yet they handle 90% of tasks.
This "expert redundancy" phenomenon means that MoE models' actual effective parameters may be far smaller than their stated values, and it opens enormous space for future model compression. From an academic perspective, this phenomenon shares similarities with the "Lottery Ticket Hypothesis"—within large neural networks, there exists a sub-network far smaller than the original that, when trained independently, can achieve performance comparable to the full network. MoE expert redundancy can be seen as a specific manifestation of the Lottery Ticket Hypothesis in sparse architectures. This also raises a deeper question: do current MoE training methods have fundamental efficiency problems? If most experts end up idle, is the compute spent training these experts wasteful? Future research directions may include dynamic expert growth (adding new experts only when needed) and more balanced routing strategies.
Selection Recommendations: 34B vs. 14B
- 34B 80-Layer: Suitable for users with sufficient VRAM (24GB+ recommended) who need coding/long-range tasks/complex reasoning, especially well-suited as a distillation base model
- 14B MoE: Suitable for users with limited VRAM (8-12GB) who need a lightweight general assistant—fast but with limited capability ceiling
- If choosing between Gemma3n 12B and this 14B MoE, the 14B is more attractive—although Gemma3n has inherently stronger architecture, the MoE's speed advantage combined with Qwen3.6's foundation gives the 14B a better actual user experience
These two models represent two directions the community is exploring at the boundaries of local deployment: scaling up for capability, and compressing down for accessibility. Regardless of direction, the core goal is enabling more people to get better AI experiences on limited hardware.
Key Takeaways
Related articles

DeepCell: One-Click AI Generation of Documents, Spreadsheets, and Slides
DeepCell tops Product Hunt with one-click generation of documents, spreadsheets, and slides, using the .deepcell format for linked updates, designed for System 2 tasks like modeling and sales reviews.

Doneas: 15-Minute Daily Accountability Calls That Keep Indie Developers From Procrastinating
Doneas is a daily accountability tool for indie developers: plan tasks on Monday, join a 15-minute call with five builders each day, and log deliveries on a public progress page. This article analyzes its core mechanics, effectiveness, and potential issues around retention and matching.

Fastlane 2.0: Fully Automated AI Ad Campaigns, From Creative to Optimization
Fastlane 2.0 is an AI ad automation tool: enter your website and it learns your brand, generates video and image ads, and runs and optimizes them on Meta, TikTok, Instagram, and YouTube.