RAG or Fine-Tuning? Diagnose the Failure First Before Swapping Models

Diagnose whether your LLM is failing at retrieval or behavior before choosing RAG or fine-tuning.
When an LLM application misbehaves, the right fix depends on where the failure occurs. This article proposes a three-layer diagnostic framework — retrieval, context, and generation — and introduces independent metrics like Recall@K and Groundedness to pinpoint the root cause. RAG addresses knowledge access failures; fine-tuning addresses behavioral failures. The article also covers production RAG components like permission-aware filtering and hybrid search, fine-tuning pitfalls like capability regression, and argues that the correct comparison unit is total cost per successful business task, not per-request inference cost.
When a large language model (LLM) application starts giving bad answers, an engineer's first instinct is often to reach for a bigger model, stuff more examples into the prompt, fine-tune on domain data, or plug in a vector database.
But each of these interventions solves a different problem. Using the wrong one only adds cost and complexity without improving results. This engineering practice article from SotaTek makes a clear, central argument: before changing the model, identify which layer the failure is occurring at.
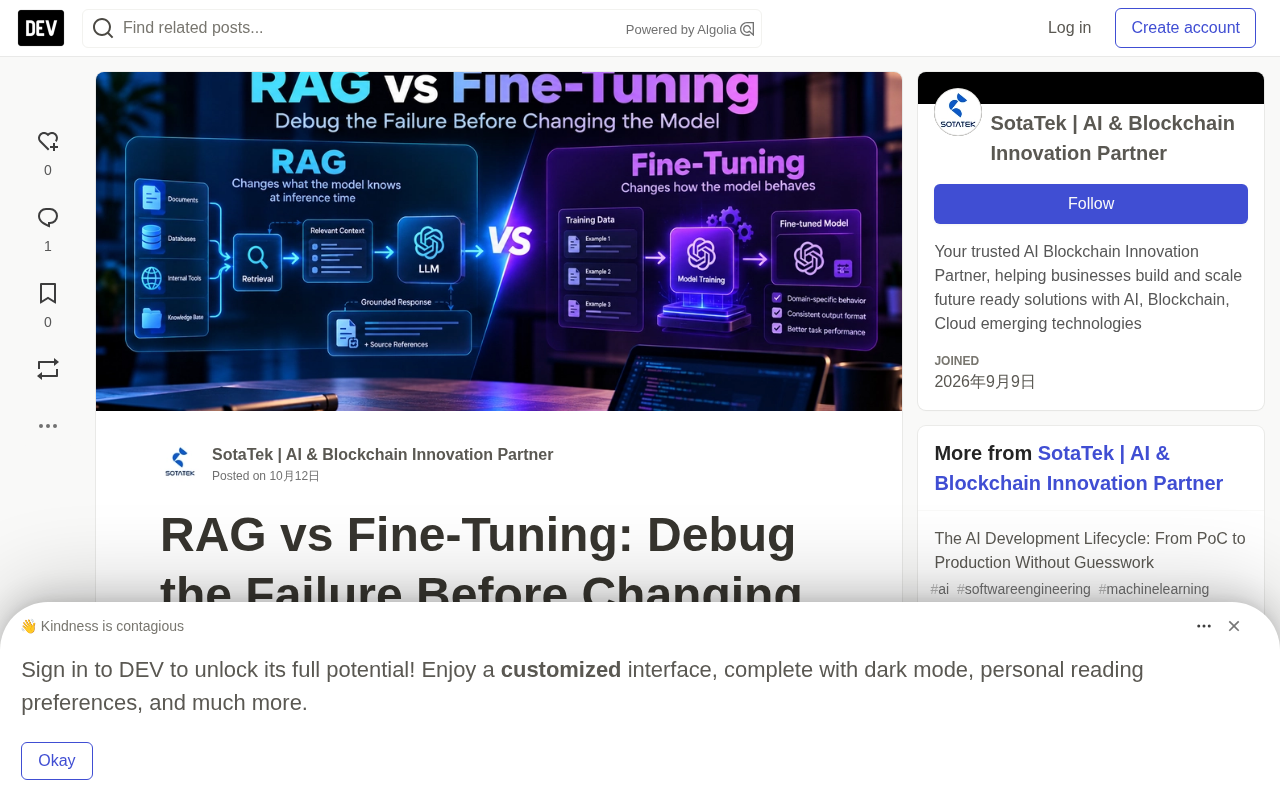
Two Types of Failure, Two Fundamentally Different Causes
The article cuts to the heart of the issue with two typical scenarios. First: an enterprise assistant gives outdated answers because the latest policy documents never reached the model. Second: a classification system has all the information it needs but repeatedly produces inconsistently formatted output.
These are fundamentally different problems. The first is a knowledge access problem — the model simply cannot retrieve the correct information. The second is a behavioral problem — the model has the information but doesn't process it as required.
Correspondingly, the two techniques change entirely different things:
- RAG (Retrieval-Augmented Generation) changes what information the model can access at inference time — model weights remain unchanged.
- Fine-Tuning changes the behavior the model has learned, reinforcing desired output patterns through additional training examples.
Understanding this distinction is a prerequisite for avoiding costly misdirection. Using fine-tuning to fix a retrieval failure is like hiring a smarter receiving clerk to fix a delivery system that isn't delivering packages.
Three-Layer Diagnosis: Find the Layer That's Actually Failing
The most practical framework in the article breaks the problem into three layers for systematic diagnosis:
Retrieval Layer
Diagnostic question: Did the system find the right evidence? If not, improve search, metadata, chunking, or reranking.
Chunking is the process of splitting documents into retrievable units in a RAG system, and it directly impacts retrieval quality. Chunks that are too small lose contextual semantics; chunks that are too large dilute vector similarity and allow irrelevant content to bleed in. Common strategies include fixed-size token splitting, semantic splitting by sentence or paragraph, and sliding windows with overlap to preserve context. Reranking takes the candidate chunks returned by an initial vector search and re-scores them using a dedicated ranking model (such as a Cross-Encoder) to improve the precision of what ultimately enters the context window. The two-stage architecture outperforms single-step retrieval because vector similarity excels at rapidly filtering large corpora, while Cross-Encoders — though more computationally expensive — can more precisely assess the semantic match between a query and a passage. When retrieval metrics like Recall@5 are low, optimizing chunking strategy and introducing reranking are often more effective than upgrading to a larger generative model.
Context Layer
Diagnostic question: Did the relevant evidence actually make it into the model's context window? If not, optimize context selection and prompt construction.
Generation Layer
Diagnostic question: Did the model correctly use the evidence it received? Only if this is the failure point should you consider improving the prompt, adding validation, or evaluating fine-tuning.
This distinction prevents an extremely common mistake. Imagine an enterprise assistant that must answer questions about internal security policies. The correct policy exists in the knowledge base, but retrieval consistently ranks it outside the top five results. Switching to a larger LLM might generate more convincing-sounding answers, but it cannot reliably use evidence that never entered the context. The fix belongs in the retrieval pipeline, not in model training.
Establish a Baseline First, Then Talk About Changes
Before introducing RAG or fine-tuning, the article emphasizes the need to establish a baseline using representative test cases. The authors offer a set of illustrative metrics:
| Metric | Baseline |
|---|---|
| Answer Accuracy | 71% |
| Groundedness | 68% |
| Format Compliance | 91% |
| Retrieval Recall@5 | 62% |
Even this small sample of data already points the way: retrieval recall is weak, while format compliance is already solid. This suggests the system is more likely failing because it can't retrieve the information it needs, not because of behavioral problems. Without further evidence, fine-tuning should not be the first intervention.
The key principle is: evaluate the retrieval layer and generation layer independently. The article provides simplified evaluation code that first computes recall_at_5, then generates answers separately. Without this separation, a single answer quality score can only tell you "it failed" — not where to look for the cause.
Recall@K is the core metric for measuring retrieval quality. It represents the proportion of truly relevant documents that are successfully found within the top K results returned by the system. For example, Recall@5 = 62% means that in 100 queries, 62 of them had the correct answer appear within the top 5 retrieved results. This metric is independent of generation quality — even if the generation layer performs perfectly, the system is doomed to fail if the relevant document never makes it into the top K. Groundedness measures what proportion of the model's generated answers can be supported by the retrieved context documents, and is used to detect hallucination. Tracking these two metrics separately allows you to accurately pinpoint whether a problem lies in the retrieval pipeline or the generative model, rather than blurring two distinct failure modes together under a single "answer accuracy" score.
Production-Grade RAG Is Far More Than a Vector Database
A basic RAG implementation is often depicted as: documents → vectorization → vector store → LLM. That's enough to demonstrate the concept, but production retrieval typically requires document parsing, chunking and metadata enrichment, vector/lexical/hybrid search, query rewriting, permission-aware filtering, reranking, context selection, citation mapping, and retrieval and groundedness evaluation.
The article specifically highlights a security consideration for multi-tenant enterprise applications: retrieval must enforce user permissions before documents ever reach the model. Post-hoc filtering of the generated answer is not a substitute for preventing unauthorized context from entering the generation pipeline at the source. Authorization must be enforced by a trusted application layer — it must never be delegated to the model or a prompt instruction.
In short: if the right information is theoretically available but retrieval quality is poor, optimize the retrieval system before assuming the model needs fine-tuning.
Hybrid Search combines the strengths of vector retrieval (based on semantic similarity) and lexical retrieval (such as BM25, based on keyword matching). Pure vector retrieval excels at semantic understanding, but can exhibit "semantic drift" with exact terms, product codes, and proper nouns. Lexical retrieval like BM25 is more sensitive to exact matches but cannot capture synonyms or semantic proximity. Production systems typically merge results from both approaches using methods like RRF (Reciprocal Rank Fusion) or weighted summation, balancing semantic understanding with precise matching. Query Rewriting expands or transforms the user's original question before retrieval — for example, rephrasing a colloquial question into language closer to the document's terminology, or decomposing a compound question into multiple sub-queries. Both techniques operate at the retrieval stage and are worth trying before resorting to fine-tuning.
When Fine-Tuning Is Actually Warranted
Fine-tuning genuinely deserves evaluation when the model has received adequate information but repeatedly fails to complete the task as required. Typical signals include:
- Output schema remains inconsistent despite clear instructions
- The same professional classification task produces unstable results
- Domain terminology is repeatedly misinterpreted
- Few-shot examples are bloating the prompt
- A smaller model needs to replicate the behavior of a larger one
But fine-tuning should never automatically become the next step. Before training, check whether the failure can be resolved with clearer instructions, structured output constraints, better examples, or simpler application logic.
If fine-tuning is genuinely necessary, keep training, validation, and final evaluation sets strictly isolated (the article suggests an approximate 70/10/20 split). For production data, split by an appropriate unit — customer, document, time period, or source record — to prevent near-duplicate samples from leaking across sets. After training, evaluate both the improvement in target behavior and regression in existing capabilities — a model that improved formatting but lost general-purpose ability may not be worth the tradeoff.
Compare Total System Cost, Not Just Model Cost
The article reminds us that RAG and fine-tuning simply shift engineering and operational costs to different places.
- RAG adds retrieval infrastructure and runtime overhead (retrieval and reranking add steps; retrieved context can be large), but naturally supports knowledge updates and source attribution.
- Fine-tuning adds dataset preparation, training, validation, artifact management, and model version maintenance. Knowledge updates may require another training run, and model weights provide no inherent attribution capability.
The right comparison unit is total cost per successful business task, including retries, human review, infrastructure, and operations. Lower inference cost per request does not necessarily equal lower cost per successful result.
When Both Techniques Are Necessary
Some applications genuinely have both problems. Consider an enterprise compliance assistant that needs to retrieve current regulations and internal policies (RAG provides current, attributable knowledge) and apply organization-specific classification schemes to produce structured conclusions (fine-tuning can help if evaluation shows prompting alone is insufficient).
They operate at different layers and can be combined. But combination must be an evidence-based decision — even after successful fine-tuning, irrelevant retrieval context can still introduce noise. The authors recommend comparing the baseline, RAG-only, fine-tuning-only, and hybrid approaches on the same held-out evaluation set. Keep the hybrid architecture only when the improvement justifies the added complexity.
A Practical Decision Sequence
The article concludes with a clear decision path:
- Start with the base model. If prompt engineering and output constraints meet your evaluation targets, ship it.
- If not, diagnose the failure: is it missing or outdated knowledge, or inconsistent behavior?
- Knowledge problem → evaluate RAG first; behavioral problem → evaluate fine-tuning.
- Both problems exist → evaluate each intervention independently before considering combining them.
- If the base model already meets acceptance criteria, don't add infrastructure without a quantifiable reason.
Ultimately, RAG and fine-tuning are not two competing approaches to making an LLM "smarter" — they address different failure modes. RAG changes the evidence available to the model; fine-tuning changes the behavior the model has learned. The real engineering challenge is determining which layer is failing and using data to prove that your intervention actually improves results. That requires representative evaluation data, clear metrics, reliable retrieval, controlled access, regression testing, and production monitoring — not just picking a model or a vector database.
Related articles

Chain of Thought Isn't Just for AI: How Humans Can Use CoT to Improve Thinking Quality
Chain of Thought isn't just a prompt trick for large models. Starting from a Hacker News discussion, this article analyzes why CoT works for human thinking too, breaks down actionable ways to transfer it, and highlights the key differences between human CoT and machine CoT.
Cloudflare Teams Up with OpenAI: Closi…
Cloudflare Teams Up with OpenAI: Closing the Loop from Vulnerability Discovery to Defense with AI
Cloudflare uses OpenAI Daybreak to investigate security vulnerabilities and generate reviewable remediation plans, while developers use Codex to boost coding efficiency and quality.

Orca Multi-Agent Orchestration in Practice: A Guide to Parallel Collaboration with Claude and Codex
Orca is Stable AI's free open-source agent workbench supporting 34 agents like Claude Code and Codex in parallel. Learn its Git worktree isolation, multi-model orchestration, and mobile management.