RaRe: Reconstructing Open-Vocabulary Scene Graph Relation Representations with Reasoning Chains
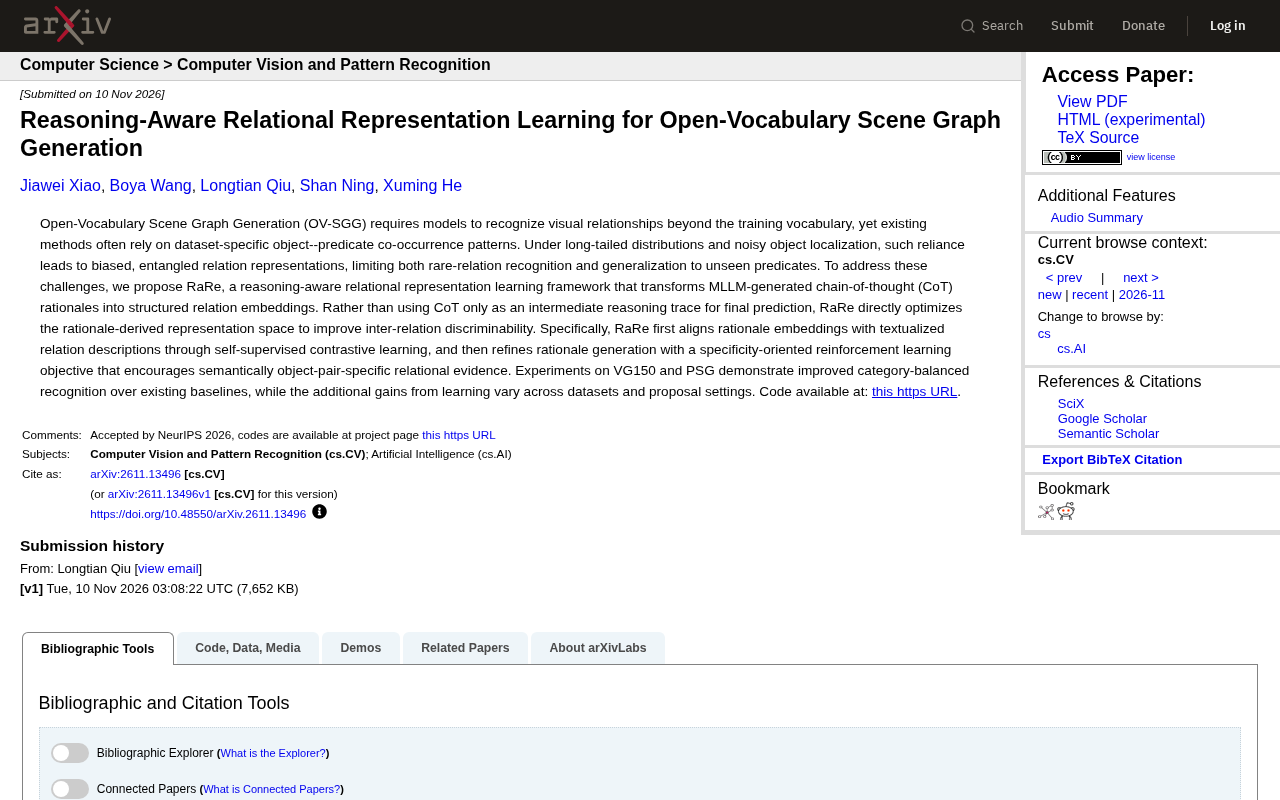
RaRe builds optimizable relation representations from MLLM chain-of-thought rationales, escaping co-occurrence dependence in open-vocabulary scene graph generation.
This article introduces RaRe, a framework for open-vocabulary scene graph generation. Existing methods rely on dataset-specific object-predicate co-occurrence statistics, which under long-tailed distributions and localization noise yield biased, entangled relation representations. RaRe instead converts MLLM chain-of-thought rationales into structured embeddings aligned with textualized relation descriptions via contrastive learning, and refines rationale generation with a specificity-oriented reinforcement learning objective. It outperforms baselines on VG150 and PSG in class-balanced recognition, though gains vary across datasets and proposal settings.
Open-vocabulary scene graph generation (OV-SGG) aims to enable models to recognize visual relationships beyond the training vocabulary. Most existing methods rely on dataset-specific object-predicate co-occurrence patterns. Under the interference of long-tailed distributions and object localization noise, this reliance leads to biased and entangled relation representations, which both limits the recognition of rare relationships and weakens generalization to unseen predicates. To address this problem, researchers propose RaRe—a reasoning-aware relation representation learning framework that transforms chain-of-thought (CoT) rationales generated by multimodal large language models (MLLMs) into structured relation embeddings, and directly optimizes the representation space derived from rationales, rather than merely treating CoT as intermediate reasoning traces before prediction.
Root Cause: Path Dependency on Co-occurrence Patterns
Traditional OV-SGG methods typically count object-predicate co-occurrence frequencies from datasets to construct relational priors. The hidden risk of this approach is that, under long-tailed distributions, the co-occurrence signal for rare predicates is inherently sparse, making the model more easily biased by high-frequency combinations; moreover, object localization noise further contaminates co-occurrence statistics, causing relation representations to become semantically entangled. As a result, the model is overconfident about common relationships but lacks discriminative power for rare and unseen relationships. The starting point of RaRe is precisely to cut off this path dependency on dataset-specific co-occurrence patterns and instead leverage the reasoning capability of MLLMs to generate relation evidence relevant to specific object pairs.
Open-vocabulary scene graph generation (OV-SGG) is a sub-setting of scene graph generation: during training, the model can only see a limited vocabulary of object categories and predicates (relationships), while at test time it needs to recognize objects or relationships outside the vocabulary. In contrast, the traditional closed-set setting assumes that testing and training share the same label space. The difficulty of the open-vocabulary setting is that the model cannot rely on a classification head learned for each predicate, but must transfer knowledge of seen relationships to unseen relationships via semantic embeddings, vision-language pretraining, and similar means. For this very reason, the model can easily degenerate into memorizing object-predicate co-occurrence statistics from the training set—precisely the origin of the co-occurrence path dependency problem described in this article.
Long-tailed distribution refers to a distribution in which category frequencies in the data are extremely imbalanced: a few high-frequency predicates (such as "on" and "has") occupy a large number of samples, while many rare predicates have only sparse annotations. Under conventional training objectives such as cross-entropy, models tend to prioritize fitting high-frequency categories to obtain lower average loss, and the gradient signal for rare categories is drowned out. In scene graph tasks, this problem is further amplified by the subjectivity and sparsity of relationship annotations themselves—the same object pair may have only some relationships annotated, leading to "missed-label" noise beyond the long tail.
The RaRe Framework: From Rationales to Structured Embeddings
The core design of RaRe consists of two steps. First, through self-supervised contrastive learning, it aligns the CoT rationale embeddings generated by the MLLM with textualized relationship descriptions, so that rationale representations are close to the corresponding relationship semantics in semantic space. Second, it employs a specificity-oriented reinforcement learning objective to refine rationale generation, encouraging the model to produce relationship evidence that is targeted at specific object pairs and semantically more discriminative, rather than generic descriptions. Unlike approaches that treat CoT merely as reasoning traces, RaRe directly optimizes the representation space derived from rationales to improve inter-relationship discriminability. This idea elevates reasoning chains from an "explanation tool" to a "representation learning signal," which is a methodological shift worth noting.
Chain-of-Thought (CoT) refers to a prompting and generation paradigm that lets large language models output a series of intermediate reasoning steps before giving the final answer. In vision-language tasks, multimodal large language models (MLLMs) can generate natural-language rationales based on image content, such as "these two objects are spatially adjacent, and one supports the other." CoT is typically used as a reasoning scaffold to improve prediction accuracy, and the reasoning process is discarded after the answer is output. The key difference of RaRe is that it encodes these rationale texts into vectors, making them trainable and optimizable representations, so that the reasoning process itself participates in representation learning rather than only serving final classification.
Contrastive learning is a class of self-supervised representation learning methods: it learns discriminative representations by pulling positive sample pairs closer and pushing negative sample pairs farther apart in embedding space, with InfoNCE loss as a typical example. RaRe uses it to align the embeddings of MLLM rationales with textualized relationship descriptions (such as semantic descriptions of predicates), so that rationale vectors fall near relationship semantics. The reinforcement learning objective is used to refine the generation process: using "whether the rationale is discriminative for the specific object pair" as the reward signal, it updates the generative model via policy-gradient-style methods, making it tend to produce targeted, informative rationales rather than templated generic descriptions.
Experimental Performance and Boundaries
On the two datasets VG150 and PSG, RaRe outperforms existing baselines in class-balanced recognition. However, the paper also honestly points out that the additional gains from learning vary across datasets and proposal settings. This detail deserves attention: it shows that relation representations based on reasoning chains do not reliably deliver benefits in all scenarios, and their effectiveness is related to factors such as data distribution and candidate box quality. For engineering teams hoping to reproduce or transfer this method, this means they need to evaluate benefits according to their own data characteristics, rather than directly assuming that reasoning-chain enhancement will necessarily bring consistent improvements. The code has been released on the project page for community verification.
Significance for Open-Vocabulary Relationship Understanding
The value of RaRe lies in providing an alternative path that does not depend on dataset-specific co-occurrence statistics: using MLLM reasoning rationales to construct relation representations, and then polishing this representation space with the dual objectives of contrastive learning and reinforcement learning. For open-vocabulary scene graph generation, this directly addresses the core pain points of rare relationship recognition and generalization to unseen predicates. Of course, the quality of rationale generation, the stability of the reinforcement learning objective, and the uneven gains across datasets remain questions that future work needs to answer.
One-line Summary
RaRe uses MLLM chain-of-thought rationales to build optimizable relation representations, escaping co-occurrence dependence to improve open-vocabulary scene graph generation.
Paragraph Summary
This article introduces RaRe, a new framework for open-vocabulary scene graph generation (OV-SGG). Existing methods rely on dataset-specific object-predicate co-occurrence statistics; under long-tailed distributions and object localization noise, this leads to biased and entangled relation representations, weakening rare relationship recognition and generalization to unseen predicates. RaRe instead uses multimodal large language models to generate chain-of-thought rationales, aligns rationale embeddings with textualized relationship descriptions via self-supervised contrastive learning, and refines rationale generation with a specificity-oriented reinforcement learning objective, directly optimizing the representation space derived from rationales rather than treating CoT merely as reasoning traces. On VG150 and PSG, RaRe outperforms baselines in class-balanced recognition, but the paper also notes that gains vary with datasets and proposal settings, suggesting that the method's benefits are not universally stable.
Related articles
Lewis's Scoring Completely Out of Control: An Absurd Observation of Gaming Entertainment
Lewis's scoring rules completely out of control in gameplay, switching from rewards to penalties at will, even offsetting deductions and additions to zero. This article analyzes the entertainment logic and rule transparency issues behind such absurd scoring.
The Democrats' Leftward Path for 2028: Blurry Labels and Backroom Games
Using Florida candidate Angie Nixon's case, this analysis examines the Democrats' leftward path for 2028: the mismatch between national media label wars and local voter perception, and how elite donations, polls, and endorsements will decide candidates' fates before the 2027 primary.
One Glass of Orange Juice Contains a Shocking Amount of Sugar: How Continuous Glucose Monitoring Changes Dietary Perception
A glass of orange juice contains up to eight teaspoons of sugar. Continuous glucose monitoring reveals individualized dietary responses. This article explores the link between blood sugar and brain health and how CGM helps ordinary people make smarter dietary choices.