Real-Time Decision-Making in Digital Twins: System-Level Integration of ML and Uncertainty Quantification

The review argues that digital twin decision-making should adopt a system-centric perspective, coordinating perception, estimation, computation, and adaptation.
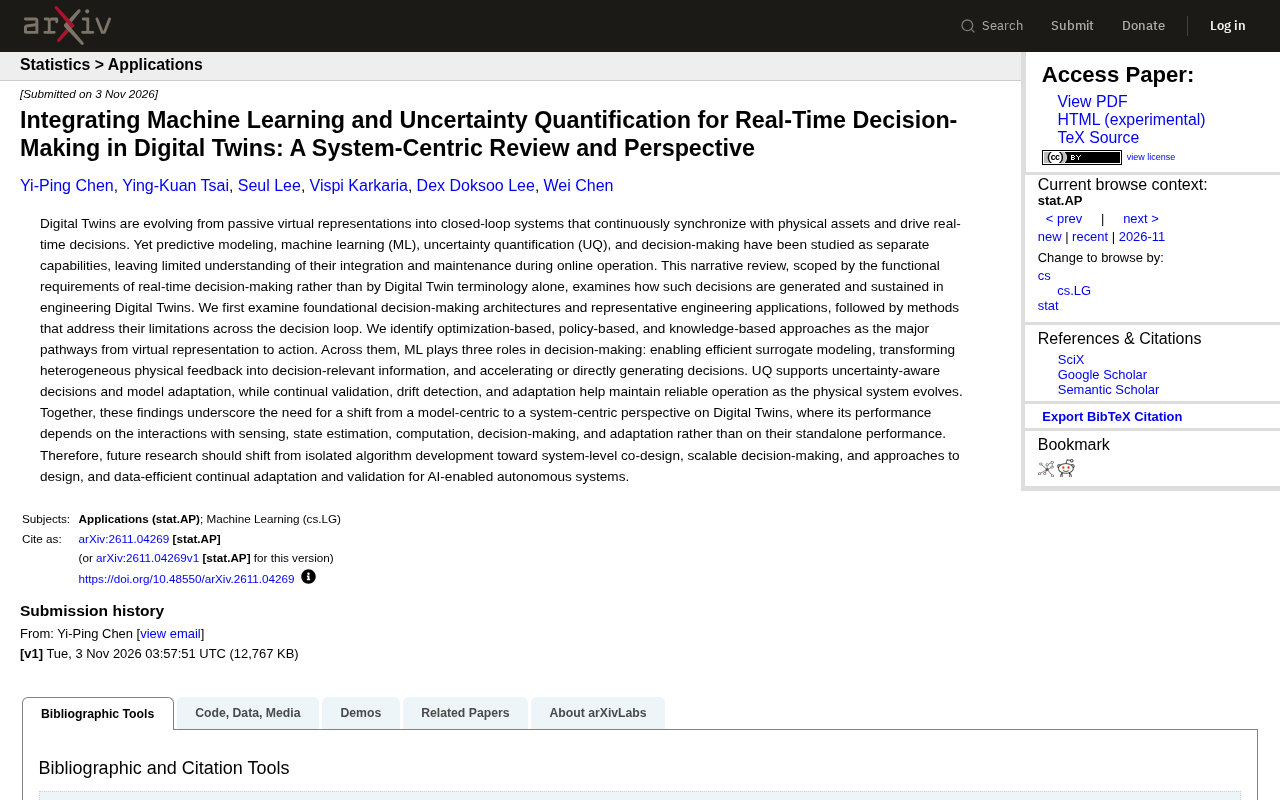
This article reviews how real-time decisions are generated and sustained in engineering digital twins, arguing for a shift from a model-centric to a system-centric perspective. It identifies three pathways from virtual representation to action—optimization-based, policy-based, and knowledge-based methods—and notes that machine learning serves three roles: surrogate modeling, heterogeneous feedback transformation, and direct decision generation. Uncertainty quantification, continuous validation, and drift detection are key supports for long-term online operation but are often marginalized. The authors stress that digital twin performance depends on interactions among perception, state estimation, computation, decision-making, and adaptation, with future research focusing on system-level co-design, scalable decision methods, and data-efficient continuous adaptation.
Digital twins are evolving from passive virtual representations into closed-loop systems that continuously synchronize with physical assets and drive real-time decision-making. However, predictive modeling, machine learning, uncertainty quantification, and decision-making have long been studied as separate capabilities, leaving little understanding of how they are integrated and maintained during online operation. A narrative review, taking the functional requirements of real-time decision-making as its entry point, systematically surveys how decisions are generated and sustained in engineering digital twins, and explicitly argues that the performance of a digital twin depends on the interactions among perception, state estimation, computation, decision-making, and adaptation—not on the isolated performance of individual modules.
Three Major Pathways from Virtual Representation to Action
The review first examines foundational decision architectures and representative engineering applications, then analyzes approaches targeting limitations at each stage of the decision loop. The study identifies three main pathways from virtual representation to actual action: optimization-based methods, policy-based methods, and knowledge-based methods. Each pathway has its applicable scenarios and faces its own constraints in terms of real-time performance, interpretability, or generalization capability.
The value of this taxonomy lies in elevating digital twin decision-making from a discussion of "which algorithm to use" to a system-level perspective of "how the decision loop closes." In engineering practice, a single method often struggles to cover the entire chain from state perception to action execution; the key to real-time decision-making lies in method combination and switching mechanisms.
The Three Roles of Machine Learning
Across the three decision pathways, machine learning plays three distinct roles: first, enabling efficient surrogate modeling to approximate complex physical simulations at lower computational cost; second, transforming heterogeneous physical feedback into decision-relevant information; and third, accelerating the decision process or even directly generating decisions. These three roles correspond to the needs of digital twins at different time scales—from offline training to online inference to real-time response.
The significance of surrogate modeling lies in alleviating the tension between high-fidelity simulation and real-time requirements; heterogeneous feedback transformation addresses the difficulty of directly using multi-source sensor data for decision-making; and direct decision generation pushes machine learning from an auxiliary tool to a decision-making entity. Together, these three form the complete positioning of ML within the digital twin decision loop.
Surrogate Modeling refers to the technique of replacing high-fidelity physical simulations (such as finite element analysis or CFD) with computationally inexpensive approximate models. Although high-fidelity simulations are accurate, a single solve often takes minutes to hours, making them unable to meet the millisecond-to-second response requirements of online decision-making in digital twins. Surrogate models typically take the form of neural networks, Gaussian processes, or reduced-order models: high-fidelity simulations are first used to generate training data, and a fast approximator is then trained offline. The core trade-off is between accuracy and speed: surrogate models sacrifice a small amount of accuracy for orders-of-magnitude acceleration, making real-time optimization and online inference possible. In digital twins, surrogate modeling is often the bridge connecting physical simulation and the real-time decision loop.
Uncertainty Quantification: An Underestimated Decision Support
The review points out that uncertainty quantification supports uncertainty-aware decision-making and model adaptation. As physical systems continuously evolve, continuous validation, drift detection, and adaptive mechanisms together maintain reliable operation. This set of capabilities is often marginalized in algorithmic research, yet it is a necessary condition for long-term online operation of digital twins.
Drift in physical systems is the norm rather than the exception. Sensor aging, changes in operating conditions, and equipment wear all cause models to gradually deviate from reality. Without drift detection and continuous validation, even the most accurate initial model will fail during operation. Here, uncertainty quantification is not merely an accuracy metric but also a signal source that triggers model updates and more conservative decision-making.
From Model-Centric to System-Centric
The core argument of the review is a shift in perspective: from a model-centric view of digital twins to a system-centric view. The former focuses on the accuracy of individual models, while the latter focuses on the quality of interactions among perception, state estimation, computation, decision-making, and adaptation. This shift means that evaluating a digital twin cannot rely solely on prediction error but must also consider the closed-loop performance of the decision loop under real operating conditions.
This view has direct implications for engineering practice. System-level co-design, scalable decision methods, and data-efficient continuous adaptation and validation are identified as key directions for future research. In other words, the research focus should shift from isolated algorithm development to system-level engineering for AI-enabled autonomous systems.
Drift Detection refers to techniques for monitoring whether the distribution of operational data or model prediction residuals exhibits systematic shifts. In engineering digital twins, sources of drift include sensor aging and calibration drift, operating conditions outside the training distribution, and changes in physical parameters due to equipment wear. Common methods include statistical tests (such as the KS test and the Page-Hinkley test), error-based monitoring windows, and distribution distance metrics. Once significant drift is detected, the system must trigger model retraining, parameter adaptation, or more conservative decision-making strategies. Continuous validation, beyond drift detection, periodically evaluates model performance on the latest data; together, the two constitute the health monitoring mechanism for long-term online operation of digital twins. Without this layer, model accuracy will silently degrade as the physical system evolves.
System-Level Co-Design emphasizes that perception, state estimation, computation, decision-making, and adaptation should be jointly designed as a whole, rather than independently optimized and then assembled. The theoretical basis is that the closed-loop performance of a digital twin is the result of interactions among all stages, and a combination of locally optimal modules does not necessarily produce a globally optimal decision loop. For example, improved perception accuracy may increase latency, which in turn drags down real-time decision-making; conversely, more conservative decision algorithms affect the data requirements for state estimation. System-level co-design requires explicitly defining the interfaces, time scales, and responsibility boundaries of each module at the architectural level, and using closed-loop metrics (rather than single-module error) as the evaluation baseline. This stands in sharp contrast to the traditional paradigm of studying predictive modeling, machine learning, and uncertainty quantification separately.
Implications for Engineering Practice
For teams building digital twins, this review suggests three actionable checkpoints. First, the choice of decision pathway should match real-time requirements; optimization, policy, and knowledge methods each have their applicable time scales. Second, the role of machine learning needs to be explicitly defined in the system architecture to avoid blurring responsibilities between surrogate modeling and decision generation. Third, drift detection and continuous validation should be incorporated into system design as first-class citizens rather than after-the-fact patches.
The competitiveness of digital twins ultimately manifests in the reliability of closed-loop decision-making. Co-designing ML, uncertainty quantification, and decision-making within a single system framework is the viable path from virtual representation to real-time action.
One-line Summary
The review argues that digital twin decision-making should shift to a system-centric perspective, coordinating perception, estimation, computation, and adaptation.
Paragraph Summary
This article reviews the mechanisms by which real-time decisions are generated and sustained in engineering digital twins, with a core argument for shifting from a model-centric to a system-centric perspective. It identifies three pathways from virtual representation to actual action—optimization-based, policy-based, and knowledge-based methods—and notes that machine learning plays three roles: surrogate modeling, heterogeneous feedback transformation, and direct decision generation. Uncertainty quantification, continuous validation, and drift detection are regarded as key supports for long-term online operation yet are often marginalized in algorithmic research. The authors emphasize that digital twin performance depends on the quality of interactions among perception, state estimation, computation, decision-making, and adaptation, and that future research should focus on system-level co-design, scalable decision methods, and data-efficient continuous adaptation.
Related articles
Hugging Face Open Together: The Carnival of Open Source AI and a Declaration of Decentralization
Hugging Face Open Together brings together global developers to showcase demos, emphasize open source AI as a public resource, and declare that the AI revolution must not be centralized.

Building a Netflix-Style Media Server with Claude: Just 15MB
A developer built Holyarrs, an all-in-one home media server app with Claude, just 15MB in size and ~70MB idle memory, consolidating six tools like Sonarr and Radarr.

A Hilarious Record of 0.5B Small Model Conversations Going Off the Rails: Why Is It Always Obama?
Reddit users share hilarious conversations with Qwen 0.5B small models that frequently derail to Obama, revealing the limits of small models in common-sense reasoning and the impact of quantization.