Reddit Hot Debate: Is LLM Overhyped? An Algorithmic Dispute Sparked by a Meme

A Reddit meme sparks discussion on whether LLMs are overhyped in vision tasks such as object tracking.
Starting from the Reddit meme "LLM = Overhyped," the article explores the phenomenon that large language models may be overhyped in computer vision video tasks (especially object tracking). The author points out that LLMs' core strengths in language understanding and generation are naturally mismatched with pixel-level visual localization; specialized vision algorithms (such as correlation filters and Siamese networks) still have irreplaceable advantages in real-time performance, interpretability, and deployment cost. The spread of the meme reflects the community's counter-reaction to the "LLM is omnipotent" narrative, reminding practitioners that technology selection should return to task constraints and avoid path dependence driven by hype. Ultimately, it advocates putting LLMs back in the positions where they excel while giving specialized algorithms the space they deserve.
Recently, a meme titled "LLM = Overhyped" appeared on Reddit, with the poster explicitly noting "meme only, plz take nothing personally," attempting to raise a serious issue in a lighthearted way: In computer vision video tasks (especially object tracking), are large language models being overhyped?
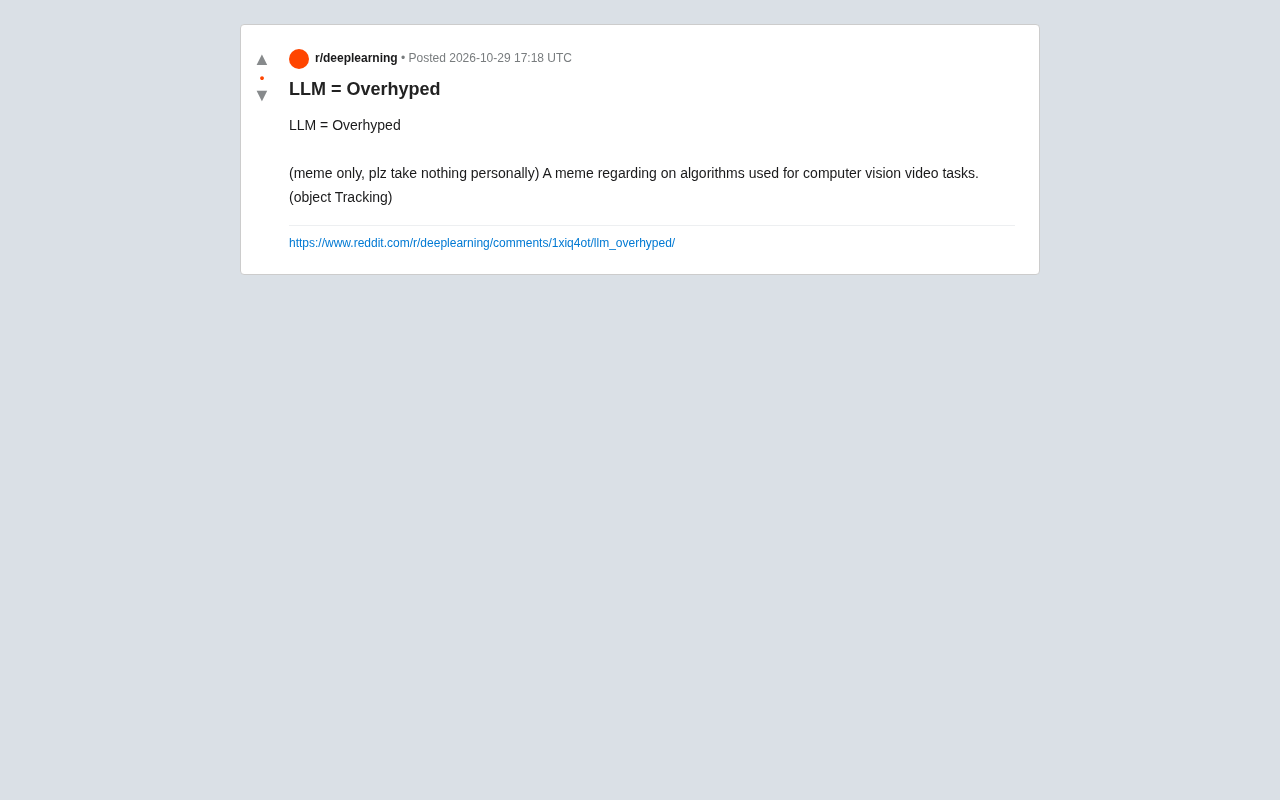
The image itself provides no data or conclusions, but it precisely taps into a brewing industry sentiment: the halo of LLMs is spilling over into areas they are not good at, and this spillover may cause algorithms truly suited for specific tasks to be overlooked.
The Real Sentiment Behind the Meme
The poster explicitly limited the discussion to "algorithms used for computer vision video tasks (object Tracking)," which is worth noting. Object tracking is a task with extremely high demands for temporal consistency, spatial localization accuracy, and real-time performance. Traditional methods (such as correlation filters, Siamese networks) and specialized vision models have long dominated.
Applying LLMs to such tasks often requires additional modality alignment and complex prompt engineering, yet the results may not outperform lightweight specialized models. The subtext of the meme is: when the entire industry focuses its attention on LLMs, those algorithms that are more efficient and controllable on vertical tasks are marginalized.
Object Tracking is a classic task in computer vision, referring to continuously locating and identifying a specific target (such as a pedestrian or vehicle) in a video sequence. Mainstream methods fall into two categories: generative and discriminative, with the latter represented by correlation filters (such as KCF) and Siamese networks (such as SiamFC, SiamRPN). Correlation filters use frequency-domain computation for high-speed tracking, while Siamese networks learn target appearance matching through a two-branch structure. These methods have small parameter counts and low inference latency, and are widely deployed in embedded devices and real-time scenarios. The core challenges of object tracking include occlusion, deformation, fast motion, and background interference. Solving these problems relies on fine-grained modeling of spatial information across consecutive frames, not on language priors.
Where Are the Boundaries of LLM Capabilities
The core strengths of LLMs lie in language understanding, generation, and cross-task generalization. Their training objectives do not naturally align with pixel-level visual localization. In object tracking scenarios, models need to handle challenges across consecutive frames such as occlusion, fast motion, and appearance changes. Solving these problems depends on fine-grained modeling of spatial information, not language priors.
This does not mean LLMs are disconnected from vision tasks—multimodal large models have indeed made progress in tasks such as video understanding and scene description. But there is a gap between "can be used" and "works well." Treating LLMs as a master key can easily lead to path dependence in technology selection.
Multimodal LLM refers to large-scale pretrained models that can simultaneously process modalities such as text, images, and video. Typical representatives include GPT-4V, LLaVA, Video-LLaMA, etc. They usually map images to features through visual encoders and then align them with language models, thereby achieving tasks such as visual question answering and video description. However, such models have limited performance on pixel-level localization tasks (such as bounding box regression in object tracking), because their training objectives emphasize semantic understanding rather than spatial accuracy. In addition, multimodal LLMs have high inference costs and large latency, making it difficult to meet the stringent real-time requirements of tracking tasks. Therefore, although multimodal LLMs have expanded the boundaries of vision tasks, specialized vision models remain a more pragmatic choice in scenarios requiring high-frequency, precise localization.
The Overlooked Specialized Algorithms
The poster specifically mentioned object tracking, hinting at a more pragmatic approach: on specific tasks, algorithms designed with targeted optimization often achieve more stable performance at lower computational cost. Such methods are highly interpretable and have low deployment barriers, and they remain the mainstay in scenarios such as industrial quality inspection, security surveillance, and autonomous driving perception.
The spread of the meme itself shows that there is a counter-reaction in the community against the "LLM is omnipotent" narrative. This backlash may not be entirely rational, but it reminds practitioners: technology selection should return to the task itself, rather than being led by hype.
Rationally Viewing the Value of Hype
Voices saying LLMs are overhyped are not new, but appearing in meme form on Reddit reflects a broader community sentiment. For developers, rather than arguing about whether LLMs are overhyped, it is better to focus on a more practical question: under given task constraints, which solution has the lowest overall cost and the most controllable risk?
Hype will recede, but task requirements will not. Putting LLMs back in the positions where they excel, while giving specialized algorithms the space they deserve, may be the attitude this meme most wants to convey.
One-line Summary
A Reddit meme sparks discussion on whether LLMs are overhyped in vision tasks such as object tracking.
Paragraph Summary
The article starts from the Reddit meme "LLM = Overhyped" and explores the phenomenon that large language models may be overhyped in computer vision video tasks (especially object tracking). The author points out that the core strengths of LLMs lie in language understanding and generation, which are naturally mismatched with pixel-level visual localization; specialized vision algorithms (such as correlation filters and Siamese networks) still have irreplaceable advantages in real-time performance, interpretability, and deployment cost. The spread of the meme reflects the community's counter-reaction to the "LLM is omnipotent" narrative, reminding practitioners that technology selection should return to task constraints and avoid path dependence driven by hype. Ultimately, it advocates putting LLMs back in the positions where they excel while giving specialized algorithms the space they deserve.
Related articles
Build a Reasoning Model from Scratch: An 11-Hour Open-Source Course Breakdown
Sebastian Raschka releases a free 8-episode, ~11-hour video course teaching you to build a reasoning model from scratch with Python and PyTorch—from a small Qwen3 model through Verifier, Inference Time Scaling, GRPO, and distillation, with open-source code on GitHub.
An 11-Hour Reasoning Model Course in Practice: How Small Models Learn to Think
Starting from Sebastian Raschka's 11-hour reasoning model course and HN buzz, this analyzes small-model training, legal text version control, Anthropic data policy, and product reliability reviews.

Lightpanda: A Headless Browser Built for AI and Automation
Lightpanda is a headless browser built from scratch in Zig for AI and automation, with 37,852 GitHub stars. This analysis covers its technical approach, design choices, and use cases.