Reflection AI's Open-Source Model Beam: Why It Ranks Last on Its Own Leaderboard

Reflection AI releases 501B-parameter Beam, competing on efficiency rather than raw scores against DeepSeek and Kimi.
Reflection AI, backed by NVIDIA and others with $2B in funding, released its first open-source model Beam: 501B total parameters, 23B active, Sparse MoE architecture focused on coding and agentic tasks. Most striking is that competitors like DeepSeek, Kimi, and GLM score higher on Beam's own benchmark table — numbers Reflection filled in themselves. Rather than hiding this gap, the company reframes the competition around efficiency, claiming 3–4× inference compute savings versus GLM. The training investment is massive, with over 100 million RL rollouts generated. NVIDIA simultaneously acted as investor, hardware supplier, and the competitor whose model Beam beats. Weights are not yet publicly available.
Reflection AI, backed by NVIDIA, has released its first open-source model, Beam, with 501 billion total parameters. This should have been a standard large model launch announcement. But what actually sparked 321 points and 92 heated comments on Hacker News was an unusual detail: in its own press release, competitors like DeepSeek, Kimi, and GLM scored higher than Beam — and Reflection filled in those numbers themselves.
A company that raised $2 billion and spent over a year building its first release openly wrote "others are better than me" on its own report card. Is this honesty, or is there something more calculated going on?
Who Is Reflection AI: The Team That Declared "The Open-Source Window Is Closing"
Reflection AI published a manifesto on its official blog titled Building Frontier Open Intelligence, with the core mission of making frontier open-source intelligence accessible to everyone. In the same post, it announced a $2 billion funding round from a formidable list of investors: NVIDIA, Sequoia, Lightspeed, DST, Citi, and Eric Schmidt.
The team's background is equally impressive. According to the official description, members have contributed to landmark projects including PaLM, Gemini, AlphaGo, AlphaCode, and AlphaProof, as well as ChatGPT and Character.AI. Think of it as a group of researchers who left major lab environments and decided to take the open-source path.
Their stated reasoning carries a strong sense of urgency. The manifesto argues that frontier capabilities are becoming concentrated in a handful of closed-source labs, and that if this continues, capital, compute, and talent will be monopolized by a small number of institutions. They push back against the philosophy of "Security Through Obscurity" and issue their boldest claim: the window for open-source frontier AI is closing, and this may be the last chance.
More than a year later, they've finally submitted their answer.
Beam's Technical Specs: Open-Source, But Not Yet Downloadable
Beam has 501 billion total parameters, activates 23 billion per forward pass, uses a Sparse Mixture-of-Experts (Sparse MoE) architecture with 52 layers, handles text only, and is optimized for coding and agentic tasks.
But there's a critical catch: no one can download it yet. The official statement says weights, a technical report, and a model card will be released under the Apache 2.0 license, but currently only a waitlist is open while the model undergoes final red-teaming.
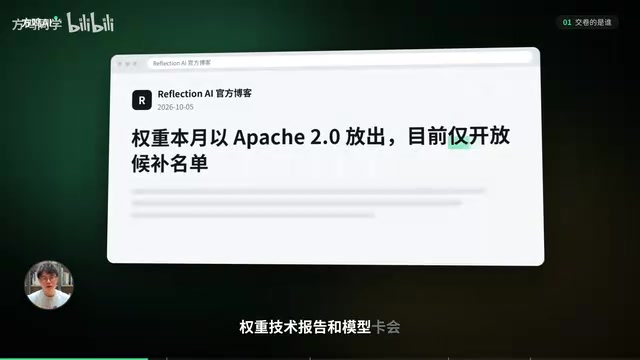
In other words, Reflection has submitted the exam — but the paper is still sitting on the teacher's desk. After more than a year of promises about open-source, the most important step is still a few weeks away.
The Sparse MoE architecture is key to understanding Beam's parameter scale. Traditional "dense" large models activate all parameters when processing every token. MoE architecture splits the model into multiple "expert" sub-networks and only routes to and activates a small subset during each inference pass. Beam has 501 billion total parameters but activates only 23 billion at a time — an activation ratio of under 5%. This means the actual computation during inference is comparable to a 23 billion-parameter dense model, not a 501 billion one — which is the underlying logic behind Reflection's claim of "3–4× inference compute savings." The trade-off is that all expert weights must reside in VRAM simultaneously, making deployment far more demanding than a dense model with equivalent active parameters. Expert routing load balancing is also a significant engineering challenge; Beam's load balancing approach is built directly on a 2024 DeepSeekAd paper.
How Much Compute Was Used: A Staggering Bill
The compute investment behind Beam is the hardest part of this launch announcement.
Pre-training used 6,144 NVIDIA GB300 NVL72 GPUs for under four weeks, consuming 23.8 trillion tokens of data sourced from public web data and licensed proprietary data. One counterintuitive figure: roughly 95% of raw internet data was discarded during parsing, deduplication, and filtering — only the refined remainder was used. Reflection also mentions that standard methods would miss approximately 1.8 trillion high-quality tokens, which they recovered.
The real scale came during the reinforcement learning phase. This stage used 1,500 GB300 GPUs running continuously for four weeks, generating over 100 million rollouts with a maximum context length of 256K. That works out to roughly 7.06 million GPU-hours (estimated from GPU count and duration — not an official figure).
To put 100 million rollouts in perspective: Reflection compared against two models, one of which used only 30 million rollouts and another that used just 753,000 — a difference of more than 100× at the low end.
The engineering numbers are equally striking: approximately 1 million training task environments were prepared, roughly 1.3 billion sandboxes were spawned, an average of 110,000 rollouts ran concurrently with a peak of 170,000 sandboxes active simultaneously, spanning 20+ clusters, two cloud providers, and four regions.
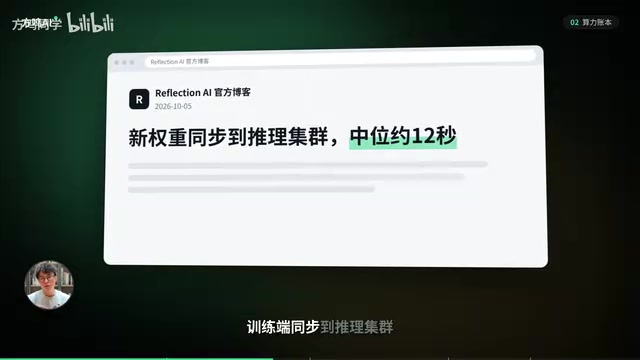
One detail that best illustrates engineering capability: syncing new weights from the training cluster to the inference cluster had a median latency of approximately 12 seconds. During training, 71 failures occurred without a single training interruption — median recovery time was 8 minutes, with service loss accounting for just 0.02% of total training time. The system even remained numerically stable when trained on data that was 107 versions behind.
These metrics don't show up on any leaderboard, but they demonstrate something important: plenty of companies can afford tens of thousands of GPUs; far fewer can keep them running at full capacity with this level of reliability. Reflection's first proof point is that it can orchestrate a massive-scale training system.
Reinforcement learning (RL) plays a fundamentally different role in large model training than pre-training. Pre-training teaches a model to "predict the next token" by consuming vast amounts of static text. RL, by contrast, has the model repeatedly "attempt → evaluate → update," reinforcing correct behavior through large volumes of rollouts. Beam generating over 100 million rollouts means the model solved 100 million problems in controlled sandbox environments, each receiving a reward signal from the environment (such as code execution results), which then updated the model's parameters. This execution-feedback-driven training approach is the core mechanism behind rapid recent progress in coding and mathematical reasoning — DeepSeek-R1 and OpenAI's o-series both follow similar approaches. Reflection pushing this to the scale of 100 million rollouts, and noting "no plateau observed," suggests the RL phase gains have not yet peaked.
Why Voluntarily Show the Losing Scores: Switching the Scorecard
Back to the most unusual question: after all that investment, why include competitors' higher scores in the press release?
Looking at the three benchmarks makes it clear:
- DeepSWE coding benchmark: Beam 44.4, DeepSeek V4.1 Flash 74.2, Kimi K3 ~68, GLM ~61, Qwen3 Max ~51 — Beam is last.
- Terminal Bench: Beam ~81, DeepSeek 90.6, Kimi 88.3, GLM 88.2, Qwen 86.6 — still last.
- SWE-Bench Pro (hard): Beam 77.2, Kimi K3 88.2, GLM ~84.3 — still behind.
This kind of press release is rare. Vendors typically cherry-pick only the benchmarks where they win. Beam explicitly includes the ones where it loses.
But the official framing makes the intent clear. Rather than claiming to be #1 globally, Reflection openly acknowledges that frontier open-source models like Kimi K3 still lead in raw capability. Beam's differentiation is efficiency: the official blog states that Beam achieves comparable performance to GLM on reasoning benchmarks while using 3–4× less inference compute.
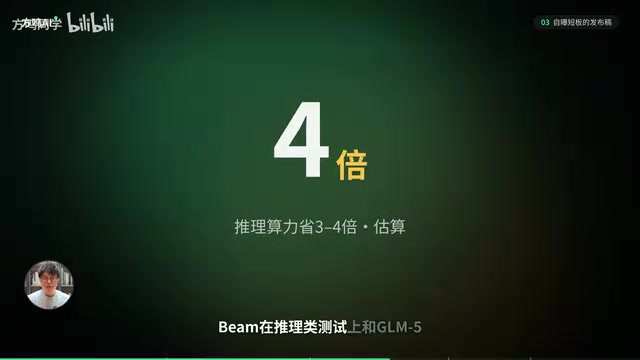
That said, this multiplier is estimated from active parameter counts and generated token quantities — Reflection itself acknowledges this doesn't equal measured real-world cost. More notably, Beam's load balancing method is explicitly built on a 2024 DeepSeek paper — the architecture itself carries DeepSeek's DNA.
This is Beam's strategy: if absolute scores can't compete, compete on cost-performance per unit of compute. And that "efficiency-first" approach is exactly the playbook that made DeepSeek famous.
It's also worth noting that Beam's scores in the table are all self-reported, while competitor scores are drawn from Artificial Analysis and Data Curve, with many cells marked "not reported." This is less a concession and more a switch to a different scorecard — one that measures not who is most capable, but who is most efficient.
SWE-bench is one of the leading benchmarks for evaluating coding agents, testing whether models can automatically fix real software bugs from GitHub. SWE-bench Verified is the standard version with human-validated task quality; SWE-bench Pro further filters for harder, more recent problems to reduce the influence of training data contamination. DeepSWE and Terminal Bench also fall in the coding/agent category — the former focuses on code generation, the latter on a model's ability to complete complex operations in a terminal environment. What these benchmarks share is that they score based on "task completion rate" rather than linguistic fluency, making results harder to inflate with prompt engineering. This is why they're taken more seriously by engineering-oriented teams than general leaderboards. Reflection's choice to compare against competitors on these specific benchmarks is both playing to strength (coding and agents are Beam's focus) and an admission of weakness (absolute scores are broadly lower) — a level of transparency that's genuinely unusual in this industry.
NVIDIA's Triple Role: Buy Cards Either Way
The comparison table includes another name more intriguing than DeepSeek: NVIDIA — the same company that invested in Reflection.
NVIDIA wears three hats in the Beam story:
- Investor: Listed among Reflection's funding round participants;
- Hardware supplier: Beam's pre-training and reinforcement learning both ran on NVIDIA GB300 GPUs;
- Competitor: NVIDIA's own open-source model Nemotron also appears in Beam's comparison table — and loses on all three tests: Terminal Bench (Beam 80.1 vs. Nemotron 56.4), SWE-Bench Pro (65.5 vs. 46.4), SWE-Bench Verified (80.9 vs. 70.7).
The company NVIDIA invested in, using GPUs NVIDIA sold, released a model that outperforms NVIDIA's own model in the press release. It sounds awkward. But the math isn't complicated from NVIDIA's perspective: money flows out from NVIDIA and returns as GPU orders. Whether Beam or Nemotron wins, training requires buying NVIDIA hardware. The wins and losses between models are surface-level — every race still requires purchasing equipment from NVIDIA. That's the genuinely stable business.
Beam's Unexpected Capabilities and Open Questions
Beyond the rankings, Beam brings a few interesting surprises.
When given internet access, Beam reportedly taught itself to search, call other large models, and use OCR APIs to read documents — despite the training tasks containing no browsing tasks and no instruction to "ask another AI." In the demo, Beam built a real-time New York City subway map (querying documentation to verify route geometry) and created a 3D game featuring an astronaut dodging meteors. Additionally, using Beam to fine-tune the smallest Gemma model improved accuracy by 66.5%.
Reflection expresses confidence about what comes next, stating that no plateau was observed as reinforcement learning continued, and that the next generation model is already in training.
But several questions remain unanswerable for now:
- Whether weights will be released fully and on time: Currently only a preview and waitlist;
- Benchmark authenticity: All scores are self-reported, pending the technical report and independent replication;
- Training data composition: Awaiting technical report disclosure;
- How open-source generates revenue: The manifesto mentions a scalable business model without specifics.
Returning to that table at the start: a company that declared "the window is closing" took over a year to deliver, and the leaders in that table are open-source models like DeepSeek, Kimi, and GLM — which Reflection chose to display openly and in full. Perhaps the open-source race was never about who scores highest, but about whose model gets downloaded, forked, and deployed by the most people. When the weights are finally released, which one will you download?
Related articles

n8n 40-Minute Masterclass: Build Your First AI Automation Workflow from Scratch
Distilled from a 40-minute n8n masterclass: the core differences between automation, AI, and AI Agents, a comparison of n8n's four deployment methods, and a complete guide from dashboard to your first workflow.

Why Does a 35GB Quantized Model Blow Up an 80GB GPU? The Truth About KV Cache VRAM
Why does a 35GB 4-bit quantized LLM still blow up an 80GB GPU? This article breaks down the four components of inference VRAM, provides precise KV Cache formulas, compares GQA vs DeepSeek MLA memory, and offers production-grade OOM prevention like FP8 KV Cache.

Turning Company Workflows into Agent Skills: A Practical Guide
An agency owner turns team workflows into Agent Skills: one command handles article writing, six-platform distribution, and dual human approval. This guide breaks down the Skill file structure, two invocation methods, three-tier storage layout, security review process, and how to turn your own weekly repetitive tasks into executable, auditable skills.