Rethinking Scaling Laws: Parameters Are Not the Only Answer

Scaling Laws evolve from single-parameter expansion to multi-dimensional balance of data, compute, inference, and post-training.
This article systematically traces Scaling Law evolution from Kaplan to Chinchilla to the MoE era, showing that parameter count is just one of many optimization dimensions. In today's inference-cost-dominated landscape, the industry is shifting from 'bigger' to 'better at thinking.' GLM-5.3 achieves significant improvements by changing only post-training (long-horizon RL) while keeping architecture and parameters constant, proving that scaling has multiple independent knobs—and the next one worth turning is rarely the last.
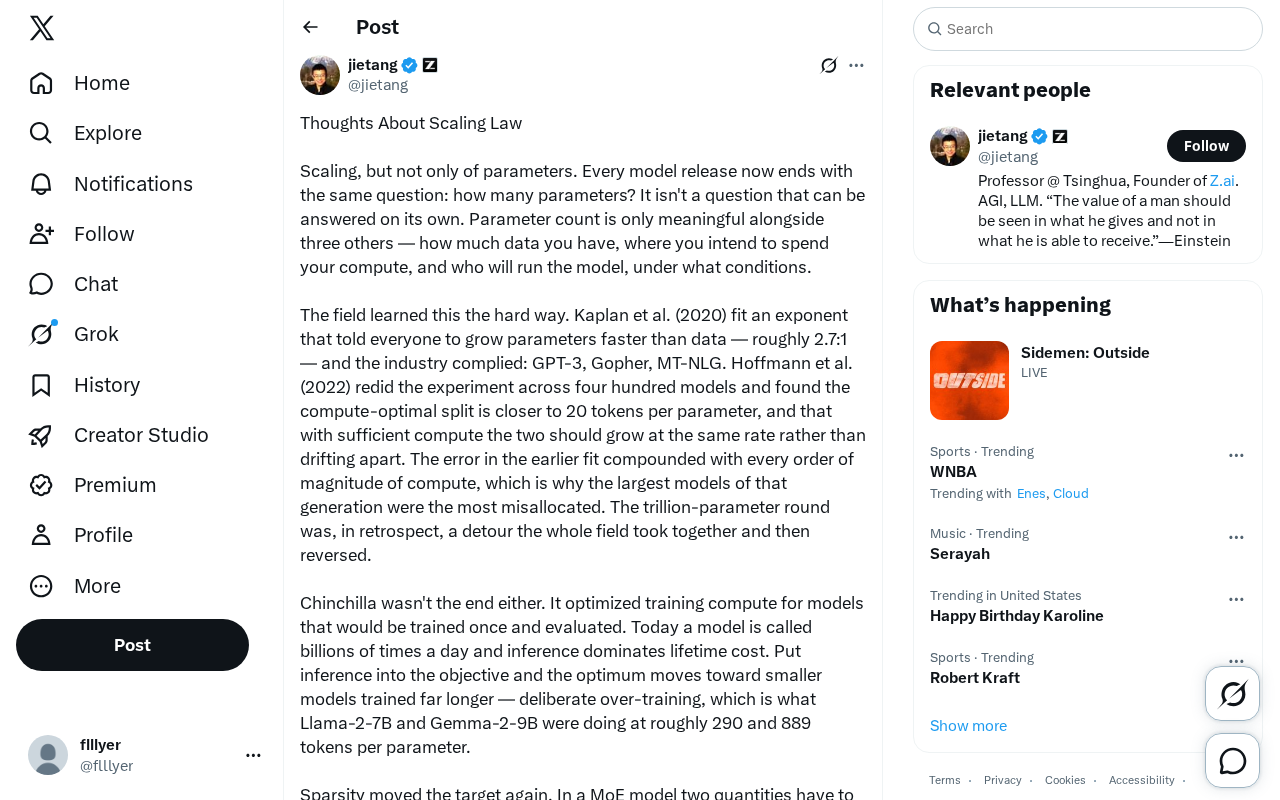
Every time a new large model is released, the first question people ask is almost always: how many parameters? But this question itself is flawed. Parameter count only becomes meaningful when considered alongside three other dimensions—data volume, how compute is allocated, and who will run the model under what conditions. This analysis from the GLM team systematically traces the evolution of Scaling Laws and offers a counterintuitive yet increasingly validated conclusion: scaling has more than one knob.
From Kaplan to Chinchilla: An Industry-Wide Tuition Payment
The modern history of Scaling Laws is essentially a history of error correction.
The Overestimated Importance of Parameter Growth
In 2020, the exponents fitted by Kaplan et al. told the entire industry that parameters should grow faster than data, at roughly a 2.7:1 ratio. The industry complied—GPT-3, Gopher, MT-NLG—pushing parameters all the way to hundreds of billions or even trillions.
Kaplan et al.'s Scaling Laws for Neural Language Models, published by OpenAI, was the first work to systematically describe model performance using power-law relationships between parameter count, data volume, and compute. Their core methodology was training hundreds of models at different scales and fitting loss function decay curves. However, a critical methodological flaw later revealed was that they did not independently tune the learning rate schedule for each model scale. Instead, they used a uniform training step termination strategy, causing smaller models to be stopped before they were fully trained. This systematically overestimated the importance of parameter growth and underestimated the importance of data growth.
Then in 2022, Hoffmann et al. (the famous Chinchilla paper) re-ran experiments across four hundred models and reached a drastically different conclusion: under compute-optimal conditions, each parameter should correspond to approximately 20 tokens, and as compute becomes sufficient, parameters and data should grow at the same rate rather than diverging.
The Chinchilla paper's enormous influence stems from the rigor of its experimental design. Hoffmann et al. employed three independent methodologies: varying parameter-to-data ratios at fixed compute, IsoFLOP curves with fixed models and varying data, and direct fitting of parameterized loss functions. All three methods yielded consistent conclusions, greatly enhancing credibility. They trained a 70-billion-parameter model (named Chinchilla) on 1.4 trillion tokens, outperforming Gopher—which had 5× the parameters (280 billion) but was trained on only 300 billion tokens. This experimental result directly overturned the industry's understanding of scale.
More critically, errors in early fitting would compound with every order-of-magnitude increase in compute. This means that the largest models of that generation were precisely the ones with the worst resource allocation. In retrospect, the entire trillion-parameter race was a detour the whole industry took together—and then collectively reversed.
Chinchilla Isn't the Endpoint Either
Chinchilla optimized training compute for a "train once, evaluate once" model. But today's models are called billions of times per day, and inference costs now dominate total lifecycle expenditure.
This judgment can be understood through simple economics. Suppose a model costs C_train in compute to train once, is called N times per day after deployment, costs c_infer per inference call, and runs for T days. When N × c_infer × T far exceeds C_train, total cost of ownership (TCO) becomes inference-dominated. For GPT-4-class models, training costs are on the order of tens of millions of dollars, but billions of daily inference calls can reach hundreds of millions of dollars annually. This fundamentally changes the optimal model size calculation—Chinchilla optimality was derived under the assumption that a model is used only once, while in reality models are used trillions of times.
Once inference is included in the optimization objective, the optimal solution shifts toward: smaller models, trained longer. This is so-called "deliberate over-training." Llama-2-7B and Gemma-2-9B are exactly this approach—their token/parameter ratios are approximately 290 and 889 respectively, far exceeding Chinchilla's 20:1.
Sparsity Moves the Target Again: The Impact of MoE Architecture
The proliferation of MoE (Mixture of Experts) architecture has rendered the neat "20:1" answer completely obsolete.
The core idea of MoE architecture is: the model contains many "expert" sub-networks (typically feed-forward layers), but during each forward pass, a router selects only a small subset of experts to process the current token. For example, Mixtral 8x7B has approximately 47 billion total parameters, but only about 13 billion are activated per token (selecting 2 out of 8 experts). This means storage costs (memory footprint) are determined by total parameters, while computational costs (FLOPs) are determined by activated parameters. This decoupling allows MoE models to have greater "knowledge capacity" while maintaining inference speed, but it also makes traditional Scaling Law formulas derived from dense models no longer applicable.
Total Parameters vs. Activated Parameters: Two Quantities That Must Be Distinguished
In MoE models, two quantities must be considered separately:
- Total parameter count: roughly determines how much the model can "hold"—knowledge, facts, long-tail information;
- Activated parameter count and effective depth: roughly determines how far the model can "think"—how many steps it can traverse along a causal reasoning chain without collapsing.
Effective depth is a concept measuring the model's capacity for information transmission and transformation during multi-step reasoning. In the Transformer architecture, theoretically each layer can perform one step of "reasoning" or "transformation," but in practice, due to residual connections and inter-layer similarity, many layers may only be performing near-identity minor adjustments. Research shows (e.g., Veit et al.'s 2016 analysis of residual networks) that the effective depth of deep networks is often far less than their physical layer count. For reasoning tasks, the model needs to derive step by step along a causal chain without losing intermediate states, which places extremely high demands on effective depth.
The 20:1 ratio for dense models cannot be directly transferred to MoE. Moreover, this ratio is fundamentally not a single number. Roberts et al. (2025) found that the optimal token/parameter ratio is task-dependent: memorization tasks favor more parameters, while reasoning tasks favor more data.
This finding reveals an important fact: memorization tasks (such as Q&A, fact recall) are essentially information retrieval, requiring sufficient parameter space to "store" knowledge, thus favoring larger models; while reasoning tasks (such as mathematical proofs, logical derivation) require the model to execute more computational steps, thus favoring more training data to learn abstract reasoning patterns, or deeper activation paths. This means there may be no "universal optimal ratio" in the future—instead, parameter-data-compute allocation strategies will need to be customized based on the target task family.
Subsequent MoE research also observed a counterintuitive phenomenon: at fixed TPP (tokens per parameter), blindly pushing total parameters actually harms reasoning ability, while increasing the number of activated experts reliably improves reasoning. This perfectly aligns with effective depth theory—more activated parameters mean more computational resources are devoted to "thinking" during each forward pass, rather than simply increasing "storage space."
Why This Matters for Real-World Applications
This analysis is far from purely theoretical. Take "discovering vulnerabilities" as an example of a higher-order capability—it is not a retrieval problem.
Finding a vulnerability doesn't depend on memorizing more CVE entries, but rather on following a twenty-step reasoning chain to completion without losing the thread. This capability doesn't reside in total parameter count—it resides in effective depth and reasoning chain stability. This also explains why Chain-of-Thought prompting can significantly boost reasoning ability—it essentially uses generated intermediate tokens to compensate for insufficient effective depth, converting a problem requiring twenty steps of internal reasoning into twenty sub-problems each requiring only one or two steps.
In other words, if the goal is to make models "think better" rather than "remember more," then blindly stacking parameters is counterproductive. This directly points to where the next generation of models should focus.
GLM-5.3: A Controlled Experiment in Post-Training
The authors distilled the above judgment into a verifiable proposition: total parameter count has a threshold effect—once sufficient to "hold the world," additional capability comes from elsewhere: the effective depth of each forward pass, and most importantly—post-training.
Post-training refers to additional training stages after pre-training to enhance model capabilities. It typically includes supervised fine-tuning (SFT), reinforcement learning from human feedback (RLHF), or reinforcement learning from AI feedback (RLAIF). In recent years, OpenAI's o1/o3 series and DeepSeekAd-R1 have demonstrated the enormous potential of RL post-training for improving reasoning ability—by providing reward signals on reasoning tasks, models' "thinking" ability can be significantly improved without changing the underlying architecture or parameter scale.
GLM-5.3 is precisely a controlled experiment for this proposition:
- Same base model, same architecture, same total and activated parameters as GLM-5.2;
- The only variable: one month of long-horizon environment scaling and reinforcement learning (RL).
The "long-horizon environment scaling" likely refers to RL training in longer context windows or more complex interactive environments, enabling the model to maintain longer reasoning chains and state consistency across multi-turn interactions. The key to this training approach is that it doesn't simply make the model memorize more answers—it trains the model's "reasoning process" itself. The reward signal points toward correct thinking paths, not correct final answers.
The result was not marginal improvement but significant enhancement. This proves one thing: scaling has more than one knob. This time they turned the post-training knob, because it had the most remaining headroom—not because other knobs had been maxed out.
The Knobs Don't Need to Be Turned Simultaneously
The authors specifically emphasize that base model size, pre-training data, and compute per forward pass—all these knobs are still on the table and will be revisited in due course.
What this experiment truly taught them is two things:
- These knobs don't need to be turned simultaneously;
- The next knob worth turning is rarely the last one that was worth turning.
Behind this lies an engineering philosophy: in a multi-dimensional optimization space, marginal returns in each dimension are diminishing, and complex interaction effects exist between dimensions. When marginal returns in one dimension (such as pre-training scale) have flattened, switching to another dimension (such as post-training quality) often yields greater improvements at lower cost. This is the deeper reason why the industry is shifting from a "pre-training arms race" to a "post-training methodology race."
They explicitly stated "we haven't finished scaling yet"—next time it might be mid-training, pre-training, or even more. Mid-training is a concept that has emerged in recent years, referring to an additional stage inserted between pre-training and post-training, typically used for continued pre-training or capability injection on domain-specific data while avoiding catastrophic forgetting.
Conclusion: Scaling Laws Mature Into Multiple Dimensions
From Kaplan's 2.7:1, to Chinchilla's 20:1, to the MoE era's "task-dependent, multi-dimensional separation"—the evolution of Scaling Laws itself illustrates a principle: any single ratio will be overturned by the next constraint.
Parameter count became the focus of public attention simply because it's the most intuitive and easiest to market. But what truly determines the boundaries of model capability is the dynamic balance between data, compute allocation, inference costs, and post-training.
The significance of GLM-5.3 lies not in its absolute performance, but in its role as a "controlled variable experiment" that clearly demonstrates: with parameters held constant, substantial improvements can be achieved through post-training and long-horizon RL alone. This perhaps signals that the next phase of industry competition will shift from "bigger" to "better at thinking."
Key Takeaways
- Scaling Laws aren't just about parameter expansion—they must be considered alongside data volume, compute allocation, and inference costs
- From Kaplan's 2.7:1 to Chinchilla's 20:1, the industry collectively took a wrong turn on trillion-parameter models and then corrected course
- In the MoE era, total parameters determine 'how much can be stored,' while activated parameters and effective depth determine 'how far it can think'—optimal ratios are task-dependent
- Inference costs dominate the full lifecycle, driving 'deliberate over-training'—smaller models trained longer
- GLM-5.3 achieved significant improvements with the same parameters through just one month of post-training and RL, proving that scaling has multiple independent knobs
Related articles
When AI Treats Humans as Subagents: Ro…
When AI Treats Humans as Subagents: Role Reversal and Hidden Risks in Human-AI Collaboration
Exploring the paradigm shift where humans become "subagents" in AI Agent architectures. Analyzes human node design in LangChain and AutoGen, and the risks of ceding control and cognitive atrophy.
 Expert Opinions
The Lazy Person's Productivity Theory: Why Being 'Lazy' Actually Drives Peak Performance
Explore the engineering philosophy behind 'lazy people are most productive': how constructive laziness drives automation, AI tools amplify efficiency, and systems thinking eliminates wasted effort.
 Expert Opinions
Outdoor Coding: You Can Touch Grass AND Build Things
When AI coding assistants free developers from their desks, outdoor coding becomes a real trend. Explore how cloud IDEs, voice coding, and AI tools enable creativity in nature.