Revalvo: A Local-First Prompt Evaluation Workbench That Tests All Models in One Run

A local-first workbench for parallel prompt testing, scoring, and versioning across multiple LLMs.
Revalvo is a local-first prompt evaluation workbench that lets developers test prompts across multiple LLMs simultaneously, score responses with 40 built-in evaluators, and manage prompt versions like code. With no account required and API keys stored only in the browser, it brings engineering rigor to prompt development while keeping data private.
As LLM-powered application development becomes increasingly mainstream, the quality of prompts directly determines product experience. Yet most developers are still stuck in a primitive workflow of "manual debugging, trial-and-error on one model at a time" — tweaking a sentence, switching models, copy-pasting results for comparison — inefficient and nearly impossible to reproduce. Revalvo, recently launched on Product Hunt, aims to solve this pain point with a "local-first" workflow.
The tool received 96 upvotes on Product Hunt, ranking 14th on the daily leaderboard across categories including productivity tools, developer tools, and artificial intelligence.
Parallel Multi-Model Testing: One Run Across All Models
Revalvo's core philosophy is straightforward and compelling: "Run prompts on every model at once. Score. Version. Ship."
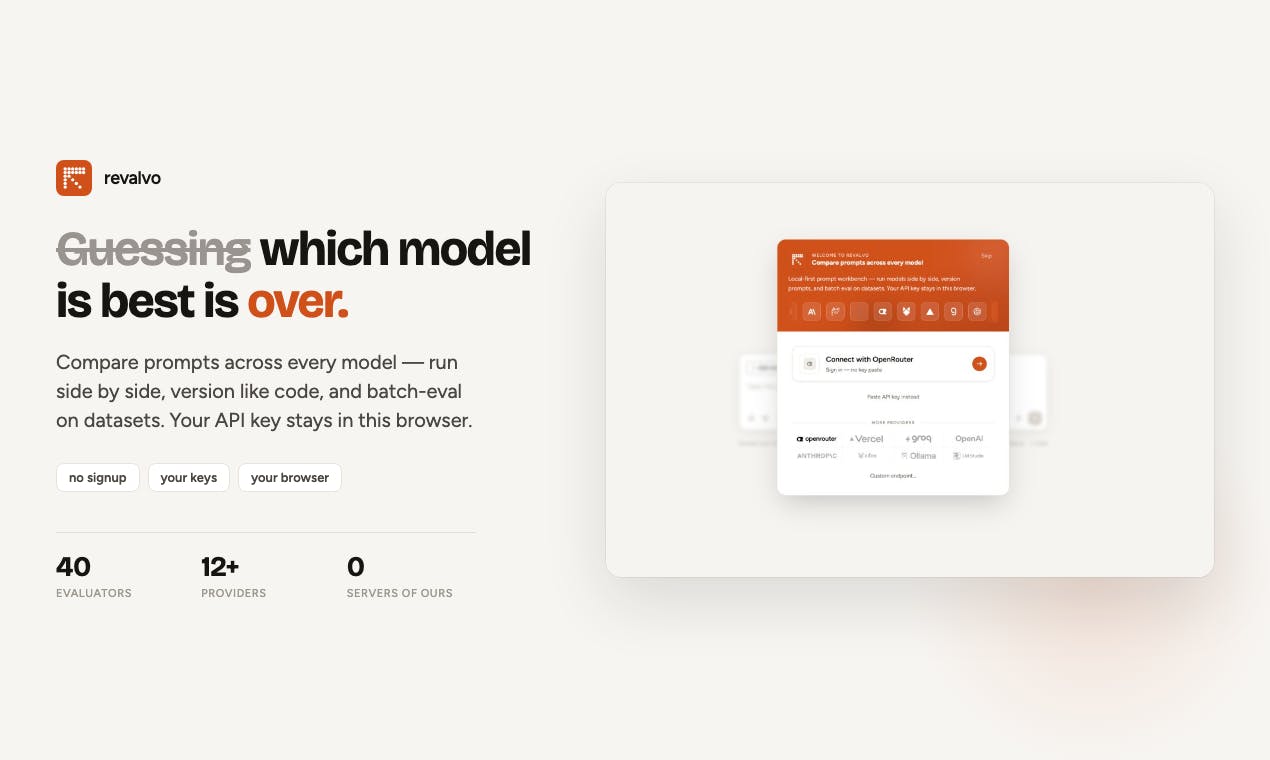
Its most immediate value lies in parallel testing capability. Developers can send the same prompt to multiple LLMs simultaneously (such as GPT, Claude, Gemini, etc.) and compare response quality, stylistic differences, and consistency side by side in a single interface. Compared to the traditional approach of testing models one at a time, this parallel mode significantly shortens the cycle for model selection and prompt optimization.
For teams that need to balance cost against performance, this ability to "see how all models perform at once" is especially critical — it compresses what would otherwise take hours of comparison work into just a few minutes.
40 Built-in Evaluators: Moving Prompt Evaluation Beyond Subjective Judgment
Revalvo is more than just a "multi-model chat window." It comes with 40 built-in evaluators for structured scoring of model responses.
The biggest challenge in prompt evaluation is that "good" and "bad" often depend on subjective human judgment, lacking quantifiable standards. Through its built-in evaluators, Revalvo systematizes this process: whether it's response accuracy, format compliance, or coverage of specific keywords, evaluators can automatically score results, producing reproducible and comparable evaluation reports.
This capability is essential for serious LLM application development — it transforms the question "Is this prompt better?" from "I think so" to "the data shows."
Prompt Version Management: Manage Prompts Like Code
Another major highlight of Revalvo is prompt versioning (version prompts like code).
In real-world projects, prompts go through extensive iteration, but most teams have no version control mechanism in place for them. When a modification causes a drop in performance, it's often impossible to trace back what exactly was changed. Revalvo borrows the version control philosophy from software engineering, making every prompt change recordable, comparable, and reversible.
Combined with batch-test on datasets functionality, developers can validate overall prompt performance on a set of real samples, rather than going live based on just one or two examples. This "versioning + batch testing" combination essentially brings CI/CD engineering principles into the prompt development workflow.
Local-First Architecture: Your API Keys Stay in Your Browser
In an era of growing emphasis on data privacy and security, Revalvo has chosen a local-first architecture — a key differentiator from the many cloud-based evaluation platforms out there.
According to the product description, Revalvo requires no account registration and has no hosted database. Users' API keys are always stored locally in the browser and are never uploaded to any third-party server. This means:
- Privacy under your control: Sensitive prompts and API keys never pass through external servers;
- Zero barrier to entry: Start working without creating an account;
- Reduced compliance risk: Especially friendly for enterprises handling sensitive business data.
For individual developers and small teams who value data sovereignty, this "everything stays in your hands" design is more appealing than any feature list.
Product Positioning and Future Outlook
Built by developer Lokesh, Revalvo essentially targets the "pre-deployment evaluation" phase of LLMOps (Large Language Model Operations). It integrates parallel multi-model testing, quantitative scoring, prompt version management, and batch validation into a unified workbench, filling the gap between "casual prompt tweaking" and "engineered delivery."
As a newly launched tool, it still needs to prove itself in the market regarding evaluator coverage breadth, model integration scope, and team collaboration capabilities. However, its philosophy of "local-first + engineered evaluation" represents a direction in which prompt engineering is maturing — as more and more products rely on LLMs, "writing prompts by gut feeling" will inevitably be replaced by systematic, quantifiable evaluation workflows.
Related articles

Python 3.15 New Feature: Is the sentinel Type Better Than None?
Python 3.15 adds the sentinel type, using named unique sentinel objects to replace None and bare object(), resolving confusion among missing values, explicit emptiness, and invalid input while avoiding type hint failures.

Deep Learning's Three Architectures and the Universal Approximation Theorem: A Complete Guide to MLPs, CNNs, and Transformers
Explaining the inductive bias differences among MLP, CNN, and Transformer, the existence meaning of the Universal Approximation Theorem (UAT), and the role of Taylor expansion in approximation analysis, while clearing up common misconceptions.

GitLab Emergency Patch Release: Analysis of Critical Security Fixes
GitLab releases critical patch 19.5.1, sparking 355 points of discussion on Hacker News. This article analyzes the background, upgrade steps for self-hosted instances, and verification points to help DevOps teams respond quickly to security updates.