Save Tokens Without Sacrificing Quality: How to Pair Model Tier with Effort for Maximum Cost Efficiency

Dynamically pair model tier with Effort level to cut LLM costs without sacrificing output quality.
This article focuses on the often-overlooked Effort (reasoning effort) parameter in LLM API calls, explaining how it controls hidden reasoning token consumption to impact both cost and speed. The key insight: the optimal strategy isn't always choosing a flagship model or maxing out Effort — it's dynamically combining both dimensions based on task complexity. For simple to moderately complex tasks, "lightweight model + Max Effort" can approximate "flagship model + Medium Effort" at much lower cost. For capability-intensive tasks like complex reasoning or long-document processing, flagship models remain irreplaceable, since Effort is only an amplifier and cannot exceed the model's inherent capability ceiling.
Why AI Has an "Effort Level"
Most people using large language models focus only on which version to pick, overlooking another dial that directly determines cost — Effort (reasoning effort level). It controls how much "thought" the AI is willing to invest when tackling a problem. The higher the Effort, the more hidden reasoning tokens the model generates. These tokens never appear in the final response, but they count toward your usage and cost — and they slow down response time.
Think of it this way: models are like people — they have their own energy and effort budget. Demanding maximum effort on every trivial task isn't just unnecessary; it's burning money. Truly savvy token optimization isn't about maxing out Effort across the board — it's about tuning both "model tier" and "effort level" together.
On a technical level, these "reasoning tokens" correspond to the Chain-of-Thought internal reasoning process unique to reasoning models like OpenAI's o-series and Anthropic's Claude 3.7. Unlike standard language models that generate answers directly, reasoning models first produce an internal self-dialogue of analytical steps before distilling the conclusion into a final reply. This intermediate process is invisible to users, but consumes a significant portion of your token quota — for OpenAI o3, for instance, the internal reasoning tokens for a single complex request can be several times the size of the final output. Effort (sometimes called reasoning_effort in API documentation) is the parameter that controls how much "thinking budget" the model allocates for this process, typically divided into Low / Medium / High (or Min / Medium / Max) tiers, each corresponding to different reasoning depths and token consumption caps.
Is Higher Effort Always Better? Not Necessarily.
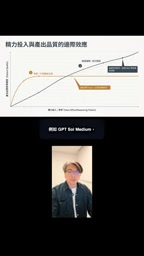
Intuition suggests that "working harder yields better results" — but that's not always the case. The extra reasoning triggered by higher Effort provides almost no benefit for simple tasks, yet pushes both cost and latency higher.
A smarter strategy is cross-dimensional pairing: a lightweight model + maximum Effort can often approximate the perceived quality of a flagship model + medium Effort. To put it concretely: a lightweight model (e.g., a Nano-tier model) running at Max can approach the output quality of a flagship model (e.g., Sonnet-tier) at Medium — at a fraction of the cost.
The logic behind this: for simple to moderately complex problems, the bottleneck isn't the model's capability ceiling — it's how much reasoning it's willing to invest. Give a smaller model a bigger thinking budget, and you can squeeze out its latent potential for the best possible cost-performance ratio.
This "cross-dimensional pairing" approach has a theoretical grounding in machine learning — Compute-Optimal Scaling. The traditional view held that improving model capability required scaling up parameter counts. But recent research (such as DeepMind's Chinchilla paper and subsequent "inference-time compute scaling" studies) has shown that dynamically increasing computation at inference time can also significantly improve a small model's output quality. In other words, a model's "capability" isn't fixed — it's jointly determined by training-time parameter scale and inference-time compute investment. This is why giving a lightweight model higher Effort can "catch up" to a larger model on certain tasks: it uses runtime compute as a capability compensator.
Complex Tasks: Flagship Models Are Still Irreplaceable
That said, lightweight model + Max is not a universal solution. When tasks are genuinely capability-intensive, the gap becomes apparent:
- Complex logical reasoning
- Ambiguous problems requiring judgment
- Long-document processing and software development
- Tasks with extremely high accuracy requirements
In these cases, a flagship model at medium Effort (e.g., Sonnet Medium) is both more capable and more consistent. No matter how much thinking budget you give a smaller model, it can't bridge the gap in raw capability. Put another way: Effort is an amplifier, and model tier is the ceiling — an amplifier can't lift things above the ceiling.
Practical Configuration Recommendations
Applying the principles above, here's how to map common use cases to configurations:
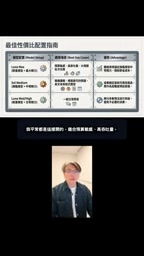
Lightweight Model + Max: Budget-Sensitive, High-Volume Tasks
This is the go-to money-saving configuration — ideal for budget-conscious, high-throughput scenarios where minor quality variation is acceptable. For large-scale batch jobs especially, this setup is extremely economical, keeping total costs low. There may be slight quality fluctuations, but for batch processing, that's entirely acceptable.
Flagship Model + Medium: Reliability First
When consistency and reliability of task output are critical, switch to a flagship model at Medium Effort. It trades a bit more cost for stable, predictable results — ideal for high-stakes tasks where errors aren't an option.
Everyday Q&A: Lightweight Model at Medium or High
For general everyday questions, Medium or High on a lightweight model is more than sufficient. In most cases, there's simply no need to push to Max — that's just wasting tokens and time.
Summary: Spend Your Token Budget Where It Counts
Optimizing token costs isn't about finding the "cheapest model" — it's about dynamically matching the model tier × Effort combination to the difficulty of each task:
- For simple to moderately complex tasks, let a small model think hard — best cost-performance ratio;
- For complex, critical tasks, hand it to a flagship model with moderate reasoning — stable and reliable;
- In everyday use, don't blindly max out Effort — mid-range is enough.
Understanding that models have both a "capability ceiling" and an "effort level" is a crucial step toward getting the most out of large language models while keeping costs in check.
Related articles

Gemini 4 Argon Hands-On: AI Builds Board Games, Constructs Temples, and Trains Robots Autonomously
Gemini 4 Argon hands-on roundup: AI autonomously builds a desk racetrack and temple in Blender, writes a ray tracing engine, trains a humanoid robot to sink 7 shots, plus API pricing and developer access.

The Magic Octagonal Coin: Why Only 9% of People Can Predict Its Flip?
Only 9% of people can correctly predict the Magic Octagon coin flip. This article explains its spatial rotation mechanism, common cognitive pitfalls, and a new hypothesis based on Relevance Theory, exploring the limits of human spatial reasoning.

Sam Altman: AI Is Entering the Era of Scientific Discovery — Math Breakthroughs Will Replicate in Biology and Energy
Sam Altman says AI is entering the era of scientific discovery — math breakthroughs will replicate in biology, materials science, and energy to help develop new drugs and energy sources.