Stanford, Meta and Others Release Hybrid Reasoning Agents: Hidden Reasoning Halves Token Usage, Accuracy Up 10%

Stanford and others propose hybrid reasoning agents that hide reasoning internally, raising accuracy ~10%, halving tokens, and doubling speed.
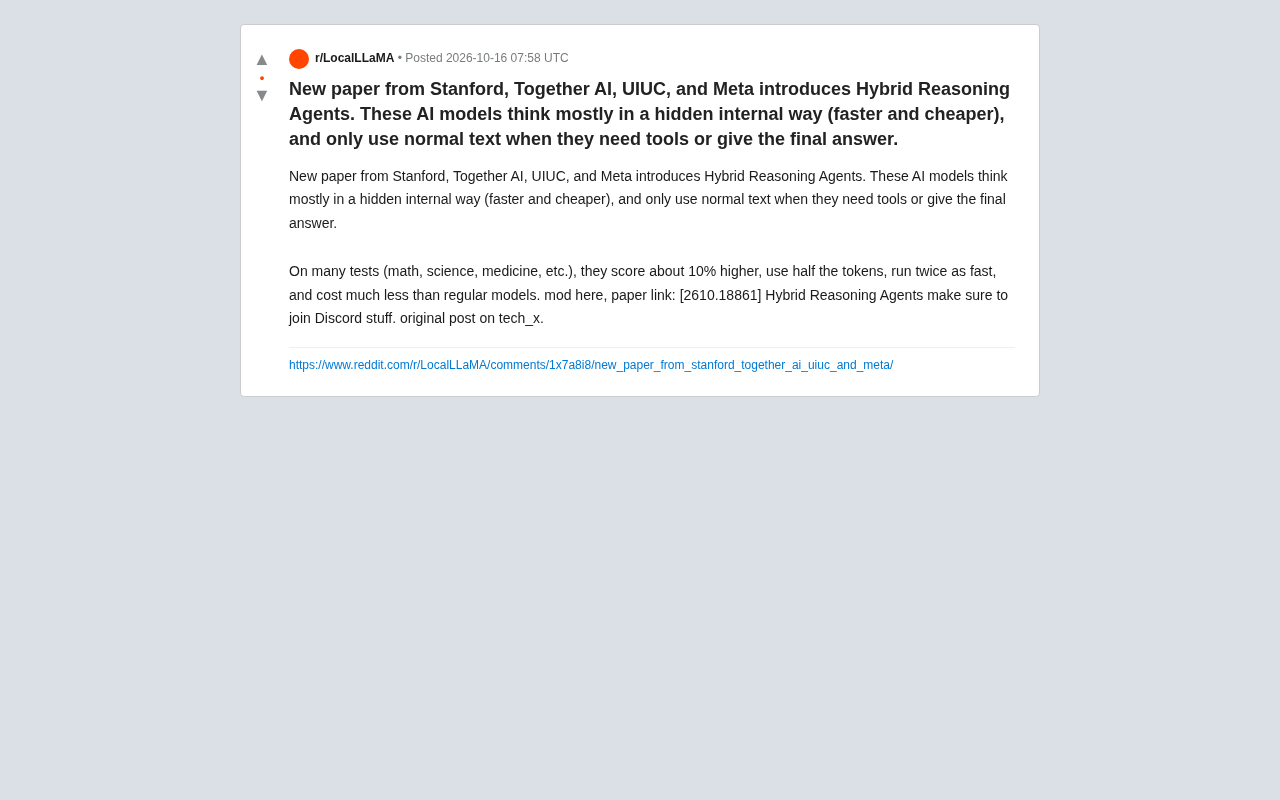
Stanford, Together AI, UIUC, and Meta jointly propose Hybrid Reasoning Agents, a new paradigm in which models no longer output step-by-step human-readable chains of thought during everyday thinking, but instead complete most computation in a hidden internal space, switching back to text mode only when calling external tools or giving final answers—decoupling "thinking" from "expressing." On math, science, and medicine tasks, the paper reports accuracy up about 10 percentage points, token usage roughly halved, and speed about 2x conventional models, with costs falling accordingly. This "cheaper yet more accurate" result is attributed to reduced self-repetition and drift within lengthy chains of thought. The method can be embedded into existing Agent frameworks, meaning direct bill reductions and latency improvements for token-billed API users. Questions to verify include the interpretability cost of hidden reasoning, generalization to open-ended tasks, and the reproduction barrier for independent teams.
When AI Learns to "Think Quietly": The Proposal of Hybrid Reasoning
Stanford, Together AI, UIUC, and Meta jointly released a new paper proposing a paradigm called Hybrid Reasoning Agents. Put simply, these models no longer write out every reasoning step in human-readable text during their day-to-day "thinking." Instead, they perform most of their computation in a hidden internal space—switching to ordinary text mode only when they need to call external tools or produce a final answer.
The motivation behind this design is straightforward: let models "think faster and cheaper." According to the paper, conventional reasoning models spend a large number of tokens repeatedly writing out chains of thought, and those tokens are both slow and expensive. Hybrid reasoning decouples "thinking" from "expressing," invoking language output only when necessary.
Three Numbers from the Benchmarks: 10%, Half, Double
The paper compared performance across math, science, medicine, and other tasks, and the conclusions can be summarized in three numbers:
- Accuracy up roughly 10%: Across multiple test sets, hybrid reasoning agents scored about 10 percentage points higher than conventional models;
- Token usage halved: Completing the same task consumed roughly half as many tokens;
- Speed doubled: Runtime was about 2x that of conventional models, with costs dropping significantly as well.
Together, these three points point to a relatively rare outcome—typically, "cheaper" models sacrifice some accuracy, yet here accuracy actually rose. The paper's explanation: compressing reasoning into a hidden space reduces the model's opportunities to "take detours" or repeat itself within lengthy chains of thought, which in turn makes decision-making more focused.
Why "Writing Less" Is Actually More Accurate
Conventional Chain-of-Thought (CoT) works because externalizing intermediate steps helps the model self-correct. But it has a side effect: once reasoning is written out as long text, the model can be led astray by its own wording, even getting bogged down in irrelevant details.
Hybrid reasoning agents keep intermediate computation "internal," converting content into text only at key junctures—such as calling a calculator, querying a database, or outputting the final answer. The benefits are twofold:
- More concentrated compute budget: The tokens saved by hidden reasoning can be redirected toward denser internal computation;
- Cleaner tool calls: Text appears only at the two points that genuinely require "outward communication"—tool interaction and the final answer—reducing formatting errors and redundant steps.
In the paper's experiments, these models performed especially well on medical Q&A and scientific reasoning tasks that require multi-step tool calls, which aligns with the design intent of "text for tool interaction."
Chain-of-Thought (CoT) is a prompting and reasoning paradigm proposed by Google Research in 2022: before giving an answer, the model writes out its intermediate reasoning process step by step in natural language, then derives the final conclusion from that. Its effectiveness stems from two factors—the externalized intermediate steps provide explicit context for subsequent tokens, essentially acting as "scratch paper"; and each step can be sampled and checked, allowing the model to self-correct after mistakes. But CoT's cost is equally clear: reasoning depth is strictly tied to the length of the generated sequence, and every additional token incurs the cost and latency of one forward computation. Subsequent research therefore split into two paths—one continuing to lengthen chains of thought (such as o1 and DeepSeekAd-R1-style long reasoning), and the other attempting to move part of the computation out of the text sequence. Hybrid reasoning agents belong to the latter, essentially redistributing the compute budget between "explicit scratch paper" and "implicit state."
What It Means for the Agent Ecosystem
If this approach can be reliably reproduced, its impact on the current AI Agent ecosystem will be significant.
The most direct effect is a shift in cost structure. Agent-type applications derive most of their cost from repeated reasoning calls. Halving tokens and doubling speed means more tasks or longer chains can run on the same budget. For API users billed by token, this is a tangible reduction in their bill.
Second is improved latency. In real-world scenarios, agents often need multiple rounds of "think—call tool—think again," and writing out a full chain of thought each round makes response time grow linearly. Hidden reasoning shortens each round, which is especially friendly to interactive agents that require low latency.
Third is compatibility with existing tool-calling protocols. Because tools are still called and answers still given in text form, this approach can be embedded into existing Agent frameworks without overturning the entire tool ecosystem. Some in the Reddit discussion also noted that the paper's identifier is 2610.18861, so interested readers can consult the original for details.
Tool calling protocols (tool calling / function calling) refer to a model describing the function name and parameters to be invoked in structured text (usually JSON), with an external runtime executing them and feeding the results back to the model. The key constraint of this mechanism is that all information exchange between the model and the outside world must pass through a serializable text channel. Hybrid reasoning agents exploit exactly this point—keeping all computation that doesn't require outward communication in the hidden space, and generating structured text only at the moment of interfacing with tools. This means it's an "addition" rather than a "replacement" for the existing ecosystem: ReAct, MCP, and various Agent orchestration frameworks can all be connected without modification, as long as the model can still produce compliant tool-call formats after hidden reasoning. The real engineering challenge lies in how, during training, to teach the model to judge "when to switch to text mode"—this gatekeeping mechanism determines whether the method can be directly applied to existing production pipelines.
Questions Still to Be Answered
The paper's numbers are impressive, but several points need follow-up validation.
First is the cost to interpretability. Hidden reasoning means that during debugging, the model's intermediate steps are invisible, making it harder after an error to pinpoint whether it "thought wrong" or "used a tool wrong." For medical and financial scenarios with high safety requirements, this could be an obstacle.
Second is cross-task generalization. Current tests focus on tasks with clear answers, such as math, science, and medicine. Whether open-ended writing, multi-turn negotiation, and similar tasks benefit equally is not addressed by the paper.
Third is the reproduction barrier. Work jointly released by multiple institutions often involves complex training details, and whether independent teams can reproduce the same 10% improvement with limited compute still needs community verification.
Overall, the direction pointed to by Hybrid Reasoning Agents—separating "thinking" from "speaking"—is an approach worth watching. It may not be the endpoint, but it does offer a new path toward "cheaper and more accurate reasoning."
The tension between hidden reasoning and interpretability deserves elaboration. A major byproduct of conventional chains of thought is auditability—safety teams can read the intermediate text and judge whether the model has hallucinated, shown bias, or overstepped its reasoning. Once computation is compressed into continuous vector space, these intermediate states are neither natural language nor easily translatable into human-readable steps, and the "faithfulness" problem in interpretability research becomes even more acute: even if probes forcibly decode some internal representations, there is no guarantee they truly reflect the basis for a decision. For regulated scenarios such as medical diagnosis, credit approval, and legal advice, the absence of an intermediate evidence chain could directly create compliance obstacles. Directions currently being explored in academia include inserting a small amount of "anchor text" into hidden reasoning, performing post-hoc attribution of internal states, or training auxiliary models to generate explanations—but none is settled yet. This is also a threshold that hybrid reasoning must cross if it is to move into high-risk domains.
One-line Summary
Stanford and other institutions propose hybrid reasoning agents that hide reasoning in internal space, raising accuracy by about 10%, halving tokens, and doubling speed.
Paragraph Summary
Stanford, Together AI, UIUC, and Meta jointly propose a new paradigm, Hybrid Reasoning Agents: instead of outputting a human-readable chain of thought step by step during everyday thinking, the model completes most computation in a hidden internal space and switches back to text mode only when calling external tools or giving a final answer, decoupling "thinking" from "expressing." On math, science, and medicine tasks, the paper reports three figures: accuracy up about 10 percentage points, token usage roughly halved, and speed about 2x that of conventional models, with costs falling accordingly. This "cheaper yet more accurate" result is explained by reduced self-repetition and drift within lengthy chains of thought. The method can be embedded into existing Agent frameworks, meaning direct bill reductions and latency improvements for API users billed by token. Questions to be verified include the interpretability cost of hidden reasoning, generalization to open-ended tasks, and the reproduction barrier for independent teams.
Related articles

Workbuddy for Absolute Beginners: How a Desktop AI Agent Fits Into Real Workflows
A beginner's guide to the Workbuddy desktop AI agent: installation, claiming credits, file management, and building automated workflows—compared with CodeX for fit and cost, helping professionals shift from AI question-askers to AI managers.

OpenAI's New Agent Stack: Computer Use, Decisions API, and Ultra-Fast Workflows
OpenAI Dev Day unveiled a new agent stack: Computer Use outperforms humans, Decisions API delivers ultra-low-latency classification via Luna, Agents API opens the same Computer Use capabilities, and GPT-6.1 Sol costs only one-seventh of Astra. Core updates, benchmark data, and developer insights.

Liang Wenfeng Open-Sources DeepInfo Inference Framework, Takes On U.S. Ban
DeepSeek open-sources its DeepInfo inference framework after its models, featuring GPU/CPU cross-pipelining, small-model prediction with large-model verification, and full Huawei Ascend and NVIDIA chip support—facing the U.S. federal ban head-on. This article analyzes its significance for AI deployment and open-source strategy.