The Agentic AI Explosion: A Complete Guide to the Paradigm Shift from Generative to Agentic AI in 2026

In 2026, AI shifts from generative to agentic, with Agentic AI entering an explosive growth phase.
In May 2026, the global AI industry is undergoing a paradigm shift from generative to Agentic AI. AI systems now possess autonomous planning, reasoning, tool invocation, and multi-step execution capabilities, with the market projected to exceed 40% CAGR. Model iteration is accelerating, inference efficiency optimization has become a core direction, Physical AI is entering real-world deployment, and technical breakthroughs in ultra-long context windows and MoE architectures continue to emerge. The global AI landscape shows clear US-China competitive differentiation, with safety governance challenges escalating in parallel.
In May 2026, the global AI industry is undergoing a profound paradigm shift—moving from "Generative AI" to "Agentic AI." Models are no longer passively answering questions; they can autonomously plan, reason, invoke tools, and execute multi-step complex tasks. Meanwhile, model iteration is accelerating, multimodal capabilities are breaking through, Physical AI is moving toward real-world deployment, and the entire industry is reshaping the technological landscape at an unprecedented pace.
Agentic AI Enters an Explosive Growth Phase: From Dialogue to Autonomous Execution
2026 has been widely recognized as the critical breakthrough year for Agentic AI. Agentic AI refers to AI systems that are no longer limited to single-turn, passive dialogue responses but possess the capabilities of planning and reasoning, tool invocation, multi-step execution, and even autonomous workflow optimization.
From a technical architecture perspective, the core technology stack of Agentic AI comprises three key layers: the Planning layer, the Tool Use layer, and the Memory layer. The Planning layer typically relies on reasoning paradigms such as Chain-of-Thought (CoT) or Tree-of-Thought (ToT), enabling models to decompose complex tasks into executable sub-steps. The Tool Use layer, through Function Calling protocols, allows AI to operate APIs, databases, browsers, and even operating systems. The Memory layer is divided into short-term working memory (context window) and long-term persistent memory (vector databases or structured storage), enabling agents to maintain state across sessions. The maturation of this architecture marks a fundamental shift in AI from "statistical pattern matching" to "goal-directed behavior."
The strategic moves of several leading companies deserve close attention:
- OpenAI GPT-5.5 series has set the Instant version as the default ChatGPT model, reinforcing agentic capabilities with support for parallel reasoning, computer control, and contextual business scenarios, positioning it as infrastructure for the "compute-driven economy."
- Anthropic Claude series has advanced the "Dreaming" feature, where agents can periodically review historical interactions, extract patterns, and form self-experiential memory, thereby enhancing long-term autonomy. In other words, AI can not only execute tasks but also "learn and grow" from past experiences.
It's worth diving deeper into Anthropic's "Dreaming" feature, which draws from neuroscience principles of memory consolidation during human sleep. During the REM stage of human sleep, the brain reactivates daytime experiences, converting short-term memories into long-term memories and extracting abstract patterns. Claude's Dreaming mechanism similarly performs offline processing of historical interactions during inactive periods, forming reusable "experience graphs" through automatic summarization, pattern recognition, and experience distillation. This fundamentally differs from traditional Retrieval-Augmented Generation (RAG)—RAG passively retrieves existing documents, while Dreaming actively distills insights from interaction history, achieving a leap from "memory retrieval" to "experiential learning."
Agent systems and orchestration frameworks are maturing rapidly, with enterprise adoption clearly accelerating. Projections indicate that the Agentic AI market will achieve a compound annual growth rate (CAGR) of over 40%, entering an explosive growth phase. In the short term, the combination of "multi-agent orchestration + tool integration + long-term memory" will first generate significant ROI in enterprise workflows, software development, and customer service scenarios.
Accelerating Model Iteration: Efficiency and Scale Advancing in Parallel
Model iteration speed across major AI labs is accelerating, exhibiting a dual-track pattern of "efficiency first" and "scale expansion."
Latest Developments in Leading Models
- OpenAI GPT-5.5 Instant: Focuses on accuracy, speed, and real-world utility, while also launching the dedicated cybersecurity model GPT-5.5 Cyber, providing AI security support for critical infrastructure defense.
- xAI Grok 4.3: Continues to strengthen real-time reasoning and multimodal capabilities, with gradual rollout recently underway.
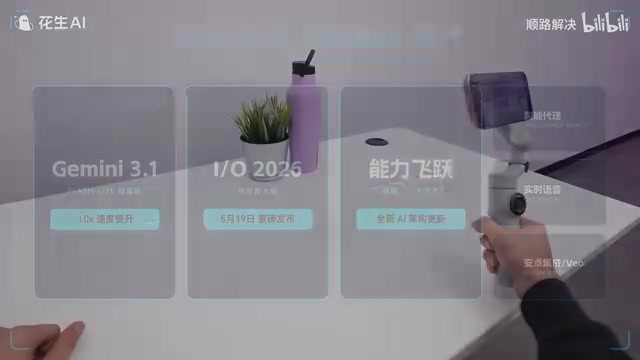
- Google Gemini 3.1 Flash-Light: The lightweight version achieves a 3x speed improvement through speculative decoding technology. More notably, Google I/O 2026 (May 19) is set to announce major Gemini updates, reportedly version 4.0 or a significant 3.X release, focusing on Gemini Intelligence agent features, hardware models, and deep Android integration with video generation.
It's necessary to explain Speculative Decoding, a key technology here. In traditional autoregressive generation, large models can only generate one token at a time, with speed limited by model scale. The core idea of speculative decoding is: first use a lightweight "draft model" to quickly generate multiple candidate token sequences, then have the large model verify the correctness of these candidate sequences in parallel. Since verification parallelism is far greater than token-by-token generation, and most candidate tokens are accepted, overall inference speed can improve 2-4x while maintaining output quality completely identical to the original large model. Google Gemini 3.1 Flash-Light's 3x speed improvement is precisely thanks to deep optimization of this technology.
DeepSeek V4 and Breakthrough Progress in Chinese Open-Source Models
Chinese open-source models like DeepSeekAd V4 continue to achieve breakthroughs in ultra-long context (million-token scale) and cost efficiency. The trend toward Small Language Models (SLMs) for specific domains is also strengthening, seeking the optimal balance between performance and deployment cost. This trend is particularly critical for enterprise AI applications—not all scenarios require the largest-scale models, and precisely-matched smaller models often deliver better cost-effectiveness.
The DeepSeek series' ability to approach frontier performance under limited compute conditions largely benefits from deep optimization of the Mixture of Experts (MoE) architecture. MoE is a sparsely activated neural network architecture whose core principle is "not all parameters need to participate in every computation." An MoE model contains multiple expert sub-networks and a Gating Network, which dynamically selects and activates only a few most relevant experts based on input. For example, an MoE model with a trillion parameters might only activate one-tenth of its parameters during inference, thereby dramatically reducing computational cost while maintaining large-model capabilities. Google's Gemini series also extensively employs MoE architecture, which has become one of the mainstream paradigms in current large model design.
Multimodal Models and Physical AI: From Virtual to Physical Worlds
The capability boundaries of multimodal foundation models are rapidly expanding, extending from text to unified processing and generation of images, audio, and video, with quality approaching Pixar-level.
Even more noteworthy is the substantial progress in Physical AI:
- NVIDIA Isaac GR-00T, Cosmos World Models, and Newton Physics Engine have released open-source GA versions, pushing robots from laboratories toward real-world deployment across manufacturing, logistics, and other scenarios.
- Platforms like ATLAS demonstrate advanced balance manipulation and natural language control capabilities.
- MeteorTribe V2's brain-predictive foundation model serves as a "digital twin" of human neural activity, achieving important progress in stimulus-response prediction.
Understanding the rapid advancement of Physical AI requires recognizing the core roles that world models and synthetic data play. A World Model is an AI system capable of understanding and simulating the operating principles of the physical world, predicting the motion trajectories and interaction outcomes of objects under different forces, velocities, and friction conditions. NVIDIA's Cosmos World Model, trained on massive video data, has learned physical laws including gravity, collisions, and fluid dynamics, generating realistic physical simulation scenarios. Synthetic data refers to virtual training data generated using these world models—robots can conduct millions of trial-and-error training sessions in digital twin environments without incurring real-world wear and safety risks. This paradigm of "training first in virtual worlds, then transferring to the real world" (Sim-to-Real Transfer) is fundamentally changing robot development cycles and cost structures.
In the medium term, Physical AI will reshape the manufacturing and service robotics industry.
Key Trends in AI Inference Optimization and Infrastructure Evolution
Ultra-Long Context Windows Become Standard
Claude Opus/Sonic has achieved widespread adoption of million-token windows, while innovative architectures like Sub-Quadratic and Geodic have previewed ultra-long context processing capabilities of up to 12 million tokens. This means AI systems can process entire books, complete codebases, or large datasets in a single pass, laying the foundation for end-to-end processing of complex tasks.
To understand the technical difficulty of this breakthrough, one must understand the fundamental bottleneck facing traditional Transformer architecture. Standard attention mechanisms have O(n²) computational complexity—every doubling of context length quadruples computation—making million-token-level context processing extremely expensive computationally. Sub-Quadratic attention mechanisms reduce complexity to approximately O(n) or O(n·log n) through methods such as linear attention, sparse attention, or hierarchical attention, thereby making ten-million-token-level context feasible. The practical significance of this breakthrough is: AI systems can comprehend an entire enterprise code repository (typically containing millions of lines of code), a complete set of legal documents, or a comprehensive medical record all at once, without needing to slice and segment information, thus avoiding comprehension biases caused by information fragmentation.
Inference Efficiency Optimization Becomes the Core Theme
Technologies including Speculative Decoding, Mixture of Experts (MoE), and Small Language Models (SLM) are dominating the efficiency optimization direction. A key data point: inference computation is expected to account for two-thirds of total AI compute, highlighting the strategic importance of AI inference efficiency optimization. The implication of this ratio is: compared to model training (a one-time large-scale computation), the continuous inference computation during actual user service is the primary driver of compute consumption. As AI applications proliferate and multi-step reasoning demands from Agentic AI surge, inference-side compute demands are growing exponentially. On-device AI acceleration is also advancing rapidly, enabling more AI capabilities to run on edge devices.
AI Safety and Governance Challenges Escalate
As Agentic AI system capabilities improve, safety concerns are becoming increasingly prominent. The US, UK, Australia, Canada, and New Zealand have jointly published safety guidelines for Agentic systems, and pre-release review discussions for models are also increasing. You may not have noticed, but research papers emphasize the criticality of compute control in the US-China AI race, pointing to a 12 to 24-month leadership window.
"Compute control" refers to the geopolitical strategy of restricting adversaries from accessing advanced AI compute through export controls, chip bans, and similar measures. Since 2022, the US has continuously tightened restrictions on advanced chip exports to China, covering high-end GPUs like NVIDIA A100/H100/H200 and advanced lithography equipment. The "12 to 24-month leadership window" mentioned in the paper means that at current technology diffusion rates, the US lead in frontier AI capabilities may only be maintained for one to two years. This assessment is based on two key variables: first, the speed at which China approaches frontier performance under limited compute through architectural innovation (such as DeepSeek's MoE optimization), and second, the maturation progress of alternative chip supply chains (such as Huawei's Ascend series). This makes the AI race not merely a technology competition but also a contest of industrial policy and supply chain control.
2026 Global AI R&D Landscape and Forward-Looking Insights
The current global AI R&D landscape exhibits clear differentiation:
- United States: Dominates global top-tier laboratories, focusing on agentic capability enhancement and infrastructure development, with massive funding supporting compute expansion.
- China: Represented by DeepSeek, continues to push forward on open-source and cost-effective models, forming differentiated competitive advantages.
- Europe and other regions: Emphasizing governance frameworks and domain-specific applications.
Core Assessments and Risk Warnings
AI technology in May 2026 is in the midst of a paradigm shift from Generative → Agentic → Embodied. Core compute power remains a bottleneck, but efficiency innovations, small model optimization, inference optimization, and agent autonomy are broadening the boundaries of practical deployment.
Risks to watch include: safety, ethical, and control challenges accompanying increased Agentic AI autonomy; energy and compute bottlenecks; geopolitical factors affecting technology timelines; and the potential atrophy of human capabilities from over-reliance on AI. "Human capability atrophy" refers to the phenomenon where, as AI agents take on increasing cognitive tasks—from code writing to decision analysis—human practitioners may gradually lose the ability to independently complete these tasks, similar to how GPS navigation has degraded human sense of direction. This risk is particularly noteworthy in fields requiring deep professional judgment such as education, medical diagnosis, and engineering design.
With Google I/O 2026 approaching, this week will further clarify Google's strategic positioning in agentic capabilities and Android AI, serving as an important technology bellwether for the industry.
Key Takeaways
- In 2026, Agentic AI enters an explosive growth phase, with AI shifting from passive dialogue to autonomous planning, reasoning, and execution, with the market projected to achieve over 40% CAGR
- Model iteration is accelerating, with leading companies like OpenAI, Google, and xAI releasing frequent updates, while China's DeepSeek V4 continues breakthroughs in ultra-long context and cost efficiency
- Physical AI moves from laboratories to real-world deployment, with platforms like NVIDIA driving robot adoption in manufacturing and logistics scenarios
- Inference computation is expected to account for two-thirds of total AI compute, with efficiency optimization (Speculative Decoding, MoE, SLM) becoming the core technical direction
- Global AI landscape shows clear differentiation, safety governance challenges escalate, and multiple nations jointly publish Agentic system safety guidelines
Related articles
Deep Dive into AI Agent Skill Design: …
Deep Dive into AI Agent Skill Design: Engineering Practices from Anthropic and Perplexity
A deep dive into Skill design philosophy from Anthropic's Claude Code team and Perplexity's Agent team, covering the Tax Test, Gotchas Flywheel, progressive disclosure, and Eval-First practices for building high-quality AI Agent skill systems.
Deep Dive into OpenAI's Official GPT-5…
Deep Dive into OpenAI's Official GPT-5.6 Prompting Guide: The Shift from Manual to Automatic
A deep dive into OpenAI's official GPT-5.6 Sol prompting guide: conciseness-first, outcome-oriented design, autonomy boundaries, tool routing, and reasoning intensity tuning.
 Deep Dives
Deep Dive into How OpenClaw (Open-Source Crayfish) AI Agent Works
Deep analysis of OpenClaw AI Agent internals: System Prompt, tool calling, SubAgents, Skill system, memory, and Context Engineering explained.