The Debate on the Nature of RL Environments: Can PDFs Be RL Environments Too?

The quip "every RL environment is a PDF environment" reveals that RL environments are essentially state-action-reward loops, not physical simulations.
Starting from the Twitter quip "Every RL environment is just a PDF environment if you're brave enough," this article explores the boundaries of reinforcement learning environment design. The author points out that while traditional RL environments rely on game or robot simulators, PDF documents can also be modeled as environments: state is the read content and query context, actions are page-turning or retrieval, and reward comes from answer accuracy. This reveals that the core of an RL environment is not physical simulation but the definition of a state-action-reward loop. The article further analyzes the recent "de-simulatorization" trend—using LLMs to generate tasks and evaluate results, packaging static information sources like documents and web pages into interactive environments, greatly reducing construction costs but also introducing challenges like reward noise and state sparsity. Finally, the author suggests teams re-examine whether static data assets can be packaged as trainable environments.
The RL Environment Design Philosophy Behind a Quip
Recently, a playful quip has been circulating on Twitter: "Every RL environment is just a PDF environment if you're brave enough."
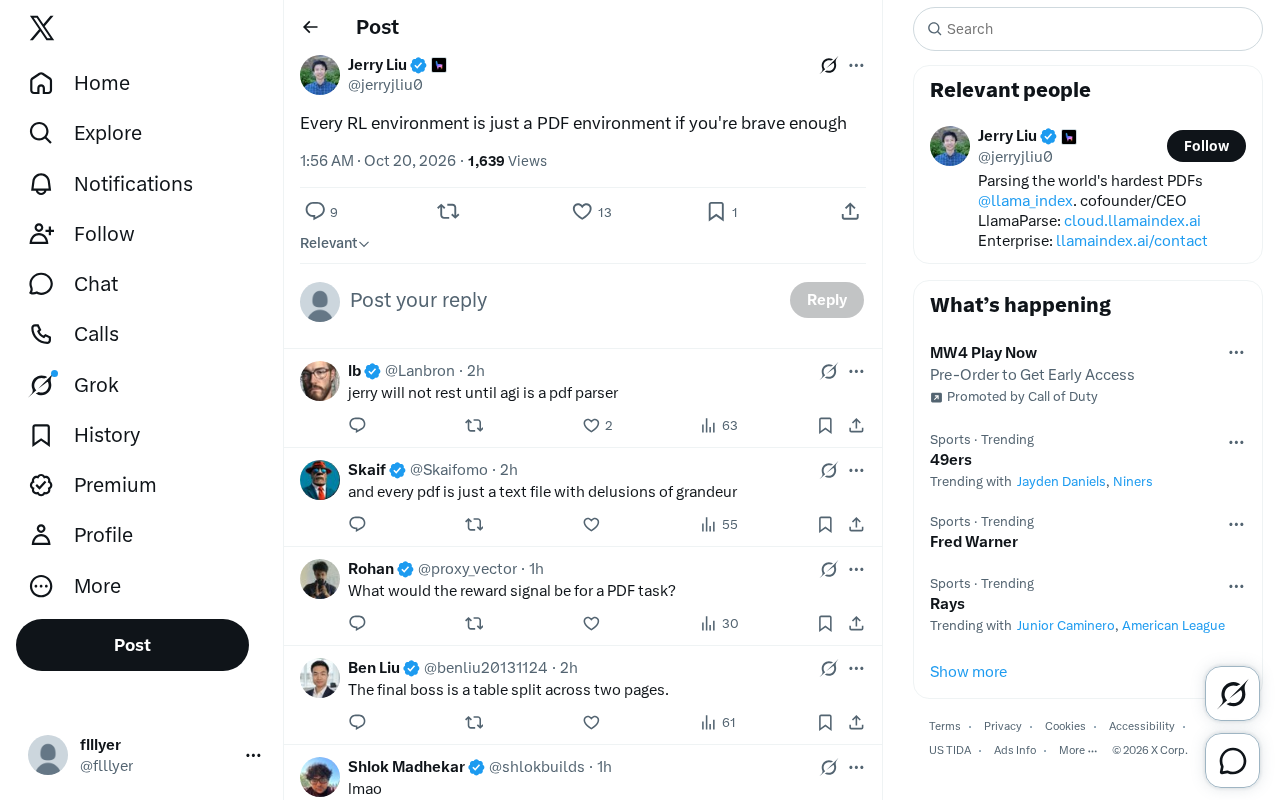
At first glance, this sounds like an inside joke in tech circles, but it precisely hits a real pain point in reinforcement learning (RL) research: where exactly do the boundaries of environment design and abstraction lie? When we treat a PDF document as an interactive environment, the applicable boundaries of RL are redefined.
Why the "PDF Environment" Notion Deserves Serious Consideration
In traditional RL research, environments usually refer to game simulators, robot simulators, or trading market backtesting systems. These environments have well-defined state transitions, action spaces, and reward signals. PDF documents appear static and lack these characteristics—but from another angle, they can absolutely be modeled as environments.
Imagine a document question-answering agent: the state is the currently read page content and the query context, the actions are turning pages, searching for keywords, or extracting paragraphs, and the reward comes from the accuracy of the answer. In this way, the PDF is no longer "data" but an "environment."
This idea is not just wordplay. It reveals a deeper trend: the core of an RL environment is not physical simulation, but the closed-loop definition of state-action-reward. As long as you can define this closed loop, any information source can become an environment.
In reinforcement learning, an environment is typically formalized as a Markov Decision Process (MDP): the state space (\mathcal{S}) represents all possible world states, the action space (\mathcal{A}) represents the operations the agent can perform, the transition function (P(s'|s,a)) defines how the state evolves with actions, and the reward function (R(s,a)) provides immediate feedback. The PDF environment holds precisely because we can define these four elements for a document question-answering task: the state is the combination of read pages and the query, the actions are page-turning or retrieval, transitions are determined by the document structure (e.g., turning the page leads to the next page), and the reward comes from answer correctness. Even if transitions are deterministic (turning the page inevitably leads to the next page), it still satisfies the MDP framework and can therefore be trained with RL algorithms. This explains why a "static document" does not prevent it from being an environment—the key is whether the closed loop can be defined, not whether the world is dynamic.
Rethinking the Environment Abstraction Layer
In the past two years, research on RL environments has shown a clear "de-simulatorization" tendency. On one hand, language models themselves are beginning to be used as part of the environment—using LLMs to generate tasks, evaluate results, and even simulate user feedback; on the other hand, researchers are packaging static information sources such as documents, web pages, and databases into interactive environments.
This shift has two direct consequences. First, the cost of building environments has dropped significantly. In the past, building a simulation environment required weeks of engineering work; now, a structured document collection plus a reasonable action interface can potentially form a trainable environment. Second, the reliability of evaluation faces new challenges—the state space of a PDF environment is essentially discrete and enormous, and reward signals often rely on LLM judgment, which introduces more noise.
Behind "de-simulatorization" is a key technical enabler: large language models (LLMs) as environment components. Traditional simulators require hand-crafted physics rules or game logic, whereas LLMs can play three roles: task generator (automatically producing diverse queries), environment simulator (returning reasonable textual feedback based on actions), and reward judge (evaluating answer quality and giving scores). This paradigm is called LLM-as-a-judge or LLM-in-the-loop, and it allows unstructured information sources (such as PDFs) to provide usable reward signals. But the cost is a decrease in reward determinism and reproducibility—the same answer may receive different scores under different prompts or sampling, which poses challenges to training stability and is a hot research issue.
A Game for the Brave: Boundaries and Risks
The phrase "If you're brave enough" is not pure humor. Treating a PDF as an RL environment means accepting several realities:
- The state representation is extremely sparse, and the agent may get lost in a large amount of irrelevant text;
- Reward signals are difficult to make deterministic and require heuristics or model-based judgment;
- The cost of environment resetting and trajectory sampling is higher than that of traditional simulators.
But conversely, this is exactly where its value lies—it forces researchers to confront the complexity of real information environments rather than gaming scores in clean simulators.
State sparsity is the most direct engineering challenge of PDF environments. In traditional simulators, state vectors are usually low-dimensional and continuous, making exploration easy for agents; in PDF environments, states are essentially high-dimensional discrete combinations of text fragments, and most states provide no information gain for the task goal. This leads to extremely low exploration efficiency, and agents easily fall into "page-turning loops" or get stuck in "irrelevant paragraphs." Common mitigation methods include: introducing a retrieval module to narrow the candidate range first, using curriculum learning to gradually transition from short documents to long documents, and designing intermediate rewards (e.g., giving a small reward each time a relevant paragraph is retrieved). These techniques essentially artificially construct dense signals in sparse reward spaces, belonging to the category of reward shaping in RL engineering.
Implications for RL Engineering Practice
The discussion sparked by this quip on Twitter essentially reflects the community's recognition of the idea that "the environment is the interface." For teams working on RL applications, it is worth re-examining their data assets: can those PDFs, web pages, and knowledge bases treated as static corpora be repackaged as environments for training and evaluating agents?
The answer depends on whether you are willing to accept imperfect reward signals and sparse state spaces. But at least, this quip provides a valuable starting point for thought: the essence of an RL environment is the interaction protocol, not the physical world.
Related articles

Claude Reportedly Able to Hide Secret Messages in Benign Images
A Reddit post claims Claude Fable 5.1 can hide secret messages in benign images. This article reviews the background, image steganography principles, and potential security risks, and suggests a testing path from rumor to verification.

Federal Government Awards $85 Million; CFS to Develop Fusion-Specific Semiconductors
The federal government awards $85 million to Commonwealth Fusion Systems to develop conductors and power semiconductors for fusion plants. This article analyzes the significance of this funding for the fusion supply chain and commercialization path.

When Should AI Assistants Proactively Suggest? Timing Is Everything
When should AI assistants proactively suggest? Reddit discussion reveals: the same suggestion feels different at different times. This article analyzes the dual nature of proactive suggestions, the boundary of user expectations, and design principles, exploring how to balance automation and user control.