The Geometry of Language Model Logits: Generic Structure and Learned Departures

Sorted logits in language models follow a log-linear relation, and the post-training slope α rises markedly and correlates with predictive performance.
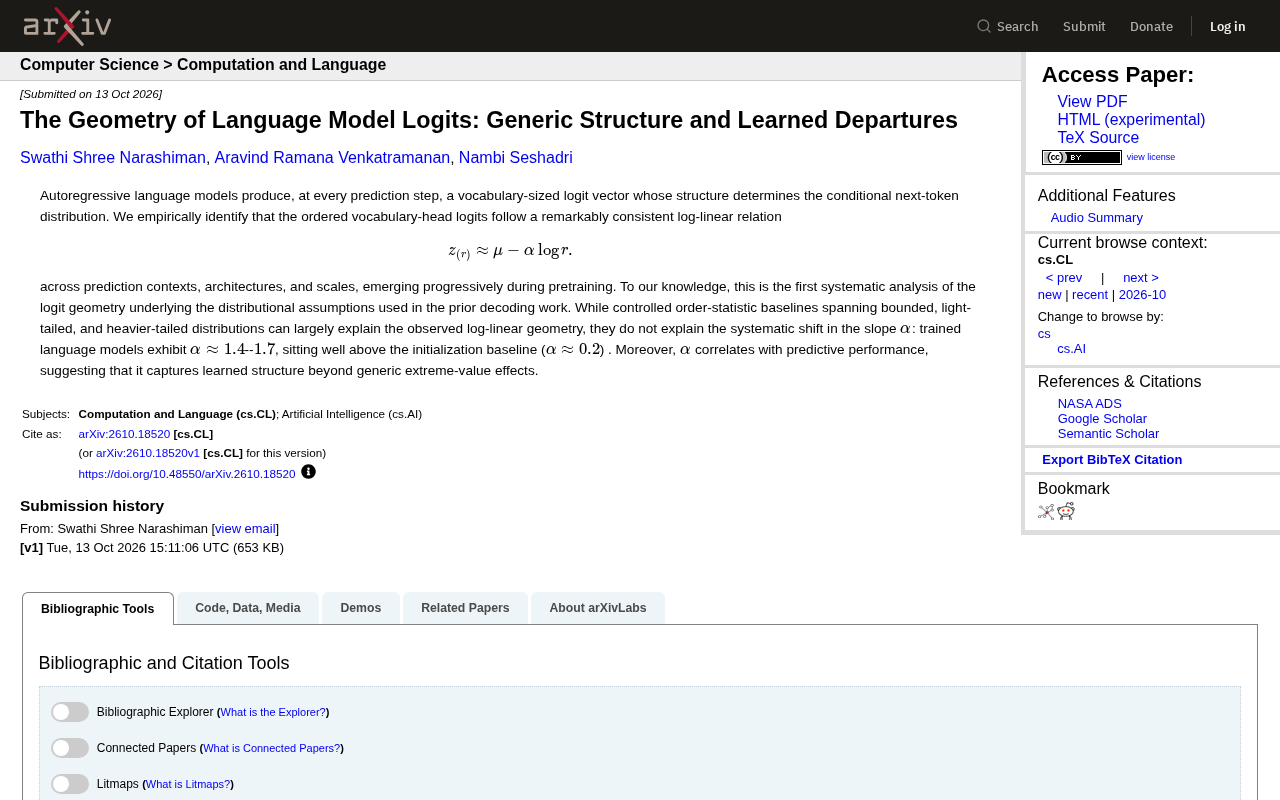
The paper provides the first systematic analysis of language model logit geometry, finding that sorted vocabulary logits follow a log-linear relationship z_(r) ≈ μ − α log r across architectures, scales, and contexts. Generic extreme-value baselines explain the shape but not the post-training slope α, which rises from about 0.2 at initialization to 1.4–1.7. Crucially, α correlates with predictive performance, suggesting it captures learned structure beyond generic extreme-value effects. The work offers new perspectives for decoding, model diagnostics, and training dynamics, while raising open questions about what drives α upward.
Autoregressive language models produce a vocabulary-sized logit vector at each prediction step, and its structure determines the conditional probability distribution over the next token. Decoding strategies have long been built on assumptions about the distributional properties of these logits, yet the geometric form of the logits themselves has rarely been studied systematically. A paper titled The Geometry of Language Model Logits: Generic Structure and Learned Departures provides the first empirical analysis of this underlying structure, revealing consistent patterns across models and scales, as well as systematic departures learned during training.
Key Finding: A Log-Linear Rank Relationship
The researchers found that when vocabulary logits are sorted in descending order, the relationship between rank (r) and logit value (z_{(r)}) exhibits a strikingly log-linear form:
[ z_{(r)} \approx \mu - \alpha \log r ]
This relationship appears consistently across a variety of prediction contexts, architectures, and parameter scales, and it emerges gradually during pretraining. According to the paper, this is the first systematic analysis of the logit geometry underlying the distributional assumptions used in prior decoding work.
The significance of this pattern is that it suggests a generic extreme-value statistical structure in the language model output layer—the highest-probability tokens and lower-probability tokens decay uniformly on a logarithmic scale. This offers a new theoretical perspective for understanding the effectiveness of decoding methods such as sampling, top-k, and nucleus sampling.
Logits and extreme-value statistics: The logit vector output by the final layer of a language model can be viewed as a score for each token in the vocabulary, which is converted into a probability distribution via softmax. The relationship between the r-th largest value z_(r) after sorting the logits in descending order and its rank r essentially falls within the domain of order statistics. In extreme value theory, the tail or upper-order statistics of many probability distributions exhibit approximately linear decay patterns; if linearity persists after taking the logarithm of the rank, it is called log-linear. The paper's discovery that z_(r) ≈ μ − α log r implies that the logits of lower-ranked tokens decay more slowly at a uniform rate with respect to log r, forming a "long-tailed but controllable" structure. This form resembles the manifestation of Zipf's law in word frequency distributions, but here it describes the geometry of the model's output layer rather than corpus statistics.
Decoding strategies and logit distribution assumptions: Decoding methods such as top-k, top-p (nucleus sampling), and temperature sampling typically implicitly assume that the logit or probability distribution has a certain shape—for example, temperature scaling assumes that a single temperature parameter can adjust the sharpness of the distribution, and top-p assumes that probability mass is concentrated in the head. These methods are effective in practice, but their effectiveness lacks validation against the true logit geometry. The discovery of the log-linear rank relationship provides a more concrete structural basis for these decoding strategies: if logits decay linearly with log r, then the effects of truncation position and temperature adjustment can be quantitatively described using α and μ, rather than relying on vague intuitions of "sharp/flat."
Generic Baselines Explain the Shape but Not the Slope
To test whether this log-linear relationship is merely an inevitable consequence of extreme-value statistics, the researchers constructed controlled order-statistic baselines covering bounded distributions, light-tailed distributions, and heavy-tailed distributions. These baselines can indeed reproduce the observed log-linear geometry to a large extent—that is, it is not surprising that sorted logits exhibit log-linearity, since many probability distributions show similar behavior after a rank transformation.
But the key divergence appears in the slope (\alpha). Trained language models show (\alpha \approx 1.4)–(1.7), whereas the baseline for initialized models is only (\alpha \approx 0.2). This large gap cannot be explained by generic extreme-value effects, indicating that training imbues the logits with some additional structure.
Order-statistic baselines: The controlled baselines constructed by the researchers refer to independently sampling a large number of values from known distributions (such as bounded, light-tailed, and heavy-tailed distributions), then sorting them and observing the form of their order statistics. Such baselines simulate "what would happen if logits were just random noise after sorting." The results show that many distributions do indeed produce approximately log-linear shapes after sorting, indicating that log-linearity itself is not special. However, the slope α reflects the decay rate: α ≈ 0.2 for initialized models means the logits are nearly flat, with very slow decay after sorting; α ≈ 1.4–1.7 after training means the gap between head tokens and tail tokens is significantly widened, and this widening follows a specific logarithmic scale. This contrast shows that training does not simply sharpen the distribution, but shapes a geometric structure with a specific slope.
The Slope α Correlates with Predictive Performance
More strikingly, the slope (\alpha) correlates with the model's predictive performance. This means that (\alpha) is not merely a descriptive statistic; it may capture structured knowledge that the model acquires during training beyond generic extreme-value effects.
In other words, language models do not merely learn to output "sharp" or "flat" distributions—they learn a specific logit geometric form, and this form is directly tied to model quality. This offers a potential signal for assessing training status and even for designing new training objectives.
α as a model diagnostic metric: The correlation between the slope α and predictive performance suggests that it may reflect the degree to which the model captures learnable structure in the data. Early in training, the model's output is close to a uniform distribution and α is low; as training progresses, the model learns to concentrate probability mass on the correct token, and α rises. But higher α is not always better—an excessively high α may indicate that the model is overconfident and has reduced generalization ability. Therefore, monitoring the trajectory of α can help determine whether training is in a healthy stage, similar to observing the loss curve or gradient norm. In addition, different training objectives (such as contrastive learning or masked language modeling) may produce different α ranges, providing a new dimension for comparing different training paradigms.
Implications for Decoding and Model Analysis
This research fills a theoretical gap: previous decoding methods (such as top-k, top-p, and temperature sampling) are mostly based on simplified assumptions about the logit distribution, but these assumptions have rarely been validated. Now we know that the logit ordering of real language models follows a log-linear pattern, and the slope carries training information.
This yields at least two insights. First, the design of decoding strategies can exploit this geometric structure more precisely, rather than relying on rough distributional assumptions. Second, the slope (\alpha) may become a lightweight model diagnostic metric—monitoring changes in (\alpha) during training may help determine whether the model is learning valuable structure.
The paper also notes that controlled baselines cannot fully explain the slope shift, leaving room for further research: which factors during training drive the increase in (\alpha)? How do different training objectives, data distributions, and model architectures affect this slope? These questions remain to be answered.
Conclusion
This research provides the first systematic characterization of the geometric structure of language model logits, revealing a cross-model consistent log-linear rank relationship, and finds that the post-training slope (\alpha) is significantly higher than the initialization baseline and correlates with predictive performance. It offers new entry points for decoding theory, model diagnostics, and the analysis of training dynamics.
One-line Summary
Sorted logits in language models follow a log-linear relationship, and the post-training slope α rises significantly and correlates with predictive performance.
Paragraph Summary
The paper provides the first systematic analysis of the geometric structure of language model logits, finding that after sorting vocabulary logits in descending order, rank and logit value follow a log-linear relationship z_(r) ≈ μ − α log r, consistent across architectures, scales, and contexts. Generic extreme-value statistical baselines can explain this log-linear shape, but cannot explain why the slope α rises from about 0.2 at initialization to 1.4–1.7 after training. More critically, α correlates with the model's predictive performance, indicating that it captures learned structure beyond generic extreme-value effects. This research offers new perspectives for decoding strategy design, model diagnostics, and the analysis of training dynamics, while leaving open questions such as which factors during training drive the increase in α.
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.