The TGIT Framework: Translating Plain-Language Commands for Aerial Navigation AI

TGIT translates plain user commands into navigator-ready instructions, lifting drone navigation success from 11% to 32%.
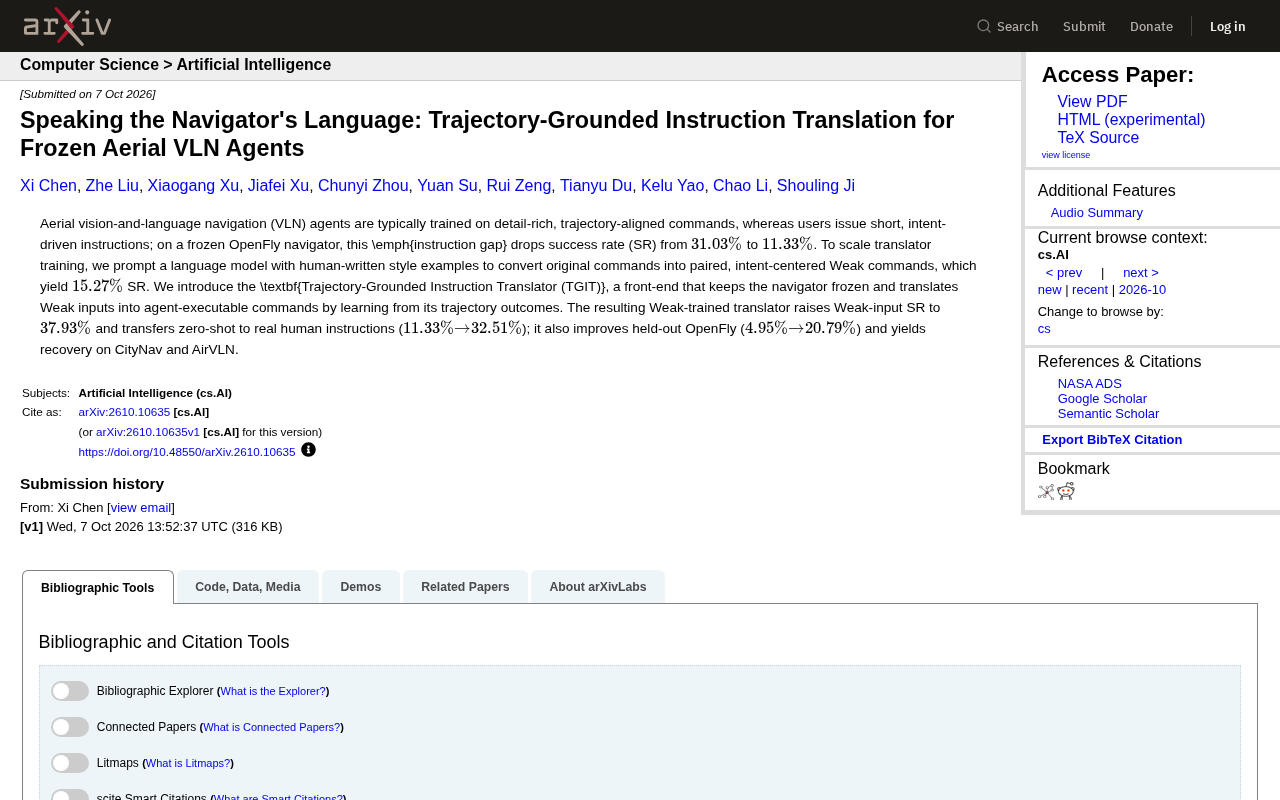
Aerial VLN faces a critical instruction gap: training data uses detailed, structured commands while real users speak in short, casual phrases — causing a frozen navigator's success rate to drop from 31% to 11%. The paper introduces TGIT (Trajectory-Grounded Instruction Translator), a lightweight front-end translator that keeps the navigation model fully frozen and converts weak user instructions into the format the navigator understands, using actual flight trajectory outcomes as the training signal. Zero-shot transfer to real human instructions improves from 11.33% to 32.51%, with consistent gains across OpenFly, CityNav, and AirVLN benchmarks.
When AI Can't Understand Plain Speech
Aerial Visual-Language Navigation (Aerial VLN) is emerging as a key direction for intelligent drones — users issue natural language commands, and the drone flies autonomously through complex environments. But a formidable gap exists in practice: the instructions used to train these agents are typically detail-rich commands precisely aligned with flight trajectories, while real users speak in short, intent-driven, conversational phrases.
A new arXiv paper quantifies just how serious this problem is: on a frozen OpenFly navigator, switching from detailed training commands to short user-style instructions causes the success rate (SR) to plummet from 31.03% to 11.33%. In other words, the "instruction gap" cuts the model's real-world usability by nearly two-thirds.
The phenomenon is intuitive enough: humans don't talk like annotators. Nobody says "fly forward 50 meters and turn left at the red-roofed building" — they say "head over to that red house." A navigator never trained to handle this kind of phrasing will naturally struggle to act on it.
Visual-Language Navigation (VLN) is a class of tasks where an agent moves through a visual environment following natural language instructions, and is one of the core research areas in Embodied AI. Ground-level VLN has mature benchmarks like R2R, while Aerial VLN faces more complex three-dimensional spaces, wider fields of view, and higher real-time decision-making demands. OpenFly is currently one of the largest aerial VLN datasets and navigator frameworks; its training instructions are carefully crafted by annotators and include directional, distance, and landmark details aligned segment-by-segment with flight trajectories. While this aids model learning, it diverges sharply from how real users express themselves. The "instruction distribution shift" problem is often underestimated at deployment time — and one of this paper's contributions is using quantitative data to clearly reveal the real cost of that shift.
The Elegant Fix: Change the Input, Not the Model
The most direct solution to the instruction gap would be to retrain the navigator, but that's costly and risks damaging existing capabilities. The paper takes a different approach — keeping the navigator completely frozen and inserting a "translation layer" in front of it.
This translation layer is called the Trajectory-Grounded Instruction Translator (TGIT). Its job is to convert a user's "weak commands" (short, intent-driven expressions) into the instruction format the navigator understands and can execute. The key innovation is that TGIT doesn't rely on simple text paraphrasing — instead, it learns from the navigator's trajectory execution results. By observing whether a translated instruction actually produces a successful flight trajectory, TGIT optimizes its own translation strategy.
This design philosophy has significant engineering value: in many real-world scenarios, the underlying navigation model may be an unmodifiable black box, or retraining it may be prohibitively expensive. TGIT shifts the adaptation work to the front end, protecting existing model assets while enabling adaptation to new instruction styles.
The source of TGIT's training signal is its core innovation. Common text rewriting methods optimize for generation quality or semantic similarity — but these signals don't guarantee that the rewritten instruction will actually get the navigator to the right place. TGIT uses trajectory-level rewards: the translated instruction is fed into the frozen navigator for execution, and whether the flight trajectory reaches the target provides the feedback signal to update the translator's parameters. This is essentially a reinforcement learning or execution-grounded training paradigm — consistent with the recent trend in code generation and tool use, where "does it run successfully" serves as the reward. This closed-loop design directly aligns the translator's optimization objective with the final task, rather than relying on linguistic proxy metrics.
Where the Training Data Comes From
To train the translator, paired data — "weak command → standard instruction" — is needed first. The paper's approach: use human-written style examples to prompt a language model, converting detailed original commands into intent-centered weak instructions to generate paired data at scale.
This step itself validates the problem's existence. Feeding these synthetic weak instructions directly to the navigator yields a 15.27% success rate — between the detailed command baseline (31.03%) and real user instructions (11.33%) — confirming that the synthetic data does a good job of mimicking how users actually express themselves.
Results: Jumping from 11% to 32%
TGIT's experimental results are impressive. After training with weak instructions:
- Success rate on weak instruction inputs rose from 15.27% to 37.93% — actually surpassing the original detailed command baseline of 31.03%;
- More critically, zero-shot transfer to real human instructions improved from 11.33% to 32.51%, nearly matching the performance with detailed commands;
- On the unseen OpenFly test set, success rate climbed from 4.95% to 20.79%;
- Performance was also recovered on two independent benchmarks, CityNav and AirVLN.
These numbers suggest TGIT learned not an overfitted mapping to a specific dataset, but a generalizable "instruction alignment" capability. The translator bridges the gap between user language and model language, allowing the frozen navigator to perform close to its trained potential.
Significance and Limitations
TGIT's approach has implications for VLN broadly and for human-computer interaction more generally. At its core, it proposes a decoupled paradigm: separating "understanding user intent" from "executing navigation", letting each be optimized in the most appropriate way. This resonates with the prompt engineering and adapter approaches common in large model applications today — but TGIT's distinguishing feature is using real downstream trajectory results as the training signal, rather than purely linguistic similarity.
Of course, as a newly released preprint, this paper merits further scrutiny. Questions worth watching include: the translator's robustness to navigator errors, performance on more complex multi-step instructions, and the sample efficiency of trajectory-feedback training. But based on the multi-benchmark results reported, this is a direction with real practical and scalable value — especially for teams that have mature navigation models but struggle to handle the diversity of user instructions.
The "frozen backbone + lightweight front-end adapter" paradigm that TGIT embodies shares conceptual ground with parameter-efficient fine-tuning (PEFT), but works in the opposite direction: PEFT typically inserts a small number of trainable parameters inside the model (e.g., LoRA, Adapters), while TGIT externalizes all adaptation to the input side. The advantage of this external approach is zero intrusion on the underlying model — whether the navigator uses open-source weights or a commercial API, TGIT can be plugged in seamlessly. The potential limitation: the translator cannot fix the navigator's own capability ceiling. If the navigator was never good at certain scenarios, better translation won't help. Additionally, trajectory-feedback training depends on the availability of a simulation environment; in purely physical real-world deployments, obtaining training signals becomes significantly more expensive — an engineering challenge this direction will need to address in the future.
Related articles

Gaussian Process Bandit Optimization: Exploration Strategies and Inference Regret Guarantees
Cumulative regret guarantees in Bayesian optimization fail to reflect final recommendation quality. This article examines a new study that provides inference regret guarantees for Gaussian process bandit optimization through exploration query strategies and fill distance analysis, validated on hyperparameter optimization and control tasks.

The Most Detailed Codex Guide on Bilibili: From Installation to Real-World Practice
The most detailed Codex guide on Bilibili: from app store installation to daily work mode configuration, with a real coffee shop project demonstrating file organization, data extraction, dashboard creation, and other practical tasks. Learn to use Plan Mode and desktop pets to leverage Codex efficiently.

Appearance Compensation in Volume Rendering: Why RGB Accuracy Cannot Guarantee Density Correctness
Volume rendering research reveals that volumetric data perfectly reproducing external RGB views may still contain density errors: appearance compensation can double central density and keep external rays unchanged even when L2 error exceeds 14.52%. Density recovery depends on appearance capacity, spatial resolution, and measurement design.