The 'Visual Thinking' of AI Agents: A Quiet Cognitive Revolution

AI agents are gaining human-like visual thinking, reasoning and planning through internal visual representations.
The article explores an emerging trend in AI agents: endowing them with 'visual thinking'—constructing and manipulating internal visual representations to understand the world and plan actions rather than relying solely on text reasoning chains. Built on multimodal large models and visual chain-of-thought, this enables better performance in spatial reasoning and physical interaction. Applications include software automation and embodied robots. Challenges include reduced interpretability, high computational cost, and lack of evaluation standards, with debate between symbolic and end-to-end visual reasoning.
When Agents Start to 'Think in Images'
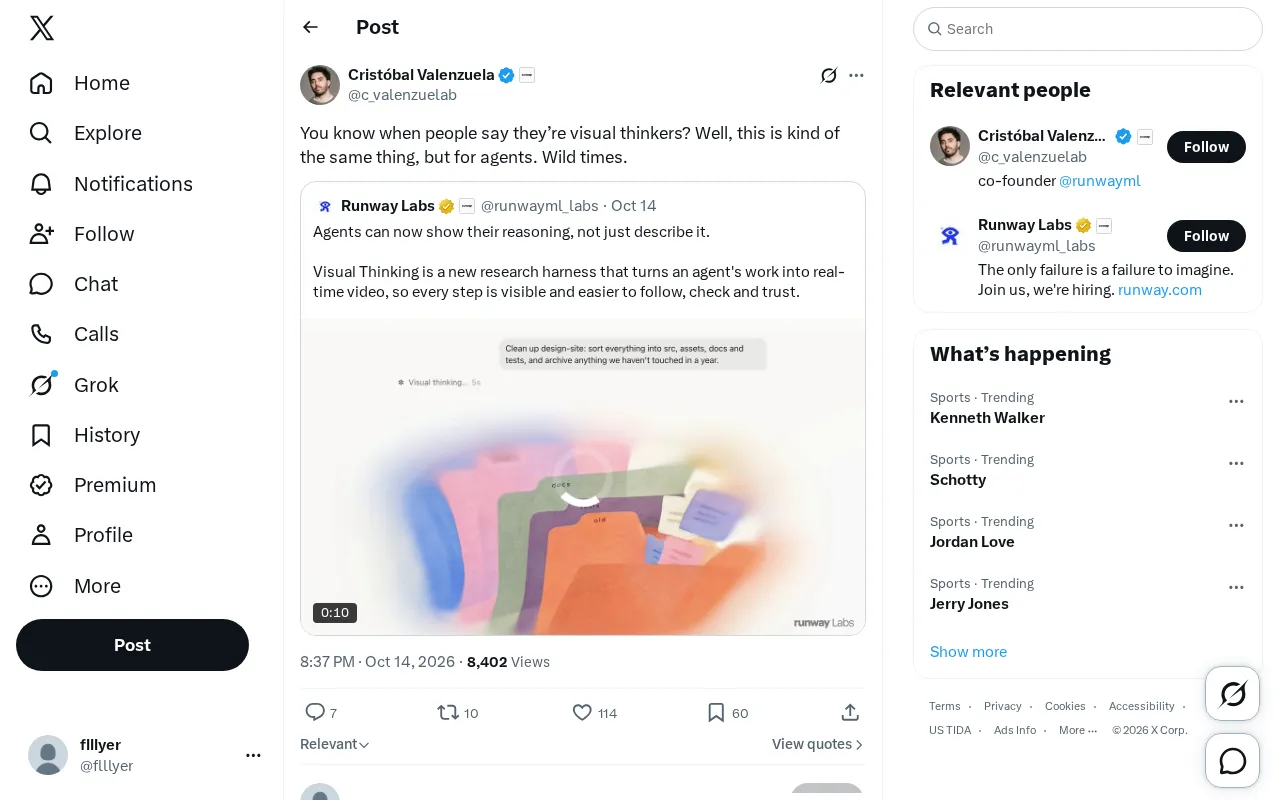
"You know when people say they're visual thinkers? Well, this is kind of the same thing, but for AI agents. Crazy times." This short tweet, paired with a screenshot, precisely captures a subtle yet pivotal shift in the current AI landscape: we are endowing AI agents with a capability akin to human 'visual thinking.'
This does not refer to simple image recognition, but rather to agents being able to construct, manipulate, and leverage internal visual representations during their decision-making processes to understand the world and plan actions. This sounds like science fiction, but it is one of the most cutting-edge directions in multimodal AI research today.
What Is an Agent's Visual Thinking?
Humans do not always rely on language when solving problems. We imagine the rotation of objects, the layout of spaces, and the consequences of actions in our minds. This 'mental simulation' capability is an important hallmark of intelligence.
For AI agents, the traditional paradigm is text-based reasoning chains. Agents receive text instructions, generate text plans, and execute text actions. However, this approach falls short when it comes to spatial relationships, physical interactions, and navigation in complex environments.
An agent's visual thinking means the agent no longer 'thinks' solely through words, but 'imagines' and 'plans' through visual representations. For example, before grasping a cup, a robot will internally 'see' the cup's three-dimensional structure, the location of the grasp point, and the trajectory of its arm movement. This capability extends the agent's reasoning from one-dimensional text sequences to two-dimensional and even three-dimensional visual spaces.
Technological Foundations: From Multimodal Perception to Visual Reasoning
This shift did not happen out of thin air. It is built upon the deep accumulation of research in multimodal large models and embodied intelligence over the past few years.
The Evolution of Multimodal Large Models
Early vision models could only perform classification or detection. Today's large models, such as GPT-4V and Gemini, are capable of jointly understanding images and text. They can not only 'see' objects in images but also 'understand' the relationships between objects and implicit physical common sense. This provides agents with foundational visual perception and description capabilities.
Visual Chain-of-Thought and Internal Representations
Further research, such as visual chain-of-thought, enables models to generate a series of visual intermediate steps before producing an answer. This is similar to humans sketching on paper to aid their thinking. Agents no longer merely output text but produce annotations of images, region segmentations, or generated schematic diagrams as intermediate products of reasoning.
According to interpretations of relevant papers by Bilibili uploaders and YouTube channels, such 'visual drafts' can significantly improve model performance in spatial reasoning and complex problem-solving. Multiple independent analyses point to a consensus: introducing a visual thinking step is a key pathway to enhancing an agent's ability to understand environments and plan.
Visual Chain-of-Thought (VCoT) is an extension of text-based chain-of-thought into the visual modality. Its core idea is that before giving a final answer, the model generates a series of intermediate visual products—which may be local annotations of images, crops of key regions, schematic sketches, or even newly generated images. These visual intermediate steps serve as 'thinking drafts,' helping the model decompose complex spatial or physical reasoning into manageable sub-problems. Compared with pure text reasoning chains, the advantage of VCoT lies in directly operating on representations isomorphic to the problem (such as spatial layouts), avoiding the information loss incurred when forcing three-dimensional relationships into one-dimensional text sequences. Research has shown that in tasks requiring multi-step spatial inference, introducing visual drafts can significantly improve accuracy.
Application Prospects: From Virtual Assistants to Embodied Intelligence
In which domains will agents' visual thinking first explode?
Smarter Virtual Assistants and Automated Workflows
In the field of software automation, agents need to operate graphical interfaces. Agents with visual thinking can 'look at' the screen, understand buttons, menus, and window layouts, thereby completing clicks, drags, and other operations more robustly rather than relying on fragile DOM selectors.
DOM Selector (Document Object Model Selector) is a traditional way to locate web elements in software automation, for example, finding a button or input box through an element's ID, class name, or XPath path. However, when page structures change dynamically, elements are obscured, or rendering is complex, DOM selectors are highly prone to failure. Agents with visual thinking take a different approach: they directly 'look at' screenshots and identify the visual features of buttons, menus, and windows like humans do, thereby bypassing dependence on underlying code structures. This visually driven mode of operation is more robust and closer to real user interaction patterns, and is one of the key capabilities for building general software automation agents.
Embodied Intelligence and Robotics
This is the most exciting application scenario. Robots need to navigate and manipulate objects in the physical world. Visual thinking enables robots to conduct 'mental rehearsals' before acting, predict the consequences of actions, and avoid danger. According to unique insights from a single source, some frontier laboratories are exploring ways for robots to directly learn and build internal visual models by watching human videos, enabling more natural human-robot collaboration.
Embodied AI emphasizes that an intelligent agent must have a physical body and learn and evolve through real-time interaction with the environment. Unlike pure software agents, embodied agents face continuous state spaces, physical constraints, and real-time requirements. Visual thinking plays a key role here: robots need to construct internal simulations of objects' three-dimensional structures, grasp points, and motion trajectories before acting, and this 'mental rehearsal' can greatly reduce trial-and-error costs. Current mainstream paths include training visual-motor policies in simulated environments and imitation learning by watching human videos. The latter especially relies on agents transforming observed visual sequences into executable internal action plans, which is an important prerequisite for achieving natural human-robot collaboration.
Challenges and the Unknown: The Black Box of Thought and Interpretability
Endowing agents with visual thinking is not without cost. It brings new challenges.
Decline in interpretability. Text reasoning chains are already difficult to explain, and when the reasoning process occurs in high-dimensional visual space, it becomes even harder for humans to understand why an agent makes a particular decision. How do we debug a visual brain that 'thinks' incorrectly?
Computational cost and real-time performance. Generating and manipulating internal visual representations requires substantial computation. For applications requiring real-time responses, such as autonomous driving or high-frequency trading, this is a real bottleneck.
Lack of evaluation standards. How do we measure whether an agent's visual thinking is 'good'? Traditional accuracy metrics are insufficient to capture the quality of spatial reasoning and planning. Academia and industry are still exploring new evaluation benchmarks.
These challenges also give rise to disagreement. Some researchers believe that we should adhere to interpretable symbolic reasoning and treat visual thinking as auxiliary; others argue that we should embrace end-to-end visual reasoning and accept a certain degree of black-box behavior in exchange for stronger capabilities. The two views have clashed fiercely at recent top AI conferences, and there is currently no consensus.
Conclusion: The Form of Thought Is Being Rewritten
The 'crazy times' mentioned in that tweet are crazy not because of the technology itself, but because it hints at a possibility: the carriers and forms of intelligence are far more diverse than we imagined. Visual thinking was once a unique ability that humans took pride in, and now we are trying to bestow it upon machines. This is not merely an expansion of technical routes, but a quiet revolution in the definition of 'thinking' itself. Agents are learning to 'see' the world, and we will witness where they go from here.
One-line Summary
AI agents are gaining human-like visual thinking capabilities, reasoning and planning through internal visual representations.
Paragraph Summary
The article explores an emerging trend in the AI agent field: endowing agents with 'visual thinking' capabilities—that is, understanding the world and planning actions by constructing and manipulating internal visual representations rather than relying solely on text reasoning chains. This shift is built on technological foundations such as multimodal large models and visual chain-of-thought, enabling agents to perform better in tasks involving spatial reasoning and physical interaction. Application prospects span software automation (visually operating graphical interfaces) and embodied intelligent robots (mental rehearsal before action). However, visual thinking also brings challenges such as decreased interpretability, high computational cost, and lack of evaluation standards, and the research community is divided between symbolic reasoning and end-to-end visual reasoning.
Related articles
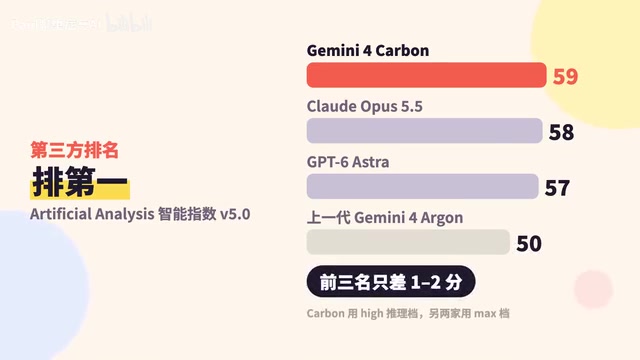
Google Releases Gemini 4 Carbon: Its Strongest Model Yet, Debuting with a Cybersecurity Focus
Google releases Gemini 4 Carbon, calling it its strongest model, with a cybersecurity focus. It tops the third-party composite ranking at 59 points but leads by only one or two. This article analyzes its security test results, staged rollout, token pricing, and the divergence between self-reported and third-party tests on hallucinations.

LangChain Adds SchemagateRetriever: On-Demand Table Retrieval Cuts Text-to-SQL Prompts by 92.9%
LangChain docs add SchemagateRetriever: retrieves only the tables needed for text-to-SQL with permission filtering, cutting median prompt size by 92.9% on Spider 2.0 large schemas via offline BM25 selection with no model calls.

Multi-Step AI Agent Guardrail in Practice: Fact-Change Detection Drives False-Alarm Rate to 0%
Developer shares first version of a multi-step AI Agent guardrail: re-verifying dependency facts before irreversible actions cut false alarms from 50% to 17% across 23 scenarios, then to 0% via conservative normalization without lowering catch rate. Runs on local qwen2.5-7b.