TokenOps: Using Data Science to Reduce AI Agent Token Costs

TokenOps applies data science to control AI agent token costs through cost structure analysis, efficiency metrics, and investment frameworks.
As AI agents scale across enterprises, token costs are growing faster than expected. Microsoft Frontier's Gareth Bland introduces TokenOps — a framework addressing why costs explode (reasoning output tokens cost 5x baseline, and uncached inputs in 40-turn loops can reach 16x expected cost), how to measure efficiency via a three-layer funnel of autonomous completion, token efficiency, and value generation ratios, and when to invest using an S-curve model that identifies underinvestment, leverage, and gold-plating zones. TokenOps repositions token spend as a strategic resource requiring continuous optimization, not just an API bill.
As AI agents are deployed at scale across enterprises, a frequently overlooked problem is emerging: costs are ballooning far beyond expectations. Gareth Bland, Chief Data Science Officer at Microsoft Frontier, has introduced a compelling concept called TokenOps — a data science approach that helps organizations make continuous, strategic decisions about where tokens are being spent and how to extract more value from every token consumed.
The Hidden Cost Structure of AI Agents
Most people's mental model of token costs is a simple one: send a message, receive a message. But the real cost structure is far more complex. Bland points out that an agent's most powerful capability is reasoning, and reasoning happens on the output side — output tokens are priced at roughly 5 times the cost of basic input tokens.
Beyond that, there are several easily overlooked cost categories. When an agent writes to cache during a loop, write costs are incurred. But once content is in the cache, subsequent reads cost only one-tenth of the baseline. This means cache utilization efficiency directly determines the overall spend.
Why Costs Rise on a Quadratic Curve
Agents don't work in a simple question-and-answer mode — they reason through tasks incrementally via multi-turn agentic loops. Bland offers a straightforward example: assume a typical task requires about 10 turns to complete, which maps to 1x the expected cost.
As the agent adds more turns and context continues to accumulate, the cost of uncached inputs follows a quadratic growth curve. At 40 turns, costs aren't a linear 4x — they balloon to a staggering 16x. This is the core pain point that TokenOps aims to solve: through context engineering, maximizing cache reuse to pull that rising curve back down to one-tenth the cost.
Context Engineering refers to the structured management of content passed into a model's prompt, with the goal of maximizing cache hit rates and minimizing redundant token transmission. In multi-turn agentic loops, each iteration appends prior conversation history, tool call results, and intermediate reasoning into the new input context. Without intervention, all of this is re-billed as uncached input on every turn. Core techniques include separating stable system prompts from dynamic content (the former can achieve long-term cache hits), compressing or summarizing historical turns, and trimming tool return values. For mainstream LLM APIs, providers typically maintain prompt caches in windows of 5 minutes to 1 hour — once expired, even a well-engineered agent will unnecessarily re-pay the full input cost, causing the cost curve to steepen again.
Measuring Agent Efficiency with Three Ratios
Engineering systems require appropriate telemetry and metrics. Bland proposes an "overall agentic efficiency score" built from three progressively nested ratios — forming a funnel model.
Autonomous Completion Rate sits at the top of the funnel, measuring how much work is completed autonomously — without failures or human intervention. This is the first checkpoint for assessing agent reliability.
Token Efficiency Ratio measures, among completed work, how much was actually merged into production and capable of delivering value to users. In other words, completion doesn't equal usefulness — only what gets deployed and serves users counts as effective output.
Value Generation Ratio sits at the bottom of the funnel. For features that are live and serving users, are they actually moving the needle? Are they delivering the value users expected? This is the ultimate standard for determining whether token spend was worthwhile.
Telemetry, in the context of AI agents, specifically refers to the systematic collection and tracking of runtime data for each model call — including token usage, latency, success/failure status, and cache hit rates. Unlike traditional software monitoring, agent telemetry needs granularity down to the individual loop iteration, because a single user request may conceal dozens of internal model calls, each with its own input/output forming a discrete billing unit. Without this layer of observability, teams cannot distinguish between "the task completed because reasoning was efficient" and "the task completed after burning through 50 unnecessary loops." Common telemetry implementations include LLM Span tracing via the OpenTelemetry standard, as well as LLM-native observability platforms like LangSmith, Weights & Biases, and Helicone, which can map token-level costs directly to specific steps in a business process.
The S-Curve: Knowing When to Invest and When to Stop
Bland uses an S-curve to help teams understand where they are in the software development lifecycle — a framework that's especially critical in the age of agentic engineering.
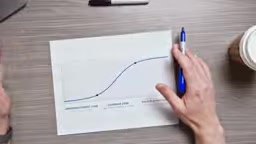
At the start of the curve is the underinvestment zone. When building the first few features of a piece of software, teams don't yet have enough functionality to form an MVP or pilot, and cannot deliver meaningful value to users or business processes.
Past a certain threshold, teams enter the leverage zone. In this range, each incremental improvement or new feature tangibly creates value for users — this is the stage with the highest return on investment.
But beyond the saturation point, the dynamic shifts. Development tends to devolve into gold plating: improving already-polished features, adding capabilities nobody asked for, and spending tokens on work that won't move any metrics. Identifying where your team or next product feature sits on the S-curve is key to avoiding wasted resources.
The S-Curve model originates from technology adoption and product development theory. It describes the typical value-return profile of a technology or feature set over its lifecycle: high initial investment with low returns (underinvestment zone); maximum marginal return per unit of investment in the middle (leverage zone); and diminishing or saturating returns at the end (gold plating zone). In traditional software development, identifying one's position on this curve relies on user research and A/B test data. In AI agent scenarios, this judgment becomes more urgent — because every ineffective feature iteration not only consumes engineering resources, it also directly translates into a quantifiable token bill. The term "gold plating" comes from project management and refers specifically to the behavior of continuing to add features after requirements have already been met — widely considered a classic anti-pattern of resource waste. Combining the S-curve with token efficiency metrics enables teams to use data, rather than intuition, to determine when to shift resources from feature development to performance optimization or new directions.
Implications for Enterprises
At its core, TokenOps is about bringing a financial and engineering efficiency lens to AI agent operations. It reminds organizations that token consumption isn't just a line item on an API bill — it's a strategic resource that requires continuous optimization.
From a cost structure perspective, output tokens and uncached inputs are the most expensive components, making context engineering and cache reuse the most direct levers for cost reduction. From an efficiency measurement perspective, you can't stop at asking whether a task was completed — you need to track all the way to value delivery. From an investment decision perspective, the S-curve provides an intuitive framework for knowing when to double down and when to stop.
For teams deploying agents at scale, building out this telemetry and metrics infrastructure may ultimately have a greater impact on ROI than chasing after more powerful models.
Related articles

How Big Can Stars Really Get? The Physical Limits of the Largest Stars
Red supergiants are the largest stars by volume, with radii up to 2,000 times the Sun, engulfing the inner solar system. But there is no precise upper limit on stellar size—models predict up to 15,000 solar radii. The most massive blue stars are far smaller than red supergiants—biggest and heaviest are two different things.

Apple HomeView Smart Display Full Feature Breakdown: Wall-Mount or Desktop, $299
Apple launches HomeView, a $299 smart display with wall-mount and desktop options, 12MP camera for facial recognition, smart home control, music playback, and recipe step-by-step cooking. Full breakdown of watch faces, apps, privacy, and cooking integration.

Where Did the Promised New Studio Go? Craft Computing Answers After Five Years
Craft Computing's host responds to viewer questions: the new studio promised five years ago was shelved as construction costs soared from $30,000 to $75,000, and was replaced by a 168-square-foot garage conversion.