Trained Two ML Models but Forgot the Accuracy: AI Practice Lessons Behind a Self-Deprecating Post

Developer jokes about training models but forgetting accuracy and losing datasets, reflecting personal AI project engineering gaps.
A developer on Reddit poked fun at himself: he trained a sentiment classifier and a language classifier supporting 59 languages, but couldn't remember their accuracy and even lost the datasets, attaching Hugging Face links and saying "If you feel useless, look at this." The article notes this is not an isolated case but a "it runs, so it's done" trap for beginners and independent developers—evaluation metrics, dataset versions, and hyperparameters scattered in temporary notes. Many personal model cards on Hugging Face lack evaluation results, contrasting with industrial standards. Losing datasets turns models into black boxes. The article recommends DVC and MLflow for data versioning and experiment tracking, and stresses that the open source community accepts imperfection, but supplementing model cards and evaluation data makes sharing truly valuable.
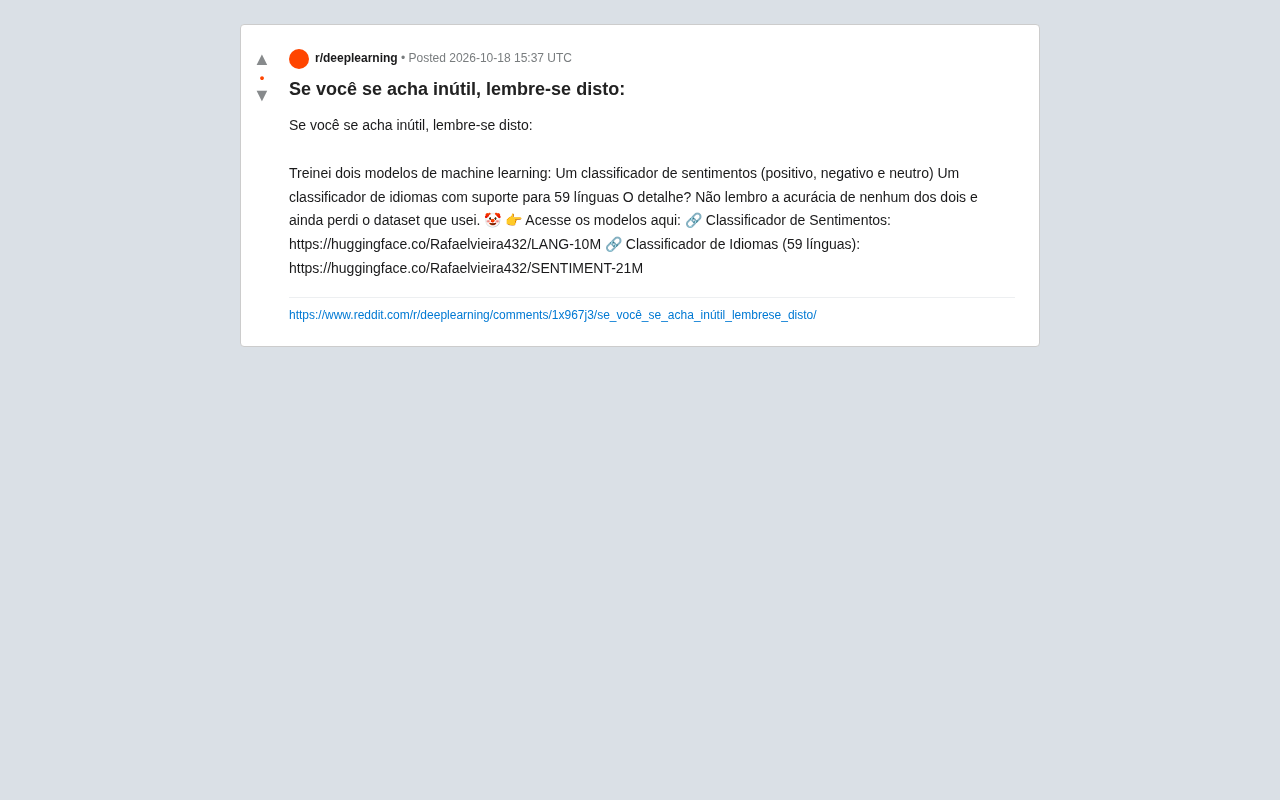
A developer on Reddit poked fun at himself: he trained two machine learning models—a sentiment classifier (positive, negative, neutral) and a language classifier supporting 59 languages—but couldn't remember their accuracy, and even lost the datasets. Embarrassed, he attached the Hugging Face links and said, "If you feel useless, look at this."
According to the original Reddit post, the two models are hosted on Hugging Face at Rafaelvieira432/LANG-10M (sentiment classification) and Rafaelvieira432/SENTIMENT-21M (language classification, 59 languages).
The Common Struggle Behind the Self-Deprecation: Why AI Projects Often Flop
Beginners and independent developers often fall into the "it runs, so it's done" trap. After training is complete, evaluation metrics, dataset versions, and hyperparameter configurations tend to be scattered across temporary notes or already-cleared Colab sessions. This developer's experience is not an isolated case—a large number of personal model cards on Hugging Face lack evaluation results and training details, contrasting sharply with industrial-grade model card requirements (such as model cards and data cards). According to the official Hugging Face documentation, model cards should include intended use, training data, evaluation results, and more, but many community models do not follow this convention.
The direct consequence of this "flop" phenomenon is that models cannot be reliably reproduced or improved. More critically, losing the dataset means even retraining to recover the metrics is impossible, turning the model into a black box. This reflects the weakness of personal AI projects in engineering management: a lack of experiment tracking, version control, and documentation habits.
Model cards and data cards are standard documents that accompany model releases. The Model Card was proposed by Google in 2019 and typically includes model purpose, training data overview, evaluation metrics, limitations, and ethical considerations; the Data Card focuses on dataset sources, collection methods, annotation processes, and potential biases. Together they form the foundation of model traceability. Hugging Face provides model card templates at the platform level and displays key fields (such as metrics, datasets, and licenses) in a structured way, but whether they are filled in depends entirely on the author's own initiative. For individual developers, even adding just a paragraph describing the training data and an evaluation script can significantly improve a model's reusability.
Sentiment Classification and Language Identification: The Technical Value and Use Cases of the Two Models
The sentiment classifier categorizes text into positive, negative, and neutral classes, making it one of the most fundamental NLP tasks, widely used in review analysis, public opinion monitoring, and customer service quality inspection. The language identification model supports 59 languages and can be used for multilingual content routing, translation preprocessing, and language filtering.
These two tasks are not complex, but training a classifier that covers 59 languages and generalizes well requires high-quality multilingual corpora and a reasonable sampling strategy. The developer did not disclose the model architecture, but judging from the "10M" and "21M" in the model IDs, the parameter count is in the tens of millions, making them lightweight models suitable for edge deployment or fast inference.
According to analyses of similar personal projects by Bilibili uploaders and YouTube channels, lightweight models still have practical value in specific scenarios, especially when response latency and resource consumption become bottlenecks. But the premise is that the model's applicable boundaries must be clearly defined—and without accuracy data, users cannot judge whether the model is reliable.
Multilingual corpora and sampling strategies are key to the generalization of language identification models. Covering 59 languages means the training set must balance high-resource languages (such as English and Spanish) with low-resource languages (such as Swahili and Icelandic), otherwise the model will be biased toward languages with larger sample sizes. Common practices include stratified sampling by language, oversampling low-resource languages, or using temperature sampling to balance batches. In addition, language identification often faces challenges such as confusion between closely related languages (e.g., Norwegian and Danish) and code-mixed text, requiring metrics to be reported separately by language during evaluation rather than only looking at overall accuracy.
Practical Lessons to Be Drawn from Failure
The positive significance of this self-deprecating post is that it reminds developers: model delivery does not equal training completion. A complete AI project should include data versioning (such as DVC), experiment tracking (such as MLflow), model card writing, and evaluation metric archiving. Even if the model is not deployed, at least the test set and baseline scores should be retained.
For those who want to reproduce or use these two models, the only option at present is to evaluate them themselves. The Hugging Face platform allows model authors to update model cards later, and it is recommended that the original author add training data descriptions, evaluation scripts, and baseline results so that the models can truly be used.
DVC (Data Version Control) and MLflow are the two easiest tools to implement in personal projects. DVC incorporates hash pointers for large files (datasets, model weights) into Git, achieving version synchronization between data and code and preventing accidents such as "dataset lost"; MLflow provides lightweight experiment tracking, automatically recording hyperparameters, metrics, and artifact paths, and supports a local file backend without requiring an additional server. Both can be integrated with the Hugging Face Hub, referencing the corresponding experiment records in the model card, thereby upgrading "it runs" to "it is reproducible."
The Value of the Open Source Community: Imperfect but Transparent Sharing
Despite mocking himself as "useless," the author still made the model links public, which is itself a contribution. Many personal projects in the open source community are not perfect, but transparent sharing can promote learning and exchange. According to feedback in the Reddit comments, many users encouraged the author to supplement the documentation and believed that this kind of real experience is more inspiring than perfectly packaged tutorials.
This also leads to a consensus in the AI field: the credibility of a model depends not only on performance metrics but also on its traceability. Against the backdrop of increasingly strict regulation (such as the EU AI Act's documentation requirements for high-risk AI systems), good documentation habits are becoming increasingly important even for personal projects.
Summary
The self-deprecating post about forgetting accuracy and losing datasets reflects the common shortcomings of personal AI projects in engineering management. Sentiment classification and language identification models themselves have practical use cases, but the lack of evaluation and documentation greatly diminishes their value. The open source community accepts imperfection but encourages responsible sharing—fill in the model card and let failure also become a valuable case study.
One-line Summary
A developer jokes about training models but forgetting accuracy and losing datasets, reflecting the engineering management shortcomings of personal AI projects.
Paragraph Summary
A developer on Reddit poked fun at himself: he trained a sentiment classifier and a language classifier supporting 59 languages, but couldn't remember their accuracy and even lost the datasets, attaching Hugging Face links and saying "If you feel useless, look at this." The article points out that this is not an isolated case but a "it runs, so it's done" trap that beginners and independent developers often fall into—evaluation metrics, dataset versions, and hyperparameters scattered across temporary notes. Many personal model cards on Hugging Face lack evaluation results, contrasting with industrial-grade model card standards. Losing datasets turns models into black boxes that cannot be reproduced or improved. The article recommends using tools such as DVC and MLflow for data versioning and experiment tracking, and emphasizes that the open source community accepts imperfection, but only by supplementing model cards and evaluation data can sharing truly be valuable.
Related articles

Amphibious Transforming Drone: Beyond 100x Power Savings, What Are the Real Needs?
Is the amphibious transforming drone just a gimmick? Starting from the 100x power difference of the M4 Morphobot, explore real application scenarios and thesis topic ideas, analyzing boundary conditions where pure drones and pure ground robots both fail.

Warhound Raises $200 Million: Genetically Engineered "War Dogs" Paired with Anduril Gear
Warhound raises $200M, backed by Ben Lamm and Palmer Luckey, to genetically engineer dogs for military and law enforcement use and equip them with Anduril gear. This article analyzes its technology direction, funding logic, and ethical controversy.

Claude API Comes to Google Cloud: IAM Integration and SDK Access Guide
Anthropic hosts the full Claude API on Google Cloud with IAM-controlled permissions and unified billing. This guide covers the Vertex AI and Anthropic-hosted entry points, IAM role configuration, and SDK access.