Turning Code into Neural Networks: It Can Learn Prices, Not Rules

Handwired translates JS into differentiable networks — scaling values learn, decision values freeze.
Handwired is a project that manually translates ordinary JavaScript into neural networks, hitting 1,313 stars in two days — yet nobody on Hacker News actually tried it, and the top comment just asked "what's the point?" The author's experiment with a five-rule shipping function: 12 layers, 50 operations, 81 weights, zero error across 16 million inputs, but 175–275x slower than the original. Backpropagation shows scaling values (prices, per-kg rates) get clean gradients, while branch-deciding thresholds stay at zero. In training, price constants were learned exactly while the free-shipping threshold never moved — the network could only distort prices to hide a rule it couldn't see. This reveals its real value: splitting code's numbers into fittable scaling values and frozen decision values, making business rules naturally immune to gradients.
Cheng Lou's new project Handwired hit GitHub and racked up 1,313 stars in under two days, with the announcement tweet pulling in over 10,000 likes. The pitch is irresistible: "turn your ordinary JavaScript code into a neural network" — no training required, output identical to the JS, and fully differentiable.
But Hacker News reacted in the exact opposite way. The hottest submission only got 9 points, and the top comment came from user skyzoidbroczky, one line long: "What's the point of this thing?" Two other comments said they couldn't see the use case either. Not a single person in the entire thread claimed to have actually tried it.
So I ran an experiment with a function I wrote myself.
The Name Is the Instructions: Manual Translation, Not Automatic Conversion
The core idea behind Handwired can be summed up in a few lines of code. A comparison operation becomes a pair of ReLUs, an if computes both branches and then mixes them using a 0-or-1 bit. Stack enough of these structures and your program turns into a stack of weighted sums and ReLU products — a neural network whose weights you hand-write rather than train.
The official docs say it outright: "There is no tool that converts existing JavaScript source into this kind of program." You have to translate by hand, writing one-off build code that appends operations one by one to a Circuit object. That's exactly where the name Handwired comes from.
Ranges and grids are part of the translation too. The README example rewrites (a > 4) ? 10 : 12 as relu(a - 4) - relu(a - 5), noting this only holds for integer a. The actual API requires you to declare a value range and grid granularity for each input (say, integer cents or integer grams), and it then builds comparisons that hold exactly for every value in the range you declared.
ReLU (Rectified Linear Unit) is the most common activation function in neural networks, defined as $\mathrm{ReLU}(x) = \max(0, x)$. It truncates negatives to zero and keeps positives unchanged, making it a piecewise linear function. Handwired's use of ReLU to express comparisons is no accident: combinations like ReLU(a - c) - ReLU(a - c - 1) can construct a step-shaped indicator function that returns exactly 1 or 0 on an integer grid, thereby simulating a boolean test. Since ReLU's linear region is differentiable everywhere with a derivative of exactly 1, it passes clean gradients through to "scaling" values; but at the kink point the derivative is discontinuous — which is precisely why gradients are zero at thresholds in Handwired.
A Five-Rule Shipping Fee Function
I wrote an integer-cents version of a shipping calculator with five rules: members with 5,000 points or more get free shipping, orders with 10,000 points or more get free shipping, up to 500 grams costs 499, up to 2,000 grams costs 899, and anything over 2,000 grams adds 300 per extra kilogram.
The one thing that made me stop and think during translation was Math.ceil. These programs can't loop, and they can't divide by a runtime-determined number, so "how many whole kilograms over 2 kg" became eight comparisons whose bits get summed. The docs call this "threshold counting."
The final product: 12 layers, 50 operations, 81 weights. Twelve comparisons account for 24 of the operations (two each), because integer cents and integer grams let every comparison take the cheapest exact form.
I verified it the dumbest way possible: iterating over every 25 cents from 0 to 200 dollars, every gram from 0 to 10 kilograms, and both member and non-member states — 16,021,602 inputs total. Zero error against the original function, covering all 11 prices it could possibly return.
One detail surprised me. After I manually folded the if branches (a light package is necessarily under 2 kg, and nested selects collapse into a single sum), the same function shrank to 7 layers and 37 active operations, producing identical answers across all 16 million inputs. In Handwired, you are the compiler, and your algebraic simplifications translate directly into network depth.
Speed isn't pretty. On an M1 Max busy with other tasks, the compiled program took 10 to 17 seconds to handle 16 million calls, while the original function took just 60 milliseconds — a gap of roughly 175x to 275x. But that's not really the selling point — the README's speed claims are about batched evaluation on GPUs, like its JSON search demo that processes 100,000 documents at once. I didn't run the GPU path.
Threshold counting here means expressing "how many integer units exceed some baseline" through a set of parallel comparisons. Because these programs can't loop and can't divide by a runtime-determined number, Math.ceil((w - 2000) / 1000) can't be translated directly. The approach is to make one comparison for each possible whole-kilogram starting point and add up the results (0-or-1 bits) to get the number of excess kilograms. The cost of this unrolling is that network width and depth grow linearly with range, but it buys a completely acyclic, purely feedforward structure — which is exactly why it can be represented as a stack of weighted sums and ReLUs.
Where Did the Gradient Go: Scaling Values Have Gradients, Decision Values Don't
"Fully differentiable" is one of the main selling points. I ran backpropagation on a 30-dollar, 3.5-kilogram order with a 14.99 shipping fee:
- The partial derivative of shipping cost with respect to the per-kilogram rate = 2, exactly matching the two excess kilograms.
- The partial derivative with respect to the mid-tier price = 1.
- The partial derivative with respect to all thresholds = 0. The 50-dollar member line, the 100-dollar line, 500 grams, 2 kilograms — all zero.
Every value that scales the answer gets a clean gradient; every value that decides which branch to take gets nothing. The docs don't hide this at all: comparison operations backpropagate the derivative of a step function, which is zero everywhere except in a gap narrower than one grid step.
Backpropagation is the standard algorithm neural networks use to compute gradients: walking the computation graph from output back to input, applying the chain rule layer by layer to get the partial derivative of the loss with respect to every weight. Differentiability requires that each operation has a well-defined derivative near the evaluation point. Comparison operations (like a > c) are numerically equivalent to a step function, whose derivative is zero everywhere except at the jump point, where it is undefined. So in this kind of network, whether a gradient can flow back to a parameter depends on whether that parameter participates in continuous scaling (multiplication, addition) or discrete decisions (comparison, rounding). This explains why in the experiment the per-kilogram rate got a gradient of 2 while the 100-dollar threshold stayed at 0.
Teaching It a New Price List: It Learned the Prices, Not the Rules
Using the program's own gradients plus a plain Adam optimizer, I trained its twin network on 2,000 random orders.
First experiment: change only the prices (549, 949, 350 per kilogram). By step 100, the network had learned exactly 549, 949, and 350, with zero errors across 2,000 orders. That result is genuinely striking: nothing told it which constant was the per-kilogram rate — the gradient found it on its own.
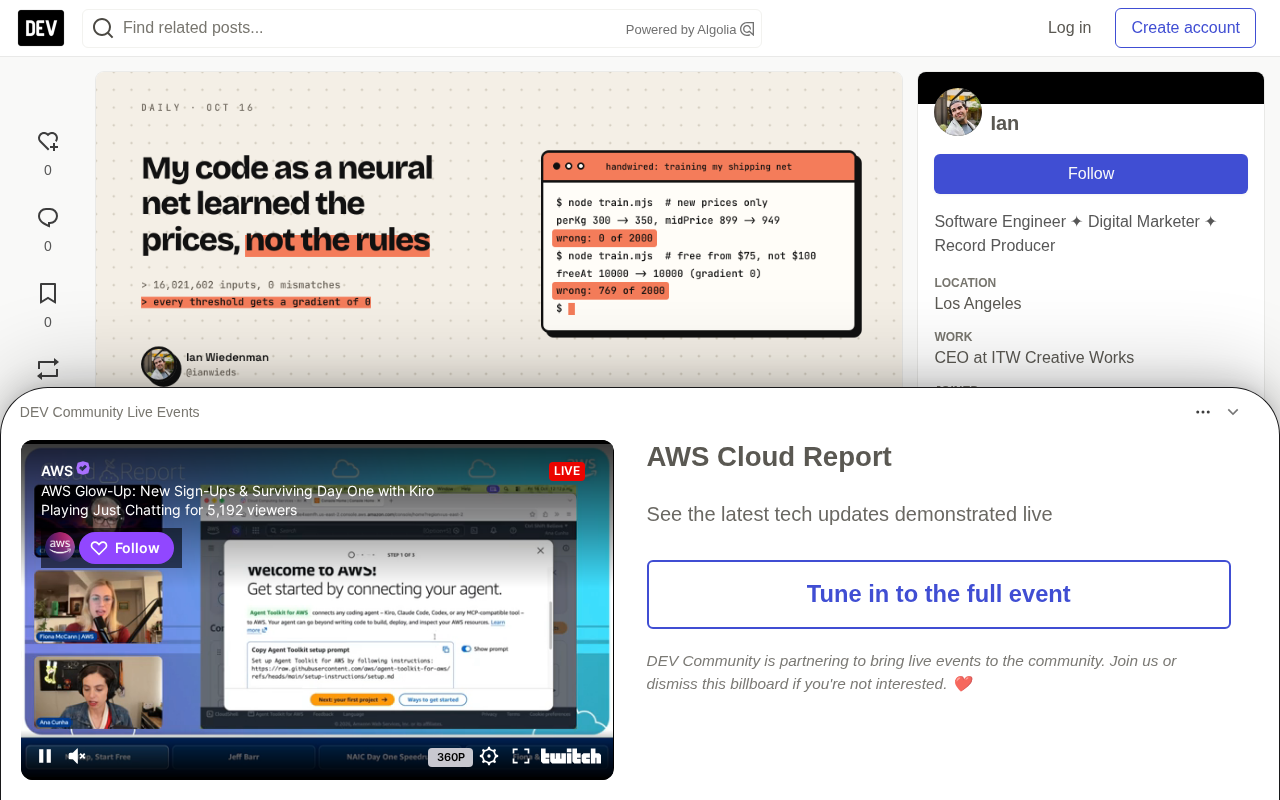
Second experiment: same prices, but the free-shipping threshold moves from 100 dollars to 75 dollars. The threshold didn't budge; it stayed pinned at 100 dollars for 600 steps, with the gradient remaining zero throughout. Training simply did the only thing it could: it dragged the base prices down (499 became 434.63, 899 became 792.88) and nudged the per-kilogram rate to 313.87, softening the error on the orders that should have shipped free. Mean squared error barely moved, from 245,000 to 243,380. Of the 769 orders it still charged for, not a single one was correct — the same ones it got wrong before training.
It learned a worse price list to paper over a rule it couldn't see.
This is exactly the problem the project's issue #1 wants to solve. The author estimates the gradient at each decision point near its flip location. In their two-column layout test, ordinary backpropagation left a breakpoint at 500, while their method pushed it to 699.9 (target was 720), fitting all samples. For now, that approach lives on a fork branch.
So What's the Point, Really
Back to that HN comment. My answer is: translating code into a network amounts to splitting its numbers into two piles. Scaling values (prices, margins, dimensions, spring constants) become weights that can be fit from samples; decision values (thresholds, breakpoints) stay exact and frozen.
The second pile is both a limitation and a feature. A rule you don't want gradients bending really can't be bent, while the constants around it can still be adjusted. The project's learned gallery demo is exactly this idea: a layout program with small networks embedded inside, whose coefficients are trained using the program's own gradients.
The limitations I ran into: you have to translate by hand, you declare your own ranges and grids, everything is 32-bit float (fine for integer cents, risky for floating-point amounts), and the repo's tests require Bun, so I didn't run them.
So here's a question to leave you with: which numbers in your own code would you hand to the gradient, and which would you never let it touch?
Adam (Adaptive Moment Estimation) is a widely used stochastic gradient descent variant that maintains running averages of the first and second moments of the gradient, adaptively adjusting the step size for each parameter. It's used extensively to train deep networks, but it requires the objective to be differentiable with respect to the parameters. In the Handwired experiment, Adam converged rapidly and precisely on the price constants (549, 949, 350), yet stalled against the zero gradient at the threshold — not a flaw of the optimizer, but the boundary of differentiable structure: an optimizer can only move parameters in directions where a gradient exists. This contrast perfectly highlights the fundamental divide between "scaling values" and "decision values" in terms of trainability.
One-line Summary
Handwired translates JS into differentiable networks by hand — scaling values learn, decision values freeze.
Paragraph Summary
Handwired is a project that manually translates ordinary JavaScript into neural networks, hitting 1,313 stars in two days — yet nobody on Hacker News actually tried it, and the top comment just asked "what's the point?" The author's experiment with a five-rule shipping function: 12 layers, 50 operations, 81 weights, zero error across 16 million inputs, but 175–275x slower than the original. Backpropagation shows scaling values (prices, per-kg rates) get clean gradients, while branch-deciding thresholds stay at zero. In training, price constants were learned exactly while the free-shipping threshold never moved — the network could only distort prices to hide a rule it couldn't see. This reveals its real value: splitting code's numbers into fittable scaling values and frozen decision values, making business rules naturally immune to gradients.
Related articles

AI Reverse-Engineers Monitor Firmware in 15 Minutes — Has the Hacking Barrier Been Flattened?
A security researcher used AI to reverse-engineer Dell monitor firmware in 15 minutes—entropy analysis, key extraction, MD5 verification—revealing encryption design flaws.

Mistral Voxtral 3: Real-Time Voice at 4 Cents per Minute, Challenging OpenAI
Mistral Voxtral 3 cuts real-time voice agent costs to 4 cents per minute, bundling three speech recognition models, a speech generation model, and a real-time voice toolkit, supporting 50+ languages and self-hosting. This article analyzes its pricing structure, sub-second response performance, and its strategic divergence from OpenAI and Gemini on data privacy versus out-of-the-box convenience.

WebMCP: Every Website as Its Own MCP Server, So AI Agents No Longer Rely on Screenshots
WebMCP lets websites expose tools via the document.modelcontext API, becoming directly callable MCP servers. This article explains its architecture, the Claude Code remote-debugging demo, Chrome's current support stage, and its impact on the agent ecosystem.